How to Fix wkhtmltopdf Stopping After About 20 Pages
wkhtmltopdf has no documented 20-page limit. Use this evidence-based checklist to find incomplete pages, blank output, resource failures, and process limits.
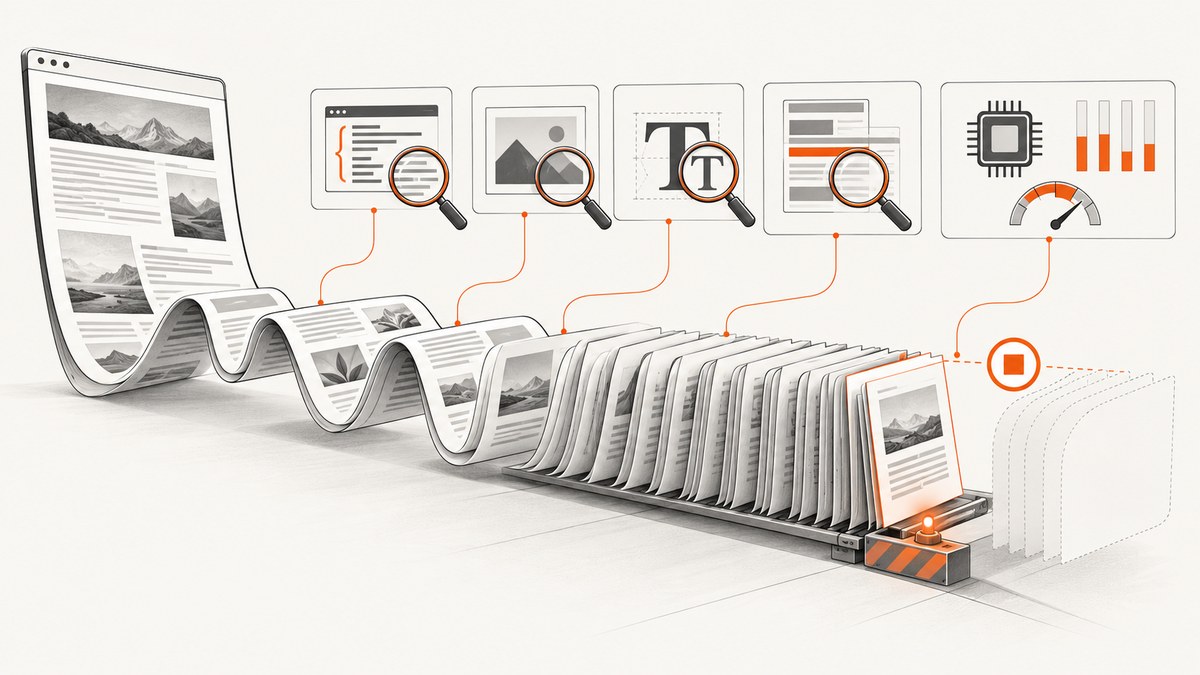
There is no substantiated universal 20-page limit in wkhtmltopdf. An output that ends near page 20, turns blank, or is cut off mid-page is a reproducible symptom rather than a diagnosis. The reliable approach is to record the exact environment, create a minimal reproduction, and isolate JavaScript, resource loading, headers and footers, and process limits one change at a time.
This guide separates the common failure shapes and gives runnable tests for the command line, Python, and Node.js. It also explains when a hosted renderer is a better operational choice.
First, identify what “stopping” means
Open the generated PDF and classify the result before changing options:
| Symptom | What to inspect first |
|---|---|
| The PDF ends at about page 20 | JavaScript completion, failed resources, timeouts, memory, open files, and worker limits |
| Pages after about 20 are blank | CSS page-break behavior, missing fonts/images, JavaScript state, and headers or footers |
| A page is cut off mid-content | Resource loading, a renderer timeout, a slow iframe, or a process being terminated |
| The command reports success but content is missing | Warnings on stderr and load-error handling settings |
An approximate page number by itself does not establish a limit. The official usage reference documents controls for JavaScript timing, slow scripts, images, and load errors, but does not say that any of them fixes every incomplete PDF: wkhtmltopdf usage reference.
Record a reproducible baseline
Before changing the command, save the information the project asks for in a useful bug report: the binary version, operating system and version, exact command, input HTML/CSS/JavaScript, output page count, and warnings. The official support guidance requests a detailed reproducible HTML/CSS/JS case: wkhtmltopdf support.
wkhtmltopdf --version
uname -a
wkhtmltopdf input.html output.pdf 2>wkhtmltopdf.stderr
pdfinfo output.pdf | grep Pages
cat wkhtmltopdf.stderr
On Windows, capture the same information from PowerShell:
wkhtmltopdf --version
Get-ComputerInfo | Select-Object WindowsProductName,WindowsVersion,OsArchitecture
wkhtmltopdf input.html output.pdf 2> wkhtmltopdf.stderr
Get-Content wkhtmltopdf.stderr
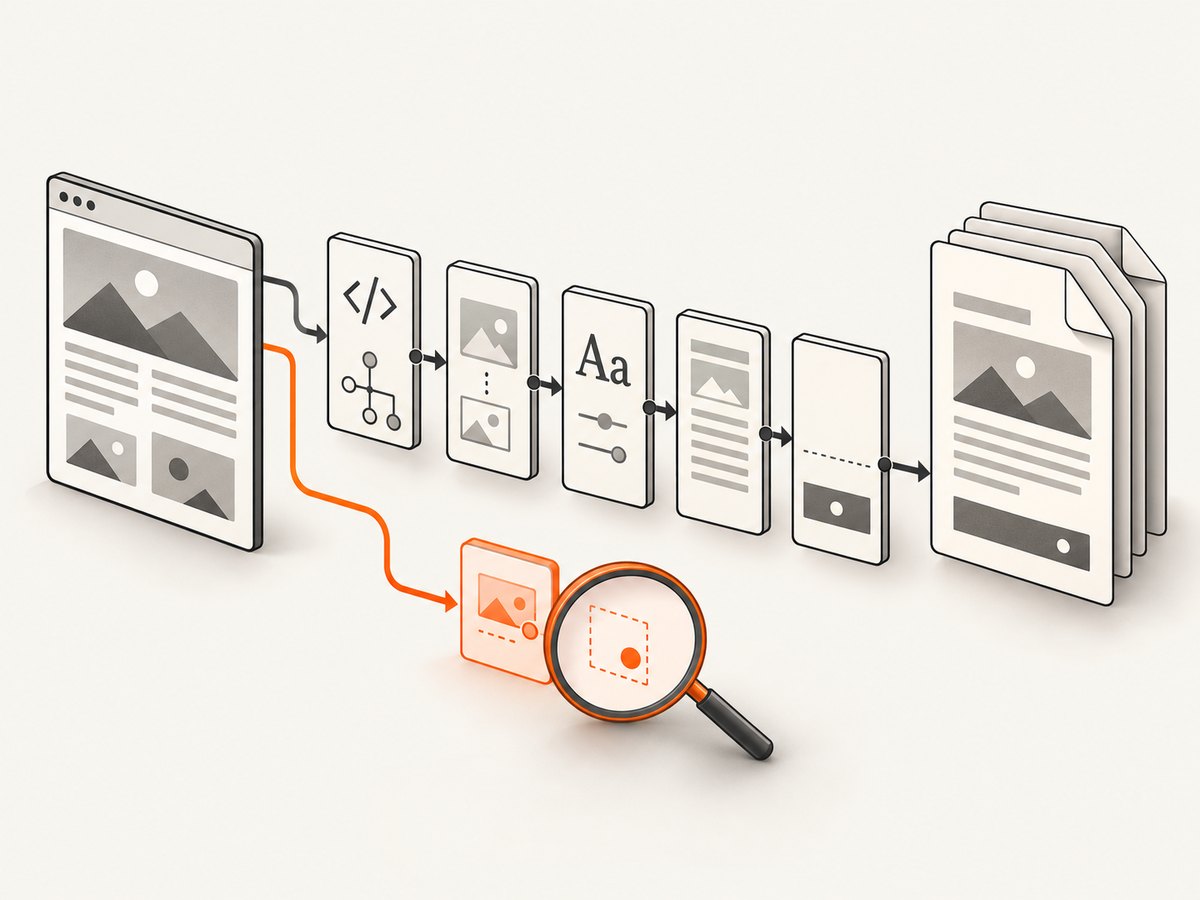
Build a minimal reproduction
- Copy the failing HTML and all referenced CSS, fonts, images, iframes, and scripts into a test directory.
- Replace remote resources with local or embedded versions where possible, while preserving one failing case.
- Remove sections from the end until the output is complete, then add sections back in small batches.
- Keep a short successful document and the smallest failing document so each option change has a clear comparison.
This distinguishes a content trigger from a page-count assumption. Keep the original and reduced inputs, because the reduced file is usually more useful than a large production export when escalating.
Test JavaScript completion
Dynamic pages can be captured before their final content exists. The CLI exposes a fixed delay, a window-status wait, and controls for scripts that run too long. Test one setting at a time and verify that the expected content appears in the PDF.
Use a controlled delay
wkhtmltopdf --javascript-delay 3000 input.html delayed.pdfA longer delay can diagnose a race, but it also increases runtime and can hide a page that never settles. Use the smallest delay that consistently produces the required content.
Wait for a page status
If your page can set window.status after rendering, wait for that value:
<script>
  // Set this after data, charts, and images are ready.
  window.status = "ready";
</script>
wkhtmltopdf --window-status ready input.html status.pdfInvestigate slow scripts
The documented options include --stop-slow-scripts and --no-stop-slow-scripts. Run both as controlled experiments when a long-running script may prevent the page from reaching a stable state:
wkhtmltopdf --stop-slow-scripts input.html stop-slow.pdf
wkhtmltopdf --no-stop-slow-scripts input.html allow-slow.pdf
Do not assume that allowing slow scripts is safer. Compare output completeness, runtime, and resource use, then fix the script or its completion signal if possible. The library settings reference documents the same JavaScript delay and slow-script behavior: library page settings.
Inspect failed images, fonts, stylesheets, and iframes
A missing asset can change layout enough to create blank or incomplete pages. Check every URL in the HTML, including redirects, authentication, TLS, and iframe sources. Keep stderr from each run and look for load warnings.
The usage reference exposes page and media load-error handling. Use those settings to make failures visible during diagnosis, then decide whether your production job should abort or continue:
wkhtmltopdf --load-error-handling abort --load-media-error-handling abort input.html strict.pdf
wkhtmltopdf --load-error-handling ignore --load-media-error-handling ignore input.html permissive.pdf
If strict mode fails, the error identifies a resource to repair. If permissive mode produces a short or blank PDF, compare the missing resource list with the layout change. An intermittent report described missing fonts or images and an iframe that took too long to load; that is evidence to inspect those resources, not proof of a universal iframe limit.
Make assets deterministic
- Use absolute URLs or local files that exist inside the renderer’s environment.
- Confirm the process can resolve DNS and establish HTTPS connections.
- Serve fonts with the correct MIME type and permit cross-origin requests when required.
- Replace a remote asset with a local copy or a data URI as a diagnostic.
- Test the HTML in the same container, VM, or worker that runs wkhtmltopdf.
Isolate headers and footers
Temporarily remove HTML headers and footers and render the document again. A large-PDF report connected one setup with remote header/footer images and file-descriptor pressure; its commenter reported that local or embedded images solved that particular setup. Treat this as a lead for an experiment, not a guaranteed fix.
# Baseline with the header/footer options removed
wkhtmltopdf input.html without-header-footer.pdf

# Then test local or embedded header/footer assets
wkhtmltopdf --header-html header-local.html --footer-html footer-local.html input.html local-assets.pdf
If removing the header or footer changes the page count, test each asset separately. Check whether the header/footer HTML creates additional network requests, references an iframe, or loads a large image on every page.
Check process limits and document growth
Compare the short successful input with the smallest failing input while monitoring the calling process. Check:
- Resident memory and container memory limits.
- Open-file limits and the number of simultaneous resource connections.
- Job, worker, or reverse-proxy timeouts.
- CPU throttling and process termination signals.
- Temporary-directory space and write permissions.
# Linux examples while a conversion runs
/usr/bin/time -v wkhtmltopdf input.html output.pdf
ulimit -n
free -h
df -h
The evidence includes a large-document report involving file descriptors, but no general threshold has been established. If the process is killed, the shell, container runtime, or worker log should show that fact. Increasing a limit without reproducing the failure under observation can conceal the real trigger.
Verify the installed version and deployment
Record which binary your wrapper actually invokes:
command -v wkhtmltopdf
readlink -f "$(command -v wkhtmltopdf)"
wkhtmltopdf --version
The official downloads page documents the 0.12.6 stable series released June 11, 2020 and recommends using the latest stable release available for the target operating system. Check the current official downloads page for your platform rather than treating that page as a live release check: official downloads.
Test any binary change against the failing document, required fonts, links, JavaScript, and deployment image before rolling it out. Also review the project’s security warning: do not process untrusted HTML or JavaScript without an appropriate isolation and sanitization boundary.
Runnable wrappers
Shell
#!/usr/bin/env bash
set -euo pipefail
input=${1:?HTML input required}
output=${2:?PDF output required}
wkhtmltopdf --javascript-delay 1000 \
  --load-error-handling abort \
  --load-media-error-handling abort \
  "$input" "$output"
Python
import subprocess
from pathlib import Path

source = Path("input.html")
target = Path("output.pdf")
result = subprocess.run(
    [
        "wkhtmltopdf",
        "--javascript-delay", "1000",
        "--load-error-handling", "abort",
        "--load-media-error-handling", "abort",
        str(source), str(target),
    ],
    text=True,
    capture_output=True,
    check=False,
)
print(result.stdout)
print(result.stderr)
if result.returncode != 0:
    raise RuntimeError(f"wkhtmltopdf failed with exit code {result.returncode}")
Node.js
import { spawn } from "node:child_process";

const child = spawn("wkhtmltopdf", [
  "--javascript-delay", "1000",
  "--load-error-handling", "abort",
  "--load-media-error-handling", "abort",
  "input.html",
  "output.pdf",
]);

let stderr = "";
child.stderr.on("data", chunk => { stderr += chunk; });
child.on("close", code => {
  if (code !== 0) {
    console.error(stderr);
    process.exit(code ?? 1);
  }
  console.log("PDF written to output.pdf");
});
A repeatable troubleshooting checklist
- Output ends near page 20: compare a minimal reproduction, inspect stderr, and monitor memory, file descriptors, and worker timeouts.
- Blank pages: remove headers and footers, verify fonts and images, and inspect CSS page breaks and JavaScript state.
- Missing dynamic content: test
--javascript-delayor--window-status; then fix the page’s readiness signal. - Slow iframe warning: load the iframe directly, check its network path, and test with the iframe removed.
- Images or fonts missing: verify URLs, TLS, authentication, MIME types, and local copies.
- Process disappears: inspect container, worker, memory, timeout, and open-file logs.
- Only one host fails: compare binary version, OS, fonts, locale, network access, and file permissions.
- Changing one flag fixes it: keep a before/after PDF and measure runtime; document the smallest reliable configuration.
Performance, reliability, and cost considerations
Fixed delays increase latency on every job, so prefer a deterministic readiness signal when the page can provide one. Remote assets add network variance; local or embedded assets improve repeatability but increase packaging work. Headers and footers are rendered repeatedly, so their remote resources can multiply requests across a large document. Splitting a huge document can help isolate a failing section, but do not present splitting as a fix until the resulting PDFs preserve page numbering, links, fonts, and layout.
For production, retain stderr, the renderer version, input identifier, elapsed time, exit code, output byte size, and page count. Retry only failures that are plausibly transient, and avoid retrying malformed HTML indefinitely. Treat untrusted HTML as code that needs isolation.
Or skip the browser setup
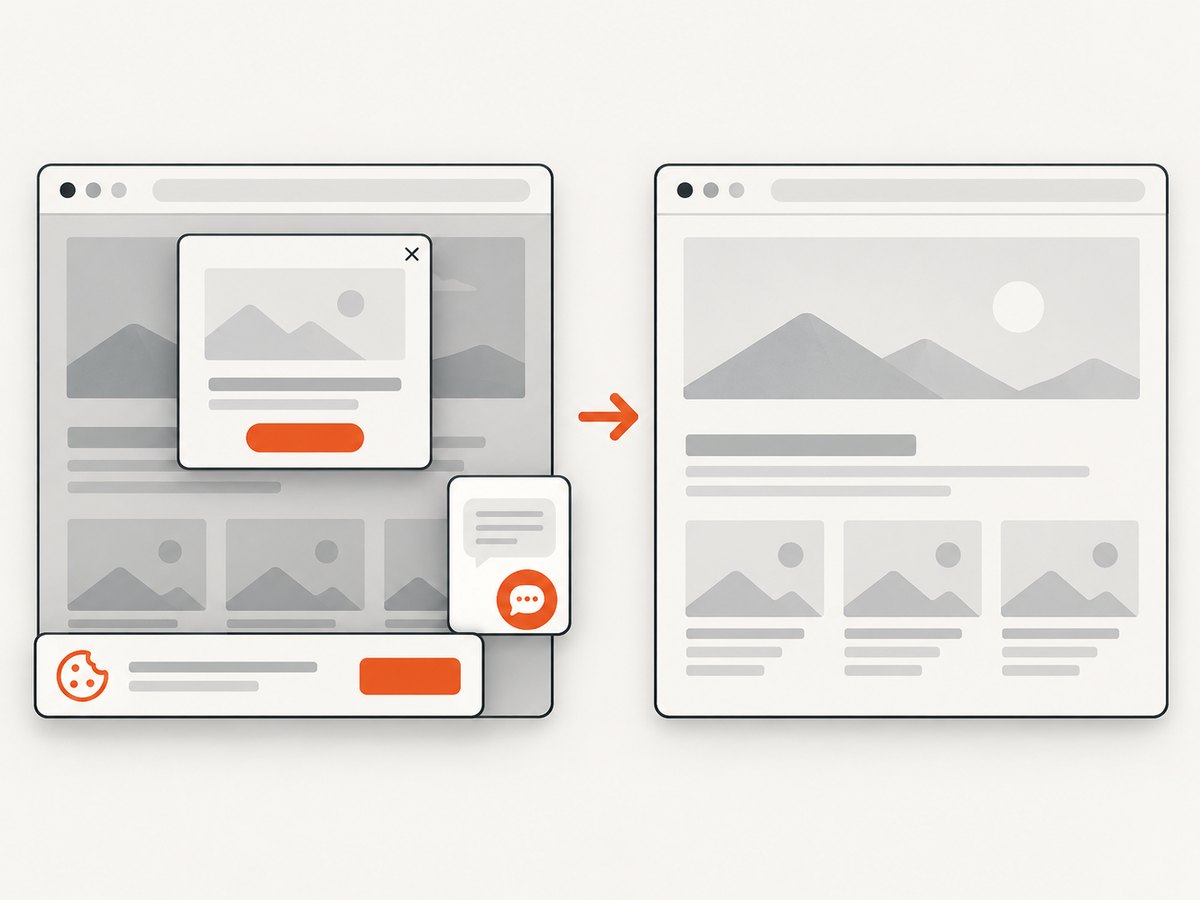
If you need a hosted capture of a public webpage instead of maintaining a wkhtmltopdf process, ScreenshotNeo provides a GET endpoint that returns a PNG, JPEG, WebP, or PDF. Its clean-shot workflow accepts consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers.
See the ScreenshotNeo API documentation for the available options, including full-page capture, CSS element selection, JavaScript and CSS, waits, request blocking, custom headers and cookies, device and viewport settings, PDF output, caching, signed links, asynchronous jobs, bulk capture, and usage reporting.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo also provides an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
FAQ
Does wkhtmltopdf stop at exactly 20 pages?
No documented universal cutoff has been established. The page count is a symptom to reproduce and investigate.
Should I always increase JavaScript delay?
No. Use a delay as a controlled diagnostic, then prefer a page readiness signal or a fixed minimum delay that your content actually needs.
Can remote images cause the failure?
They can contribute to an individual failure, especially in headers and footers, but the available evidence does not establish a general rule. Test local or embedded assets and inspect warnings.
What should a support report contain?
Include the exact binary version, OS and version, command, minimal HTML/CSS/JS reproduction, output page count, and complete warnings or logs.
Is ScreenshotNeo a drop-in replacement for local HTML?
The shown endpoint captures a URL. It is useful when your source is reachable by URL and you want a managed browser capture; local-file workflows still need a renderer that can access those files safely.


