Flight Scraper: How the Go Project Works, How to Run It, and When to Use an API
Learn how the antodippo/flight-scraper Go project queries Kayak, emails results, handles scheduling, and where a managed capture API fits.
Flight scraper usually means software that collects flight prices from airline, metasearch, or travel pages. In this article, the title refers specifically to antodippo/flight-scraper, a small Go project that queries Kayak.com for a route and date, parses flight results, and emails a table to one or more recipients.
The project is intended for learning and experimentation. Its README documents the required airport codes, date, recipients, SMTP configuration, and cron scheduling suggestion. It does not establish that the current Kayak site still matches the parser or that the project works unchanged today. Treat the code as a useful starting point and inspect the repository before relying on it for production alerts.
What the flight-scraper project does
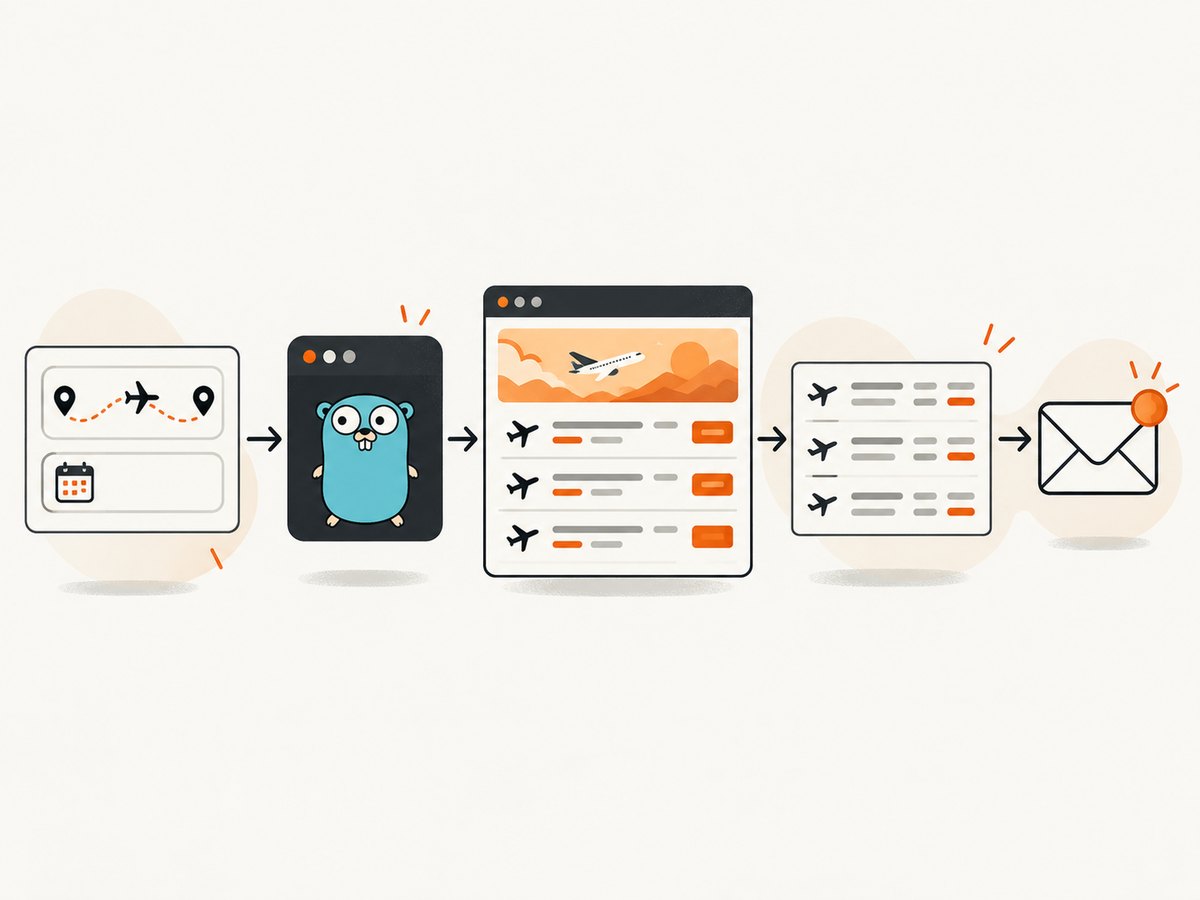
The documented workflow has four inputs:
- A departure airport code.
- An arrival airport code.
- A travel date in
YYYY-MM-DDformat. - One or more email recipients.
It then requests flight information from Kayak.com, extracts fields such as route, departure and arrival time, airline, and price, and sends the parsed rows by email. The sample figures in the README are illustrative output, not current fare quotes.
SMTP settings are required. The README provides environment variables for the sender address, SMTP host, port, username, and password. The author also suggests running the program from cron so a search can be repeated on a schedule.
Before you run it
- Install a recent Go toolchain.
- Clone the repository and read its README and source code.
- Create SMTP credentials that your mail provider permits for application use.
- Choose airport codes and a date in the documented format.
- Review Kayak.com’s terms and conditions before using the scraper, as the repository README instructs.
git clone https://github.com/antodippo/flight-scraper.git
cd flight-scraper
go mod download
go run .
The final command above starts the project, but the exact command-line flags or prompts depend on the version in the repository. Use the README’s example invocation for the route, date, and recipient values instead of assuming flags that are not documented.
Inputs and validation
Validate inputs before a scheduled run. Airport codes are normally three-letter IATA identifiers, but the repository’s documentation is the authority for what it accepts. Validate the date with a strict layout and reject dates in the past if your use case does not need historical searches.
package main

import (
    "fmt"
    "os"
    "regexp"
    "time"
)

var airportCode = regexp.MustCompile(`^[A-Za-z]{3}$`)

func main() {
    if len(os.Args) != 4 {
        fmt.Println("usage: validate FROM TO YYYY-MM-DD")
        os.Exit(2)
    }

    from, to, date := os.Args[1], os.Args[2], os.Args[3]
    if !airportCode.MatchString(from) || !airportCode.MatchString(to) {
        fmt.Println("airport codes must contain three letters")
        os.Exit(2)
    }
    if _, err := time.Parse("2006-01-02", date); err != nil {
        fmt.Println("date must use YYYY-MM-DD")
        os.Exit(2)
    }
    fmt.Printf("validated %s -> %s on %s\n", from, to, date)
}
This validator is a standalone guard, not a replacement for the repository’s scraper. It prevents malformed scheduled jobs from consuming a request or sending a misleading email.
How the scraping pipeline works
- Build a search. The program combines departure, arrival, and date values into a Kayak search.
- Fetch the page. An HTTP client requests the page or endpoint used by the project.
- Parse results. The parser identifies route, time, airline, and price fields.
- Format an email. Parsed rows become an HTML or text table.
- Deliver through SMTP. The message is sent to the configured recipients.
Each stage can fail independently. A successful HTTP response does not prove that flight rows were found, and a successful SMTP transaction does not prove that the parser selected the right fares. Log the search inputs, response status, number of parsed rows, and mail result separately.
Dynamic pages and parser maintenance
Travel pages frequently render content with JavaScript, change CSS classes, apply consent dialogs, or return different markup by region and user agent. A parser written against one page shape can stop finding prices after a site change while still returning HTTP 200.
When maintaining a learning scraper:
- Save a redacted HTML fixture and write parser tests against it.
- Fail loudly when zero rows are parsed.
- Keep selectors in one place instead of scattering them through the code.
- Record the currency and locale used for each result.
- Do not treat a displayed price as bookable until you verify it on the provider’s site.
If the target requires a real browser, a plain Go HTTP request may not execute the JavaScript that creates the results. Browser automation adds rendering, waits, cookies, consent handling, and concurrency concerns. Those are separate from the repository’s documented setup.
Email and SMTP configuration
Keep SMTP credentials outside source control. The repository README lists environment variables for sender, host, port, username, and password; use those names for the version you checked. A typical deployment pattern is:
export SMTP_FROM='alerts@example.com'
export SMTP_HOST='smtp.example.com'
export SMTP_PORT='587'
export SMTP_USERNAME='alerts@example.com'
export SMTP_PASSWORD='use-a-secret-manager'

# Add the project's documented route, date, and recipient arguments here.
go run .
Port 587 commonly uses authenticated submission with STARTTLS, while port 465 commonly uses implicit TLS. Your provider’s documentation determines the correct mode. If authentication succeeds but delivery fails, check sender verification, recipient restrictions, and provider rate limits.
Scheduling with cron
The README suggests cron for repeated searches. Use an absolute working directory, an explicit Go binary or built executable, and a log file so failures are diagnosable.
# Every morning at 07:00 UTC
0 7 * * * cd /opt/flight-scraper && /usr/local/bin/flight-scraper >> /var/log/flight-scraper.log 2>&1
Prevent overlapping runs if a request occasionally takes longer than the schedule interval. A lock file, systemd timer, or queue can provide this protection. Add retries with backoff for transient network errors, but avoid retrying invalid dates, authentication failures, or a parser that returned zero rows until you investigate.
Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| No rows in the email | Kayak markup changed, JavaScript did not run, or the search returned no matches. | Save the response, inspect rendered HTML, verify the route and date, and update selectors or browser handling. |
| HTTP 403 or a bot page | The site challenged the request or limited the client. | Respect the site’s terms, reduce request frequency, and do not assume retries will solve a challenge. |
| HTTP 200 but blank content | The response is an interstitial, consent page, or script shell. | Classify the response body before parsing and use a browser only when the workflow requires one. |
| Date rejected | The value is not exactly YYYY-MM-DD. |
Validate with Go’s time.Parse before making a request. |
| SMTP authentication failed | Wrong credentials, wrong port/TLS mode, or provider policy. | Verify the provider settings and use an app password or approved SMTP credential. |
| Email accepted but never arrives | Spam filtering, sender policy, or an invalid recipient. | Check SMTP logs, SPF/DKIM requirements, spam folders, and recipient addresses. |
| Cron works manually but not on schedule | Cron has a smaller environment and a different working directory. | Use absolute paths, export variables in a protected file, and redirect stdout and stderr. |
Performance, reliability, and cost
A single route-and-date search is usually limited by the target page’s response time and rendering. More concurrency is not automatically better: it can trigger rate limits, increase SMTP volume, and make debugging harder. Start with one route per process, measure request and parse durations, then add bounded concurrency only when the target and mail provider permit it.
The repository does not document uptime, current compatibility, a pricing model, or production reliability. Your direct costs are the machine, network, and email service you operate. If you need many routes, repeated browser rendering, geolocation, structured delivery, or operational monitoring, compare managed scraping infrastructure separately. Bright Data describes managed proxy and unblocking infrastructure; Browserbase describes cloud browser sessions and geolocated concurrency; ScrapingBee markets a managed extraction API. These products are adjacent options, not dependencies of this GitHub project, and their pricing and limits should be checked before adoption.
When a screenshot API is useful
Sometimes the deliverable is a visual record of a flight search rather than a structured fare database. A screenshot can preserve the rendered page, including the route summary and visible price context, for review or an email attachment. It does not replace a parser when you need normalized fields, historical comparisons, or automated booking logic.
Or skip the browser setup
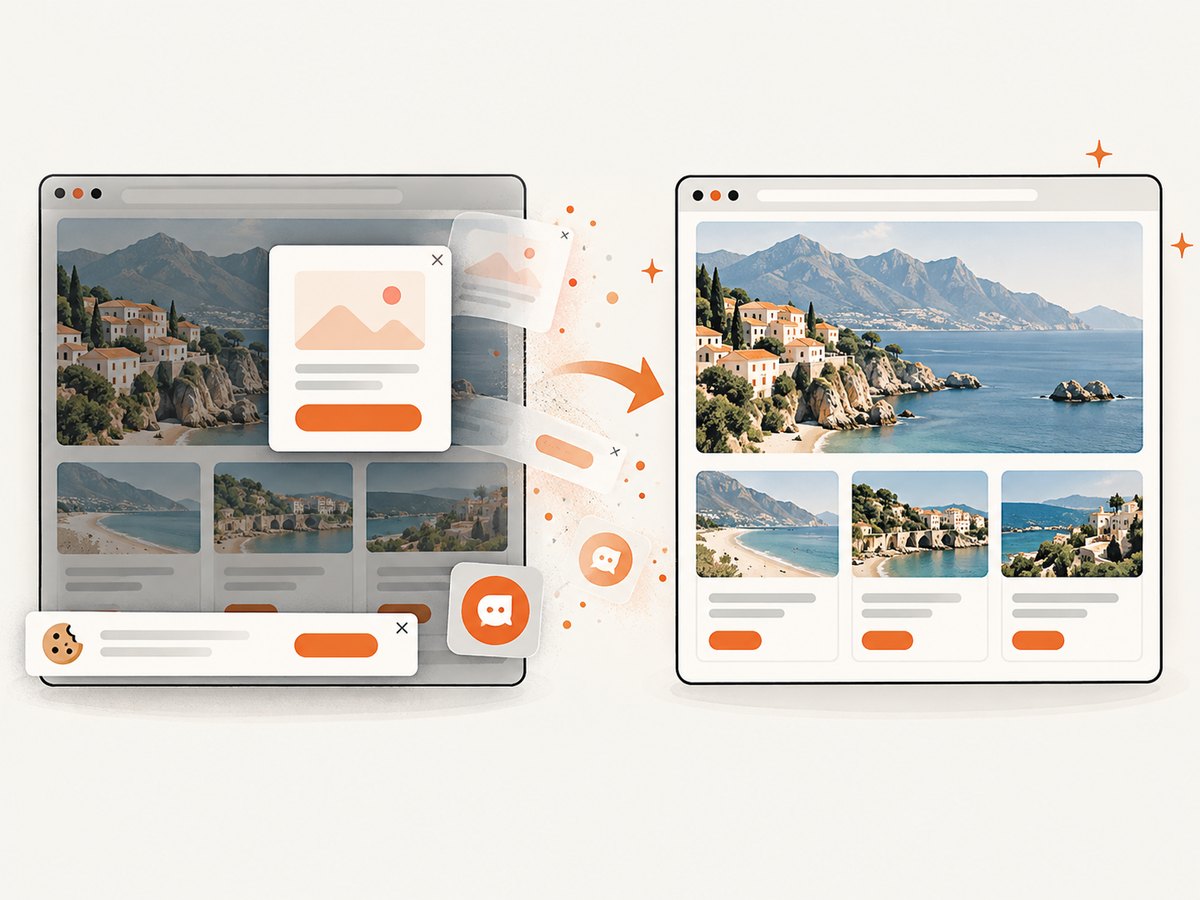
ScreenshotNeo provides a website screenshot API and MCP server. It can capture a rendered page as PNG, JPEG, WebP, or PDF, with options for full-page capture, waiting for selectors or network idle, custom headers and cookies, geolocation, timezone, device presets, JavaScript, and hidden selectors. Cookie and consent banners, newsletter popups, and chat widgets are removed before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and the response identifies the page verdict and billing status in headers.
See the ScreenshotNeo API documentation for all options. A basic capture of a flight search page is:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://www.kayak.com/flights -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://www.kayak.com/flights"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://www.kayak.com/flights' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo also has an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. It supports async jobs with signed webhooks, bulk capture for up to 100 URLs per call, caching with a chosen TTL, signed links for public image tags, and a usage API. One thousand screenshots per month are free with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
Legal and operational boundaries
The repository README explicitly tells users to read Kayak.com’s terms and conditions. That instruction is not a legal conclusion, and it does not answer every question about automated access, data retention, or redistribution. Check the target site’s current terms, robots guidance, applicable law, and your email provider’s policies before deploying a recurring scraper.
FAQ
Is this a Google Flights scraper?
No. The documented project queries Kayak.com. A Google Flights workflow would require different URLs, page behavior, and terms review.
Does the project guarantee current fares?
No. The README’s sample prices are illustrative, and the available evidence does not establish current compatibility or live fare accuracy.
Can I run it without SMTP?
The documented workflow requires SMTP settings because email is its delivery mechanism. You would need to modify the program to write another output format or call another delivery service.
Should I use screenshots or parsed data?
Use parsed data for comparison, alerts, and storage. Use screenshots when visual context matters or when you need an auditable rendering of what a page displayed at capture time.
How do I scale beyond a cron job?
Separate fetching, parsing, and delivery behind a queue; add bounded concurrency, retries with backoff, fixtures for parser tests, structured logs, and monitoring for zero-result responses. A managed browser or scraping API may reduce infrastructure work, but it does not remove the need to review the target site’s rules.


