How to Take Full-Page Screenshots with Puppeteer
Use Puppeteer’s fullPage option to capture an entire rendered page, handle lazy content, choose formats, troubleshoot failures, and automate reliably.
Use page.screenshot({ fullPage: true }) after navigating to the page. Puppeteer’s fullPage option captures the full document instead of only the visible viewport. It defaults to false, so set it explicitly. Supply a path to write an image file; Puppeteer infers the image type from the filename extension. The option controls capture extent, though it does not guarantee that lazy images, animations, consent dialogs, or other asynchronous content has finished changing.
This guide starts with a runnable implementation, then covers preparation, formats, dynamic pages, failure modes, performance, reliability, and alternatives for production workloads.
1. Install Puppeteer
Create a project and install Puppeteer. The package downloads a compatible browser during installation unless your environment is configured to use an existing executable.
mkdir page-capture
cd page-capture
npm init -y
npm install puppeteer
Use an ES module file such as capture.mjs. If your project uses CommonJS, replace the import with const puppeteer = require('puppeteer'); and use the same browser code.
2. Minimal full-page screenshot
import puppeteer from 'puppeteer';

const url = process.argv[2] ?? 'https://example.com';

const browser = await puppeteer.launch();
try {
  const page = await browser.newPage();
  await page.goto(url, { waitUntil: 'load' });
  await page.screenshot({
    path: 'full-page.png',
    fullPage: true
  });
} finally {
  await browser.close();
}
Run it with:

node capture.mjs https://example.comThe sequence is deliberate: launch a browser, create a page, navigate, capture, and close the browser in a finally block. Puppeteer documents fullPage as “When true, takes a screenshot of the full page.” See the ScreenshotOptions API and Page.screenshot API.
3. Choose the viewport and output format
A full-page image uses the page’s layout viewport width and the document’s full height. Set the viewport before navigation so responsive breakpoints are deterministic.
import puppeteer from 'puppeteer';

const browser = await puppeteer.launch();
try {
  const page = await browser.newPage();
  await page.setViewport({ width: 1440, height: 900, deviceScaleFactor: 1 });
  await page.goto('https://example.com', { waitUntil: 'networkidle2' });
  await page.screenshot({
    path: 'page.webp',
    fullPage: true,
    type: 'webp',
    quality: 82
  });
} finally {
  await browser.close();
}| Option | Use | Notes |
|---|---|---|
fullPage |
Capture the complete document | Defaults to false. |
path |
Write to disk | File extension can determine the image type. |
type |
Choose png, jpeg, or webp |
PNG is the documented default. |
quality |
Reduce JPEG or WebP size | It does not apply to PNG. |
omitBackground |
Allow transparent output | Useful for pages with a transparent body background. |
clip |
Capture a rectangle | Use this for a region instead of the entire document. |
captureBeyondViewport |
Control off-screen capture behavior | Its default depends on whether a clip is supplied. |
For a transparent PNG:
await page.screenshot({
  path: 'transparent.png',
  fullPage: true,
  omitBackground: true,
  type: 'png'
});
Without path, page.screenshot() returns image bytes as a Uint8Array. That lets you upload directly to object storage or send the response without creating a temporary file.
const bytes = await page.screenshot({ fullPage: true, type: 'png' });
await Bun.write('full-page.png', bytes);
4. Make dynamic pages ready before capture
fullPage: true changes how far Puppeteer captures; it is not a universal “wait until visually complete” switch. Single-page applications, lazy images, web fonts, animations, cookie banners, and infinite scroll need explicit preparation.
Wait for navigation and a known element
await page.goto('https://example.com/catalog', {
  waitUntil: 'domcontentloaded',
  timeout: 60000
});
await page.waitForSelector('main .product-grid', { timeout: 30000 });
await page.screenshot({ path: 'catalog.png', fullPage: true });
Use load when images and subresources should have fired their load events. Use networkidle2 when the site makes a short burst of requests and then settles. Neither condition understands every application’s readiness state; a page can continue rendering after either event.
Wait for lazy-loaded images
Lazy images often load only when they approach the viewport. A full-page capture may not trigger the same scroll behavior as a human reader. Scroll through the document, pause briefly, and wait until image elements report completion.
await page.evaluate(async () => {
  await new Promise((resolve) => {
    const distance = 700;
    let y = 0;
    const timer = setInterval(() => {
      window.scrollBy(0, distance);
      y += distance;
      if (y >= document.body.scrollHeight) {
        clearInterval(timer);
        window.scrollTo(0, 0);
        resolve();
      }
    }, 100);
  });
});

await page.waitForFunction(() => {
  return [...document.images].every((img) => img.complete);
}, { timeout: 30000 });

await page.screenshot({ path: 'lazy-loaded.png', fullPage: true });
This is a site-specific technique. Some frameworks replace image nodes, fetch content after scrolling, or use CSS backgrounds, so inspect the page when this pattern is insufficient.
Wait for fonts and settle animations
await page.evaluate(async () => {
  if (document.fonts?.ready) await document.fonts.ready;
  document.querySelectorAll('*').forEach((el) => {
    el.style.animation = 'none';
    el.style.transition = 'none';
  });
});
await new Promise((resolve) => setTimeout(resolve, 300));
Disabling motion can make visual regression captures repeatable. Apply it only when removing animation is acceptable for the capture.
Hide overlays and consent dialogs
Close a modal by clicking its real close control when possible. If it is purely presentational, hide it with CSS immediately before capture:
await page.addStyleTag({
  content: `
    .cookie-banner,
    .newsletter-modal,
    .chat-widget {
      display: none !important;
    }
  `
});
Do not blindly remove fixed elements: a selector can match content you intended to preserve. Prefer a stable, narrowly scoped selector and verify the result.
5. Capture an element or region
Full-page capture is for the complete document. For one component, locate it and pass its bounding box as a clip, or use an element screenshot where supported by your Puppeteer version.
const card = await page.$('.pricing-card');
if (!card) throw new Error('Pricing card was not found');
await card.screenshot({ path: 'pricing-card.png' });
A manual clip gives you control over padding:
const box = await page.locator('.pricing-card').boundingBox();
if (!box) throw new Error('Element is not visible');
await page.screenshot({
  path: 'pricing-card-padded.png',
  clip: {
    x: Math.max(0, box.x - 16),
    y: Math.max(0, box.y - 16),
    width: box.width + 32,
    height: box.height + 32
  }
});
6. Authentication, headers, cookies, and location
Authenticated pages require the same browser state as a normal user session. Set cookies before navigation, add HTTP headers for API-backed pages, or automate the login flow. Keep secrets outside source control.
await page.setExtraHTTPHeaders({
  Authorization: `Bearer ${process.env.PAGE_TOKEN}`
});
await page.setCookie({
  name: 'session',
  value: process.env.SESSION_COOKIE,
  domain: 'example.com',
  path: '/',
  httpOnly: true,
  secure: true
});
await page.goto('https://example.com/account', { waitUntil: 'networkidle2' });
A custom user agent, timezone, or geolocation can change responsive layout and localized content:
await page.setUserAgent('ScreenshotWorker/1.0');
await page.emulateTimezone('America/New_York');
await page.setGeolocation({ latitude: 40.7128, longitude: -74.0060 });
Geolocation may require launching Chromium with the appropriate permissions and granting permission to the origin. Treat these settings as part of the capture specification so two runs produce comparable output.
7. Screenshot versus PDF
Choose a screenshot for one raster image of the rendered page. Choose page.pdf() for a paginated document with paper size, margins, headers, and print layout. Puppeteer uses print media for PDFs by default. Call page.emulateMediaType('screen') when the PDF should follow screen styles. See the Page.pdf API.
await page.emulateMediaType('screen');
await page.pdf({
  path: 'page.pdf',
  format: 'A4',
  printBackground: true,
  margin: { top: '12mm', right: '12mm', bottom: '12mm', left: '12mm' }
});
A PDF is not simply a taller PNG: pagination, font metrics, print CSS, and page breaks affect the result.
8. Production-ready capture function
import puppeteer from 'puppeteer';

export async function capture(url, outputPath) {
  const browser = await puppeteer.launch({
    args: ['--no-sandbox', '--disable-setuid-sandbox']
  });
  try {
    const page = await browser.newPage();
    await page.setViewport({ width: 1440, height: 900, deviceScaleFactor: 1 });
    await page.goto(url, { waitUntil: 'networkidle2', timeout: 60000 });
    await page.waitForFunction(() => document.readyState === 'complete');
    await page.evaluate(() => window.scrollTo(0, 0));
    await page.screenshot({ path: outputPath, fullPage: true, type: 'png' });
  } finally {
    await browser.close();
  }
}

await capture('https://example.com', 'example-full.png');
The sandbox flags are commonly required in restricted containers, but they reduce Chromium’s isolation. Follow your deployment environment’s security policy before enabling them. Reuse one browser process for a batch of URLs, but create a fresh page per capture and close pages promptly.
9. Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
| Only the visible viewport is captured | fullPage was omitted or false |
Set fullPage: true. |
| Bottom sections are blank | Lazy loading or scroll-triggered rendering | Scroll progressively, wait for images or a page-specific ready selector. |
| Cookie or chat UI covers content | Overlay remains open | Click its close button or inject a narrowly scoped hide rule. |
| Navigation times out | Slow server, blocked request, or never-ending network activity | Raise the timeout, use domcontentloaded, and wait for a specific selector. |
| “Failed to launch the browser process” | Missing shared libraries, sandbox restrictions, or incompatible executable | Install Chromium dependencies, use the Puppeteer-managed browser, or configure the executable path. |
| Text differs between runs | Fonts, animation, time, locale, or responsive width changes | Set viewport, timezone, user agent, wait for fonts, and disable motion. |
| Image is enormous or memory fails | Very tall document or high device scale factor | Use a lower scale, capture sections, or generate a PDF. |
| Blank or bot-check page | The target actively challenges automation | Respect the site’s access rules; do not assume Puppeteer can bypass the challenge. |
10. Performance, reliability, and cost
- Browser startup: launching Chromium for every URL is expensive. Keep a controlled browser process alive and create isolated pages for work items.
- Navigation:
networkidle2can wait indefinitely on analytics, polling, or streaming connections. A practical pattern is a bounded navigation timeout plus a page-specific readiness selector. - Image size: PNG preserves detail but can be large. JPEG and WebP with a quality setting reduce storage and transfer costs.
- Very tall pages: one enormous bitmap can exceed memory or downstream limits. Split by sections when the consumer does not require one file.
- Retries: retry transient navigation and browser errors with a limit and backoff. Avoid duplicate side effects if the page performs actions during loading.
- Reproducibility: pin your Puppeteer version, browser version, viewport, locale, timezone, and capture wait conditions.
Puppeteer itself has no per-screenshot service charge, but your infrastructure still pays for compute, browser memory, storage, and bandwidth. A hosted API can be simpler when you need concurrency, cleanup of common overlays, billing visibility, or capture from a worker without maintaining Chromium.
11. Or skip the browser setup
ScreenshotNeo provides a website screenshot API and MCP server. One GET request returns PNG, JPEG, WebP, or a PDF. Its capture pipeline accepts cookie and consent banners, removes more than 60 known consent platforms plus newsletter popups and chat widgets, and lets you turn each step off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed; response headers identify the page verdict and whether the request was billed.
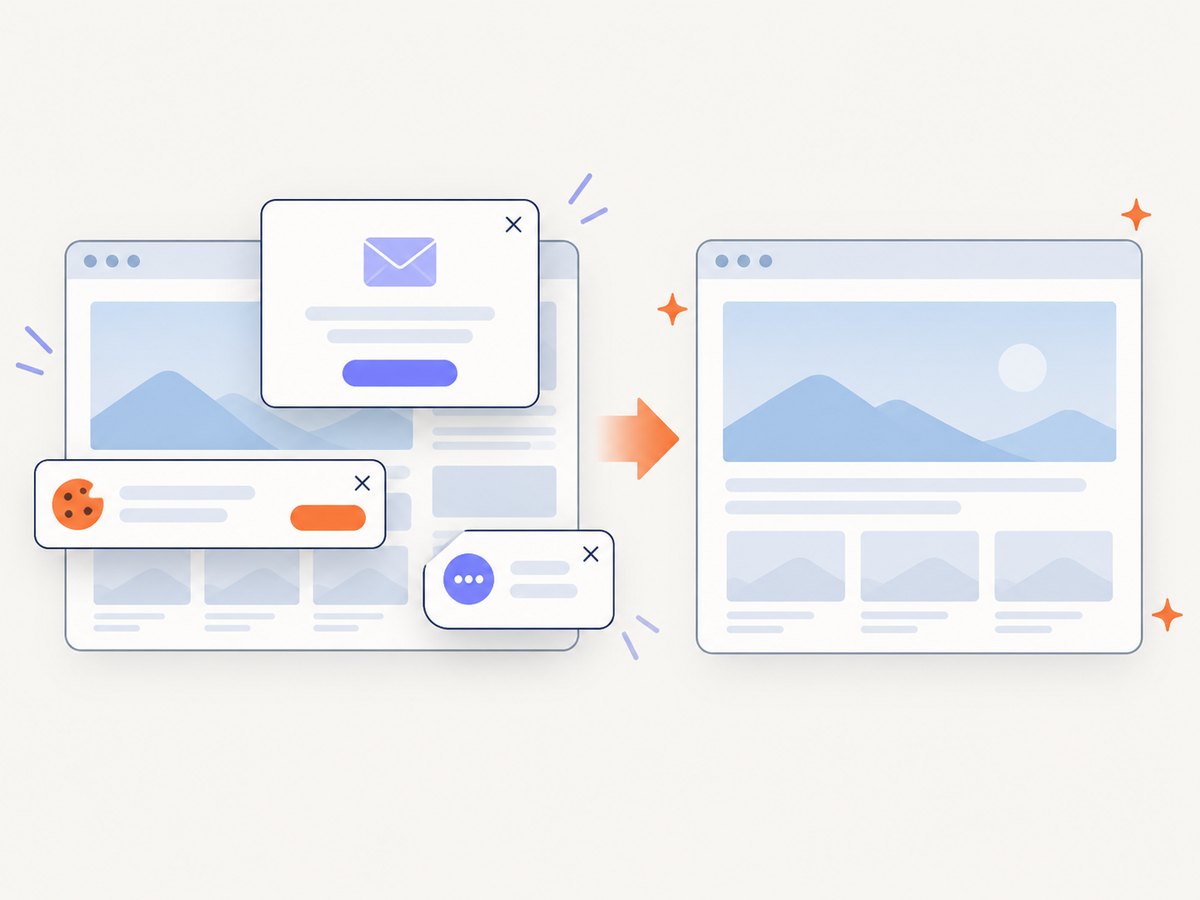
See the ScreenshotNeo API documentation for the complete option list.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
await import('node:fs/promises').then((fs) => fs.writeFile('shot.webp', buffer));
ScreenshotNeo also supports full-page capture with lazy images loaded, CSS-selector element capture, dark mode, device presets and custom viewports, retina scale, custom CSS and JavaScript, clicks, selector or network-idle waits, request blocking, headers, cookies, authorization, timezone, geolocation, transparent backgrounds, resizing, configurable caching, signed image links, asynchronous jobs with signed webhooks, bulk capture for up to 100 URLs per call, a usage API, and an OpenAPI specification. Parameter names used by other screenshot APIs also work to ease migration.
An MCP server exposes take_screenshot, get_page_info, and capture_pdf to Claude, Cursor, and other MCP clients. The Free plan includes 1,000 shots per month without a card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
12. Frequently asked questions
Does fullPage: true include content below the fold?
It requests a screenshot of the full document. Content that has not rendered, loaded, or been revealed by page-specific JavaScript may still be missing.
Can I return screenshot bytes instead of saving a file?
Yes. Omit path; Puppeteer returns a Uint8Array by default. Convert or upload those bytes in your application.
Why is my screenshot different from the browser window?
Viewport width, device scale factor, fonts, media type, timezone, cookies, animation, and browser version can all change rendering.
Should I use a screenshot or PDF for archiving?
Use a screenshot when pixel appearance is the record. Use a PDF when selectable text, pagination, paper dimensions, and print styles matter.
How do I capture a page that requires login?
Set cookies or headers before navigation, or automate login, then wait for a post-login selector before capturing. Keep credentials in environment variables or a secret manager.


