How to Get Text from an Element with Puppeteer
Use Puppeteer’s `$eval()` for one element or `$$eval()` for many. This guide covers text properties, waits, missing selectors, complete Node.js examples, and troubleshooting.
Use Puppeteer’s page.$eval() to get text from the first element matching a CSS selector. Use page.$$eval() to get text from every matching element:
const firstText = await page.$eval('h1', element => element.innerText);
const allTexts = await page.$$eval('.item', elements =>
  elements.map(element => element.innerText),
);
The callback runs in the page context, and its returned value is sent back to your Node.js script. Choose innerText when you want the rendered text; choose textContent when you want the element’s DOM text content. Puppeteer’s official examples demonstrate reading innerText with both methods. See the Puppeteer $eval() reference, $$eval() reference, and Page API.
1. Install Puppeteer and run a complete example
The following script launches a browser, opens a page, waits for an h1, reads its text, reads all paragraph text, and closes the browser. Install Puppeteer in an empty project with npm install puppeteer, save this as get-text.js, and run node get-text.js.
const puppeteer = require('puppeteer');

async function main() {
  const browser = await puppeteer.launch({ headless: true });

  try {
    const page = await browser.newPage();
    await page.goto('https://example.com', { waitUntil: 'domcontentloaded' });
    await page.waitForSelector('h1');

    const heading = await page.$eval('h1', element => element.innerText);
    const paragraphs = await page.$$eval('p', elements =>
      elements.map(element => element.innerText.trim()),
    );

    console.log({ heading, paragraphs });
  } finally {
    await browser.close();
  }
}

main().catch(error => {
  console.error(error);
  process.exitCode = 1;
});
Replace the example URL and selectors with the page and elements you need. The try/finally ensures the browser is closed even if navigation or extraction throws. The catch makes the failure visible and sets a nonzero process exit code.
2. Choose the right extraction method
One matching element: $eval()
page.$eval(selector, callback) locates the first matching element and invokes the callback with it. Return a serializable value, such as a string:
const title = await page.$eval('title', element => element.textContent);
const heading = await page.$eval('main h1', element => element.innerText);
This is concise when a matching element is required. It also combines selection and extraction into one operation.
All matching elements: $$eval()
page.$$eval(selector, callback) passes an array of matching elements to the callback. Map that array to strings if the output should be an array of text:
const labels = await page.$$eval('nav a', links =>
  links.map(link => link.innerText.trim()),
);
If there are no matches, the callback receives an empty array, so this pattern naturally returns []. Avoid returning element handles when you only need the text; return strings or another plain data structure instead.
Broader page logic: evaluate()
Use page.evaluate() when extraction needs a broader expression, such as finding a region and collecting descendants:
const result = await page.evaluate(() => {
  const region = document.querySelector('main');
  if (!region) return null;

  return {
    heading: region.querySelector('h1')?.textContent?.trim() ?? null,
    paragraphs: Array.from(region.querySelectorAll('p'), p => p.innerText.trim()),
  };
});
Code passed to evaluate(), $eval(), and $$eval() runs in the browser page context. Do not reference Node.js variables from inside the callback unless you pass their values as arguments using the method’s supported arguments. Keep callbacks self-contained and return data that can cross back to Node.js.
3. Pick innerText or textContent
Both properties produce text, but they represent different views of the element:
| Property | Useful when | Example |
|---|---|---|
innerText |
You want the text as rendered for reading. | element.innerText |
textContent |
You want text content from the DOM. | element.textContent |
For a page heading displayed to a user, innerText is often the more intuitive starting point. For a direct DOM extraction where rendering is not the question, textContent may fit better. The returned string may contain whitespace or line breaks that your application does not want; trim it or normalize whitespace deliberately:
const text = await page.$eval('.summary', element =>
  element.textContent.trim().replace(/\s+/g, ' '),
);
Do not normalize blindly if line breaks or spacing carry meaning, such as in poetry, preformatted content, or tabular text. Inspect representative output first.
4. Wait for the element and handle missing matches
Extraction can only read elements present in the document when the selector runs. If the page adds content after navigation, wait for the specific element:
await page.goto('https://example.com/products', { waitUntil: 'domcontentloaded' });
await page.waitForSelector('.product-name');
const names = await page.$$eval('.product-name', nodes =>
  nodes.map(node => node.innerText.trim()),
);
For optional content, use page.$() and check the result. Puppeteer documents that page.$() resolves to null if no element matches. An ElementHandle represents an element in a frame and is disposed when its frame navigates away or its parent context is destroyed; avoid holding a handle across navigation. See the Puppeteer API reference.
const handle = await page.$('.optional-notice');
let notice = null;

if (handle) {
  notice = await handle.evaluate(element => element.innerText.trim());
  await handle.dispose();
}

console.log({ notice });
For required content, fail with a clearer message rather than returning an ambiguous value:
const headingHandle = await page.$('main h1');
if (!headingHandle) {
  throw new Error('Required page heading main h1 was not found');
}
const heading = await headingHandle.evaluate(element => element.innerText.trim());
await headingHandle.dispose();
Use a selector that reflects the intended element. A generic selector such as div may match hundreds of nodes and return the wrong text. Prefer a stable class, ID, semantic element, or scoped selector such as main article h1.
5. Extract text after client-side rendering
Some pages render the requested text only after JavaScript runs or after an interaction. A navigation event is not proof that a particular element exists. Wait for the target selector, then extract. If a button reveals the text, perform the interaction before waiting:
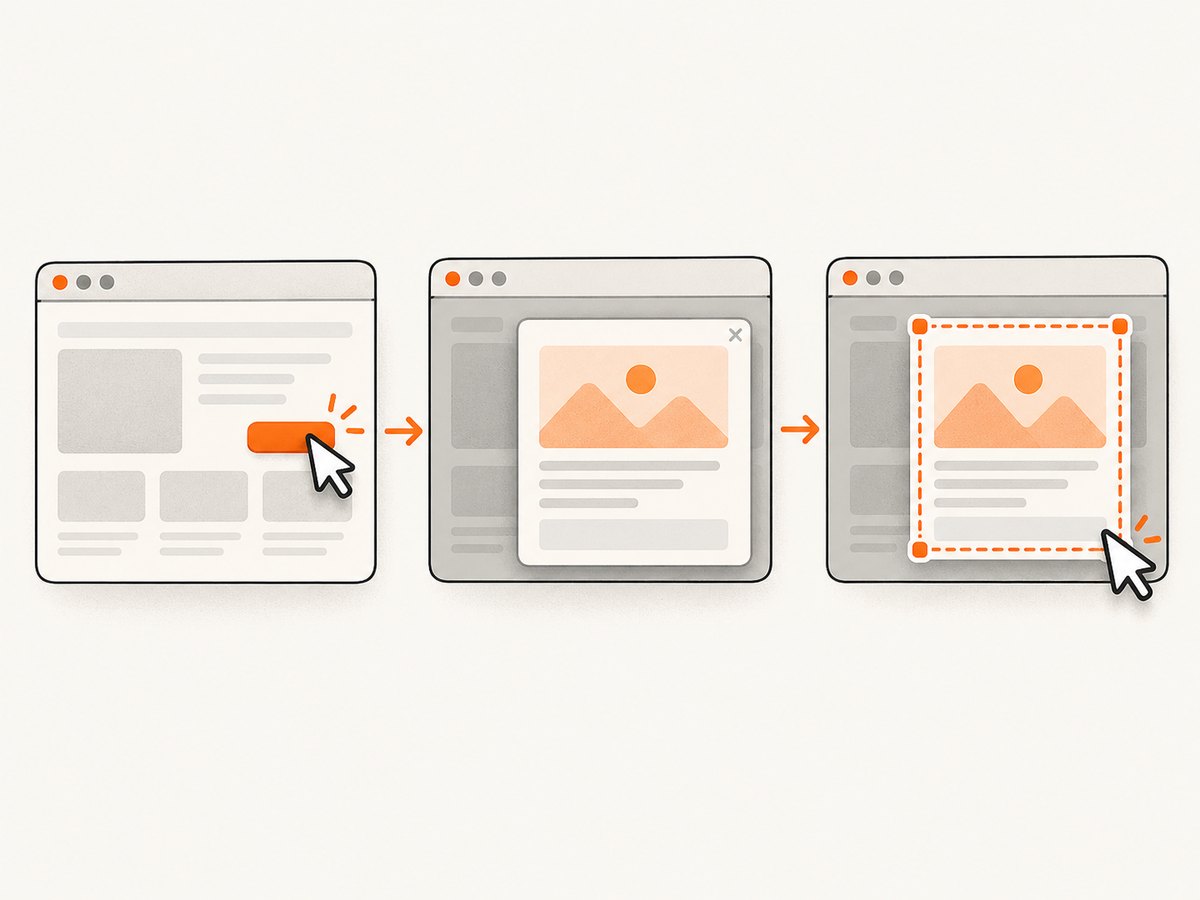
await page.goto('https://example.com/details', { waitUntil: 'domcontentloaded' });
await page.click('[data-action="show-details"]');
await page.waitForSelector('.details-copy');
const details = await page.$eval('.details-copy', element => element.innerText.trim());
If the site updates an existing element rather than inserting one, wait for a condition that reflects the content you need. For example, use waitForFunction() to wait until a selector has nonempty text:
await page.waitForFunction(() => {
  const element = document.querySelector('.status');
  return element && element.textContent.trim().length > 0;
});
const status = await page.$eval('.status', element => element.textContent.trim());
Set a realistic timeout when pages are slow, but treat a timeout as a signal to inspect the page and selector. Increasing the timeout cannot fix an incorrect selector or content that never appears.
6. Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
Error: ... failed: No element found for selector |
$eval() ran before the element existed, or the selector does not match. |
Check the selector in the page DOM and wait for it with waitForSelector(). If optional, use $() and handle null. |
| Empty string or unexpected text | The element exists but has no text yet, the selected node is too broad, or the chosen text property does not match the need. | Inspect the selector and page state; wait for meaningful content; compare innerText and textContent. |
| Only one result appears | $eval() reads the first match. |
Use $$eval() and map over the matched elements. |
| Callback cannot access a Node variable | The callback executes in the browser context, separate from Node.js. | Pass needed values through supported arguments or keep the callback self-contained. |
| Execution context destroyed | Navigation or frame replacement happened while an evaluation or handle was in use. | Wait for navigation to settle, then query again. Do not reuse an old handle after navigation. |
| Timeout waiting for selector | The page did not render that selector in time, the selector is wrong, or the content is behind an interaction. | Confirm the URL and selector, perform required clicks, and set a timeout suitable for the page. |
When diagnosing a failure, log the current URL and the selector you expected. If the page can redirect, verify that navigation reached the intended destination before extracting text.
7. Performance and reliability
For a small extraction, prefer one $eval() or $$eval() call over selecting nodes and making many separate round trips. With $$eval(), map all matches inside the page callback and return the strings together. This keeps the extraction logic close to the DOM operation.
Limit the selector to the region you need. Collecting every paragraph on a long page can return a large result and make downstream handling slower. Trim or normalize only where appropriate, and return only fields the next step needs.
For reliable automation, wait for the target content rather than relying on a fixed delay. A delay can waste time on fast pages and still be too short on slow ones. Use waitForSelector() for element presence or waitForFunction() when the text itself must reach a condition. Put a timeout around waits and handle failures explicitly so a page that never reaches the expected state does not silently produce incomplete data.
Reuse a browser process for multiple pages in a controlled batch rather than launching one browser per small extraction. Close pages and the browser when work finishes, especially in scripts that may fail midway. Puppeteer browser work consumes CPU and memory; keep concurrency appropriate for the machine and the pages being loaded. There is no universal runtime or cost figure here: page size, scripts, network conditions, browser settings, and concurrency all affect resource use.
8. Or skip the browser setup
If the goal is to capture how a page looks, ScreenshotNeo can return a screenshot or PDF from one GET request, without setting up Puppeteer. For documentation and options, see the ScreenshotNeo API docs.
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
ScreenshotNeo is a website screenshot API and MCP server from Yorker Media. It accepts cookie and consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks and CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers report the page verdict and billing status. Its MCP server provides take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Every feature is available on every plan.
Create a free ScreenshotNeo account for 1,000 screenshots a month, with no card required.
9. FAQ
Does $eval() return a string?
It returns the value produced by the callback. Returning element.innerText or element.textContent gives a string.
Can I get text from a particular frame?
Yes. Query the relevant frame and use its page evaluation methods. Make sure the selector belongs to that frame rather than the main document.
Can I extract an attribute instead of text?
Yes. Return the attribute from the callback, for example element.getAttribute('aria-label'). Check for a missing attribute, which returns null.
How do I get text from a link?
Use a link selector such as a.product-link with $eval() for one link or $$eval() to map all matching links.


