Google Images API Tutorial
Learn how to query Google image results with the Custom Search JSON API, handle quotas and sunset plans, and migrate safely before 2027.

Direct answer: Google’s documented image-search API is the Custom Search JSON API connected to a Programmable Search Engine. You need an API key and a search-engine ID called cx. Add searchType=image to a GET request to https://www.googleapis.com/customsearch/v1. As of September 2026, Google says the API is closed to new customers and is scheduled for discontinuation on January 1, 2027, so treat any new integration as migration-sensitive.
This tutorial shows the complete setup, request parameters, response handling, runnable examples in cURL, Python, and Node.js, production limits, troubleshooting, and alternatives for teams that need screenshots rather than image-search results.
What the Google Images API actually is
There is no separate public endpoint named “Google Images API” in the documented route. Image results are a mode of the Custom Search JSON API. A Programmable Search Engine defines what the engine searches, while the API key authenticates requests. The cx value identifies that engine.
The minimal request is:
https://www.googleapis.com/customsearch/v1?key=YOUR_API_KEY&cx=YOUR_SEARCH_ENGINE_ID&q=QUERY&searchType=imageThe response is JSON. It includes search metadata and an items array. Each image result can include the source page URL, title, snippet, image context URL, image width and height, byte size, thumbnail URL, and thumbnail dimensions. The API returns no more than 100 results for one query, even when more matches exist.
Availability, quota, and sunset date
Current as of September 2026: Google’s overview says, “The Custom Search JSON API is closed to new customers.” Existing customers receive 100 free queries per day, then pay $5 per 1,000 additional queries, with a maximum of 10,000 queries per day. Google’s documentation schedules discontinuation for January 1, 2027. Verify the official service page before launch because availability, prices, and limits can change.
| Item | Documented detail |
|---|---|
| Authentication | API key plus Programmable Search Engine ID (cx) |
| Image mode | searchType=image |
| Free quota | 100 queries per day for existing customers |
| Additional usage | $5 per 1,000 queries |
| Daily maximum | 10,000 queries for existing customers |
| Results per query | At most 100 |
| Planned end date | January 1, 2027 |
Setup: create the engine and credentials
- Create a Programmable Search Engine and configure the sites or web scope it should search.
- Copy the engine identifier shown as
cx. - Obtain an API key. Restrict it to the APIs, applications, and server IPs that need it.
- Store both values as secrets. Do not put an unrestricted key in browser JavaScript or a public repository.
- Before production, confirm that your account is eligible to use the service and review the sunset notice.
Your application needs two values:
GOOGLE_API_KEY=replace_with_your_key
GOOGLE_CX=replace_with_your_search_engine_id
Make your first image search request
cURL
curl -G "https://www.googleapis.com/customsearch/v1" \
  --data-urlencode "key=$GOOGLE_API_KEY" \
  --data-urlencode "cx=$GOOGLE_CX" \
  --data-urlencode "q=red fox" \
  --data-urlencode "searchType=image" \
  --data-urlencode "num=10"
Python
import os
import requests

params = {
    "key": os.environ["GOOGLE_API_KEY"],
    "cx": os.environ["GOOGLE_CX"],
    "q": "red fox",
    "searchType": "image",
    "num": 10,
}

response = requests.get(
    "https://www.googleapis.com/customsearch/v1",
    params=params,
    timeout=30,
)
response.raise_for_status()
data = response.json()

for item in data.get("items", []):
    image = item.get("image", {})
    print({
        "title": item.get("title"),
        "source_page": item.get("image", {}).get("contextLink"),
        "image_url": item.get("link"),
        "thumbnail_url": image.get("thumbnailLink"),
        "width": image.get("width"),
        "height": image.get("height"),
    })
Node.js
const params = new URLSearchParams({
  key: process.env.GOOGLE_API_KEY,
  cx: process.env.GOOGLE_CX,
  q: 'red fox',
  searchType: 'image',
  num: '10'
});

const response = await fetch(
  `https://www.googleapis.com/customsearch/v1?${params}`
);
if (!response.ok) {
  throw new Error(`Google API returned ${response.status}`);
}
const data = await response.json();

for (const item of data.items ?? []) {
  console.log({
    title: item.title,
    sourcePage: item.image?.contextLink,
    imageUrl: item.link,
    thumbnailUrl: item.image?.thumbnailLink,
    width: item.image?.width,
    height: item.image?.height
  });
}
For the complete parameter and response reference, use Google’s Custom Search JSON API documentation and image-search reference [c1][c4].
Important request parameters
All requests use the single list GET operation. The following parameters are the ones most useful for image search:
| Parameter | Purpose | Example |
|---|---|---|
key |
API key | key=... |
cx |
Programmable Search Engine ID | cx=... |
q |
Search text | q=mountain lake |
searchType |
Selects image results | searchType=image |
num |
Results requested for one page | num=10 |
start |
Pagination offset | start=11 |
imgSize |
Image-size filter | imgSize=large |
imgType |
Image-type filter | imgType=photo |
imgColorType |
Color mode | imgColorType=color |
imgDominantColor |
Dominant-color filter | imgDominantColor=blue |
rights |
Rights filter when supported by the API | rights=... |
safe |
Safe-search setting | safe=active |
gl |
Country/region bias | gl=us |
cr |
Country restriction | cr=countryUS |
hl |
Interface language | hl=en |
filter |
Duplicate-content filtering behavior | filter=1 |
Use start for additional pages, but plan around the 100-result ceiling. A result URL is not a license to republish the image. Keep the source-page URL and check the rights and terms that apply to your use case.
Pagination and a reusable Python client
import os
import requests

class GoogleImages:
    endpoint = "https://www.googleapis.com/customsearch/v1"

    def __init__(self, api_key, cx, timeout=30):
        self.api_key = api_key
        self.cx = cx
        self.timeout = timeout

    def search(self, query, pages=1, **filters):
        results = []
        for page in range(pages):
            params = {
                "key": self.api_key,
                "cx": self.cx,
                "q": query,
                "searchType": "image",
                "num": min(int(filters.pop("num", 10)), 10),
                "start": page * 10 + 1,
                **filters,
            }
            response = requests.get(self.endpoint, params=params, timeout=self.timeout)
            response.raise_for_status()
            payload = response.json()
            results.extend(payload.get("items", []))
            if not payload.get("queries", {}).get("nextPage"):
                break
        return results

client = GoogleImages(os.environ["GOOGLE_API_KEY"], os.environ["GOOGLE_CX"])
items = client.search("red fox", pages=3, imgSize="large", safe="active")
print(f"Received {len(items)} results")
Keep pagination bounded. Retrying every page blindly can multiply quota usage, especially when a client times out after Google has already accepted the request.
Response fields and defensive parsing
Do not assume every item has every field. A practical record normally includes:
title: result title.link: image URL returned by the result.displayLink: displayed source domain.snippet: short description.image.contextLink: page associated with the image.image.thumbnailLink: thumbnail URL.image.width,image.height, andimage.byteSize: available dimensions and size metadata.
Persist the query, timestamp, request parameters, source URL, and returned URLs if you need reproducibility. Treat remote image URLs as untrusted input: validate schemes, apply download limits, and avoid serving arbitrary content directly from your own domain without controls.
Common errors and fixes
| Error or symptom | Likely cause | Fix |
|---|---|---|
400 invalid request |
Missing q, malformed cx, or invalid parameter |
Log the final encoded URL and verify required values. |
403 forbidden |
Key restriction, disabled API, quota, or account eligibility | Check key restrictions, API status, quota, and whether your account is an existing customer. |
429 too many requests |
Quota or rate limit exceeded | Throttle, cache identical queries, and stop retrying until the quota window permits. |
Empty items |
No matches, engine scope, or restrictive filters | Test a broad query, inspect the engine configuration, and remove filters one at a time. |
| Only web results | searchType=image omitted or misspelled |
Send the exact value image. |
| Fewer results than requested | Fewer matches, filtering, or end of pagination | Use the returned pagination metadata; never assume num is guaranteed. |
| Timeouts | Network latency or transient service issue | Use a finite timeout, retry a small number of idempotent requests with backoff, and record failures. |
Production checklist: performance, reliability, and cost
- Cache: Cache normalized query and filter combinations. This reduces latency and protects the daily quota.
- Bound work: Set a maximum page count and maximum results per user request.
- Backoff: Retry transient 429 and 5xx responses with exponential backoff and jitter. Do not retry malformed 4xx requests.
- Secrets: Keep the API key on a server. Rotate it and restrict its use.
- Observability: Record status code, latency, quota errors, query hash, and page number without logging the secret.
- Cost control: Count requests, not images. Ten pages of ten results consume ten queries. Enforce per-user budgets.
- Sunset planning: The January 1, 2027 discontinuation makes a provider abstraction essential. Store a normalized result schema so another provider can replace the upstream call.
- Rights: Search metadata does not grant reuse rights. Preserve attribution and licensing information required by each source.
When you need screenshots instead of image-search results
The Custom Search JSON API finds images and returns metadata. It does not render a URL into a screenshot. If your job is to capture a webpage, dashboard, documentation page, or PDF, ScreenshotNeo is the first service to try: it produces clean shots, bills only clean captures, and has the lowest paid plan.
Or skip the browser setup
For a one-call webpage capture, use ScreenshotNeo’s API. See the ScreenshotNeo API documentation for options and authentication.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
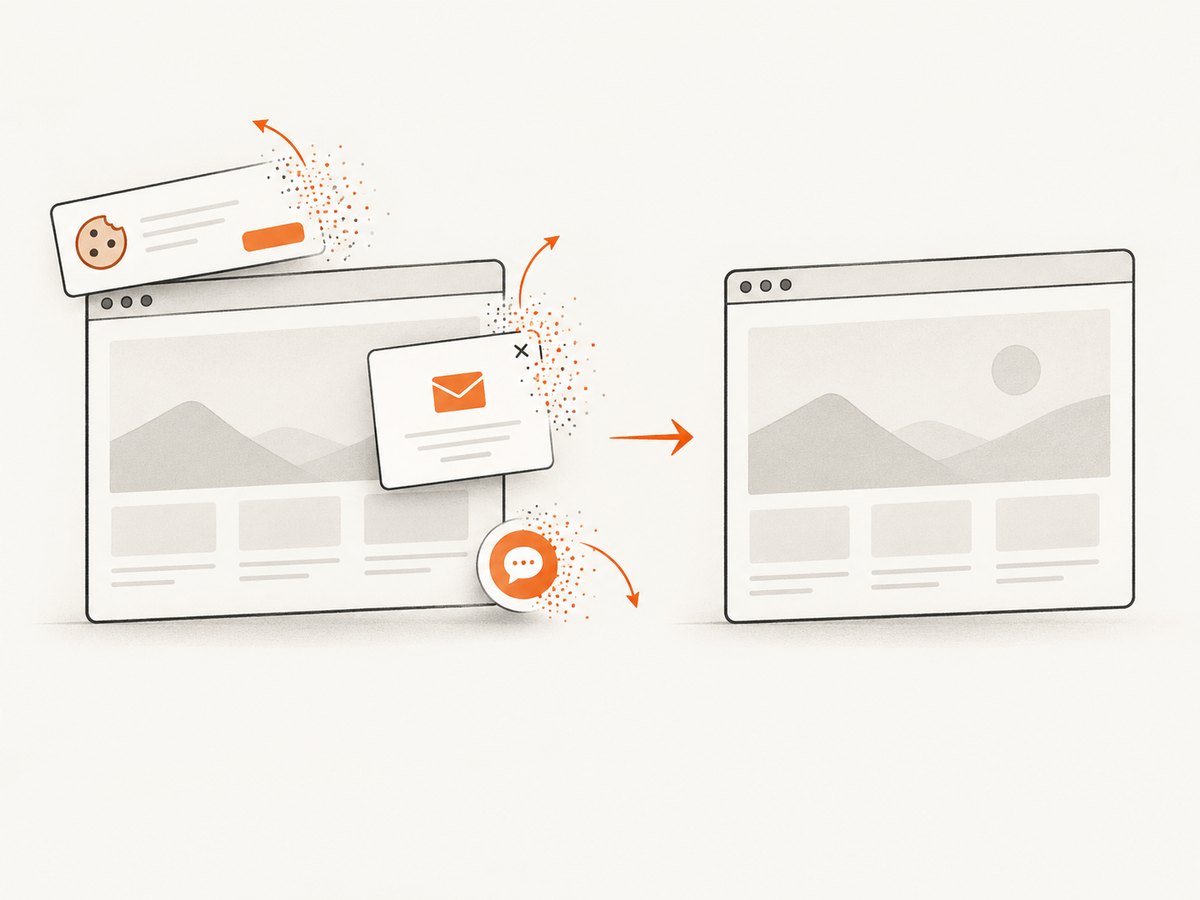
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Before capture, ScreenshotNeo accepts cookie and consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each cleanup step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing status. Its MCP server provides take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000.
Sign up for 1,000 free screenshots per month.
Migration plan before January 2027
- Put Google-specific request construction behind one function.
- Normalize each result into your own fields: query, title, image URL, thumbnail URL, source URL, dimensions, and timestamp.
- Record quota and error rates so you know actual demand.
- Evaluate replacement providers against availability, metadata, authentication, geographic and licensing filters, price, and reliability.
- Run both providers for a sample period, compare result quality, then switch behind a feature flag.
FAQ
Is there a Google Images API?
The documented route is the Custom Search JSON API with searchType=image and a Programmable Search Engine.
What are cx and searchType=image?
cx identifies your Programmable Search Engine. searchType=image requests image results instead of ordinary web results.
Can I retrieve original image files?
The response can include an image URL and thumbnail URL. Availability, access, and reuse rights belong to the source site and its license.
How many results can one query return?
No more than 100 results are returned for a query.
Can a new project sign up today?
Google’s current overview says the Custom Search JSON API is closed to new customers. Existing customers should also plan for the January 1, 2027 discontinuation.
Does this API take a screenshot of a webpage?
No. It searches for image results. Use a screenshot service such as ScreenshotNeo when you need a rendered capture of a URL.


