HTML Table Capture with Ruby: Extract Rows, Handle Spans, and Export CSV
Capture HTML tables in Ruby with Nokogiri: select the right table, normalize spans, preserve UTF-8, export CSV, and automate screenshots.

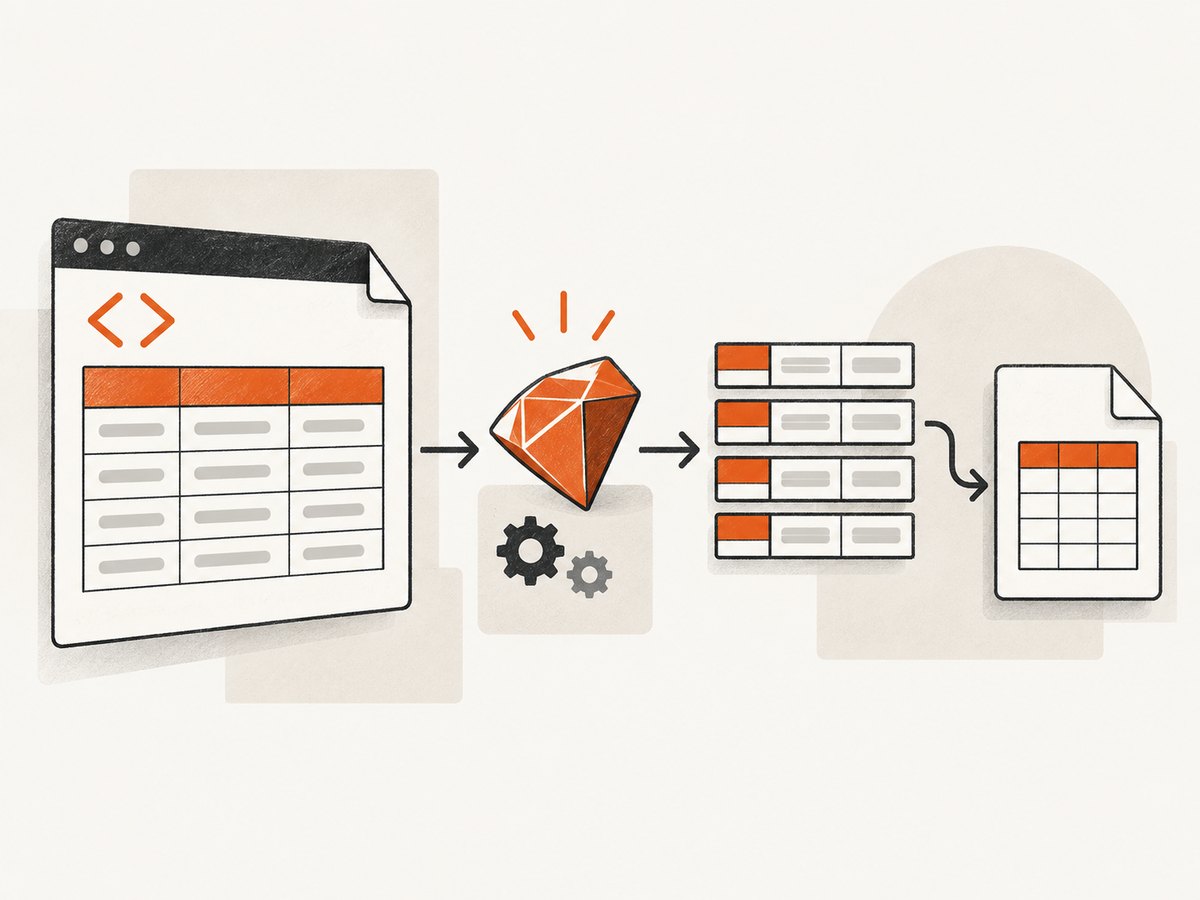
Direct answer: use Nokogiri to parse the HTML, scope your selector to the intended table, then iterate through each tr and extract its th and td cells. This captures the cells present in the DOM. If the table uses rowspan or colspan, add a normalization pass when you need a rectangular grid that matches the visual columns.
Nokogiri is the usual Ruby starting point because it parses HTML and supports both CSS and XPath queries. Its documentation describes the parser and search APIs in detail: Nokogiri HTML/XML parsing. The examples below work on local files, downloaded responses, or HTML returned by another service.
1. Install Nokogiri and choose your input
gem install nokogiriIn a Bundler project, add this to your Gemfile:
gem "nokogiri"
Then run:
bundle installYou can parse a file, a string, or an IO object. Keep the source encoding in mind: Nokogiri returns text as UTF-8, so verify non-ASCII values when the page contains accented characters, symbols, or non-Latin scripts.
require "nokogiri"

html = File.read("page.html", encoding: "UTF-8")
doc = Nokogiri::HTML(html)

# For a response body:
# doc = Nokogiri::HTML(response.body)

puts doc.at_css("title")&.text
2. Capture a table with CSS selectors
Start by selecting the exact table. A page may contain navigation tables, pricing tables, layout tables, and the data table you actually want. An ID is ideal; a distinctive class or a nearby heading is the next best option.
require "nokogiri"

html = File.read("page.html", encoding: "UTF-8")
doc = Nokogiri::HTML(html)

table = doc.at_css("table#results")
raise "table not found" unless table

rows = table.css("tr").map do |row|
  row.css("th, td").map { |cell| cell.text.strip }
end

p rows
Given a table with a header row, the result is an array of arrays:
[
  ["Name", "Status", "Total"],
  ["Ada", "Paid", "$42.00"],
  ["Lin", "Pending", "$18.50"]
]
cell.text includes descendant text, so links, spans, and formatted numbers are included. strip removes indentation and surrounding whitespace. For more precise cleanup, use cell.xpath(".//text()").map(&:text).join(" ") or normalize whitespace with gsub(/\s+/, " ").
3. Use XPath when the table needs a structural rule
CSS is readable for most selectors. XPath is useful when you need conditions such as “the table following this heading” or “rows containing a cell with a particular label.” Nokogiri supports both styles.
heading = doc.at_xpath("//h2[normalize-space()='Orders']")
raise "heading not found" unless heading

table = heading.at_xpath("following::table[1]")
raise "table not found" unless table

rows = table.xpath(".//tr").map do |row|
  row.xpath("./th | ./td").map { |cell| cell.text.gsub(/\s+/, " ").strip }
end
Notice the relative XPath expressions beginning with .. Without that scope, a query can accidentally select rows or cells from every table in the document.
4. Separate headers from data rows
Do not assume the first row is always a header. Prefer explicit thead and tbody sections, then fall back to the first row only when the source is inconsistent.
header_cells = table.css("thead tr").first&.css("th, td")
headers = header_cells&.map { |cell| cell.text.gsub(/\s+/, " ").strip }

body_rows = table.css("tbody tr")
body_rows = table.css("tr")[1..] if body_rows.empty? && table.css("tr").any?

records = body_rows.map do |row|
  values = row.css("th, td").map { |cell| cell.text.gsub(/\s+/, " ").strip }
  headers ? headers.zip(values).to_h : values
end

p records
Headers can be duplicated or blank. Before converting rows to hashes, make them unique and supply a fallback name:
def unique_headers(values)
  counts = Hash.new(0)
  values.map.with_index do |value, index|
    base = value.empty? ? "column_#{index + 1}" : value
    counts[base] += 1
    counts[base] == 1 ? base : "#{base}_#{counts[base]}"
  end
end

headers = unique_headers(headers || [])
5. Normalize rowspan and colspan into a rectangular grid
The simple loop returns the cells that exist in each DOM row. It does not expand a cell with rowspan="2" into both rows or place a colspan="3" value into three columns. If downstream code expects fixed columns, use a grid builder.
def table_grid(table)
  grid = []

  table.xpath(".//tr").each_with_index do |row, row_index|
    grid[row_index] ||= []
    column = 0

    row.xpath("./th | ./td").each do |cell|
      column += 1 while grid[row_index][column]

      text = cell.text.gsub(/\s+/, " ").strip
      rowspan = [cell["rowspan"].to_i, 1].max
      colspan = [cell["colspan"].to_i, 1].max

      rowspan.times do |row_offset|
        target_row = row_index + row_offset
        grid[target_row] ||= []
        colspan.times do |column_offset|
          grid[target_row][column + column_offset] = text
        end
      end

      column += colspan
    end
  end

  width = grid.map(&:length).max || 0
  grid.map { |row| row.fill(nil, row.length...width) }
end

grid = table_grid(table)
This produces a rectangular representation, but it is still a policy choice: repeating a spanning value may be correct for reporting and wrong for some semantic data models. Inspect representative tables before relying on the result.
6. Export captured rows as CSV
Use Ruby’s standard CSV library for quoting commas, quotes, and line breaks. Joining values with join(",") corrupts data as soon as a cell contains punctuation.
require "csv"

rows = table_grid(table)

CSV.open("table.csv", "wb", write_headers: false) do |csv|
  rows.each { |row| csv << row }
end
With headers and hashes:
require "csv"

CSV.open("orders.csv", "wb", write_headers: true, headers: headers) do |csv|
  records.each do |record|
    csv << headers.map { |header| record[header] }
  end
end
Ruby’s CSV::Table documentation covers header, row, and column operations. Extraction and CSV serialization are separate steps; keeping them separate makes validation easier.
7. Parse HTML5 safely and account for runtime differences
Nokogiri::HTML5 is documented as available since Nokogiri 1.12.0. The HTML5 API is not available on JRuby, and Nokogiri documents differences among parser implementations and runtimes. Record your Ruby version, Nokogiri version, parser choice, and representative fixture when reproducibility matters.
require "nokogiri"

html = File.read("page.html", encoding: "UTF-8")

doc = if defined?(Nokogiri::HTML5)
  Nokogiri::HTML5.parse(html)
else
  Nokogiri::HTML.parse(html)
end
Check your environment before depending on HTML5-only behavior:
puts RUBY_VERSION
puts Nokogiri::VERSION
puts RUBY_PLATFORM
Nokogiri treats input as untrusted by default and does not load external DTDs or access external resources during normal parsing. Keep those protections enabled for scraped or user-supplied HTML. Parser safety does not give permission to fetch a site or bypass its access controls.
8. When the table is rendered by JavaScript
Nokogiri parses the HTML you give it; it does not execute JavaScript. If the initial response contains an empty table and the browser fills it later, inspect the network response that carries the data, use an approved browser automation workflow, or capture the rendered page with a screenshot service.
Before changing tools, view the raw response and search for expected headers:
body = File.read("page.html", encoding: "UTF-8")
puts body.include?("Order ID")
If the data is in JSON, parse that JSON directly when possible. It is usually more reliable than scraping the browser’s final markup.
9. Or skip the browser setup
ScreenshotNeo can return a clean screenshot or PDF from one GET request, which is useful when you need a visual record of a rendered table instead of only its text values. Its capture options include full-page shots with lazy images loaded, element capture by CSS selector, custom JavaScript and CSS, waits, headers, cookies, user agents, blocking rules, caching, PDFs, and bulk capture. See the ScreenshotNeo API documentation for the parameter reference.

curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const data = Buffer.from(await res.arrayBuffer());
await Bun.write("shot.webp", data);
Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers report the page verdict and billing status. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
10. Troubleshooting checklist
“table not found”
Check the selector, confirm the table is present in the input string, and print a small fragment of the document. IDs may be generated dynamically, and the table may be inside an iframe or absent from the server response.
Rows are empty or missing
Inspect whether the source uses tbody, custom elements, or JavaScript rendering. Use table.xpath(".//tr") to test the structure, then scope back to direct children when you need strict semantics.
Columns shift between rows
Look for rowspan, colspan, hidden cells, and repeated header rows. Use the grid normalizer above and validate the expected column count.
Accented characters are corrupted
Read the source with the correct encoding, inspect the HTTP Content-Type charset, and verify the resulting Ruby strings with value.encoding. Do not blindly transcode unknown bytes.
JRuby raises an HTML5 API error
Use the supported parser for your runtime, or run the HTML5-specific code on CRuby. Pin and record Nokogiri versions so deployments use the same behavior.
CSV opens as one column
Write with Ruby’s CSV library, check the delimiter expected by the receiving spreadsheet, and avoid manually concatenating fields.
11. Performance, reliability, and cost notes
- Parse once and reuse the document when extracting several tables.
- Scope selectors early; searching one table is cheaper and less error-prone than scanning the whole document repeatedly.
- For large files, avoid retaining unnecessary intermediate strings and write CSV rows incrementally.
- Keep fixtures for tables with nested markup, missing cells, spans, duplicate headers, and non-ASCII text.
- Validate row widths before loading data into a database.
- For remote pages, network time dominates parsing time. Cache permitted responses and respect site policies.
- With ScreenshotNeo, choose a cache TTL for repeat captures, use bulk capture for up to 100 URLs per call, and inspect
X-Page-VerdictandX-Billedto reconcile usage.
12. FAQ
Can Nokogiri turn a table directly into hashes?
No single universal conversion exists because headers may be missing, duplicated, or span multiple columns. Extract rows first, normalize headers, then zip each row deliberately.
Should I use CSS or XPath?
Use CSS for stable IDs and classes. Use XPath when selection depends on relationships, text, or document order.
Does Nokogiri execute JavaScript?
No. Parse the server HTML or obtain the underlying data endpoint. Use a rendered capture workflow when the visual result is the requirement.
How do I preserve formulas or links?
Extract attributes separately, such as cell.at_css("a")&.[]("href"). Text extraction alone discards markup semantics.
What is the safest default for untrusted HTML?
Keep Nokogiri’s default protections enabled and do not enable external DTDs, entity expansion, or network access merely to make malformed input parse.