HTML to PDF in Python
Convert HTML to PDF in Python with WeasyPrint or Playwright. Compare trade-offs, use runnable examples, and handle print CSS, dependencies, security, and failures.

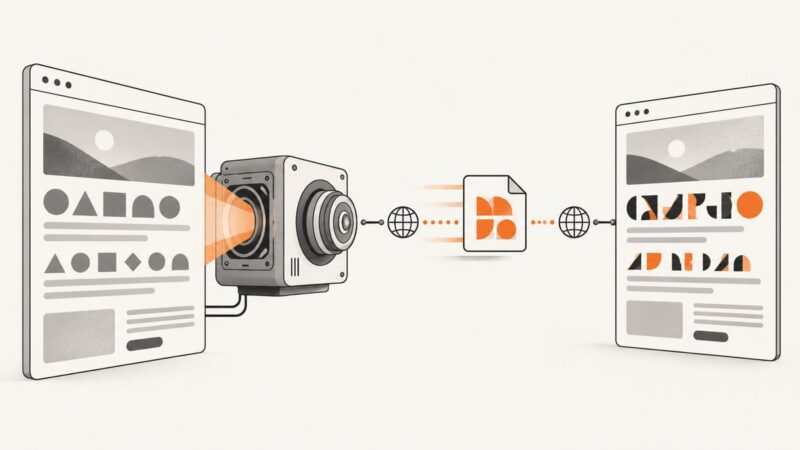
Python can turn HTML into PDF with a library such as WeasyPrint or by generating the PDF through a browser controlled by Playwright. Choose WeasyPrint when its print-oriented CSS support and runtime dependencies fit your templates and deployment; choose Playwright when browser rendering is important and you can deploy its browser runtime. In either case, test representative documents in the same environment you plan to run in. Neither choice guarantees identical output for every page.
This guide covers both approaches, their setup and trade-offs, print styling, production concerns, and common failures. If you only need a PDF of a public webpage, ScreenshotNeo can also return one from a single API request; its documentation describes the available options.
1. Choose a conversion approach
| Approach | Good fit when | Investigate before shipping |
|---|---|---|
| WeasyPrint | You want a Python-facing HTML and CSS to PDF API with print page controls. | Native dependencies, CSS support for your templates, resource loading, and isolation of untrusted input. |
| Playwright for Python | You want to render through an automated browser page and can provision the browser runtime. | Browser installation, page readiness, and whether print media produces the intended document. |
| ReportLab | You are evaluating a separate Python PDF-generation toolkit. | It is a PDF-generation route; the cited material does not establish it as a direct HTML converter. |
Compare actual HTML and CSS requirements, output fidelity on sample documents, production dependencies, access to network and local resources, required PDF features, and supported deployment platforms. No comparable benchmark establishes one renderer as fastest or best for every workload.
2. Convert HTML with WeasyPrint
WeasyPrint exposes an HTML class and a write_pdf() method. It accepts HTML supplied as a string as well as inputs such as a filename, URL, or readable file object. Its first-steps documentation lists Python and Pango among requirements; consult the current installation instructions for your operating system before selecting it.

Install and render a string
python -m pip install weasyprintThen save this as make_pdf.py:
from weasyprint import HTML

html = """
<!doctype html>
<html lang="en">
<head>
  <meta charset="utf-8">
  <title>Example report</title>
  <style>
    @page { size: A4; margin: 2cm; }
    body { font: 12pt sans-serif; line-height: 1.45; }
    h1 { break-after: avoid; }
    .page-break { break-before: page; }
  </style>
</head>
<body>
  <h1>Example report</h1>
  <p>Rendered from an in-memory HTML string.</p>
  <h2 class="page-break">Second section</h2>
  <p>This section starts on a new page.</p>
</body>
</html>
"""

HTML(string=html).write_pdf("example.pdf")
Run it with python make_pdf.py. The CSS @page rule sets page size and margins. WeasyPrint’s documentation also describes PDF/A and PDF/UA output variants; confirm the applicable requirements and options in the version you deploy if archival or accessibility output is required.
Render a file or a URL
from weasyprint import HTML

# A local document. Relative resources resolve from the input file.
HTML(filename="report.html").write_pdf("report.pdf")

# A URL. Only use this for a trusted, reachable source.
HTML(url="https://example.com/report").write_pdf("web-report.pdf")
For a string that references relative images or stylesheets, provide a usable base URL, such as the directory containing the assets. Check the current API for the precise argument behavior of your installed version. A URL input also means the renderer must be able to retrieve that URL and its referenced resources.
3. Convert HTML with Playwright
Playwright’s page.pdf() generates a PDF using print media by default. If you need styles intended specifically for screen media, call page.emulate_media(media="screen") before generating the PDF. That choice changes which CSS applies, so decide based on the output you want.

Install and run a browser-backed example
python -m pip install playwright
python -m playwright install chromium
Save as playwright_pdf.py:
import asyncio
from pathlib import Path
from playwright.async_api import async_playwright

HTML = """<!doctype html>
<html><head><meta charset="utf-8">
<style>
  @page { size: A4; margin: 18mm; }
  body { font: 12pt sans-serif; }
  h1 { break-after: avoid; }
</style>
</head><body>
<h1>Example report</h1>
<p>Rendered by a browser through Playwright.</p>
</body></html>"""

async def main():
    async with async_playwright() as p:
        browser = await p.chromium.launch()
        page = await browser.new_page()
        await page.set_content(HTML, wait_until="load")
        # Optional: use screen CSS rather than the default print CSS.
        # await page.emulate_media(media="screen")
        await page.pdf(path="example.pdf", format="A4", print_background=True)
        await browser.close()

asyncio.run(main())
Run python playwright_pdf.py. For production HTML with external fonts, images, or stylesheets, confirm that those requests have completed before saving the PDF. wait_until="load" waits for the page load event, but pages with later asynchronous updates may need an application-specific readiness condition. Avoid indefinite waits for network idleness on sites with persistent connections.
Render a URL instead of an in-memory document
import asyncio
from playwright.async_api import async_playwright

async def main():
    async with async_playwright() as p:
        browser = await p.chromium.launch()
        page = await browser.new_page()
        await page.goto("https://example.com", wait_until="load")
        await page.pdf(path="web-page.pdf", format="A4", print_background=True)
        await browser.close()

asyncio.run(main())
Use the URL your application is authorized to access. A public site can render differently for a browser than for a PDF print pass, and remote resources can fail or change between runs.
4. Style pages and handle assets
Start with print CSS, then inspect the output rather than assuming browser layout rules translate perfectly to paper. Define page geometry and intentional breaks explicitly:
@page {
  size: A4;
  margin: 18mm 16mm;
}

h1, h2, h3 { break-after: avoid; }
figure, table, blockquote { break-inside: avoid; }
.new-page { break-before: page; }
@media print {
  .screen-only, nav, .cookie-banner { display: none !important; }
}- Page size and margins: use
@pagefor page geometry in CSS. With Playwright, the PDF API also accepts page sizing options; choose one source of truth to avoid confusion. - Backgrounds: Playwright’s PDF call accepts
print_background; enable it when colored backgrounds are part of the document. - Fonts: install or bundle the fonts needed in the runtime, and check font fallback in the produced PDF.
- Images: confirm paths resolve, remote resources are available, and dimensions do not force unwanted overflow.
- Tables and long content: inspect row splitting, repeated headings, and page breaks with realistic data.
- Special scripts and layout: test right-to-left or bidirectional text, complex scripts, and other specialized requirements with representative content. WeasyPrint documents limitations, including support limitations for right-to-left or bidirectional text.
Keep fixtures for short and long documents, empty sections, unusually wide tables, missing images, and multilingual text. Compare rendered pages visually after dependency or template changes.
5. Production, security, reliability, and cost
Runtime and throughput
WeasyPrint has Python and native/runtime requirements that must be present in the deployment image. Playwright requires a compatible browser runtime in addition to the Python package. Include installation and rendering in the same operating system and dependency environment used in production. The reviewed project documentation does not provide neutral comparative throughput benchmarks; measure your own document sizes and concurrency needs.
For either approach, avoid creating unbounded concurrent conversions. Set request and job time limits, cap input sizes, and account for the memory used by large documents and images. Reuse application infrastructure where appropriate, but ensure browser and process lifetimes are managed cleanly. Track failures and retain enough metadata to reproduce a problematic render, such as template version and renderer version.
Untrusted HTML and resource access
WeasyPrint warns that untrusted HTML or CSS can create security problems and documents resource-loading concerns. User-controlled markup, styles, or URLs deserve particular care: check the current security guidance, constrain which resources can load, and isolate conversion processes with suitable permissions and network access. Do not assume a converter cannot access local files or internal network resources without confirming its current controls.
The same general service design principle applies to browser automation: treat user-provided URLs and content as untrusted, limit reachable resources, and use process-level isolation appropriate to the application. The exact controls depend on your deployment and the versions you operate.
Cost
Self-hosted conversion has no per-document price stated in the cited project materials. Budget for compute, memory, storage, dependency maintenance, and engineering time instead; actual cost depends on document size, traffic, and service design. Browser-backed rendering also has browser runtime and operational requirements. Measure your workload before setting capacity or cost expectations.
6. Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| WeasyPrint installation fails or import reports a missing library. | A required system dependency, including Pango, is missing or mismatched. | Use the current WeasyPrint installation guide for the target OS; rebuild the deployment image with documented dependencies. |
| Images, fonts, or styles are absent. | Relative URLs have no usable base, or the renderer cannot retrieve the resource. | Use absolute resource URLs or the correct base URL; check filesystem permissions and network access. |
| PDF differs from the screen page. | Print media is active by default in Playwright, or the CSS feature is unsupported or behaves differently. | Review print styles; use screen media only when intended; test the specific feature in the chosen renderer. |
| Output is clipped or has awkward page breaks. | Content dimensions exceed the page or break rules are missing. | Set page size and margins; add suitable break rules; inspect wide tables, long words, and fixed-width elements. |
| Playwright cannot launch Chromium. | The browser binary is not installed or runtime dependencies are unavailable. | Install the browser for the deployed environment using Playwright’s installation procedure and check OS compatibility. |
| PDF omits content loaded after navigation. | JavaScript updates or remote assets completed after the chosen readiness event. | Wait for a meaningful application selector or state before calling page.pdf(); use a bounded timeout. |
| Text direction or glyphs look wrong. | Font coverage or renderer support is insufficient for the content. | Install appropriate fonts and test the exact scripts; review WeasyPrint’s current documented limitations if using it. |
| A conversion service behaves unexpectedly with user input. | Untrusted HTML, CSS, or resource URLs can reach files or network resources. | Follow current security guidance, restrict resource access, and isolate conversion jobs. |
7. Or skip the browser setup
If the input is a public webpage and you want its rendered PDF, ScreenshotNeo provides a one-request screenshot API that can return a PDF. This Python example follows the documented request pattern; see the API documentation for configuration and response details.
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={
        "access_key": "YOUR_API_KEY",
        "url": "https://example.com",
        "format": "pdf",
    },
    timeout=90,
)
r.raise_for_status()
with open("page.pdf", "wb") as f:
    f.write(r.content)
cURL:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com -d format=pdf -o page.pdfNode.js:
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://example.com',
  format: 'pdf'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`ScreenshotNeo request failed: ${res.status}`);
await import('node:fs/promises').then(fs => fs.writeFile('page.pdf', Buffer.from(await res.arrayBuffer())));
ScreenshotNeo accepts cookie and consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each of those steps can be turned off. Bot checks, blank pages, and failed loads are never billed, and response headers identify the page verdict and billing status. Its MCP server lets AI agents use take_screenshot, get_page_info, and capture_pdf. The free plan includes 1,000 shots a month with no card; paid plans start at $5 for 3,000. Sign up for 1,000 free screenshots a month, with no card required.
8. A practical implementation checklist
- List the CSS, assets, scripts, languages, and PDF requirements your document uses.
- Choose WeasyPrint or Playwright based on those needs and the runtime you can support.
- Render representative short, long, and edge-case documents in the deployment environment.
- Inspect pagination, fonts, image loading, links, tables, and specialized text.
- Set resource and execution limits, especially when content or URLs come from users.
- Keep renderer versions and visual fixtures stable enough to investigate output changes.
9. FAQ
Can Python convert HTML without launching a browser?
Yes. WeasyPrint provides a Python-facing HTML-to-PDF API. It still has system dependencies and its own CSS support boundaries to account for.
Does Playwright make a PDF from screen CSS?
By default, page.pdf() uses print media. Call page.emulate_media(media="screen") first when screen styles are specifically required.
Which option should I pick?
Pick the one that supports the features your actual template uses and fits your deployment. Render sample documents in that environment before committing to a production choice.
Can I use a converter for user-submitted HTML?
That requires a deliberate security design. Review the renderer’s current guidance and control resource loading and process access before accepting untrusted markup or styles.