How to Identify the Technology Behind a Website
Learn how to identify a website’s CMS, framework, ecommerce platform, analytics, and infrastructure using profilers and public evidence.
Direct answer: use a website technology profiler for a fast first pass, then verify important findings against the page source, HTTP headers, cookies, JavaScript variables, and browser-visible behavior. Profilers infer technologies from public signals, so a result is evidence rather than a guarantee of the complete or current stack.
This workflow can reveal a site’s content management system (CMS), frontend framework, ecommerce platform, analytics tools, infrastructure, plugins, themes, and fonts. The right method depends on whether you need a one-off answer, repeated manual research, or an automated inventory.
1. Define what you need to identify
“What is this website built with?” can mean several different things. Decide the question before collecting a long list of detections.
- CMS: WordPress, Drupal, Shopify, or another publishing system.
- Frontend framework: a client-side or server-rendered framework exposed through scripts, markup, or asset paths.
- Ecommerce platform: the service handling products, checkout, carts, or payments.
- Analytics and marketing: analytics tags, ad pixels, consent systems, and customer-data tools.
- Infrastructure: hosting, CDN, web server, DNS, and other public delivery signals.
- Plugins, themes, and fonts: useful when auditing a site or planning compatibility work.
A broad scan is useful for reconnaissance. For a technical decision, narrow the question and corroborate the answer with more than one signal.
2. Run a technology profiler
A profiler is usually the quickest starting point. Wappalyzer describes detection based on source code, HTTP headers, cookies, JavaScript variables, and other observable methods. Its lookup workflow can inspect one domain, while its browser extension displays detections as you browse. WhatRuns provides a similar extension-oriented workflow.
- Enter the site’s canonical domain into a lookup service.
- Record the categories and the evidence shown for each detection.
- Check whether the result is cached or live.
- Verify important matches manually before making a decision.
See Wappalyzer’s technology lookup for a one-off check and its FAQ for the differences between lookup, extension, and API workflows.
| Approach | Best fit | Trade-off |
|---|---|---|
| Page-source inspection | Answering one focused question or checking a clue | Requires interpreting HTML and browser-visible signals |
| Browser extension | Repeated manual research while browsing | Convenient, but categories and coverage vary |
| Website lookup | One domain or a small batch | Cached and live results may differ in freshness |
| API | Recurring audits and automated pipelines | Requires handling limits and asynchronous crawls |
3. Verify the result in page source
Open the page source (Ctrl+U or Cmd+Option+U) and search for distinctive markers. A common example is a generator meta tag:
<meta name='generator' content='WordPress 4.9.8' />This is a useful clue, not a universal test. A site can remove, change, or spoof metadata. Search for script URLs, stylesheet paths, inline configuration objects, data attributes, and comments that identify a platform or plugin. Also inspect response headers and cookies: profilers use these signal classes because they can expose delivery layers and application behavior that is absent from the visible markup. Wappalyzer’s guide explains these signal types and uses the WordPress generator tag as an example.
Use the browser’s rendered view too
“View source” shows the original response. The Elements panel shows the DOM after JavaScript has run. Compare both when a site is a single-page application or loads content dynamically.
- Open DevTools and select the Network panel.
- Reload with the panel open.
- Filter requests by
js,css,fetch, andxhr. - Inspect response headers, cookies, and script URLs.
- Use the Application panel to review cookies and storage keys.
Do not infer the entire backend from a single library name. A frontend bundle may be served by a CDN, while the CMS and application server remain invisible.
4. Automate a basic evidence check
For a small audit, you can fetch the public response and search it for likely markers. This does not replace a profiler; it gives you reproducible evidence to compare with the profiler’s result.
cURL
curl -L -sS -D headers.txt https://example.com -o page.html
rg -i 'generator|wp-content|shopify|drupal|next|nuxt|gtag|analytics' page.html headers.txt
Python
import re
import requests

url = 'https://example.com'
r = requests.get(url, timeout=30, headers={'User-Agent': 'technology-audit/1.0'})
r.raise_for_status()

signals = {
    'generator_meta': re.findall(r'<meta[^>]+name=["\']generator["\'][^>]*>', r.text, re.I),
    'wordpress_paths': re.findall(r'[^"\']*wp-content[^"\']*', r.text, re.I),
    'shopify_paths': re.findall(r'[^"\']*cdn\.shopify[^"\']*', r.text, re.I),
}
print('status:', r.status_code)
print('server:', r.headers.get('server'))
for name, matches in signals.items():
    print(name, matches[:5])
Node.js
const res = await fetch('https://example.com', {
  headers: { 'user-agent': 'technology-audit/1.0' }
});
if (!res.ok) throw new Error(`${res.status} ${res.statusText}`);
const html = await res.text();

const tests = {
  generator: /<meta[^>]+name=["']generator["'][^>]*>/i,
  wordpress: /wp-content/i,
  shopify: /cdn\.shopify/i,
  analytics: /gtag|google-analytics/i
};
console.log('status:', res.status);
console.log('server:', res.headers.get('server'));
for (const [name, pattern] of Object.entries(tests)) {
  console.log(name, pattern.test(html));
}
These scripts inspect only the initial HTML and headers. They will miss technologies injected after JavaScript execution, hidden behind a login, or delivered only after interaction. Respect a site’s access controls and do not turn a simple audit into an aggressive crawler.
5. Account for dynamic pages and JavaScript
Server-rendered HTML can expose a CMS directly, while a client-rendered application may return a minimal document and load its meaningful clues later. In that case:
- Inspect the live DOM after the page finishes loading.
- Review JavaScript bundles and network requests for platform-specific paths.
- Look at cookies and storage after consent has been handled.
- Repeat the check in a clean session if a consent banner changes what loads.
A screenshot is useful for documenting what a human visitor sees, but an image alone cannot prove which framework or CMS generated it. Capture the rendered page alongside the profiler output and source evidence.
6. Handle freshness and incomplete results
Technology inventories change. Wappalyzer’s lookup page distinguishes cached results from live results, with cached results described as verified within the previous 30 days. Its API documentation warns that a site not already in the dataset may initially return no technologies while a crawl is running.
- Check whether the result is cached or live.
- For a time-sensitive audit, request or run a fresh lookup.
- If an API response is empty, retry after the crawl has had time to complete.
- Save the lookup date with your report.
An empty response does not necessarily mean the site uses no detectable technology. It can indicate that discovery is still in progress or that the site exposes few public signals.
7. Corroborate important detections
Use at least two independent clues when the result affects a migration, security review, procurement decision, or competitive analysis. For example, a CMS detection is stronger when a profiler result agrees with a generator tag, recognizable asset path, and cookie or header pattern.
Keep an evidence table:
| Claim | Evidence | Confidence | Checked |
|---|---|---|---|
| CMS | Profiler plus source marker | High | Date and URL |
| Analytics | Script request and network host | Medium | Rendered page |
| Hosting/CDN | Headers and DNS clues | Medium | Live response |
This separates what the page proves from what the tool infers.
8. Capture a clean visual record without browser setup
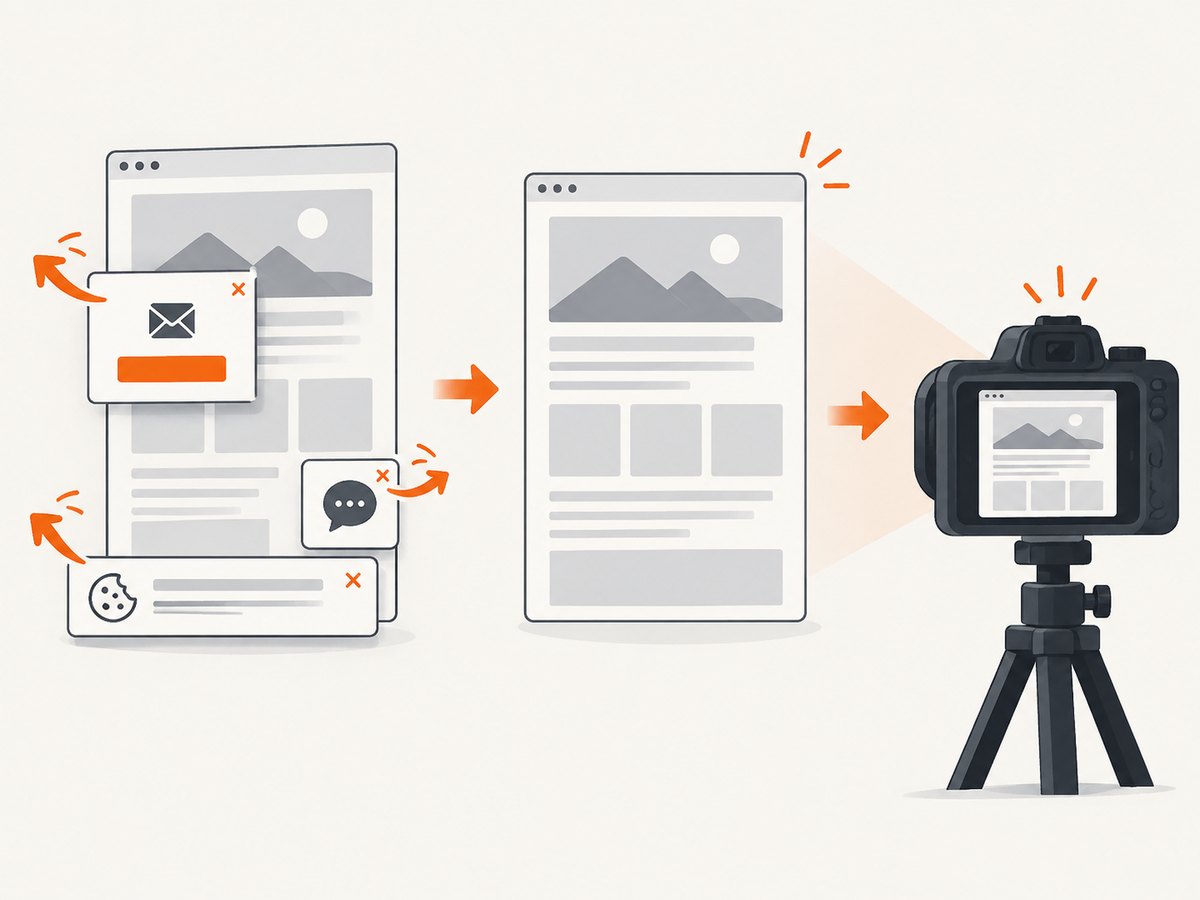
If you need a screenshot of the rendered evidence for a report, ScreenshotNeo can load the URL and return a PNG, JPEG, WebP, or PDF. It accepts consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets. Each step can be turned off. Only clean shots are billed: bot checks, blank pages, timeouts, failed loads, and cache hits cost nothing, and the response identifies the outcome with X-Page-Verdict and X-Billed headers.
Or skip the browser setup
Use one GET request to capture the page you want to document. The ScreenshotNeo API docs list the options.
curl -G 'https://api.screenshotneo.com/v1/shot' -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get('https://api.screenshotneo.com/v1/shot', params={'access_key': 'YOUR_API_KEY', 'url': 'https://stripe.com'}, timeout=90)
r.raise_for_status()
open('shot.webp', 'wb').write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`${res.status} ${res.statusText}`);
const buffer = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('shot.webp', buffer);ScreenshotNeo also supports full-page captures with lazy images loaded, CSS-selector element captures, dark mode, device presets, custom viewports, retina scale, custom CSS and JavaScript, clicks, selector or network-idle waits, request blocking, custom headers and cookies, timezone and geolocation, transparent backgrounds, resizing, configurable caching, signed links, asynchronous jobs with signed webhooks, bulk capture for up to 100 URLs per call, a usage API, and an OpenAPI specification. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
Cookie banners, popups, and chat widgets are removed before the shot; bot checks, blank pages, and failed loads are never billed; AI agents can take screenshots through MCP; 1,000 screenshots per month are free with no card, and paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
9. Troubleshooting common errors
| Problem | Likely cause | Fix |
|---|---|---|
| No technologies detected | Initial API crawl, blocked request, or few public signals | Retry after crawling, run a live lookup, and inspect source and headers |
| Profiler says one CMS, source suggests another | Old metadata, migration residue, proxy, or false positive | Check multiple signals and record the disagreement |
| HTML script finds nothing | Technology loads after JavaScript execution | Use DevTools Network and Elements panels or a rendered capture |
| Results change between runs | Cache age, A/B tests, geolocation, consent state, or deployment changes | Record timestamps, region, user agent, and whether the run was live |
| Request returns 403 or 429 | Access policy or rate limit | Slow down, use the permitted workflow, and do not bypass controls |
| Screenshot contains a popup | The page needs a wait or the overlay is not recognized | Wait for a selector or network idle, hide the selector, or disable the relevant capture step |
10. Performance, reliability, and cost considerations
- Performance: a lookup or extension is faster for a single domain than building a crawler. For batches, cache results and avoid repeatedly fetching unchanged pages.
- Reliability: public detection is inherently partial. Store the source URL, timestamp, response status, and evidence so another reviewer can reproduce the conclusion.
- Freshness: prefer live checks for release reviews or incident response. Treat cached results as a dated snapshot.
- Cost: compare API limits, batch support, and refresh frequency before automating. ScreenshotNeo’s Free plan includes 1,000 shots per month without a card; paid plans are $5 for 3,000, $15 for 15,000, $39 for 60,000, $99 for 250,000, and $249 for 1,000,000. Yearly billing gives two months free, and every feature is on every plan.
FAQ
Can I identify a site’s backend language?
Usually not with confidence from public browser signals. You may infer frameworks or hosting layers, but the server language can remain hidden.
Is a profiler result proof?
No. It is an inference from observable signals. Verify important findings with source, headers, cookies, network requests, or a second tool.
Why do two profilers disagree?
They use different detection rules, datasets, crawl times, and categories. Compare the evidence and timestamps instead of choosing a result by name alone.
Should I report versions?
Only when a public marker exposes a version and you can date the observation. Versions may be stale, masked, or changed by deployment.
Can a screenshot reveal the complete stack?
No. It documents the rendered appearance. Pair it with profiler output and public response evidence for a useful record.
Conclusion
Start with a profiler, define the exact technology question, verify the result using public signals, and record freshness and evidence. For repeatable work, automate the HTML and header check, handle asynchronous crawls, and preserve timestamps. When the deliverable also needs a clean visual record, ScreenshotNeo provides a URL-to-image or PDF request without maintaining your own browser setup.


