JavaScript Rendering Tests: Comparing Raw and Rendered HTML
Compare the HTML your server sends with the DOM JavaScript builds, then verify Google’s rendering with Google’s own tools.
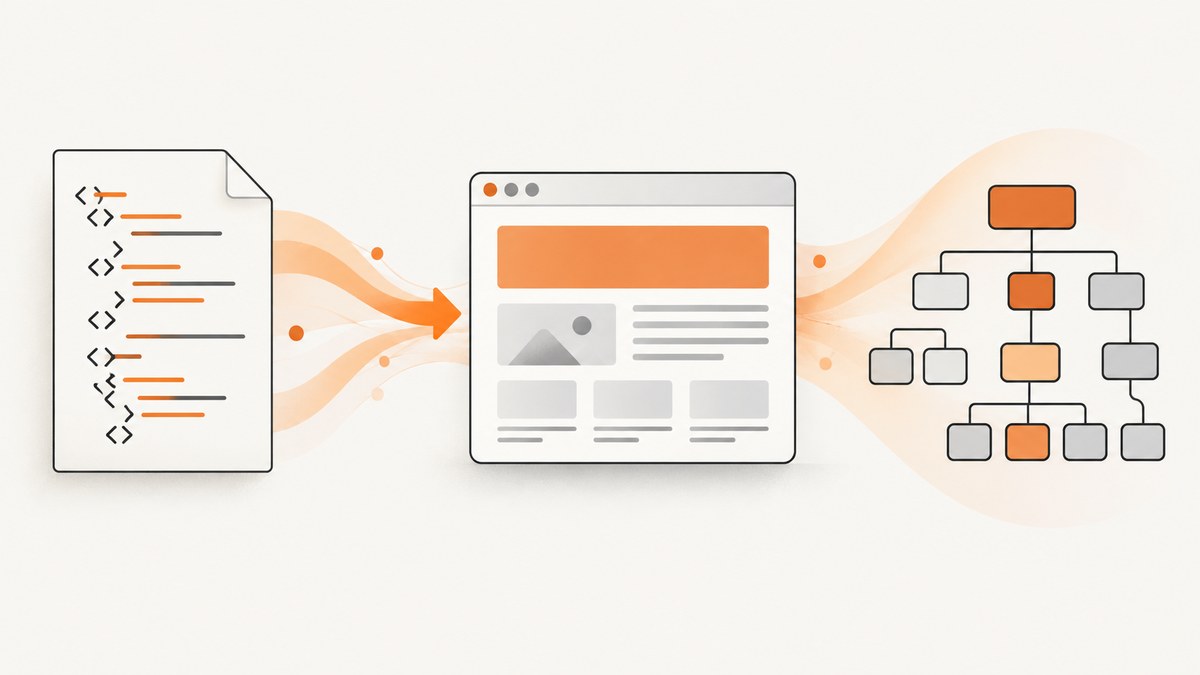
To compare raw and rendered HTML, save the HTTP response before a browser runs JavaScript, then load the same URL in an automated browser and inspect the resulting DOM after the application reaches a meaningful ready state. The raw response answers what the server sent; the rendered DOM answers what that browser produced after scripts ran. A local browser test tells you what happened under its test conditions. It does not prove what Google rendered for that URL.
For repeatable application checks, use a browser automation tool such as Playwright or Puppeteer. For Google-specific diagnosis, use Search Console URL Inspection or the Rich Results Test and review its rendered HTML, loaded resources, and JavaScript errors. Google’s documented process separates crawling, rendering, and indexing, and a page may wait in a rendering queue. Google’s JavaScript SEO guide explains the stages and their limitations.
1. What raw HTML and rendered HTML mean
Raw HTML is the response body delivered by the server for a request. It can include markup, metadata, inline scripts, and references to external files. It is commonly inspected with View Source, curl, or an HTTP client. The browser has not yet run the page’s JavaScript when you inspect this response.

Rendered HTML is a convenient name for the browser’s DOM after it has parsed the response and executed some or all of the scripts and interactions relevant to the current state. In Chrome, Inspect Element exposes the live DOM. It may differ from the source because scripts inserted, changed, or removed nodes. The DOM is a live structure, not necessarily a byte-for-byte HTML string that the server ever sent.
A difference is not automatically a defect. A client-rendered application may intentionally send a small shell and fill it with data after loading. The test question is whether the content, links, metadata, or structured data that matter exist in the correct state and can be reached under the conditions you care about.
| Question | Inspect |
|---|---|
| Did the server include the title, description, or content in its response? | Raw response HTML |
| Did the application insert a product card after loading? | Rendered DOM after a ready condition |
| Can Google access and render this public URL? | Search Console URL Inspection or Rich Results Test |
| Does the app behave correctly across engines or devices? | Automated browser tests with the relevant browser and viewport matrix |
2. Compare raw and rendered HTML in a repeatable test
The example below uses JavaScript and Playwright. It fetches the initial response separately, then opens the URL in a browser and checks an application-defined ready selector. Change the URL, selector, and assertions to match your application. It saves both bodies for inspection and prints whether required content appeared in each.
Install and run
npm init -y
npm install --save-dev playwright
npx playwright install chromium
node compare-html.mjs https://example.com
Save this as compare-html.mjs. This example uses Node’s built-in fetch and file APIs and the Playwright Chromium browser. It assumes the page displays a main heading inside main; replace the selectors and text with stable markers from your app.
import { chromium } from 'playwright';
import { writeFile } from 'node:fs/promises';

const url = process.argv[2];
if (!url) throw new Error('Usage: node compare-html.mjs <url>');

const requiredText = 'Example heading';
const readySelector = 'main h1';
const browser = await chromium.launch({ headless: true });

try {
  const response = await fetch(url, { redirect: 'follow' });
  const rawHtml = await response.text();
  await writeFile('raw.html', rawHtml, 'utf8');

  const page = await browser.newPage({
    viewport: { width: 1280, height: 800 },
  });
  const consoleErrors = [];
  const failedRequests = [];
  page.on('console', message => {
    if (message.type() === 'error') consoleErrors.push(message.text());
  });
  page.on('requestfailed', request => {
    failedRequests.push(`${request.url()}: ${request.failure()?.errorText ?? 'failed'}`);
  });

  const navigation = await page.goto(url, { waitUntil: 'domcontentloaded' });
  if (!navigation) throw new Error('Navigation returned no response');
  console.log('Browser status:', navigation.status());

  // Prefer a selector or application-ready signal over an arbitrary sleep.
  await page.locator(readySelector).waitFor({ state: 'visible', timeout: 15000 });
  const renderedHtml = await page.locator('html').evaluate(node => node.outerHTML);
  await writeFile('rendered.html', renderedHtml, 'utf8');

  const rawHasText = rawHtml.includes(requiredText);
  const renderedHasText = await page.getByText(requiredText, { exact: false }).count() > 0;
  console.log({ rawHasText, renderedHasText, consoleErrors, failedRequests });

  if (!renderedHasText) throw new Error(`Missing rendered content: ${requiredText}`);
  await page.close();
} finally {
  await browser.close();
}
The two requests are deliberately separate: the direct fetch records the server response, while the browser navigation runs scripts. A site can vary responses by cookies, authentication, user agent, geography, or cache state, so for a strict comparison make those conditions equivalent or record the difference. A direct fetch is not a complete model of everything a browser receives.
Make the assertion meaningful
- Assert stable content and destinations, not generated class names or incidental markup.
- Check the exact state users need: after initial load, after login, after opening a menu, or after pagination.
- For links, inspect actual
a[href]elements and their destinations, not only visible link text. - For metadata, evaluate
document.title, description tags, canonical link, and relevant structured-data scripts in the DOM. - Record the status code, browser errors, and failed resource requests with a failing assertion so the failure is diagnosable.
3. Capture the raw response with cURL, Python, and Node.js
These options are useful for saving or inspecting the server response independently of JavaScript execution. They do not produce the browser-rendered DOM.
cURL
curl -L --fail-with-body \
  -H 'Accept: text/html' \
  'https://example.com/products/widget' \
  -o raw.html

# Search for a phrase in the saved response
rg -n 'Example heading|<title>|application/ld\+json' raw.html
-L follows redirects and --fail-with-body returns an error for HTTP error statuses while retaining the response body. On older cURL versions without that option, omit it and inspect the status with -w '%{http_code}\n'. A response can be compressed or vary based on request headers; cURL normally handles common content encodings.
Python
from pathlib import Path
import requests

url = 'https://example.com/products/widget'
response = requests.get(url, timeout=(5, 30), allow_redirects=True)
print('status:', response.status_code)
print('final URL:', response.url)
response.raise_for_status()
Path('raw.html').write_text(response.text, encoding='utf-8')

for phrase in ('Example heading', '<title>', 'application/ld+json'):
    print(f'{phrase}:', phrase in response.text)
The connect and read timeout tuple helps prevent a stalled request from hanging indefinitely. raise_for_status() makes HTTP error responses visible instead of silently treating them as successful HTML.
Node.js
import { writeFile } from 'node:fs/promises';

const url = 'https://example.com/products/widget';
const response = await fetch(url, { redirect: 'follow' });
console.log('status:', response.status);
console.log('final URL:', response.url);
const html = await response.text();
if (!response.ok) throw new Error(`HTTP ${response.status}: ${html.slice(0, 300)}`);
await writeFile('raw.html', html, 'utf8');
console.log('Contains heading:', html.includes('Example heading'));
4. Test timing, interactions, and browser differences
Many false failures come from capturing too early or testing the wrong state. DOMContentLoaded means parsing has completed; it does not guarantee that an application’s API calls, hydration, lazy content, or user-triggered UI have completed. load waits for load-event resources, but it still does not mean the application is ready. A fixed delay can hide races on a fast machine and fail on a slow one.
Use a readiness condition tied to the feature under test: an element becomes visible, a loading indicator disappears, a known application state is exposed, or a specific API response completes. In Playwright, wait for the locator or response that represents that condition. If the page only reveals content after scrolling, scrolling is part of the test. If a consent dialog blocks content, decide explicitly whether the test accepts or dismisses it.
Test the browser engine and channel that matter. Playwright supports Chromium, WebKit, and Firefox, branded Chrome and Edge channels, and device emulation. Bundled browser builds and branded channels can behave differently. A Chromium-only test is useful for a focused check; it does not establish compatibility with every engine or device. See the Playwright browser documentation and emulation documentation. Puppeteer is another option for Chrome and Firefox automation; see its official guides.
5. Check whether Google can see JavaScript-generated content
Google describes crawling, rendering, and indexing as separate stages. It can use rendered HTML for indexing, but rendering may happen later, and some responses may not be rendered. Google also cannot render a page or script it is blocked from accessing. A local Playwright result is evidence about the browser and conditions you chose, not evidence of Google’s output for the URL.
- Open Search Console URL Inspection for a property you manage and inspect the live URL.
- Review the rendered page or HTML, loaded resources, and JavaScript console output or exceptions.
- For an eligible public page, use the Rich Results Test to inspect the rendered result and structured data. The page must be accessible without login and not blocked by robots.txt.
- Compare the Google tool’s result with the expected content and your local test. Investigate differences in resources, status, access, or browser support.
Google’s JavaScript troubleshooting guide describes these diagnostic tools. Its JavaScript SEO basics also recommends server-side rendering or prerendering for speed and for crawlers that cannot run JavaScript. Google characterizes dynamic rendering as a workaround rather than a long-term solution in its dynamic-rendering guidance.
6. Troubleshooting common failures
| Symptom | Likely cause | What to check or change |
|---|---|---|
| Text appears in Inspect Element but not View Source | Client-side JavaScript inserted it after the initial response. | Decide whether that is intended. Test the DOM after the app’s ready signal; for crawler-critical content, consider server-side or prerendered HTML. |
| Rendered assertion times out | Wrong selector, app never reached ready state, failed API call, or a state such as login is required. | Inspect screenshot, URL, status, console errors, failed requests, and test data. Verify the selector manually in the live DOM. |
| Raw request returns 401, 403, or a different page | Authentication, anti-bot behavior, missing headers, or request-specific routing. | Use the intended session and headers in the test; do not compare a logged-in browser with an anonymous fetch as if they were equivalent. |
| Browser shows content, Google tool does not | Google may be blocked from the page or script, a resource failed, an API is unavailable, or the rendered result differs by conditions. | Check robots rules, HTTP status, resource access, console exceptions, and Google’s rendered output. Do not use the local result as a substitute for URL Inspection. |
| Test passes locally but fails in CI | Different browser version, viewport, timing, missing system dependencies, or environment-specific network behavior. | Pin and install the intended Playwright browser build, log versions and viewport, and wait for a deterministic condition. Reproduce CI conditions locally where possible. |
| Google appears to use old CSS or JavaScript | Cached resources may be stale; Google notes that its Web Rendering Service may ignore caching headers. | Use fingerprinted asset filenames so updated resources have new URLs, then inspect the resources Google loaded. |
| Page or script is absent from Google’s rendering | robots.txt or another access restriction may block it; non-200 responses may not be rendered. | Check the live response status and crawl access for both the page and required resources. |
7. Performance, reliability, and cost
Browser rendering is more expensive than checking a string in a response because it starts a browser, loads resources, and executes page code. Keep the test focused: use one representative URL, a minimal viewport, and only the browser engines needed for the risk you are checking. Reuse a browser process across tests where your runner supports it, but isolate browser contexts when cookies or storage could leak between cases.

Make failures repeatable. Record the URL after redirects, response status, browser version, viewport, readiness condition, console errors, and failed requests. Save raw and rendered HTML only when useful, since pages can contain private user data or tokens. Avoid arbitrary long sleeps; they increase suite time while still not guaranteeing readiness.
For production diagnosis, a screenshot can make layout and overlay problems easier to see, but a screenshot is a visual artifact, not a replacement for DOM assertions or Google’s rendering diagnostics. Cost depends on the infrastructure and frequency of your own browser runs; this guide makes no benchmark claim. If a CI job repeatedly visits the same public page, cache deliberately only when stale content will not undermine the test.
8. Or skip the browser setup
ScreenshotNeo is a website screenshot API and MCP server. Its one-call API can capture a page as PNG, JPEG, WebP, or PDF; it does not replace a DOM assertion when your test needs to prove that a specific node or link exists. The API accepts the target URL and returns the capture. See the ScreenshotNeo API documentation for request options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://example.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);- Cookie banners are accepted and removed before capture, along with 60+ known consent platforms, newsletter popups, and chat widgets; each step can be turned off.
- Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed; response headers identify the page verdict and billing status.
- An MCP server lets AI agents, including Claude, Cursor, and other MCP clients, take screenshots with
take_screenshot, inspect pages withget_page_info, and capture PDFs withcapture_pdf. - The free plan includes 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 screenshots; every feature is on every plan.
Sign up for ScreenshotNeo’s free plan: 1,000 screenshots a month, no card required.
FAQ
Does View Source show the final page?
No. It usually shows the original response. Inspect Element shows the live DOM after browser parsing and script execution.
Can a rendered screenshot prove that text is in the DOM?
No. A screenshot shows pixels. Use a DOM query or assertion for text and links, and a screenshot to diagnose visual layout.
Does Google render every JavaScript page immediately?
No. Google documents a separate rendering stage and a queue; timing and whether a page is rendered can vary.
Should I use Puppeteer or Playwright?
Choose based on the browser coverage and workflows you need. Playwright documents Chromium, WebKit, Firefox, branded channels, and device emulation; Puppeteer provides browser automation. Keep the chosen versions and environments explicit.