How to Load JavaScript from a String When Converting HTML to PDF
Render JavaScript inside an HTML string with Puppeteer or Playwright, wait for the page’s content to be ready, and save a PDF reliably.
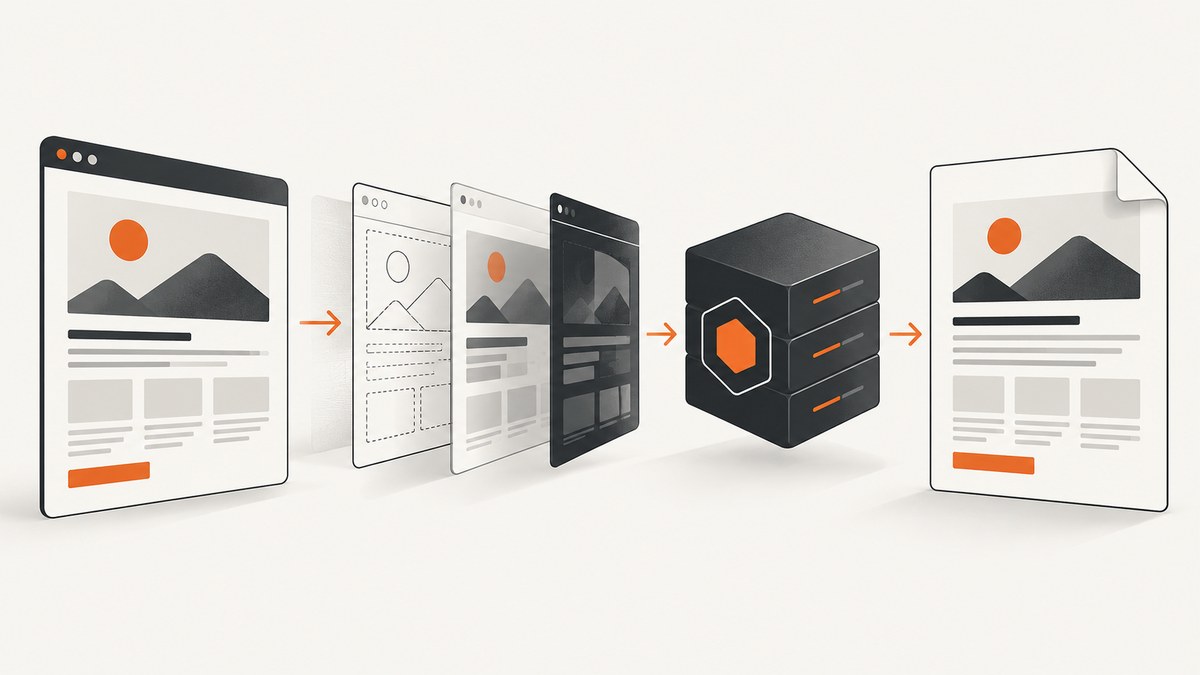
To run JavaScript from an HTML string before converting it to PDF, load the markup into a headless browser page, wait for the content your script produces, then print the page. With Puppeteer, the core sequence is page.setContent(html) followed by page.pdf(). Playwright provides the same basic flow. For asynchronous rendering, wait for an application-specific signal such as a report-ready element rather than assuming the initial load means every script has finished.
1. Understand the two kinds of JavaScript input
“JavaScript from a string” can mean either of two things:
- The HTML string contains a script: pass the complete HTML, including its
<script>element, tosetContent(). - The JavaScript is a separate string: insert it into the HTML as a script element, or add it to the page with the browser automation library before printing.
In both cases, code must execute in a browser context. Converting the HTML string directly to a PDF without a browser or another JavaScript-capable renderer will not execute browser scripts. Puppeteer documents Page.setContent(html) as assigning markup to a page; its PDF guide shows printing that page to a PDF file. Puppeteer setContent API · Puppeteer PDF guide
2. Run JavaScript in an HTML string with Puppeteer
Install Puppeteer in a Node.js project:
npm install puppeteerSave this as make-pdf.js and run it with node make-pdf.js. The inline script updates the page, then exposes a readiness element that Puppeteer waits for before printing.
const puppeteer = require('puppeteer');

async function main() {
  const html = `<!doctype html>
<html>
  <head>
    <meta charset="utf-8">
    <title>Generated report</title>
    <style>
      body { font: 16px sans-serif; margin: 32px; }
      h1 { color: #174ea6; }
      @media print { .screen-only { display: none; } }
    </style>
  </head>
  <body>
    <h1 id="heading">Preparing report…</h1>
    <p id="result"></p>
    <script>
      document.querySelector('#heading').textContent = 'Monthly report';
      document.querySelector('#result').textContent = 'Revenue: $42,000';
      document.body.dataset.ready = 'true';
    </script>
  </body>
</html>`;

  const browser = await puppeteer.launch();
  try {
    const page = await browser.newPage();
    await page.setContent(html, { waitUntil: 'load' });
    await page.waitForSelector('body[data-ready="true"]');
    await page.pdf({
      path: 'report.pdf',
      format: 'A4',
      printBackground: true,
      preferCSSPageSize: true
    });
  } finally {
    await browser.close();
  }
}

main().catch(error => {
  console.error(error);
  process.exitCode = 1;
});
The readiness marker here is an example under your control. Replace it with a condition that represents finished application output. The try/finally block closes the browser even when page setup or PDF creation fails. Puppeteer’s PDF API waits for fonts by default, but that does not mean it can infer when your own asynchronous data or chart rendering is complete. PDF generation guide
When the script is a separate JavaScript string
If you have separate html and js strings, the clearest approach is to include the script in the markup before calling setContent():
const html = `<!doctype html><html><body>
  <div id="output"></div>
  <script>${js}</script>
</body></html>`;
await page.setContent(html, { waitUntil: 'load' });
await page.waitForSelector('#output[data-ready="true"]');
await page.pdf({ path: 'output.pdf', printBackground: true });
Only interpolate JavaScript you control or have safely prepared. If the string may contain a closing script sequence, escape or otherwise safely serialize it so it cannot prematurely end the HTML script element. For an externally sourced script, use the library’s script-injection API and check the overload supported by your installed version. Puppeteer’s Page API includes addScriptTag. Puppeteer Page API
3. Choose a reliable readiness condition
The browser’s document load events describe document and resource milestones; they do not know whether your application has finished its own work. If a script fetches data, builds a chart, or waits on an asynchronous operation, printing immediately can produce an incomplete PDF.
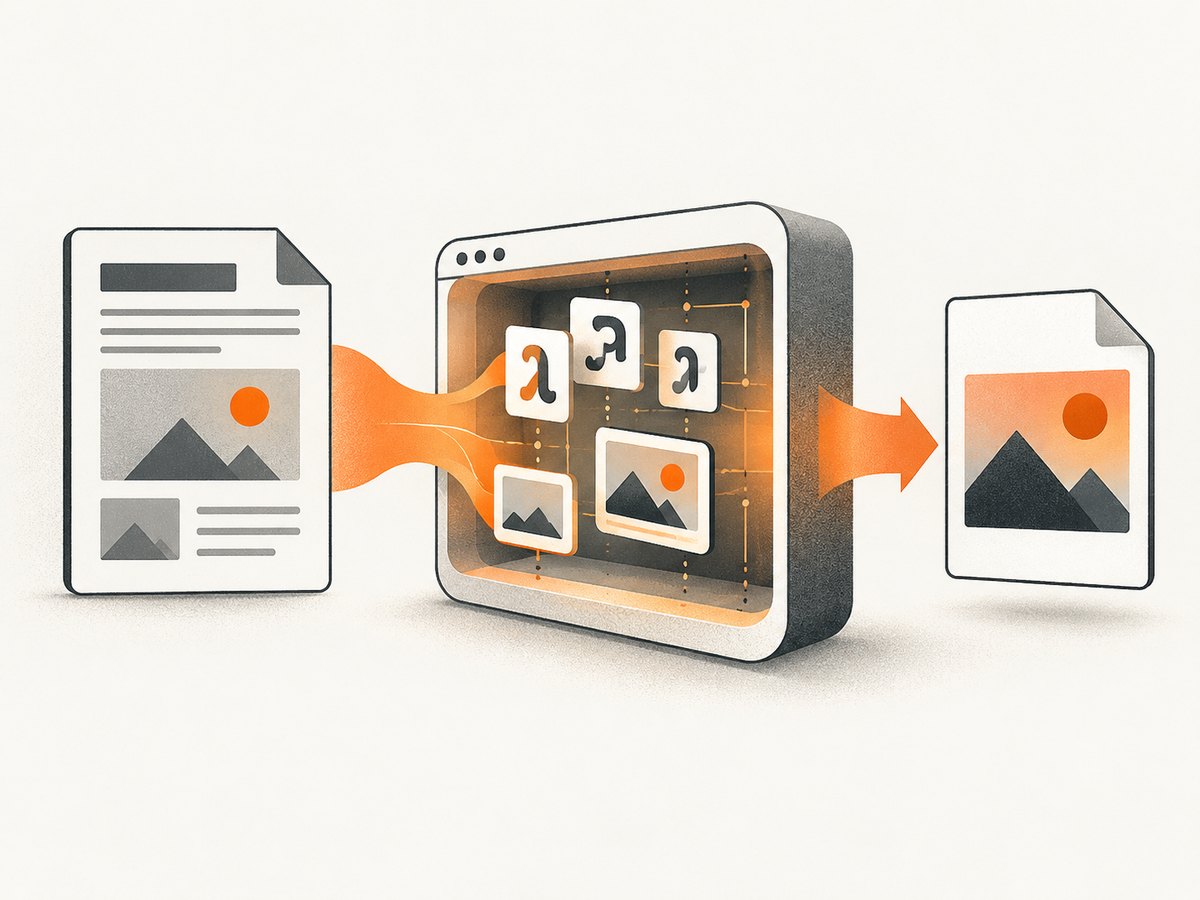
- Have the page set an explicit ready marker when all PDF content has been rendered.
- Wait for that marker with
waitForSelector(), or wait for a defined application promise or state. - Set a timeout appropriate to your operation and surface a useful error if readiness is never reached.
- Print only after the condition succeeds.
For example, your script can set document.body.dataset.ready = 'true' after its awaited work, and the automation can wait for body[data-ready="true"]. This application-specific approach is a practical inference from the documented wait controls and Playwright’s warning that networkidle should not be used as a general readiness test. Playwright Page API
If you control the script, make its asynchronous work explicit:
<script>
(async () => {
  const response = await fetch('/report-data.json');
  const data = await response.json();
  document.querySelector('#total').textContent = data.total;
  document.body.dataset.ready = 'true';
})();
</script>
For a self-contained HTML string, a relative URL such as /report-data.json may not resolve as expected because the document has no ordinary site URL. Provide an absolute resource URL, embed the needed data in the document, or load the content from a page with an appropriate base URL. Also check cross-origin restrictions if your script fetches data from another origin.
4. Print with Playwright instead
If your project already uses Playwright, the flow is nearly identical. Install its package and browser according to the official setup instructions for your environment, then use this CommonJS example:
const { chromium } = require('playwright');

(async () => {
  const html = `<!doctype html><html><body>
    <h1>Loading…</h1>
    <script>
      document.querySelector('h1').textContent = 'Ready for PDF';
      document.body.dataset.ready = 'true';
    </script>
  </body></html>`;

  const browser = await chromium.launch();
  try {
    const page = await browser.newPage();
    await page.setContent(html, { waitUntil: 'load' });
    await page.waitForSelector('body[data-ready="true"]');
    const pdf = await page.pdf({ format: 'A4', printBackground: true });
    require('fs').writeFileSync('output.pdf', pdf);
  } finally {
    await browser.close();
  }
})().catch(error => {
  console.error(error);
  process.exitCode = 1;
});
Playwright’s page.pdf() returns a PDF buffer, which the example writes to disk. Its API says setContent() internally calls document.write(), inheriting that method’s characteristics and behaviors. When using waitUntil, Playwright documents load, domcontentloaded, networkidle, and commit; it discourages networkidle for readiness checks and recommends assertions instead. Playwright Page API
5. Control PDF appearance
Both libraries print with print CSS media by default. That means @media print rules can change visibility, colors, spacing, and page breaks in the generated file. Start by deciding whether the PDF should look like a print layout or the screen view.
| Need | Approach |
|---|---|
| Paper format | Set a PDF option such as format: 'A4', or define page sizing in print CSS. |
| Background colors and graphics | Enable printBackground: true. |
| Honor CSS page dimensions | Use Puppeteer’s preferCSSPageSize: true when your stylesheet defines @page. |
| Use screen styles in Puppeteer | Call await page.emulateMediaType('screen') before page.pdf(). |
| Preserve exact colors in Puppeteer | Use the CSS property -webkit-print-color-adjust: exact where appropriate. |
Puppeteer documents that PDF generation uses print CSS media and that colors are modified for printing by default; it documents screen media emulation and the color-adjust property for controlling those behaviors. Puppeteer Page.pdf API
@page { size: A4; margin: 16mm; }

@media print {
  .page-break { break-before: page; }
  .avoid-split { break-inside: avoid; }
  body { -webkit-print-color-adjust: exact; }
}
Check long tables, oversized images, and elements with fixed heights: they can split or clip differently in print layout than on screen. Add page-break rules selectively and inspect representative output when you change your template.
6. Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| PDF contains “Loading…” or missing chart data | The PDF call ran before asynchronous rendering finished. | Wait for an app-owned ready marker or condition after the data and visual rendering are complete. |
waitForSelector times out |
The script failed, the selector differs, or the page never reaches its ready state. | Log page errors, verify the selector exists in the final DOM, and make the script expose failure state as well as success. |
| External image or font is absent | The resource URL is relative, unreachable from the document, blocked, or still loading. | Use a resolvable URL, check browser console and network failures, and wait for the relevant resource or application condition. |
| Styles or colors differ in the PDF | Print CSS media is active, or backgrounds are not enabled. | Review @media print, enable printBackground, or emulate screen media in Puppeteer if that is the intended output. |
| Script appears not to run | The JavaScript string was never added to the markup, contains a syntax error, or relies on browser APIs unavailable in the current context. | Confirm the script is present before setContent(), inspect page errors, and run it in the browser environment rather than a plain HTML-to-PDF parser. |
| PDF is empty or a browser process stays open | Page setup failed before output, or the browser was not closed on an error path. | Use try/finally around browser work and await the PDF call before closing. |
| Relative fetch or stylesheet fails | A content string has no expected page origin or base path. | Embed content, use absolute URLs, or set up a document URL/base appropriate to the resources. |
7. Performance, reliability, and cost
The research sources document the APIs and output behavior, but provide no performance benchmarks or cost comparison for Puppeteer versus Playwright. In practice, browser startup, page rendering, external resources, and the amount of printed content all contribute to the work; measure your own templates and workload before setting throughput expectations.
For repeated jobs, structure the service so browser lifetime and failure handling are explicit. Always close pages and browsers on failed operations. Put time limits on readiness waits, report whether the failure happened during setup, script execution, readiness, or PDF generation, and retry only failures that are safe to repeat. Avoid a broad network-idle wait as a substitute for knowing what “ready” means to your application. If templates load third-party assets, those dependencies also affect whether an output is reproducible.
For cost, account for the compute and infrastructure required to run browser processes in your own environment; the cited documentation does not establish a per-PDF price. If you only need a screenshot of an existing public web page rather than a PDF from your own JavaScript-generated HTML string, a screenshot API may avoid managing browser setup. ScreenshotNeo is a website screenshot API and MCP server; its API returns screenshots or PDFs from a URL. Its documented plans include a free tier and paid tiers listed below in the setup block.
8. Or skip the browser setup
If the input is a public URL and the goal is a rendered page capture, ScreenshotNeo accepts one GET request for the URL. It is a different fit from passing an arbitrary in-memory HTML string with custom JavaScript; use the browser examples above for that case. ScreenshotNeo supports screenshot output and PDF capture from web pages, with additional capture options in its API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo removes cookie banners, popups, and chat widgets before the shot. Bot checks, blank pages, and failed loads are never billed, and response headers report the page verdict and billing status. An MCP server lets AI agents use take_screenshot, get_page_info, and capture_pdf. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000 screenshots. See ScreenshotNeo and read the docs. Sign up for 1,000 free screenshots a month, with no card.
9. FAQ
Can I use this with HTML that has no external URL?
Yes. setContent() accepts markup directly, so an external page URL is not required. Any linked resources inside the markup still need URLs the browser can resolve.
Will JavaScript execute if it is in a separate string?
Only after you insert or add that code to the browser page. Include it in the HTML string before loading, or inject it through the automation API.
Should I wait for networkidle?
Not as a general proof that your application is ready. Wait for the specific content or state that must appear in the PDF.
Does page.pdf() return bytes or save a file?
Playwright returns a PDF buffer. Puppeteer’s guide demonstrates saving directly with the path option. Choose the form that fits how your application handles output.


