How to Load JavaScript from a String When Generating PDFs in Node.js
Learn when to run JavaScript before PDF rendering and when to embed it in the PDF, with complete Node.js, Puppeteer, pdf-lib, and ScreenshotNeo examples.
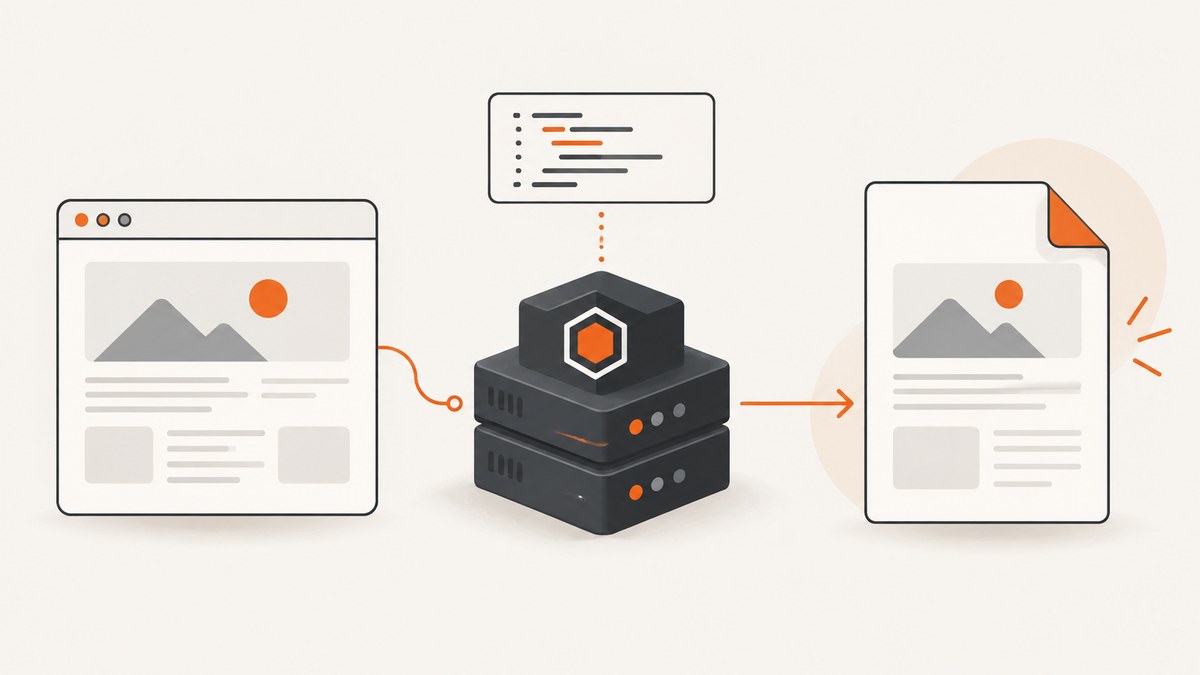
There are two different meanings behind “load JavaScript from a string” when generating a PDF in Node.js:
- Run JavaScript while the HTML page is being rendered, then print the resulting page to a PDF.
- Store JavaScript inside the finished PDF, so a compatible PDF viewer can run it when the document opens or when an action calls it.
These workflows use different tools. Puppeteer drives a browser and creates a visual printout with Page.pdf(). pdf-lib modifies PDF documents and exposes PDFDocument.addJavaScript(name, script) for attaching a script string to a document. Decide which stage you need before choosing an API.
Choose the execution stage first
| Goal | Input | Tool | Result |
|---|---|---|---|
| Execute code before printing | HTML, CSS, page JavaScript | Puppeteer | Static visual PDF |
| Attach code to a PDF | Existing PDF document and script string | pdf-lib | PDF with optional document JavaScript |
Use Puppeteer when the script changes the page: it can fill a template, calculate totals, render a chart, expand content, or add DOM nodes before printing. Use pdf-lib when the visual PDF already exists and you want to add document-level behavior. A PDF viewer may disable or ignore embedded scripts, so do not assume that every reader will execute them.

Run a JavaScript string before creating the PDF with Puppeteer
Puppeteer’s documentation says to use Page.pdf() for PDF printing. PDF generation uses print CSS media by default, and the API waits for fonts by default. If your design targets screen media, call page.emulateMediaType('screen') before printing. See the Puppeteer PDF generation guide and the Page.pdf() API reference.
Install Puppeteer
npm install puppeteerThe package downloads or uses a compatible Chromium build according to the Puppeteer version you install. Pin the version in production and read the matching documentation when you upgrade.
Complete example: HTML plus a script string
const puppeteer = require('puppeteer');

(async () => {
  const browser = await puppeteer.launch({
    headless: true,
    args: ['--no-sandbox', '--disable-setuid-sandbox']
  });

  try {
    const page = await browser.newPage();
    await page.setViewport({ width: 1280, height: 900, deviceScaleFactor: 1 });

    const html = `<!doctype html>
<html>
  <head>
    <meta charset="utf-8">
    <style>
      body { font-family: Arial, sans-serif; margin: 40px; }
      .total { font-size: 28px; color: #14532d; }
    </style>
  </head>
  <body>
    <h1>Invoice</h1>
    <div id="app"></div>
  </body>
</html>`;

    // This string runs inside the browser page, not in Node.js.
    const script = `
      const items = [
        { name: 'Design', price: 120 },
        { name: 'Hosting', price: 30 }
      ];
      const total = items.reduce((sum, item) => sum + item.price, 0);
      document.querySelector('#app').innerHTML =
        '<p>' + items.map(item =>
          item.name + ': $' + item.price
        ).join('<br>') + '</p>' +
        '<p class="total">Total: $' + total + '</p>';
    `;

    await page.setContent(html, { waitUntil: 'domcontentloaded' });

    // Evaluate the source string in the page context.
    await page.evaluate((source) => {
      (0, eval)(source);
    }, script);

    // Wait for a condition your script guarantees.
    await page.waitForSelector('.total');

    // Optional: use screen CSS instead of print CSS.
    // await page.emulateMediaType('screen');

    await page.pdf({
      path: 'invoice.pdf',
      format: 'A4',
      printBackground: true,
      preferCSSPageSize: true,
      margin: { top: '18mm', right: '14mm', bottom: '18mm', left: '14mm' }
    });
  } finally {
    await browser.close();
  }
})();
The important sequence is: create or load HTML, run the string in the browser context, wait for the resulting DOM or resources, and call page.pdf(). The eval call above is deliberately limited to a string you control. Never pass untrusted user input to eval; instead, expose a small function and pass validated data as arguments.
Safer alternative to eval: pass data to page code
const data = { customer: 'Ada', amount: 150 };
await page.evaluate((value) => {
  document.querySelector('#app').textContent =
    `${value.customer}: $${value.amount}`;
}, data);
If you must accept a source string, validate its origin, keep the browser isolated, and avoid giving the page unnecessary credentials or access to sensitive network resources.
Loading external scripts
If the string references a library, either include the library in the HTML or load it before printing. Wait for a deterministic signal such as window.reportReady = true and then use page.waitForFunction(() => window.reportReady === true). A network-idle event alone can be misleading because analytics, sockets, or advertisements may keep connections open.
await page.evaluate(() => {
  window.reportReady = false;
  const script = document.createElement('script');
  script.src = 'https://example.com/chart.js';
  script.onload = () => {
    // Render the chart here, then signal completion.
    window.reportReady = true;
  };
  script.onerror = () => { window.reportReady = 'error'; };
  document.head.appendChild(script);
});

await page.waitForFunction(() => window.reportReady === true, {
  timeout: 30000
});
For exact loading and sandbox behavior, check the API documentation for your installed Puppeteer version. The research-backed guarantees here are the PDF method, print-media default, and font waiting behavior.
Add JavaScript to an existing PDF with pdf-lib
When the PDF itself should contain JavaScript, use pdf-lib. Its API documents PDFDocument.addJavaScript(name, script). The library runs in Node.js and can create or modify PDFs; it is not a browser renderer, so it will not execute HTML, CSS, or page scripts for you. See the PDFDocument API and the pdf-lib project site.
Install and create a PDF with document JavaScript
npm install pdf-lib

const fs = require('node:fs');
const { PDFDocument, StandardFonts, rgb } = require('pdf-lib');

(async () => {
  const pdfDoc = await PDFDocument.create();
  const page = pdfDoc.addPage([595.28, 841.89]);
  const font = await pdfDoc.embedFont(StandardFonts.Helvetica);

  page.drawText('This PDF contains document JavaScript.', {
    x: 50,
    y: 780,
    size: 16,
    font,
    color: rgb(0.1, 0.1, 0.1)
  });

  const script = `
    app.alert('The PDF opened.');
  `;

  pdfDoc.addJavaScript('open-message', script);

  const bytes = await pdfDoc.save();
  fs.writeFileSync('scripted.pdf', bytes);
})();
The script is stored in the document as an attachment to the PDF’s JavaScript name. Viewer behavior is outside pdf-lib’s control: enterprise policies, browser PDF viewers, mobile readers, and security settings can block alerts or other actions. Treat embedded JavaScript as optional behavior and provide a usable static document.
Common options that affect the rendered PDF
Media, page size, and backgrounds
page.emulateMediaType('screen')selects screen media rules; omit it for the default print media.format: 'A4','Letter', or explicitwidth/heightcontrols the paper.printBackground: trueincludes CSS backgrounds and colors.preferCSSPageSize: truehonors CSS@pagedimensions when present.- Use
marginvalues with units such asmm,in, orpx.
Waiting and fonts
Wait for the event that proves your content is ready: a selector, a function, an application flag, or a short delay for an unavoidable animation. Puppeteer’s guide states that Page.pdf() waits for fonts by default. You still need to ensure external font URLs are reachable and that your CSS does not hide text until a late-running script finishes.
Page ranges and long documents
Use the PDF API’s page-range option when you only need selected pages. For very long pages, prefer normal document flow and CSS page breaks over a single enormous canvas. Split independent reports into separate jobs when memory usage becomes a problem.
Or skip the browser setup
ScreenshotNeo provides a GET API for PNG, JPEG, WebP, or PDF captures. It can run custom JavaScript before capture, wait for a selector, delay, or network idle, choose print settings, and return a PDF without you managing Chromium.
See the ScreenshotNeo documentation for the complete option list. A PDF request can use the same URL and add PDF parameters such as paper size, margins, landscape mode, or page ranges.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
'https://api.screenshotneo.com/v1/shot',
params={'access_key': 'YOUR_API_KEY', 'url': 'https://stripe.com'},
timeout=90,
)
r.raise_for_status()
open('shot.webp', 'wb').write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
require('node:fs').writeFileSync('shot.webp', buffer);ScreenshotNeo removes cookie banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and the response identifies the page verdict and billing status with X-Page-Verdict and X-Billed headers. Its MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 shots per month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
Troubleshooting
The PDF contains the original page, not the script output
Cause: the script ran in Node.js or ran after page.pdf(). Fix: execute it with page.evaluate before printing, then wait for a selector or readiness flag that the script creates.

document is not defined
Cause: browser-only code was executed in the Node.js process. Fix: move DOM code into page.evaluate or inject it into the page; keep filesystem and secrets in Node.js.
External images or fonts are missing
Cause: the resource failed, was blocked by CSP, or was still loading. Fix: use absolute HTTPS URLs, inspect requests, wait for a known completion condition, and confirm the runtime can reach the host. Inline critical assets when appropriate.
Screen styles do not appear
Cause: PDF printing uses print media by default. Fix: call await page.emulateMediaType('screen') before page.pdf(), or add explicit print CSS.
Embedded PDF JavaScript does nothing
Cause: the viewer blocks scripts or does not implement the action. Fix: test in the target reader, document the dependency, and keep the static PDF useful without scripting.
The process hangs
Cause: an open browser, unresolved page request, websocket, or wait condition. Fix: close the browser in a finally block, set explicit navigation and function timeouts, and avoid waiting forever for network idle.
Performance, reliability, and cost
- Reuse browsers carefully: launch one browser and create isolated pages for batches, then close it after the batch.
- Limit concurrency: too many Chromium pages increase CPU and memory use and can trigger site rate limits.
- Make readiness deterministic: a selector or application flag is more reliable than an arbitrary sleep.
- Cache stable assets: local fonts, CSS, and images reduce network variance.
- Record failures: save the URL, timeout stage, browser error, and PDF size for diagnosis, while excluding secrets.
- Retry selectively: retry navigation and transient network failures, but do not blindly retry deterministic script errors.
- Control document size: huge DOM trees and uncompressed images increase rendering time and memory.
Self-hosted Puppeteer costs your compute and browser maintenance time. pdf-lib avoids browser startup when you only modify a PDF, but it cannot replace HTML rendering. ScreenshotNeo charges only for clean shots; failed loads, bot checks, blank pages, timeouts, and cache hits are not billed. Its caching TTL, bulk capture, async jobs, signed webhooks, and usage API can reduce repeated work in production.
FAQ
Can one JavaScript string both render HTML and remain in the PDF?
Yes, but these are separate steps. Run one string in Puppeteer before printing, then use pdf-lib to add document JavaScript to the resulting PDF if a compatible viewer feature is also required.
Does pdf-lib execute browser JavaScript?
No. pdf-lib edits PDF structures. Use Puppeteer or another browser renderer for HTML, CSS, and DOM execution.
Why does the same PDF look different in a viewer?
PDF viewers can differ in font substitution, JavaScript support, and security policy. Validate the static layout first, then test optional interactive behavior in the readers your users actually use.
Should I use a delay or network idle?
Prefer a selector or explicit readiness flag. Delays are fragile, while network idle can never arrive on pages with long-lived connections.
Can ScreenshotNeo run custom page JavaScript?
Yes. Its capture options include custom JavaScript and waits, along with PDF output settings. Use the API when you want browser rendering without operating Puppeteer yourself.