Mastering Python cURL Requests: A Practical Guide for Developers
Translate cURL commands into reliable Python Requests code with timeouts, auth, sessions, uploads, retries, curl_cffi, and troubleshooting.
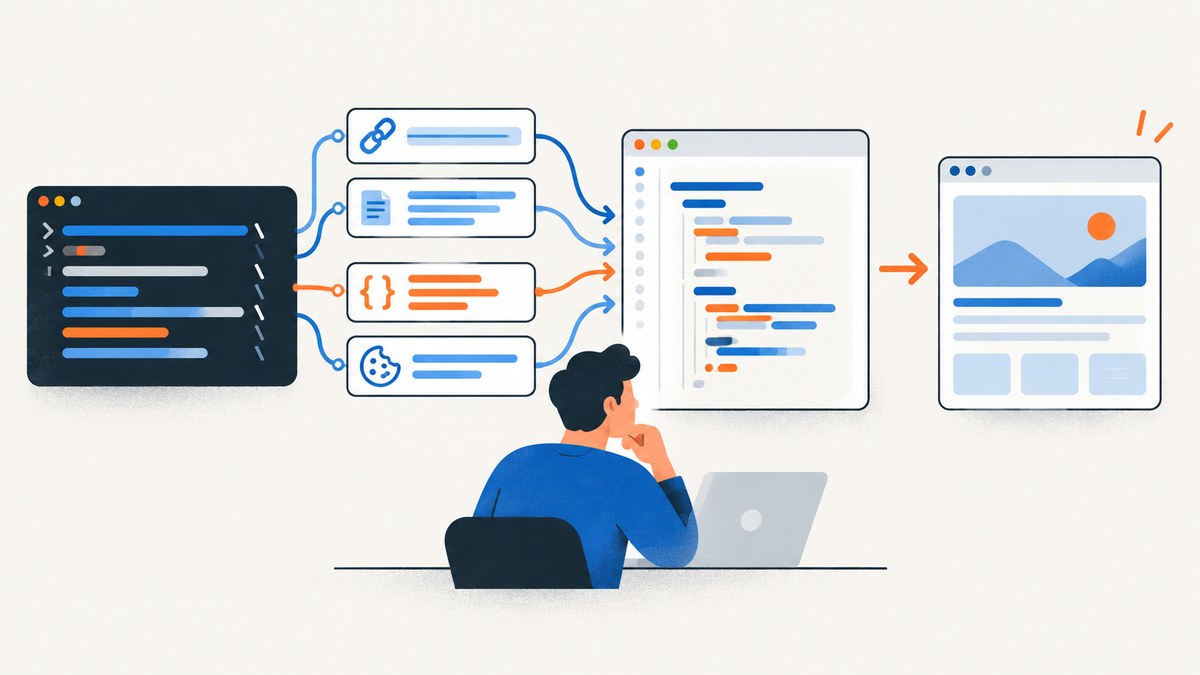
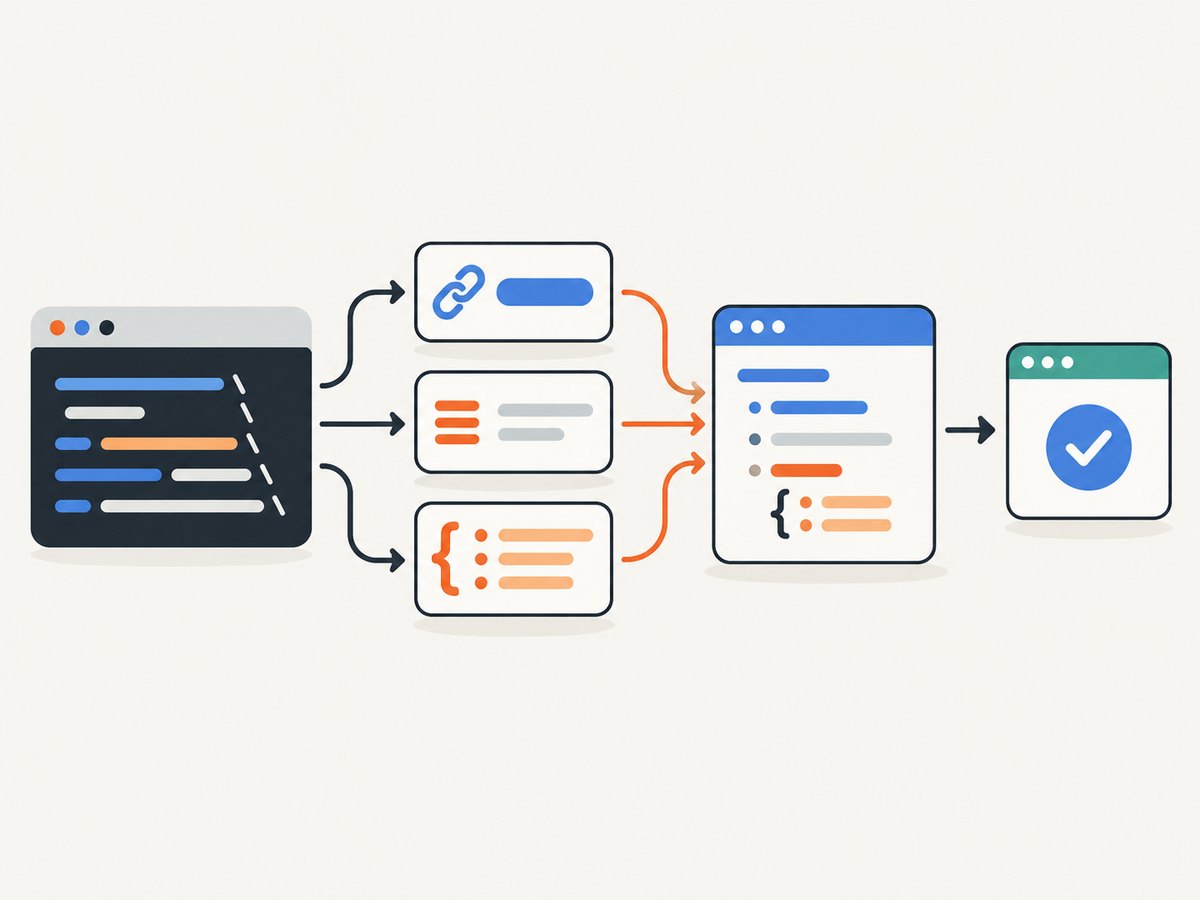
Direct answer: convert each cURL concern to the matching argument in Python Requests. Put query-string values in params, form or raw bodies in data, JSON bodies in json, headers in headers, credentials in auth, cookies in cookies, uploads in files, and network limits in timeout. Then check the status code, call raise_for_status() when appropriate, and parse the response according to its content type.
This guide starts with a one-to-one translation, then covers installation, request construction, authentication, sessions, reliability, performance, curl_cffi, and the errors developers most often meet when “cURL works but Python fails.” The examples use only placeholder credentials and public test endpoints; replace them with the contract documented by your API.
1. The cURL-to-Requests mental model
Consider this representative cURL command:
curl -G 'https://api.example.com/orders' \
  -H 'Accept: application/json' \
  -H 'Authorization: Bearer YOUR_TOKEN' \
  --data-urlencode 'status=paid' \
  --data-urlencode 'limit=25'
The equivalent Requests call is:
import requests

response = requests.get(
    "https://api.example.com/orders",
    params={"status": "paid", "limit": 25},
    headers={
        "Accept": "application/json",
        "Authorization": "Bearer YOUR_TOKEN",
    },
    timeout=(5, 30),
)
response.raise_for_status()
orders = response.json()| cURL option | Requests argument | Use it for |
|---|---|---|
-G plus --data-urlencode |
params= |
URL query parameters |
-H |
headers= |
HTTP headers |
-d, --data |
data= |
Form encoded or raw request bodies |
--json |
json= |
JSON body and content type |
-u user:password |
auth=(user, password) |
Basic authentication |
-F name=@file |
files= |
Multipart uploads |
-b/-c |
cookies= or a Session |
Cookies |
-L |
allow_redirects=True |
Following redirects (the default for GET) |
--max-time |
timeout= |
Connect and read limits |
The target server still decides the exact method, media type, authentication scheme, redirect policy, and status semantics. Requests is an HTTP client, not a translation layer that can infer an undocumented API contract.
2. Install Requests and make a safe first call
Install the package in the interpreter or virtual environment that runs your application:
python -m pip install requestsThe official Requests documentation describes it as an HTTP library with a simple API. Keep tokens in environment variables or a secret manager, and never commit them to source control.
import json
import os
import requests

url = "https://api.example.com/health"
headers = {"Accept": "application/json"}
token = os.environ.get("API_TOKEN")
if token:
    headers["Authorization"] = f"Bearer {token}"

try:
    response = requests.get(url, headers=headers, timeout=(5, 20))
    response.raise_for_status()
except requests.exceptions.Timeout:
    raise SystemExit("The server did not respond within the configured timeout")
except requests.exceptions.RequestException as exc:
    raise SystemExit(f"HTTP request failed: {exc}")

content_type = response.headers.get("content-type", "").lower()
print("status:", response.status_code)
print("request-id:", response.headers.get("x-request-id"))
if "application/json" in content_type:
    print(json.dumps(response.json(), indent=2))
else:
    print(response.text[:500])
3. Build requests correctly
Query parameters
Use params instead of concatenating strings. Requests URL-encodes spaces, ampersands, Unicode, lists, and repeated keys:
requests.get(
    "https://api.example.com/search",
    params={"q": "red shoes", "tag": ["sale", "new"]},
    timeout=30,
)
For APIs that expect repeated keys, a list produces repeated query values. Inspect response.request.url while debugging, but redact secrets before logging it.
JSON, forms, and raw data
json= serializes a Python object and sets the normal JSON content type. Use data= for form fields or an already serialized body:
# JSON
r = requests.post(
    "https://api.example.com/orders",
    json={"sku": "ABC-123", "quantity": 2},
    timeout=(5, 30),
)

# application/x-www-form-urlencoded form
r = requests.post(
    "https://api.example.com/login",
    data={"username": "alice", "password": os.environ["PASSWORD"]},
    timeout=30,
)

# Raw bytes (for example, an XML document)
r = requests.post(
    "https://api.example.com/import",
    data=b"<items></items>",
    headers={"Content-Type": "application/xml"},
    timeout=30,
)
Headers and cookies
r = requests.get(
    "https://api.example.com/profile",
    headers={
        "Accept": "application/json",
        "User-Agent": "inventory-worker/1.0",
    },
    cookies={"region": "eu"},
    timeout=30,
)
Cookie values are not a substitute for authentication unless the service explicitly documents that behavior. Avoid logging Cookie and Authorization headers.
Multipart file uploads
with open("report.csv", "rb") as handle:
    r = requests.post(
        "https://api.example.com/upload",
        files={"file": ("report.csv", handle, "text/csv")},
        data={"description": "March report"},
        timeout=(5, 120),
    )
r.raise_for_status()
Opening the file in binary mode preserves bytes. Close it with a context manager, and set a generous read timeout for large uploads or slow processing.
4. Responses, status codes, and errors
A response exposes status_code, case-insensitive headers, decoded text, raw content, and json(). Do not call json() merely because a request succeeded; check the media type or handle a decoding error.
response = requests.get("https://api.example.com/item/42", timeout=30)

if response.status_code == 404:
    print("The item does not exist")
elif response.ok:
    if "application/json" in response.headers.get("content-type", ""):
        item = response.json()
    else:
        item = response.text
else:
    # Raises HTTPError for unsuccessful 4xx/5xx responses.
    response.raise_for_status()
The quickstart and API reference document raise_for_status() and timeout behavior: quickstart and API reference. For an API that returns useful validation details in a 400 response, read the body before raising or catch requests.exceptions.HTTPError and include a redacted request ID in your log.
5. Timeouts and reliable retries
Always set a timeout. A scalar such as timeout=30 applies one limit, while timeout=(5, 30) separates connection establishment from waiting for response bytes. Neither value is a total wall-clock limit for every streamed byte.
import random
import time
import requests

RETRYABLE = {429, 500, 502, 503, 504}

def get_with_backoff(url, attempts=4):
    for attempt in range(attempts):
        try:
            response = requests.get(url, timeout=(5, 30))
            if response.status_code not in RETRYABLE:
                response.raise_for_status()
                return response
        except requests.exceptions.Timeout:
            if attempt == attempts - 1:
                raise
        except requests.exceptions.ConnectionError:
            if attempt == attempts - 1:
                raise
        delay = min(8, 0.5 * (2 ** attempt)) + random.random() * 0.2
        time.sleep(delay)
    raise RuntimeError("request failed after retries")
Retry only operations that are safe to repeat, or use an idempotency key supported by the API. Respect Retry-After for 429 and 503 responses. Do not blindly retry authentication failures, malformed requests, or a POST that may have succeeded before the connection broke.
6. Sessions, cookies, and connection pooling
A requests.Session persists cookies, applies shared headers, and reuses pooled connections. That reduces handshake overhead for repeated calls and is useful for login flows. The advanced usage documentation covers this behavior: Sessions and advanced usage.
import requests

with requests.Session() as session:
    session.headers.update({
        "Accept": "application/json",
        "User-Agent": "billing-sync/2.1",
    })
    login = session.post(
        "https://api.example.com/login",
        json={"email": "alice@example.com", "password": "..."},
        timeout=(5, 20),
    )
    login.raise_for_status()

    account = session.get("https://api.example.com/account", timeout=(5, 20))
    account.raise_for_status()
    print(account.json())
Use a context manager or call session.close(). Keep sessions scoped to a worker or client rather than sharing one carelessly across unrelated threads. TLS verification is enabled by default; do not disable it as a routine workaround. For a private certificate authority, point verify to the approved CA bundle.
7. Authentication patterns
Requests supports Basic and Digest authentication, .netrc, and integrations for OAuth and OAuth 2/OpenID Connect. The authentication guide is at requests.readthedocs.io authentication. The server determines which scheme, scopes, audience, and refresh behavior are valid.
# Basic auth (Requests builds the Authorization header)
r = requests.get(
    "https://api.example.com/private",
    auth=(os.environ["USER"], os.environ["PASSWORD"]),
    timeout=30,
)

# Bearer token acquired elsewhere
r = requests.get(
    "https://api.example.com/private",
    headers={"Authorization": f"Bearer {os.environ['ACCESS_TOKEN']}"},
    timeout=30,
)
Acquire and refresh tokens outside low-level request functions. Keep scopes minimal, redact tokens in exception logs, and never place credentials in query strings unless the provider explicitly requires it.
8. Why cURL works but Requests fails
- Different URL encoding: compare
response.request.urlwith the working cURL URL. Move values intoparamsinstead of hand-building a query string. - Missing content type: use
json=payloador set the exactContent-Typerequired by the API. - Authentication mismatch: cURL’s
-umeans Basic auth; a bearer token belongs in anAuthorizationheader. Digest auth requires a different handler. - Redirect differences: inspect
response.history, the final URL, and whether authorization is retained across a host change. - Certificate or proxy differences: compare proxy environment variables, CA bundles, and TLS policy. Fix the trust store instead of setting
verify=False. - Timeout differences: cURL may have a command-level limit while Python waits indefinitely. Set connect and read values explicitly.
- Body formatting: cURL’s
-dcan send a form body; sending the same text throughjson=changes the wire format.
9. Performance, streaming, and operational cost
Use a Session for repeated requests so connections can be reused. Avoid downloading large responses into memory: stream them and write chunks to disk.
with requests.get(
    "https://cdn.example.com/archive.zip",
    stream=True,
    timeout=(5, 120),
) as response:
    response.raise_for_status()
    with open("archive.zip", "wb") as output:
        for chunk in response.iter_content(chunk_size=1024 * 1024):
            if chunk:
                output.write(chunk)
Bound concurrency to the service’s rate limits and your connection pool. Record latency, status, response size, retry count, and a provider request ID; redact URLs that contain secrets. Keep dependency versions pinned and review certificate, proxy, and authentication changes as deployment configuration.
10. When to use curl_cffi
Requests is the default for ordinary API clients. curl_cffi provides a Requests-like interface plus curl-oriented options, browser impersonation controls, sessions, and a CLI. Its documentation exposes an impersonate parameter; see the quickstart and API reference.
from curl_cffi import requests

response = requests.get(
    "https://example.com",
    impersonate="chrome",
    timeout=30,
)
response.raise_for_status()
print(response.status_code)| Consideration | Requests | curl_cffi |
|---|---|---|
| Migration effort | Standard Python HTTP API | Similar surface, with curl-specific options |
| Sessions and cookies | Built-in sessions and pooling | Sessions plus curl behavior |
| Browser or TLS fingerprint needs | Not its purpose | Impersonation controls are available |
| Deployment | Small, familiar dependency | Review native-library and policy requirements |
| CLI | Use cURL separately | Documentation provides uv run curl-cffi and python -m curl_cffi |
Impersonation does not grant permission to access a site or override its terms. Choose it only when your compatibility and operational requirements justify the additional dependency.
11. Or skip the browser setup
If your goal is a clean website image rather than an HTTP API response, ScreenshotNeo turns one GET request into a PNG, JPEG, WebP, or PDF. It accepts cookie and consent banners as a visitor, removes more than 60 known consent platforms plus newsletter popups and chat widgets, and lets you turn each step off. Only clean shots are billed: bot checks, CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers identify the page verdict and billing status.
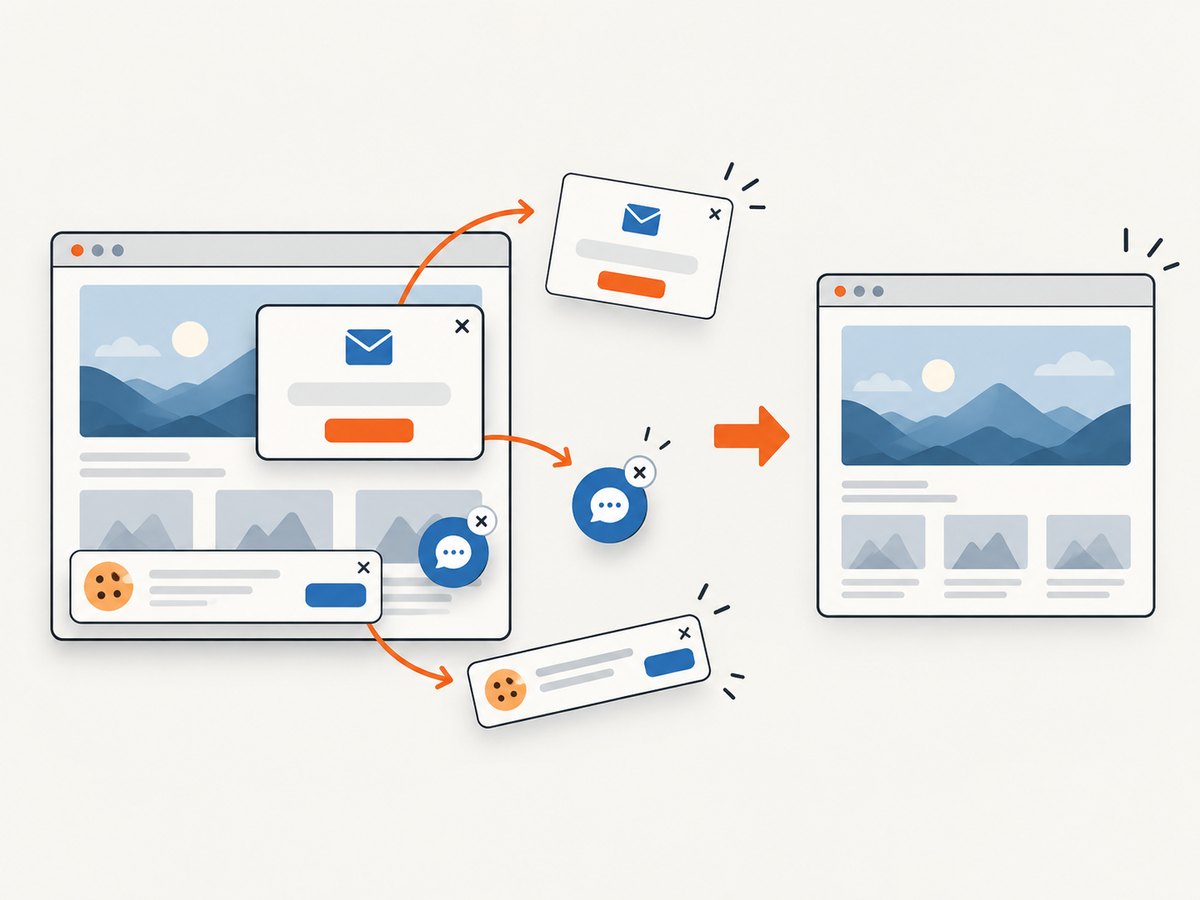
See the ScreenshotNeo API documentation for all options. A minimal Python call is:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
The same request with cURL:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpAnd Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
ScreenshotNeo also offers full-page captures with lazy images loaded, CSS-selector element shots, dark mode, device presets and custom viewports, retina scale, PDF paper and page controls, custom CSS and JavaScript, clicks, selector or network-idle waits, request blocking, custom headers and cookies, timezone and geolocation, transparent backgrounds, resizing, selectable cache TTLs, signed image links, asynchronous jobs with signed webhooks, bulk capture for up to 100 URLs, a usage API, and an OpenAPI specification. An MCP server exposes take_screenshot, get_page_info, and capture_pdf to Claude, Cursor, and other MCP clients.
There is a free allowance of 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is on every plan. Create a free ScreenshotNeo account.
12. Troubleshooting checklist
- Timeout: set a tuple such as
(5, 30); increase only the read limit when the server is legitimately slow. - SSLError: install the correct CA bundle or configure the approved private CA with
verify=. - 401 or 403: verify scheme, token audience, scopes, expiry, and whether a redirect changed the host.
- 415 Unsupported Media Type: match the API’s content type; choose
json=,data=, or multipartfiles=correctly. - 429 Too Many Requests: honor
Retry-After, reduce concurrency, and use bounded exponential backoff. - JSON decoding error: inspect
Content-Type, status, and the first bytes ofresponse.content; error pages are often HTML. - Connection pool exhaustion: close streamed responses and sessions, and avoid leaving response bodies unread.
- Unexpected cookies: use a dedicated Session and inspect
session.cookiesafter redirects and login.
FAQ
Should I use data or json?
Use json for a JSON object. Use data for form encoding or a raw body whose serialization you control.
Is a Session required for one request?
No. A direct function call is fine for an isolated request. Use a Session when calls share cookies, headers, or a host.
Does a timeout cancel server-side work?
It stops waiting in the client. The server may continue processing, so retry only when the operation is safe or idempotency is supported.
When is curl_cffi justified?
Choose it when curl-level behavior or browser impersonation is a documented compatibility requirement. For ordinary APIs, Requests has the simpler deployment path.
How do I keep converted cURL code maintainable?
Separate configuration and credentials from request construction, use a Session for shared policy, set timeouts everywhere, check status explicitly, and test the wire format against the API contract.


