Why Monitor Large-Scale Web Scraping Projects?
Learn which scraping metrics, data checks, alerts, and collection patterns keep large web scraping jobs reliable as they grow.
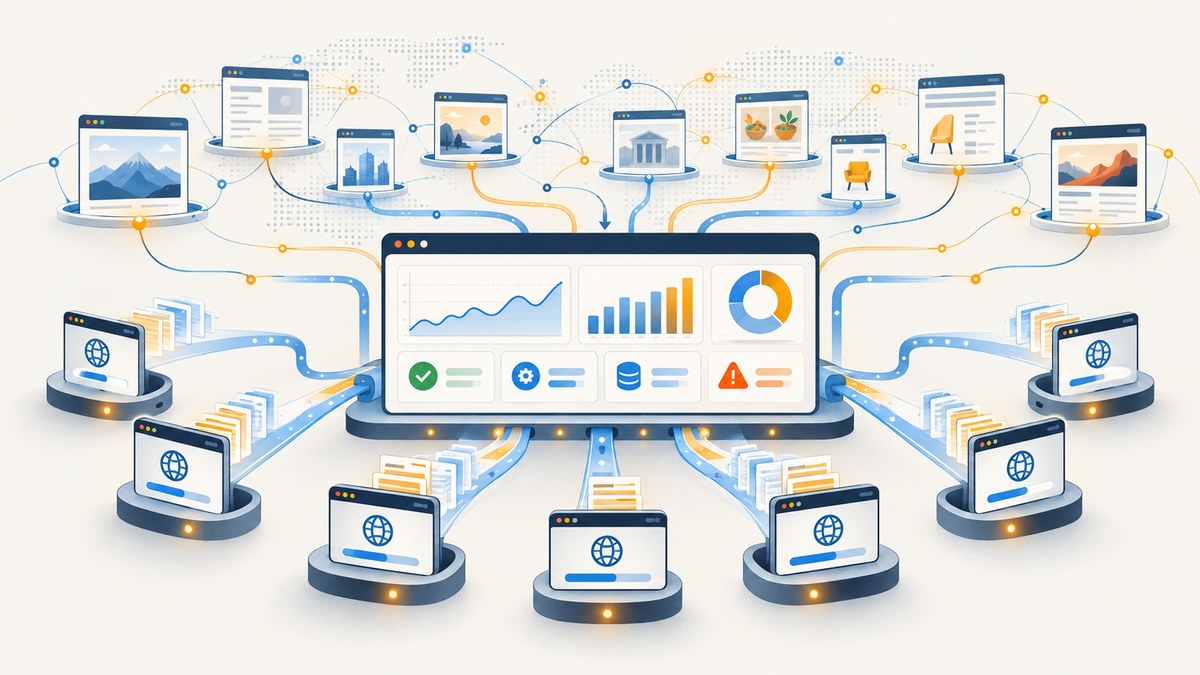
Large scraping projects fail in ways that a process monitor cannot see. A worker can remain online while requests begin timing out, a parser can return structurally valid but incomplete records, or a pipeline can stop writing data while queues continue to drain. Monitoring makes those failure modes visible early enough to investigate them before downstream users rely on stale or incomplete data.
The practical answer is to monitor outcomes as well as infrastructure. Record whether each expected run completed, how long it took, what each stage did, how many requests and records succeeded, and whether the output passed completeness checks. Then alert on missed runs, delays, error-rate changes, output drops, and stale downstream data. Prometheus describes metrics as a diagnostic aid for understanding why an application behaves as it does (Prometheus overview).
What monitoring prevents
Monitoring does not make a target site available or settle whether a crawl is permitted. It gives your team evidence about what happened, where it changed, and which response is appropriate.
- Silent stoppage: a scheduled job never starts or exits before completing its partitions.
- Slow degradation: latency rises, queues grow, or a stage takes longer after a deployment or target-site change.
- Hidden extraction failure: pages load successfully but selectors no longer match, producing few or zero useful items.
- Persistence failure: extraction continues while validation, deduplication, or storage rejects records.
- Stale data: the pipeline appears healthy but the newest accepted record is older than the business requirement.
- Capacity and cost surprises: retries, excessive resource use, or an expanding backlog increase operational work and infrastructure cost.
Define success before you scale
Start with the business case and the data contract. Zyte’s scale-planning guidance recommends defining the required data, evaluating team and infrastructure capabilities, and estimating development and infrastructure costs before increasing volume (Web Scraping at Scale). Write down:
- The expected schedule and freshness target for every job or partition.
- The fields that must be present for a record to be accepted.
- Reasonable ranges for record counts, response status, and latency.
- What constitutes a completed run and where its output is published.
- Who receives an alert and what action they can take.
These definitions turn a dashboard into an operational contract. A run that processes one million pages but produces no accepted records is a failed run even if every worker reports healthy.
The metric set for a large scraper
Prometheus recommends tracking the last successful run, the last completion whether successful or failed, total runtime, stage runtimes, and job-specific totals such as records processed (Prometheus instrumentation practices). Extend that baseline with signals that show quality and freshness.

| Area | Metrics | What a change can indicate |
|---|---|---|
| Schedule | Last success timestamp; last completion timestamp; run status; run count | Missed schedules, crashes, or jobs that finish with failure |
| Requests | Attempts; responses by status; errors; latency percentiles; retries | Target changes, network problems, throttling, or an overloaded worker pool |
| Stages | Request, extraction, validation, deduplication, and persistence duration and counts | The stage where a run is stalled or degrading |
| Output | Records extracted, accepted, rejected, written, and duplicate counts | Parser breakage, quality-rule changes, or storage failures |
| Freshness | Newest source timestamp; newest accepted-record timestamp; propagation heartbeat | Stale data even when workers and queues look active |
| Capacity | Queue depth, backlog age, worker utilization, and resource saturation | Insufficient workers, memory pressure, or an uneven partition |
Track attempts as well as errors so you can calculate an error ratio. Track records at each boundary, not only the final total. A fall from extracted to accepted records points toward validation or schema changes; a fall from accepted to written points toward persistence.
Instrument the pipeline by stage
Scrapy separates crawling and scraping components from item pipelines that can clean, validate, deduplicate, or store items (Scrapy item pipelines). Mirror that separation in your metrics. Give each stage a counter and a duration metric, and attach a bounded label such as job, site, or partition.
A small Python example using the Prometheus client library illustrates the shape of instrumentation. Adapt the calls to your framework and storage layer:
from time import monotonic
from prometheus_client import Counter, Gauge, Histogram, start_http_server

runs = Counter("scraper_runs_total", "Completed runs", ["job", "status"])
requests = Counter("scraper_requests_total", "HTTP attempts", ["job", "result"])
records = Counter("scraper_records_total", "Records by pipeline stage", ["job", "stage"])
stage_seconds = Histogram("scraper_stage_seconds", "Stage duration", ["job", "stage"])
last_success = Gauge("scraper_last_success_timestamp", "Unix time of last successful run", ["job"])
heartbeat = Gauge("scraper_heartbeat_timestamp", "Unix time of latest pipeline heartbeat", ["job"])

start_http_server(8000)

def run(job, fetch, extract, validate, write):
    try:
        with stage_seconds.labels(job, "request").time():
            pages = fetch()
        requests.labels(job, "attempt").inc(len(pages))
        records.labels(job, "extracted").inc(len(pages))

        with stage_seconds.labels(job, "extraction").time():
            items = extract(pages)
        with stage_seconds.labels(job, "validation").time():
            accepted = [item for item in items if validate(item)]
        records.labels(job, "accepted").inc(len(accepted))

        with stage_seconds.labels(job, "persistence").time():
            write(accepted)
        records.labels(job, "written").inc(len(accepted))
        runs.labels(job, "success").inc()
        last_success.labels(job).set(monotonic())
    except Exception:
        runs.labels(job, "failure").inc()
        raise
    finally:
        heartbeat.labels(job).set(monotonic())
Use wall-clock Unix timestamps in production rather than a process-relative clock such as monotonic() when another system must compare freshness. The example focuses on metric shape; your scheduler should set the run start and completion values and handle retries explicitly.
Collection models: pull and push
Long-running workers can expose a metrics endpoint for Prometheus to scrape. This gives you resource, latency, and queue series over time. Short-lived batch jobs may exit before a pull occurs. Prometheus recommends reporting batch-job gauges such as last success through Pushgateway; jobs running longer than a few minutes can also use pull-based collection (instrumentation practices).
A minimal scrape configuration looks like this:
global:
  scrape_interval: 15s

scrape_configs:
  - job_name: "scraper-workers"
    static_configs:
      - targets: ["worker-1:8000", "worker-2:8000"]
For a batch job, push a small set of gauges after completion and include a stable grouping key. Remove or expire old groups when partitions are deleted so the monitoring system does not retain stale series.
Alert design that leads to action
Alerts should describe a condition, its scope, and the first useful action. Tie thresholds to the schedule and business requirement; the sources do not prescribe universal values.
- Missed run: alert when the last completion is older than the expected schedule plus an investigation window.
- Failed run: alert on a failed completion and include the job, partition, and run identifier.
- Stage delay: alert when request, extraction, validation, or persistence duration stays above its normal operating range.
- Error ratio: alert on errors divided by attempts, with enough attempts to avoid noise from tiny runs.
- Output anomaly: alert when accepted or written records fall outside the expected range, or when the acceptance ratio changes sharply.
- Backlog: alert when queue depth or backlog age threatens the freshness target.
- Stale downstream data: alert when the propagation heartbeat or newest accepted record stops advancing.
Keep metric labels bounded. Prometheus cautions that cardinality above 100, or dimensions that could grow to that level, should prompt investigation. Do not label metrics with URLs, request IDs, arbitrary error text, or other unbounded values; put those details in logs or traces instead.
Data-quality checks catch healthy-looking failures
Transport success is not data success. Add checks for required fields, type validity, duplicate rates, allowed value ranges, and minimum or expected record counts. Compare each partition with its own historical pattern where seasonality is understood, and use explicit business rules for critical fields.
Scrapy’s item pipelines provide natural points for cleaning, validating, deduplicating, and storing records. Spidermon is described by Zyte as an open-source extension for checking spider statistics, validating data, and notifying a team when checks fail (Spidermon). The cited page is older, so verify current maintenance and compatibility before adopting it.
Store the run’s validation summary with the output: extracted, accepted, rejected, duplicate, and written counts; rule names and failure counts; and the source window covered. This makes a later investigation possible without rerunning the entire crawl.
Cardinality, retention, and cost
As targets and partitions grow, monitoring itself needs capacity planning. Use low-cardinality labels and aggregate where detailed dimensions are not needed. Retain high-value run summaries longer than noisy per-request series. Query cost grows with the number of series, retention period, and dashboard range, so decide which data is needed for live diagnosis versus historical reporting.
Prometheus is designed for numeric time series and diagnosis. Its documentation says it is not appropriate as the sole source for 100%-accurate per-request billing; use a complete processing or billing system for that requirement (Prometheus overview). Keep immutable run and usage records in your application datastore when financial reconciliation matters.
Common failure modes and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| No metrics for a completed batch | The process exited before a pull scrape | Push completion gauges through Pushgateway, or run a long-lived exporter. |
| Dashboard shows workers up but output is empty | Selectors or extraction logic changed | Alert on accepted-record totals and validation ratios; retain sample failures for inspection. |
| Error percentage is noisy | Very small sample sizes or retries counted inconsistently | Alert only after a minimum attempt count and define whether retries are attempts or separate events. |
| Series count grows without limit | Unbounded labels such as URL or request ID | Remove those labels and place details in logs or traces. |
| Last-success alert never fires | Gauge is reset on restart or set only on process start | Persist the completion timestamp and update it only after a successful end-to-end run. |
| Records are delayed downstream | Persistence or propagation stage is stalled | Measure stage counts and a heartbeat after the final write, then alert on freshness. |
| Monitoring costs rise with scale | Too many dimensions, long retention, or expensive queries | Aggregate labels, shorten noisy retention, and keep detailed run data outside the metrics system. |
Operational checklist
- Define expected schedule, freshness, and minimum acceptable output for every job.
- Record last success and last completion separately.
- Count attempts, errors, latency, retries, and responses by useful status groups.
- Measure request, extraction, validation, deduplication, and persistence stages.
- Track extracted, accepted, rejected, duplicate, and written records.
- Add schema and completeness checks that can fail a run explicitly.
- Choose pull collection for long-running workers and push reporting for short batches.
- Keep labels bounded and move high-cardinality details to logs.
- Test alerts with a controlled failed run and document the first responder action.
- Review retention, query cost, and infrastructure capacity as targets grow.
Or skip the browser setup
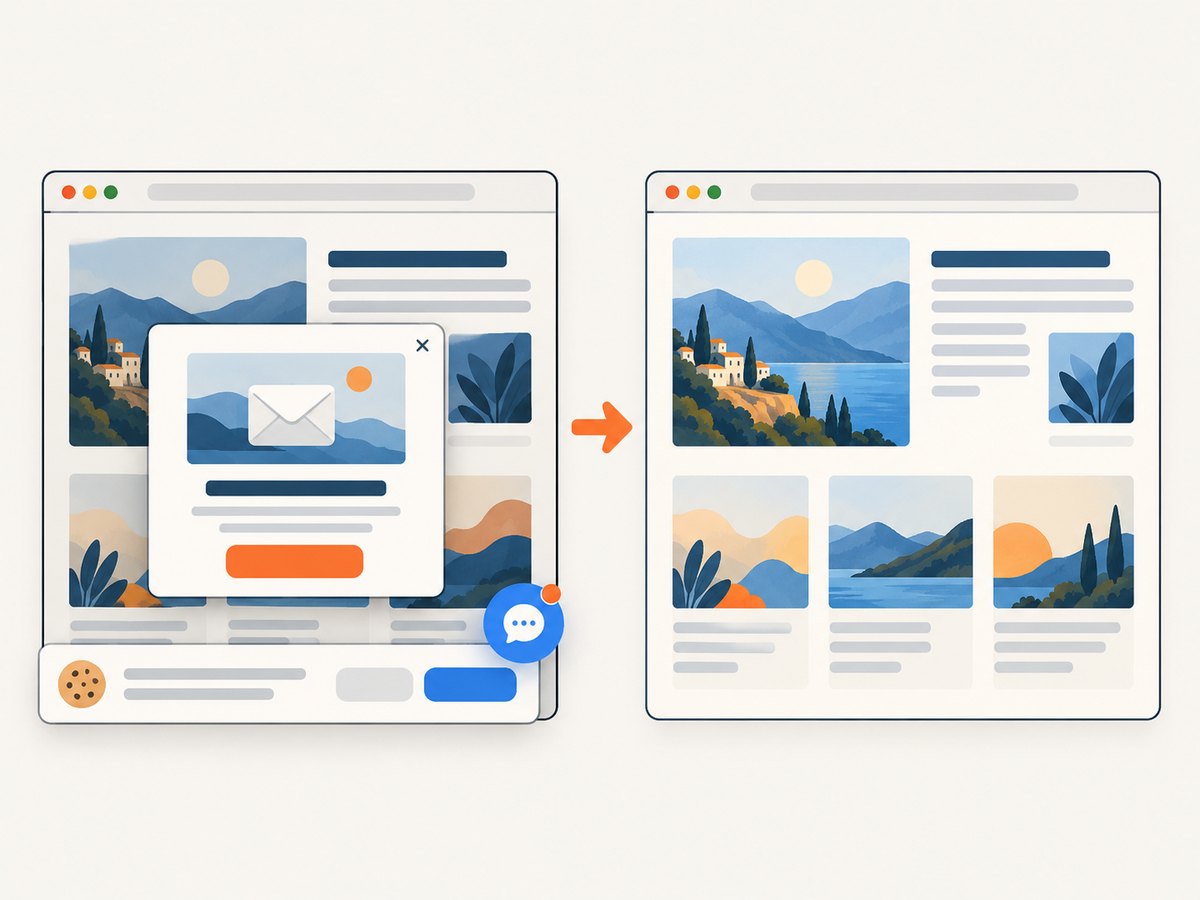
When your monitoring workflow needs reliable page images for incident records, visual checks, or dataset evidence, ScreenshotNeo provides a website screenshot API and MCP server. One GET request returns a PNG, JPEG, WebP, or PDF. It accepts cookie and consent banners like a visitor, removes more than 60 known consent platforms plus newsletter popups and chat widgets, and lets you turn each cleanup step off.
Only clean shots are billed. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and each response reports the result through X-Page-Verdict and X-Billed headers. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
See the ScreenshotNeo API documentation for all options. This is a complete cURL example:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o incident-shot.webp
Python:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("incident-shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({
  access_key: 'YOUR_API_KEY',
  url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const data = Buffer.from(await res.arrayBuffer());
await require('node:fs').promises.writeFile('incident-shot.webp', data);
You can also capture full pages with lazy images loaded, one element by CSS selector, dark mode, device presets or custom viewports, retina scale, PDFs with paper size and margins, HTML or CSS, custom JavaScript, clicks, waits, blocked resources, custom headers and cookies, timezone and geolocation, transparent backgrounds, resizing, chosen cache TTLs, signed image links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs per call, and usage data. Existing parameter names used by other screenshot APIs also work, which simplifies migration.
Start with 1,000 free screenshots each month with no card. Paid plans start at $5 for 3,000 shots; every feature is available on every plan.
FAQ
Should every request be a separate metric?
No. Aggregate requests with bounded labels. Put request-specific URLs, identifiers, and diagnostic text in logs or traces.
What proves that a run succeeded?
Use an end-to-end definition: expected partitions completed, accepted records passed validation, and data was written and propagated. A live worker or successful HTTP response alone is insufficient.
When should I use Pushgateway?
Use it for short-lived batch jobs that may finish between Prometheus scrapes. Long-running workers can expose a pull endpoint.
Can monitoring determine whether scraping is allowed?
No. Monitoring reports operational behavior. Follow the target’s terms, permissions, and applicable requirements. Scrapy recommends an identifying User-Agent where crawling is allowed so site owners can contact the operator (Scrapy common practices).
How do I detect a parser that still returns valid-looking data?
Track accepted-record totals, required-field checks, value distributions, and freshness. Alert on completeness and acceptance changes, not only exceptions.