Node.js SDK: Generate PDFs from JavaScript and TypeScript
Compare PDFKit, pdf-lib and Puppeteer, then build, edit and print PDFs with complete Node.js and TypeScript examples.
Short answer: choose the PDF tool that matches your source document. Use PDFKit when you want to draw a document from primitives such as text, paths, images and tables. Use pdf-lib when you need to create, inspect or modify existing PDF structures, pages or forms. Use Puppeteer when the document already exists as HTML and CSS and you want a browser engine to print it.
This guide shows complete Node.js and TypeScript implementations, explains the important options and edge cases, and compares the three approaches without claiming a universal performance winner. The official documentation describes different feature sets, not a fair same-workload benchmark; measure your own workload when throughput or memory is decisive.
Choose the right Node.js PDF approach
| Approach | Best fit | Main tradeoff |
|---|---|---|
| PDFKit | Drawing printable documents from text, vectors, images, tables or forms | Node output is stream-based; browser builds have a narrower stream interface |
| pdf-lib | Creating and editing PDF files, pages, embedded content and forms | Its API is an explicit PDF-document editing model |
| Puppeteer | Printing an HTML/CSS page with Chromium | It automates browser printing rather than exposing drawing primitives |
Decide using five questions:

- Is your source layout drawing commands or HTML/CSS?
- Must you edit an existing PDF?
- Do you need a browser runtime, or only Node?
- Should the result stream directly to a file or HTTP response?
- Are forms, custom fonts, page ranges or print-specific CSS required?
Set up a Node.js project
Use a current Node.js LTS release and initialize a project:
mkdir node-pdf-example
cd node-pdf-example
npm init -y
npm install pdfkit pdf-lib puppeteer
npm install --save-dev typescript tsx @types/node @types/pdfkit
Use ES modules by adding "type": "module" to package.json. The examples below use ES module syntax. If your project uses CommonJS, PDFKit’s documented form is the named export from require('pdfkit').
Generate a PDF with PDFKit
PDFKit is a drawing-oriented JavaScript PDF generation library for Node and browsers. Its documented feature set includes vector paths and transformations, text layout and alignment, embedded TrueType, OpenType and WOFF fonts, JPEG and PNG images, tables, annotations, AcroForms, outlines and security options. In Node, a document is a readable stream: pipe it to a file or HTTP response, add content, then call end().
Runnable Node.js example
import { PDFDocument } from 'pdfkit';
import fs from 'node:fs';

const doc = new PDFDocument({
  size: 'A4',
  margins: { top: 50, bottom: 50, left: 50, right: 50 },
  info: {
    Title: 'Node.js PDF example',
    Author: 'Example application'
  }
});

const output = fs.createWriteStream('pdfkit-report.pdf');
doc.pipe(output);

doc.fontSize(22).text('Monthly report', { align: 'center' });
doc.moveDown();
doc.fontSize(11).text('Generated with PDFKit in Node.js.');
doc.moveDown();
doc
  .fontSize(12)
  .text('PDFKit lets you place text, draw vector shapes and embed images directly on each page.');

doc.moveDown();
doc
  .rect(50, 180, 495, 70)
  .fill('#e8f0fe');
doc.fillColor('#111').fontSize(14).text('Revenue: $42,000', 70, 205);

doc.addPage();
doc.fontSize(18).text('Second page');
doc.fontSize(11).moveDown().text('Add pages whenever the document needs a new layout.');

doc.end();

output.on('finish', () => console.log('Wrote pdfkit-report.pdf'));
The stream does not contain a complete PDF until doc.end() runs. In an HTTP handler, replace the file stream with the response and set Content-Type: application/pdf before piping.
PDFKit options and edge cases
- Page geometry: pass a standard size such as
A4or a custom width and height. Set margins explicitly so wrapping is predictable. - Fonts: register and select a font before drawing text. Embed the font when the PDF must render consistently on machines that do not have it installed.
- Images: use PNG for transparency and JPEG for photographs. Resolve file paths on the server; browser builds cannot directly read filesystem paths.
- Long content: track the current Y position and add a page before content runs into the bottom margin. Tables need their own row-height and page-break logic.
- Browser builds: the guide describes a limited stream interface and no filesystem access. Register asset bytes rather than passing a path. The
toBlobandtoByteshelpers underpdfkit/outputare documented as experimental.
Create and edit PDFs with pdf-lib
pdf-lib is written in TypeScript, compiled to pure JavaScript, and documented for Node, browsers, Deno and React Native. It can create documents, add, insert and remove pages, draw text and images, embed PDF pages, create or fill forms, and save a modified file.
Create a new document
import { PDFDocument, StandardFonts, rgb } from 'pdf-lib';
import fs from 'node:fs/promises';

const pdfDoc = await PDFDocument.create();
const page = pdfDoc.addPage([595.28, 841.89]); // A4 points
const font = await pdfDoc.embedFont(StandardFonts.Helvetica);

page.drawText('Invoice 1007', {
  x: 56,
  y: 780,
  size: 22,
  font,
  color: rgb(0.08, 0.12, 0.2)
});
page.drawText('Subtotal: $120.00', { x: 56, y: 730, size: 12, font });
page.drawRectangle({
  x: 56, y: 680, width: 480, height: 1,
  color: rgb(0.75, 0.78, 0.82)
});

const bytes = await pdfDoc.save();
await fs.writeFile('invoice.pdf', bytes);
Load and modify an existing PDF
import { PDFDocument, StandardFonts, rgb } from 'pdf-lib';
import fs from 'node:fs/promises';

const input = await fs.readFile('source.pdf');
const pdfDoc = await PDFDocument.load(input);
const pages = pdfDoc.getPages();
const first = pages[0];
const font = await pdfDoc.embedFont(StandardFonts.HelveticaBold);

first.drawText('Reviewed', {
  x: 48,
  y: 48,
  size: 10,
  font,
  color: rgb(0.8, 0.1, 0.1)
});

const output = await pdfDoc.save();
await fs.writeFile('reviewed.pdf', output);
Custom fonts and document operations
For a custom font, install and register the documented fontkit integration, then embed the font bytes:
npm install @pdf-lib/fontkitimport { PDFDocument } from 'pdf-lib';
import fontkit from '@pdf-lib/fontkit';
import fs from 'node:fs/promises';
const pdfDoc = await PDFDocument.create();
pdfDoc.registerFontkit(fontkit);
const fontBytes = await fs.readFile('./Inter-Regular.ttf');
const font = await pdfDoc.embedFont(fontBytes);
const page = pdfDoc.addPage();
page.drawText('Text using an embedded font', { x: 50, y: 750, font, size: 16 });
await fs.writeFile('custom-font.pdf', await pdfDoc.save());
Use getPages(), insertPage(), removePage() and page embedding for splitting, merging and rearranging files. Form APIs cover creating and filling interactive fields. Loading an untrusted or malformed PDF can fail; catch the exception and reject the upload with a clear validation error.
Print HTML and CSS with Puppeteer
Puppeteer launches a browser, navigates to a page and calls page.pdf(). The official guide says PDF generation uses print CSS media and waits for fonts to load by default. This is usually the shortest route when your design already lives in HTML and CSS.
import puppeteer from 'puppeteer';

const browser = await puppeteer.launch({ headless: true });
try {
  const page = await browser.newPage();
  await page.setContent(`
    <!doctype html>
    <html>
      <head>
        <style>
          @page { size: A4; margin: 18mm; }
          body { font-family: Arial, sans-serif; color: #172033; }
          h1 { color: #2457a6; }
          .total { break-inside: avoid; border-top: 1px solid #ccd3df; padding-top: 12px; }
        </style>
      </head>
      <body>
        <h1>Invoice</h1>
        <p>This page is printed by Chromium.</p>
        <div class="total">Total: $120.00</div>
      </body>
    </html>`, { waitUntil: 'networkidle0' });

  await page.pdf({
    path: 'puppeteer-report.pdf',
    format: 'A4',
    printBackground: true,
    preferCSSPageSize: true,
    margin: { top: '18mm', right: '18mm', bottom: '18mm', left: '18mm' }
  });
} finally {
  await browser.close();
}
For a URL, use page.goto(url, { waitUntil: 'networkidle0' }) instead of setContent. Use print-specific rules such as @page, break-inside and break-before. If your page loads remote fonts or images, wait for those resources explicitly when they are not covered by navigation readiness.
Or skip the browser setup
ScreenshotNeo provides a website screenshot API that can return PNG, JPEG, WebP or PDF from one GET request. It handles browser capture for you and includes PDF controls such as paper size, margins, landscape mode and page ranges. See the ScreenshotNeo documentation for the current request options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
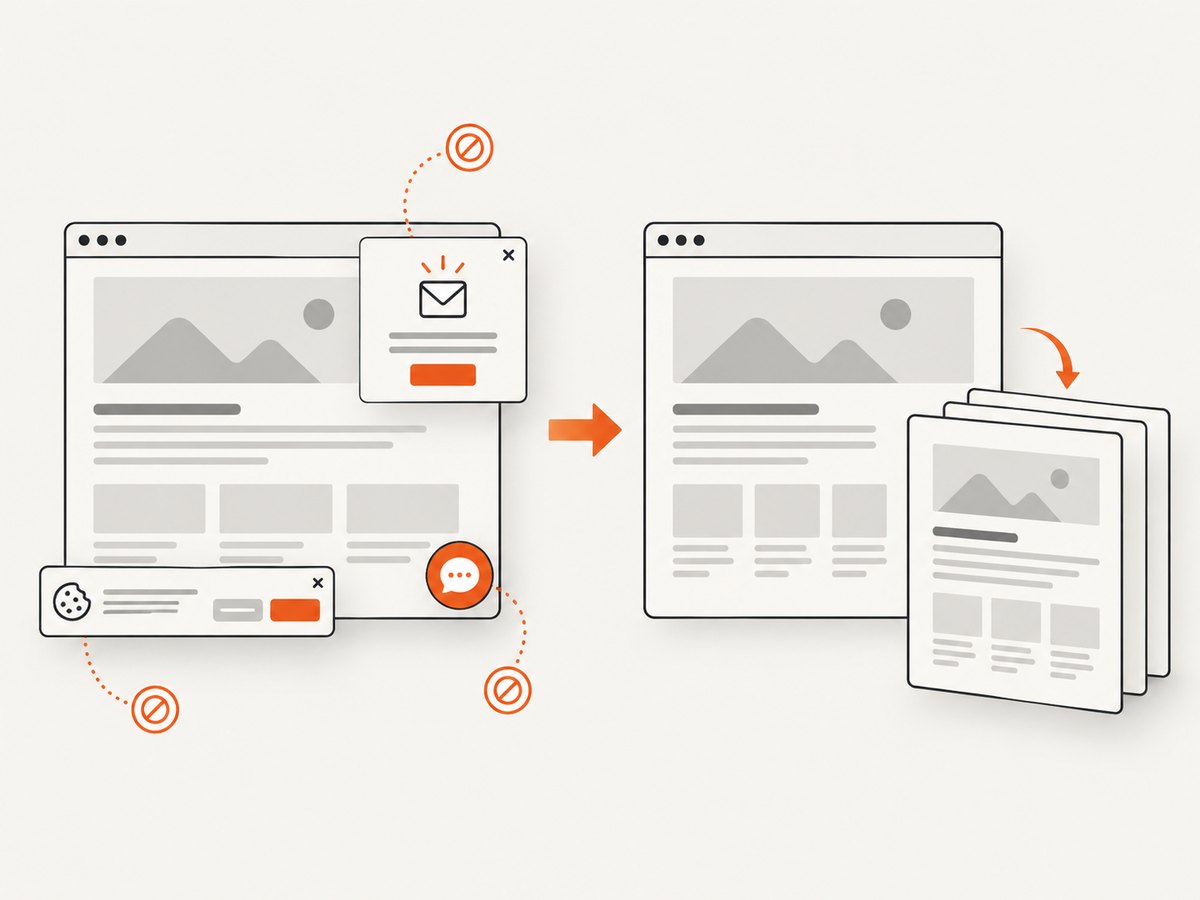
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Before capture, cookie and consent banners are accepted and more than 60 known consent platforms, newsletter popups and chat widgets can be removed; each step can be disabled. Bot checks and CAPTCHAs, blank pages, timeouts, failed loads and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. The service also offers an MCP server with take_screenshot, get_page_info and capture_pdf for Claude, Cursor and other MCP clients. The Free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
Reliability, performance and cost considerations
- PDFKit: stream output to avoid holding the entire document in memory. Reuse loaded font data and scale images before embedding. Handle the stream’s
errorandfinishevents. - pdf-lib:
save()returns a byte array, so memory use grows with the output document. For large files, process one job at a time, avoid unnecessary copies and place limits on upload size. - Puppeteer: each browser process consumes substantially more resources than direct PDF libraries because it runs Chromium. Reuse a browser across jobs, create isolated pages, set navigation timeouts and always close pages and the browser on failure.
- Fonts and assets: missing fonts change line breaks; remote assets can delay or break output. Bundle critical assets or verify them before finalizing.
- Concurrency: queue jobs, cap parallel browser pages and observe CPU, memory, file descriptors and output size. The official sources do not establish a cross-library benchmark, so benchmark your own templates and workload.
- Security: sanitize user supplied HTML, restrict navigation targets in browser jobs and avoid embedding secrets in generated documents or URLs.
Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| Empty or truncated PDFKit file | end() was never called, or the process exited before the stream finished |
Call doc.end() and await the output stream’s finish event. |
| Text overlaps or runs off the page | Coordinates, margins or font metrics were not accounted for | Measure text, wrap deliberately and add page-break logic before the bottom margin. |
| Custom font fails in pdf-lib | Fontkit was not registered or the bytes are invalid | Install @pdf-lib/fontkit, call registerFontkit and pass valid font bytes. |
| Existing PDF cannot be loaded | Corrupt, encrypted or unsupported input | Validate the upload, catch the load error and require a readable, unencrypted file when appropriate. |
| Puppeteer PDF misses images | Images were still loading when printing started | Wait for navigation and image completion, then call page.pdf(). |
| Styles look different in Puppeteer | Screen CSS is being used instead of print CSS | Define @media print and @page; use printBackground: true for colored backgrounds. |
| Chromium does not launch | Browser binary, sandbox or container dependency issue | Install Puppeteer’s browser, check container dependencies and configure the sandbox only according to your deployment security policy. |
| Slow jobs or memory spikes | Too many concurrent browsers/pages or oversized images | Reuse browsers, cap concurrency, resize assets and monitor resource limits. |
Testing and deployment checklist
- Render representative short and long documents.
- Verify page size, margins, orientation, fonts, links, images and page breaks.
- Test missing assets, malformed PDFs, slow URLs and cancellation paths.
- Run the same job in the production container or serverless runtime.
- Record output byte size, duration, memory and error rate for your workload.
- Return
application/pdfand a download-safe filename from HTTP endpoints. - Keep credentials, font files and browser binaries outside user-controlled paths.
FAQ
How do I generate a PDF in Node.js?
Install PDFKit for direct drawing, pdf-lib for PDF structure editing, or Puppeteer for printing HTML/CSS. The examples above are complete starting points.
Which library edits an existing PDF?
pdf-lib is the documented choice among these options for loading a PDF, changing pages or drawing additional content, then saving it.
Can I use these libraries in TypeScript?
Yes. pdf-lib is written in TypeScript, and PDFKit and Puppeteer can be used from TypeScript with the appropriate package types.
Should I use a browser for invoices?
Use Puppeteer when your invoice is already an HTML template. Use PDFKit or pdf-lib when you need deterministic drawing or PDF editing without Chromium.
Where can an AI agent generate a PDF from a web page?
ScreenshotNeo’s MCP server exposes a capture_pdf tool for MCP clients such as Claude and Cursor, alongside its HTTP API.