How to Open Multiple Pages in One PhantomJS Script
Open URLs sequentially in PhantomJS by starting the next page.open call inside the previous callback, then exit only after all page work is complete.
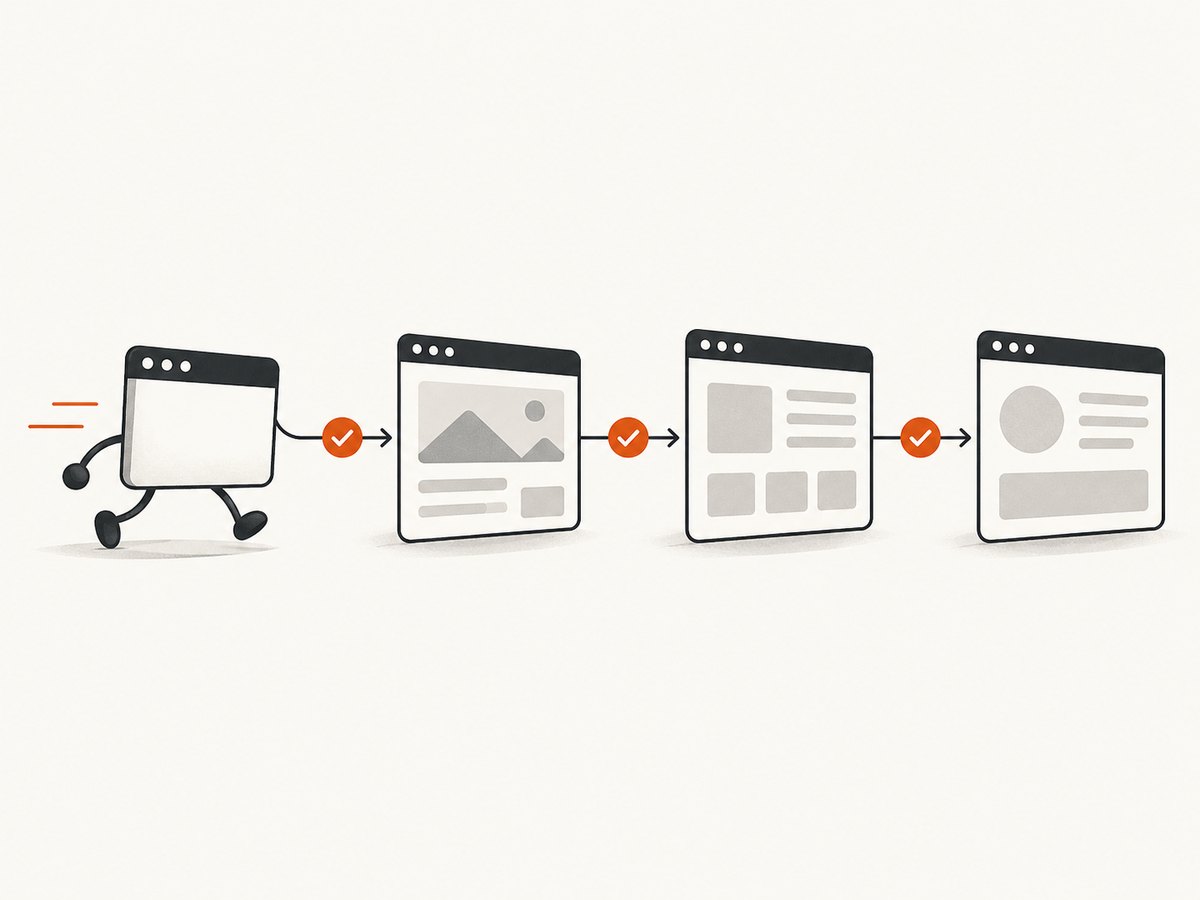
Direct answer: page.open is asynchronous. To open multiple URLs in order with one PhantomJS page object, call the next page.open from the current call’s completion callback. Check its success or fail status, finish that page’s work, and call phantom.exit() after the final callback. The callback and status behavior are documented in the PhantomJS WebPage open API; its Quick Start explains that the process must be explicitly terminated.
1. Sequentially open several URLs with one page object
Save this as multi.js and run it with phantomjs multi.js. The script opens each URL in order, reads its title after a successful load, records failures, and continues to the next URL. It exits with a nonzero status if any URL failed.
var webpage = require('webpage');
var page = webpage.create();
var urls = [
  'https://example.com/one',
  'https://example.com/two',
  'https://example.com/three'
];
var index = 0;
var failures = 0;

function openNext() {
  if (index >= urls.length) {
    console.log('Finished ' + urls.length + ' pages; failures: ' + failures);
    phantom.exit(failures === 0 ? 0 : 1);
    return;
  }

  var url = urls[index++];
  console.log('Opening ' + url);

  page.open(url, function (status) {
    if (status === 'success') {
      var result = page.evaluate(function () {
        return {
          title: document.title,
          url: window.location.href
        };
      });
      console.log('Loaded: ' + result.title + ' (' + result.url + ')');
      // Render or process this page here, before openNext().
    } else {
      failures++;
      console.log('Failed to load: ' + url);
    }

    openNext();
  });
}

openNext();
The example’s callback chain follows the API’s asynchronous lifecycle. It is a documented-pattern example, not a claim that the code was run against a particular PhantomJS installation. Confirm compatibility with the version available in your environment; PhantomJS development is suspended, as its project site states.
Why the callback controls the sequence
Calling page.open(url, callback) starts navigation and returns before the page is ready. The callback runs when loading completes and receives success or fail. If the script calls page.open repeatedly in a normal loop, later navigations can begin before earlier callbacks have finished. With a single page object, the later navigation can replace the page state the earlier work expected to inspect.
In the example, openNext() advances only after status checking and page-specific work. This gives a simple invariant: there is at most one active navigation on that page object, and each page is handled before the next one starts. The index is incremented before opening so the next callback knows which URL follows, while the end condition ensures the final page leads to process termination.
2. Extract data or render each page before advancing
Put all work that depends on the current document inside the callback and before the call to openNext(). For example, this variation stores titles and writes a JSON report after all URLs have been processed.
var webpage = require('webpage');
var fs = require('fs');
var page = webpage.create();
var urls = ['https://example.com/', 'https://example.org/'];
var index = 0;
var results = [];

function done() {
  fs.write('results.json', JSON.stringify(results, null, 2), 'w');
  phantom.exit();
}

function openNext() {
  if (index === urls.length) {
    done();
    return;
  }

  var url = urls[index++];
  page.open(url, function (status) {
    if (status === 'success') {
      var title = page.evaluate(function () { return document.title; });
      results.push({ url: url, status: status, title: title });
      // Optional: page.render('page-' + (index - 1) + '.png');
    } else {
      results.push({ url: url, status: status, title: null });
    }
    openNext();
  });
}

openNext();
Use a filename derived from a safe index or sanitized identifier if rendering files. Do not use a raw URL as a path: URLs contain slashes, query strings, and characters that may not be valid or safe in filenames. Decide whether a failed page should be skipped, retried, or make the whole run fail. The code above records it and carries on; the first example returns a failure exit code if any failed.
Use page.evaluate at the page boundary
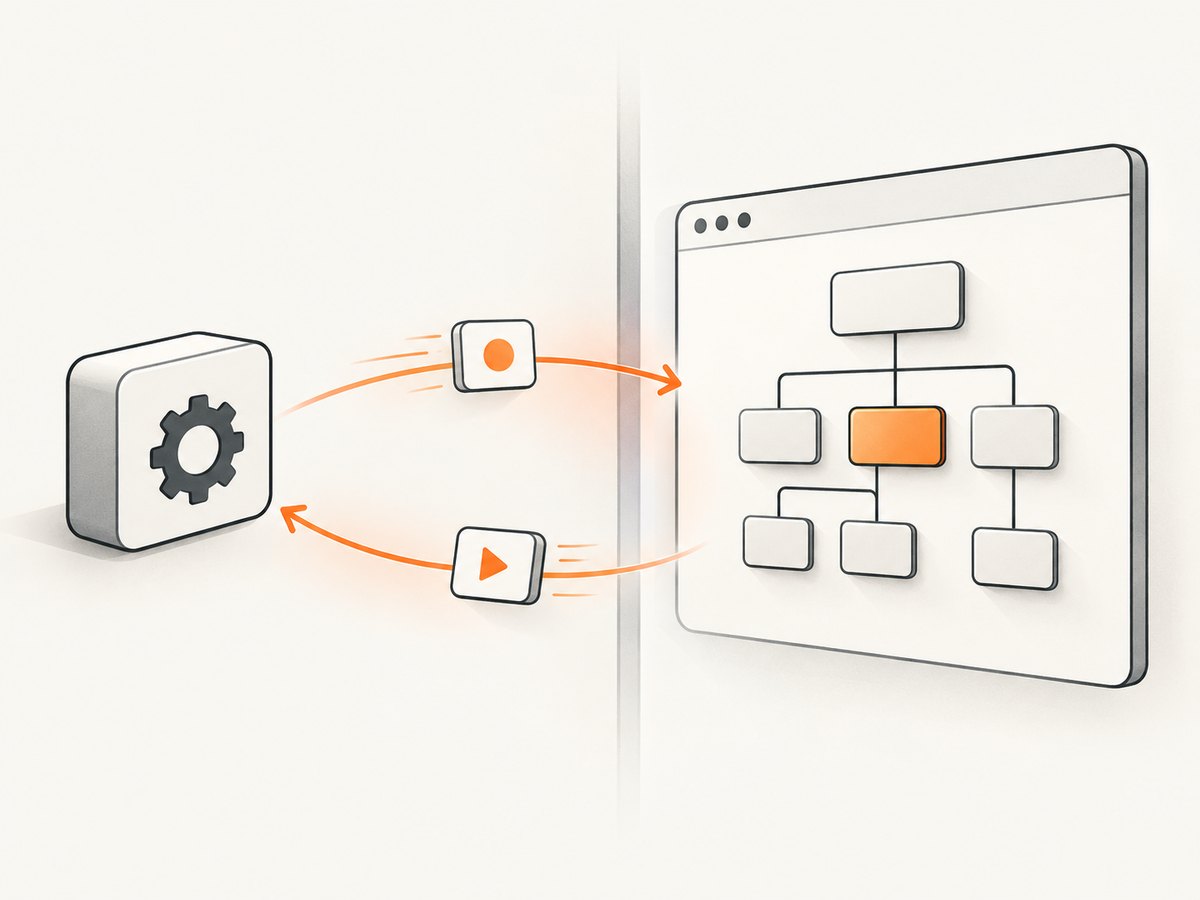
page.evaluate runs code in the loaded page’s context, where DOM APIs such as document.title are available. The PhantomJS documentation says values passed into and returned from this context must be simple serializable values; closures, functions, and DOM nodes do not cross the boundary. Keep orchestration, the URL array, counters, and PhantomJS objects in the outer script. Return strings, numbers, booleans, arrays, or plain data objects from the page context. See the official evaluate API.
For example, pass a selector as a serializable argument rather than expecting the page function to see a variable from the outer scope:
var selector = 'h1';
var heading = page.evaluate(function (s) {
  var node = document.querySelector(s);
  return node ? node.textContent : null;
}, selector);
A page’s own console.log output is not forwarded to the PhantomJS script by default. If page-side logging is useful, set page.onConsoleMessage in the outer script and log the received message there.
3. Choose sequential reuse or separate page objects
| Approach | Use it when | Tradeoff |
|---|---|---|
| One page object, callback chain | Order matters, later steps depend on earlier results, or simplicity is the priority. | Only one page is being navigated at a time; each page’s work finishes before the next navigation. |
| Multiple page objects | Pages need separate state, or you want to explore overlapping loads. | You must track each page and its callback, handle completion exactly once, and exit only when the intended work is finished. The gathered official docs do not specify a universal safe concurrency limit. |
For independent pages, create distinct objects with require('webpage').create(); do not try to run overlapping page.open calls on the same object and treat them as independent pages. A small multi-object pattern can count completions:
var webpage = require('webpage');
var urls = ['https://example.com/', 'https://example.org/'];
var remaining = urls.length;
var failed = 0;

function finished(status, url) {
  console.log(status + ': ' + url);
  if (status !== 'success') failed++;
  remaining--;
  if (remaining === 0) phantom.exit(failed === 0 ? 0 : 1);
}

urls.forEach(function (url) {
  var page = webpage.create();
  page.open(url, function (status) {
    if (status === 'success') {
      console.log('Title: ' + page.evaluate(function () {
        return document.title;
      }));
    }
    finished(status, url);
  });
});
This demonstrates independent page state and completion accounting; it does not establish how many simultaneous pages a particular machine or PhantomJS build can handle. Start with a small batch and observe memory, CPU, network behavior, and failures in your actual environment. Use sequential reuse if concurrency is not needed.
4. Handle timing, failures, and process lifecycle
Load completion is not always application readiness
The page.open callback indicates load completion according to PhantomJS’s API. A site may still update content after that event through timers or client-side requests. If you need a specific element or value, check for that condition before extracting it. A short fixed delay may help for a known page, but it adds latency and can still be too short or unnecessarily long. For robust workflows, wait for the actual condition with a bounded timeout and record a distinct timeout outcome. Avoid an unbounded wait that can leave the entire batch stuck.
Retry deliberately
A fail status can be logged, skipped, retried, or treated as fatal depending on the task. For a retry, keep an attempt count per URL and schedule the retry only after the failed callback; cap attempts so one unreachable page cannot loop forever. Add a delay between retries if repeated requests could overload a target or hit a rate limit. The dossier’s documented API reports only success or fail; do not interpret that callback as a complete diagnosis of HTTP status, bot checks, or why the load failed.
Exit only when all work is done
An unconditional phantom.exit() immediately after starting page loads can terminate the process before callbacks execute. Put exit logic at the chain’s terminal condition, or in a completion counter when using multiple page objects. If you need to signal failure to a shell or scheduler, pass a nonzero return value such as phantom.exit(1). The Quick Start explicitly notes that PhantomJS will not terminate on its own without an exit call.
5. Troubleshooting common problems
| Symptom | Likely cause | Fix |
|---|---|---|
| Only the first page is processed. | The next navigation is never started, or the script exits from the first callback. | Call openNext() after handling both success and failure, and exit only at the terminal condition. |
| Callbacks report unexpected pages or results. | Multiple opens overlap on one page object, or processing happens after a later navigation. | Use the sequential callback chain for one object. Use distinct page objects for independent state. |
| The process never exits. | A code path misses the final exit, or a callback never completes. | Ensure every completion path advances the chain or decrements the counter. Add bounded timeouts for application-level waits and always terminate at completion. |
| The script exits before work finishes. | phantom.exit() runs immediately after asynchronous opens are started. |
Move exit into the final callback or all-pages completion handler. |
| DOM values are undefined or evaluate fails. | The code runs before the needed page is loaded, or page-context code depends on an outer closure or returns a DOM node. | Evaluate after successful load, pass serializable arguments explicitly, and return simple serializable data. |
| No page console messages appear. | Page-context console messages are not displayed by default. | Assign page.onConsoleMessage and forward its message to the outer script’s console. |
A page reports fail. |
The load did not complete successfully; the callback status alone does not explain why. | Log the URL and status, decide whether to skip or retry, and investigate the URL and runtime separately. |
6. Performance, reliability, and cost considerations
Sequential loading is easy to reason about, but total run time grows with the time spent on each navigation plus any page-specific wait or processing. Reuse one page object when preserving a strict order matters and the workload is modest. Separate objects can allow independent work to overlap, but they also introduce completion tracking and may increase resource pressure. The official material gathered here gives no benchmark, quantified memory cost, or universal concurrency recommendation, so do not assume a speedup or a safe page count.
For a long list, log progress as each URL starts and completes, save intermediate results when losing the whole run would be costly, and make failures visible in the final exit status or report. Keep retries bounded. If the script runs under a scheduler, ensure its outer timeout is longer than the expected batch duration while still having a mechanism to stop a stuck workflow. PhantomJS is a legacy runtime with suspended development; verify that its binary and behavior remain suitable for your environment before relying on it for a new production dependency.
7. Or skip the browser setup
If your actual goal is to capture pages as images or PDFs rather than run custom page automation, ScreenshotNeo provides a website screenshot API and MCP server. One GET request captures a URL. Its clean-shot flow accepts cookie or consent banners like a visitor and removes 60+ known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and responses identify the page verdict and billing status in headers. Its MCP server offers take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. There are 1,000 free shots per month with no card; paid plans start at $5 for 3,000.
See the ScreenshotNeo API documentation for parameters and configuration. cURL example:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
Cookie banners, popups, and chat widgets are removed before the shot; bot checks, blank pages, and failed loads are never billed; an MCP server lets AI agents take screenshots; and 1,000 screenshots a month are free with no card, with paid plans starting at $5 for 3,000. Sign up for the free plan.
8. Frequently asked questions
Can I call page.open from a loop?
A loop can start calls, but it does not wait for asynchronous callbacks. For ordered navigation on one object, put the next call in the previous callback.
Does success guarantee every dynamic widget has finished?
No. It is the page-load callback status. If later content matters, wait for that content with a bounded condition.
Can I use one page object for unrelated URLs?
Yes, sequentially. Complete extraction, rendering, and any other page-specific work before opening the next URL.
Should every failed URL stop the batch?
That depends on whether the batch is best-effort or all-or-nothing. Make the choice explicit in the report and process exit code.


