How to Parse HTML in Python
Learn when to use html.parser or Beautiful Soup, choose a backend, handle malformed markup, and extract data with runnable Python code.
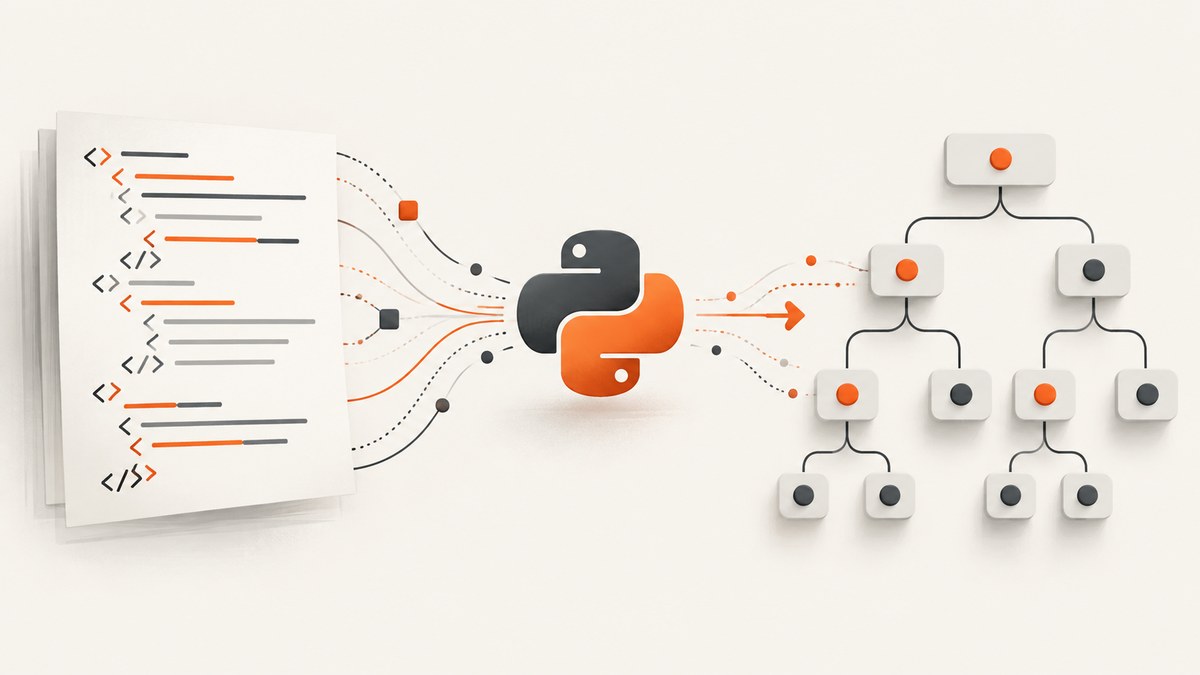
Parsing HTML in Python means turning markup into data you can search, inspect, or transform. For a standard-library solution, subclass html.parser.HTMLParser and collect values in handler methods. For a navigable document tree, use Beautiful Soup and select an explicit parser backend.
Use html.parser when you want no third-party dependency and event-driven processing. Use Beautiful Soup when you need convenient selectors, parent and sibling navigation, or edits to a parsed tree. Beautiful Soup can use Python’s built-in parser, lxml, or html5lib; malformed input can produce different trees, so name the backend in reproducible code. See the Python markup-processing overview, the HTMLParser documentation, and the Beautiful Soup documentation.
1. Choose the right parser
| Choice | Best fit | Tradeoff |
|---|---|---|
html.parser |
Small scripts, standard-library deployments, streaming handlers | Event-oriented API; it does not validate matching start and end tags |
Beautiful Soup + html.parser |
Tree navigation without an external parser dependency | Usually less forgiving and slower than lxml |
Beautiful Soup + lxml |
Tree queries where speed matters | Requires an external C dependency |
Beautiful Soup + html5lib |
Browser-like recovery of very imperfect HTML | Very lenient and very slow; requires an external Python package |
Beautiful Soup converts input to Unicode and exposes a higher-level tree API. Its backend choice is consequential for invalid markup: the same source can produce different parent-child relationships under different parsers. Pin your dependency versions and pass the parser name explicitly.
2. Parse HTML with Python’s standard library
HTMLParser receives text through feed() and calls methods such as handle_starttag, handle_endtag, and handle_data. This is useful when you need a small, predictable collector rather than a full tree.

from html.parser import HTMLParser
class LinkParser(HTMLParser):
def __init__(self):
super().__init__(convert_charrefs=True)
self.links = []
self._current_href = None
self._current_text = []
def handle_starttag(self, tag, attrs):
if tag == 'a':
attributes = dict(attrs)
self._current_href = attributes.get('href')
self._current_text = []
def handle_data(self, data):
if self._current_href is not None:
self._current_text.append(data)
def handle_endtag(self, tag):
if tag == 'a' and self._current_href is not None:
text = ' '.join(''.join(self._current_text).split())
self.links.append({'href': self._current_href, 'text': text})
self._current_href = None
self._current_text = []
html = ''' Documentation Example '''
parser = LinkParser()
parser.feed(html)
parser.close()
print(parser.links)The parser converts character references by default in normal text, so an entity such as & becomes &. Script and style content has special handling. Call close() after the final chunk, especially when feeding data incrementally.
Collect headings and visible text
from html.parser import HTMLParser

class HeadingParser(HTMLParser):
    def __init__(self):
        super().__init__(convert_charrefs=True)
        self.headings = []
        self._level = None
        self._text = []

    def handle_starttag(self, tag, attrs):
        if tag in {'h1', 'h2', 'h3', 'h4', 'h5', 'h6'}:
            self._level = int(tag[1])
            self._text = []

    def handle_data(self, data):
        if self._level is not None:
            self._text.append(data)

    def handle_endtag(self, tag):
        if self._level is not None and tag == f'h{self._level}':
            text = ' '.join(''.join(self._text).split())
            self.headings.append((self._level, text))
            self._level = None
            self._text = []

with open('page.html', encoding='utf-8') as file:
    parser = HeadingParser()
    parser.feed(file.read())
    parser.close()

for level, text in parser.headings:
    print(level, text)
HTMLParser is not a strict nesting validator. It does not check that an end tag matches the most recent start tag, and it may omit an end-tag callback when an element is implicitly closed by an outer element. If your extraction depends on a corrected browser-style tree, use a tree parser instead.
3. Parse and query a tree with Beautiful Soup
Install Beautiful Soup and select the backend explicitly. The built-in backend keeps deployment simple:
python -m pip install beautifulsoup4from bs4 import BeautifulSoup
html = '''
Release notes
First release
Second release
'''
soup = BeautifulSoup(html, 'html.parser')
print(soup.title) # None: no title element exists
print(soup.h1.get_text(' ', strip=True))
for link in soup.select('a.entry'):
print(link.get_text(' ', strip=True), link.get('href'))For speed-oriented workloads, install lxml and request it directly:
python -m pip install beautifulsoup4 lxmlfrom bs4 import BeautifulSoup
with open('page.html', encoding='utf-8') as file:
soup = BeautifulSoup(file, 'lxml')
for image in soup.select('img[src]'):
print(image['src'], image.get('alt', ''))For browser-like HTML5 recovery, install html5lib and pass 'html5lib'. Its lenient recovery is useful for badly formed pages, but the Beautiful Soup documentation describes it as very slow.
4. Extract safely and handle edge cases
Missing attributes and optional nodes
Use tag.get('attribute') for optional attributes. Indexing, such as tag['href'], raises KeyError when the attribute is absent. Likewise, soup.find('title') can return None, so check before calling .get_text().
Whitespace, nested elements, and comments
get_text(' ', strip=True) joins text from nested elements while normalizing surrounding whitespace. If you need to preserve formatting, iterate over descendants instead of collapsing the text. Comments are available as special strings in Beautiful Soup:
from bs4 import BeautifulSoup, Comment

soup = BeautifulSoup('<p>Visible</p><!-- internal note -->', 'html.parser')
comments = [node for node in soup.find_all(string=True) if isinstance(node, Comment)]
print(comments)
Relative URLs
Parsing extracts the URL text; it does not resolve it. To create absolute links after parsing, use Python’s URL utilities and the page’s known base URL:
from urllib.parse import urljoin

base = 'https://example.com/docs/index.html'
absolute = urljoin(base, '../guide.html')
print(absolute)
Encoding and malformed input
Give Beautiful Soup decoded text or an open file with a known encoding when possible. If you pass bytes, it will attempt to detect an encoding, but a wrong server declaration can still produce incorrect characters. Keep the original response bytes when debugging. Parser recovery is not validation: sanitize or reject untrusted input according to your application’s security requirements before rendering it.
5. Fetching HTML and JavaScript-rendered pages
Parsing begins after HTML has been obtained. The parser documentation does not define HTTP retries, response validation, character-set detection, or JavaScript execution. Treat fetching as a separate step: check the HTTP status, preserve the response encoding, enforce timeouts, and only then pass the resulting text to your parser. A page that fills its content in the browser after JavaScript runs will not yield those nodes from the original HTML response. Use a browser capture workflow when you need the rendered page.
6. Or skip the browser setup
ScreenshotNeo provides a website screenshot API and MCP server. It accepts one GET request and returns PNG, JPEG, WebP, or PDF. You can still parse HTML yourself when you need structured fields; use ScreenshotNeo when the goal is a faithful rendered capture.
See the ScreenshotNeo API documentation for all options. A basic request:
curl -G 'https://api.screenshotneo.com/v1/shot' -d access_key=YOUR_API_KEY --data-urlencode 'url=https://stripe.com' -o shot.webpimport requests
r = requests.get('https://api.screenshotneo.com/v1/shot', params={'access_key': 'YOUR_API_KEY', 'url': 'https://stripe.com'}, timeout=90)
r.raise_for_status()
open('shot.webp', 'wb').write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('shot.webp', buffer);ScreenshotNeo supports full-page capture with lazy images loaded, CSS-selector element capture, dark mode, 12 device presets, custom viewports, retina scale, PDF paper sizes and page ranges, custom CSS and JavaScript, clicks, selector or network-idle waits, blocked ads and resource types, custom headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, caching with a chosen TTL, signed links, asynchronous jobs with signed webhooks, bulk capture for 100 URLs per call, a usage API, and an OpenAPI specification. Parameter names used by other screenshot APIs also work, which can simplify migration.
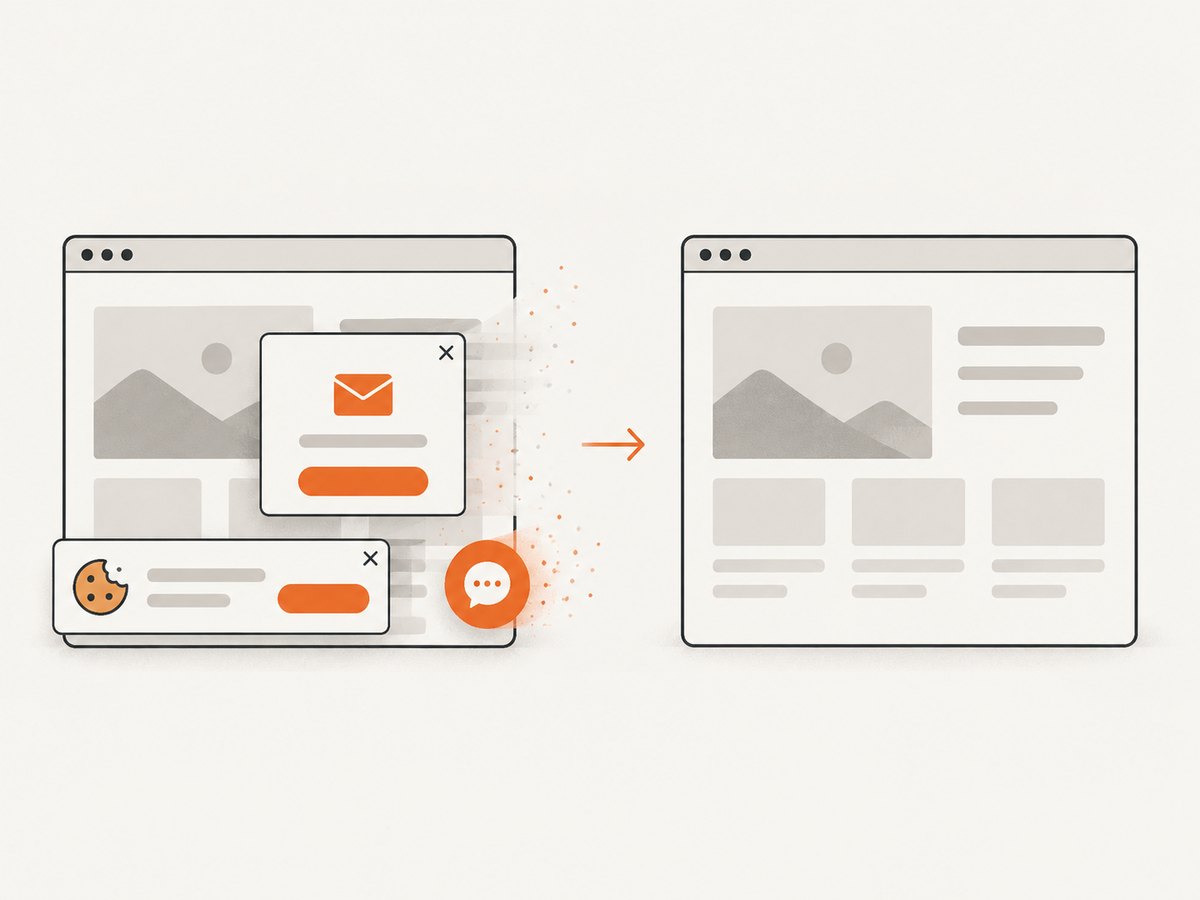
Before capture, it accepts consent banners like a visitor and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be disabled. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing. Response headers identify the page verdict and whether the request was billed with X-Page-Verdict and X-Billed. Its MCP server exposes take_screenshot, get_page_info, and capture_pdf to Claude, Cursor, and other MCP clients.
The Free plan includes 1,000 shots per month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is available on every plan. Create a free ScreenshotNeo account and start with the included 1,000 screenshots.
7. Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
ModuleNotFoundError: bs4 |
Beautiful Soup is not installed in the active environment | Run python -m pip install beautifulsoup4 using the same interpreter that runs the script |
| Different elements appear under different machines | Implicit or different parser backend | Pass 'html.parser', 'lxml', or 'html5lib' explicitly and pin dependencies |
AttributeError: 'NoneType' object |
A selector found no match | Check the input HTML, test the selector, and guard the result before reading text |
| Text is empty | Content is inside a script-rendered application or the selector targets a container with no text | Inspect the original HTML; obtain rendered HTML with a browser workflow, then parse that output |
| Unclosed or rearranged tags | Malformed source and backend recovery rules | Compare explicit backends; choose html5lib for browser-like recovery or fix the source upstream |
| Screenshot contains a popup | The overlay loaded before capture or the relevant cleanup step was disabled | Enable consent and widget cleanup, add a wait, or hide the selector in ScreenshotNeo |
| Screenshot response is not an image | Authentication, URL, or page-load failure | Check the HTTP status and response headers, verify the access key, and inspect X-Page-Verdict |
8. Performance, reliability, and cost
For small documents, handler-based HTMLParser avoids building a tree and can process chunks as they arrive. Tree parsers use more memory because they retain nodes, but they reduce application code for selectors and relationships. Benchmark your real documents; the documentation provides qualitative tradeoffs rather than universal speed numbers.
For repeatable extraction, pin the parser backend and package versions, write fixtures containing malformed cases, and assert the fields you require. Separate network retries from parsing retries: retrying a deterministic parse will not repair bad markup. Keep timeouts and maximum input sizes at the fetch boundary.
For ScreenshotNeo, caching with a TTL can reduce repeated captures. Bulk capture handles up to 100 URLs per call, while asynchronous jobs and signed webhooks keep long captures out of request timeouts. Failed loads and cache hits are not billed, and the X-Billed header lets usage accounting distinguish clean captures from non-billed outcomes.
9. FAQ
Is html.parser a validator?
No. It reports markup events and tolerates invalid input; it does not verify matching nesting.
Which Beautiful Soup backend should I use?
Start with html.parser for zero external parser dependencies, choose lxml when speed and its dependency are acceptable, and choose html5lib when browser-like recovery matters more than speed.
Can Beautiful Soup execute JavaScript?
No. It parses supplied markup. Obtain rendered HTML with a browser-capable workflow first if the content is created by JavaScript.
When should I parse instead of taking a screenshot?
Parse when you need structured values such as links, headings, or attributes. Capture when you need the visual result, a PDF, or a page after browser interactions and cleanup.


