How to Parse XML in JavaScript: A Step-by-Step Guide
Parse XML safely in JavaScript with DOMParser, fetch, namespaces, Node.js libraries, validation, troubleshooting, and complete runnable examples.
To parse XML in a browser, pass the XML string to DOMParser.parseFromString() with an XML MIME type such as application/xml, then check for a parsererror element before reading the returned Document. In Node.js, use a package such as @xmldom/xmldom for a DOM-like API or @rgrove/parse-xml for an object-tree result.
This guide shows how to parse XML text, fetch and parse a remote document, handle namespaces and attributes, detect malformed input, validate application rules, choose a Node.js library, and avoid common security mistakes.
1. Parse XML in a browser with DOMParser
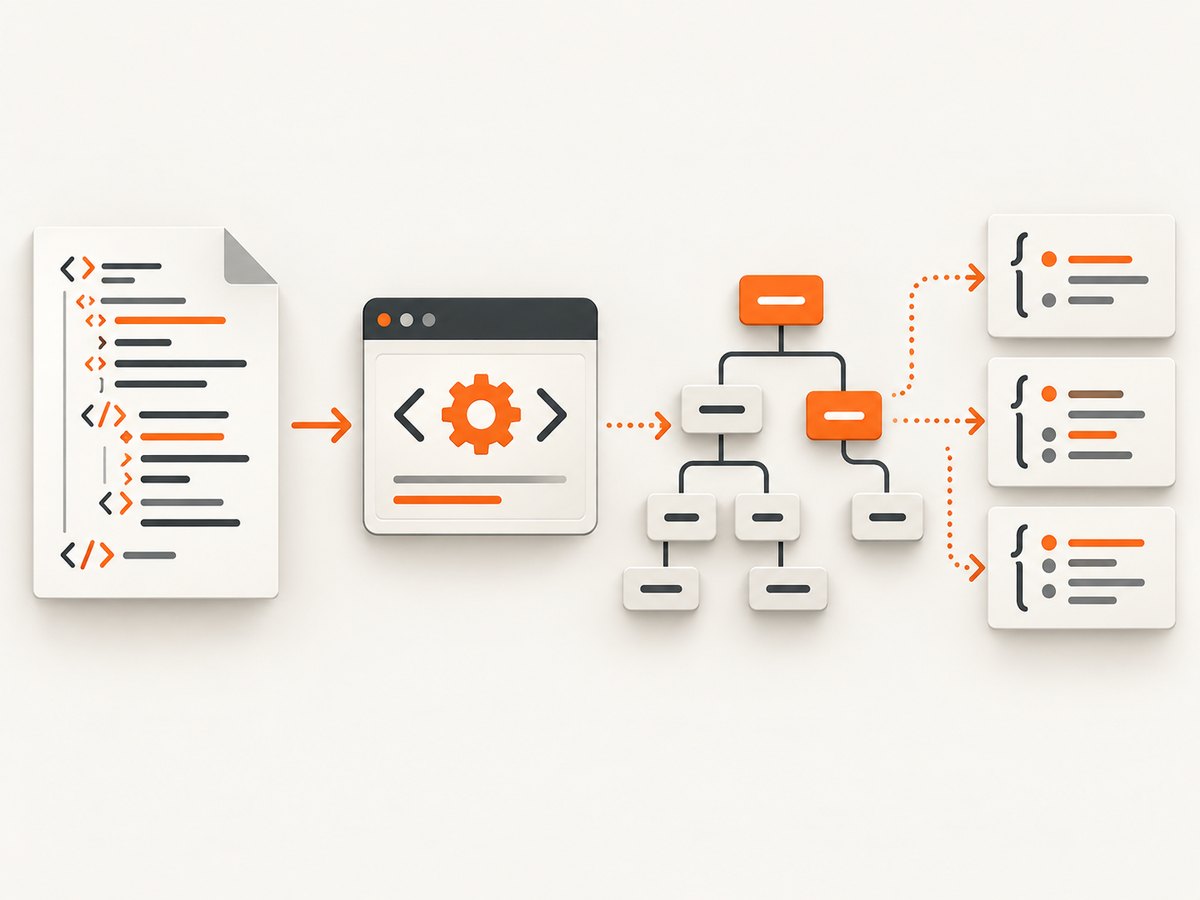
The browser-native approach is available without a dependency. DOMParser converts a string into an in-memory DOM Document. Use an XML MIME type; text/html applies HTML parsing rules and can produce a different tree.
const xmlText = `<catalog>
  <book id="b1">XML basics</book>
</catalog>`;

const parser = new DOMParser();
const doc = parser.parseFromString(xmlText, "application/xml");

const errorNode = doc.querySelector("parsererror");
if (errorNode) {
  throw new Error("The XML is not well formed");
}

const book = doc.querySelector("book");
if (!book) {
  throw new Error("Expected a book element");
}

console.log(book.getAttribute("id"));
console.log(book.textContent.trim());
An ill-formed input normally returns a document containing parsererror instead of throwing a JavaScript exception. Check for that node immediately. Error markup and human-readable messages vary by browser, so application logic should only depend on the presence of a parse error, not on the exact message. See MDN’s DOMParser reference and the W3C DOM Parsing specification.
Accepted MIME types
| MIME type | Typical use |
|---|---|
application/xml |
General XML (the usual choice) |
text/xml |
XML documents from older integrations |
application/xhtml+xml |
XHTML documents |
image/svg+xml |
SVG XML |
text/html |
HTML parsing rules, not strict XML parsing |
2. Read elements, attributes, and repeated values
Start at doc.documentElement when you need to inspect the root. Use CSS selectors for simple, unqualified XML, querySelectorAll() for repeated elements, and getAttribute() for attributes. textContent returns descendant text, so trim it when whitespace formatting is not meaningful.
const xml = `<orders>
  <order id="1001" status="paid">
    <customer>Ada Lovelace</customer>
    <total currency="USD">49.50</total>
    <item sku="book-1">XML Handbook</item>
    <item sku="book-2">DOM Parsing</item>
  </order>
</orders>`;

const doc = new DOMParser().parseFromString(xml, "application/xml");
if (doc.querySelector("parsererror")) throw new Error("Malformed XML");

const order = doc.querySelector("order");
const result = {
  id: order?.getAttribute("id"),
  status: order?.getAttribute("status"),
  customer: order?.querySelector("customer")?.textContent.trim(),
  total: Number(order?.querySelector("total")?.textContent),
  currency: order?.querySelector("total")?.getAttribute("currency"),
  items: [...order?.querySelectorAll("item") ?? []].map((item) => ({
    sku: item.getAttribute("sku"),
    name: item.textContent.trim()
  }))
};

console.log(result);
Do not assume an element exists. Optional chaining prevents a missing node from becoming a confusing null-reference error, while explicit checks let you report a useful schema problem.
3. Fetch XML and then parse the response body
Network retrieval and XML parsing are separate operations. First check the HTTP response, then read the body as text, and only then parse it. A successful HTTP status does not guarantee well-formed XML.
async function fetchXml(url) {
  const response = await fetch(url, {
    headers: { Accept: "application/xml, text/xml;q=0.9" }
  });

  if (!response.ok) {
    throw new Error(`HTTP ${response.status} while fetching XML`);
  }

  const xmlText = await response.text();
  const doc = new DOMParser().parseFromString(xmlText, "application/xml");
  const parseError = doc.querySelector("parsererror");

  if (parseError) {
    throw new Error("The response was not well-formed XML");
  }

  return doc;
}

const doc = await fetchXml("https://example.com/feed.xml");
const titles = [...doc.querySelectorAll("item > title")]
  .map((node) => node.textContent.trim());
console.log(titles);
In browser applications, cross-origin requests also need the server’s CORS policy to allow your origin. A CORS failure happens before parsing and cannot be fixed by changing DOMParser code. For large responses, consider streaming or a server-side parser rather than loading the entire string into memory.
4. Handle XML namespaces correctly
Namespace-qualified names are not always matched by an unqualified CSS selector. For reliable namespace handling, use getElementsByTagNameNS() or lookupNamespaceURI() with the namespace URI.
const xml = `<feed xmlns="urn:example:feed">
  <entry id="a1"><title>Namespaced XML</title></entry>
</feed>`;

const doc = new DOMParser().parseFromString(xml, "application/xml");
if (doc.querySelector("parsererror")) throw new Error("Malformed XML");

const namespace = "urn:example:feed";
const entries = [...doc.getElementsByTagNameNS(namespace, "entry")];
for (const entry of entries) {
  const title = entry.getElementsByTagNameNS(namespace, "title")[0];
  console.log(entry.getAttribute("id"), title?.textContent.trim());
}
Prefixes are aliases, not the identity of a namespace. Two documents can use different prefixes for the same URI, so match the namespace URI when the vocabulary matters.
5. Parse XML in Node.js
DOMParser is a browser Web API. Node.js projects commonly install a parser package. Choose based on output shape, namespace and DTD requirements, diagnostics, supported runtimes, maintenance, and security behavior.
DOM-style parsing with @xmldom/xmldom
npm install @xmldom/xmldomimport { DOMParser } from "@xmldom/xmldom";
const xml = `<catalog><book id="b1">XML basics</book></catalog>`;
const parser = new DOMParser({
errorHandler: {
warning: (message) => console.warn(message),
error: (message) => console.error(message),
fatalError: (message) => console.error(message)
}
});
const doc = parser.parseFromString(xml, "application/xml");
const book = doc.getElementsByTagName("book")[0];
if (!book) throw new Error("Missing book element");
console.log(book.getAttribute("id"));
console.log(book.textContent.trim());The project supplies a DOM-like DOMParser and XMLSerializer, but its documentation notes that the implementation is not fully feature-complete and can differ from standards behavior. Review its current documentation and test the XML features your application needs.
Object-tree parsing with @rgrove/parse-xml
npm install @rgrove/parse-xmlimport { parseXml } from "@rgrove/parse-xml";
const xml = `<catalog>
<book id="b1">XML basics</book>
</catalog>`;
const tree = parseXml(xml);
console.log(tree.children[0].name);
console.log(tree.children[0].attributes.id);
console.log(tree.children[0].children[0].text);
@rgrove/parse-xml returns an object-tree representation and documents that it does not load external DTDs, validate against DTDs, or resolve custom DTD entity references. That behavior may be desirable, but confirm it matches your input format before selecting the package.
6. Serialize a parsed document
Use XMLSerializer when you need XML text again, for example after changing an attribute or adding a node.
const xml = "<note><to>Sam</to></note>";
const doc = new DOMParser().parseFromString(xml, "application/xml");
if (doc.querySelector("parsererror")) throw new Error("Malformed XML");

doc.querySelector("to").textContent = "Taylor";
const output = new XMLSerializer().serializeToString(doc);
console.log(output);
Serialization creates text; it does not validate business rules or make content safe to inject into a visible page.
7. Validate structure and treat parsed data as untrusted
Well-formedness only means the XML syntax is valid. It does not prove that required elements exist, values have the right format, or the document matches your application’s schema.
function requireText(parent, selector) {
  const node = parent.querySelector(selector);
  const value = node?.textContent.trim();
  if (!value) throw new Error(`Missing required value: ${selector}`);
  return value;
}

function parseUser(xmlText) {
  const doc = new DOMParser().parseFromString(xmlText, "application/xml");
  if (doc.querySelector("parsererror")) throw new Error("Malformed XML");

  const user = doc.querySelector("user");
  if (!user) throw new Error("Missing user element");

  const id = user.getAttribute("id");
  if (!/^user_[a-z0-9]+$/.test(id ?? "")) {
    throw new Error("Invalid user id");
  }

  return { id, name: requireText(user, "name") };
}
Parsing is not sanitization. MDN explains that parsed content starts in a separate in-memory document, but unsafe nodes or attributes can become active if inserted into the visible document. Never copy untrusted XML-derived markup into innerHTML without sanitizing it. Prefer assigning plain text with textContent, validate URLs and other values at the point of use, and apply Trusted Types protections where your application uses them.
8. Troubleshooting common XML parsing errors
| Symptom | Likely cause | Fix |
|---|---|---|
parsererror appears |
Unclosed tag, invalid nesting, bad entity, or malformed declaration | Log the raw response safely, inspect the indicated area, and reject the document before extraction. |
| Selectors return nothing | Elements are in a namespace | Use getElementsByTagNameNS() with the namespace URI. |
| Fetch fails before parsing | Non-2xx status, network error, or CORS policy | Check response.ok, catch the request error, and configure CORS on the server. |
| Expected JSON-like fields are missing | XML has repeated elements, attributes, mixed content, or a different structure | Inspect documentElement, distinguish attributes from child elements, and map repeated nodes explicitly. |
Node.js says DOMParser is not defined |
Browser API used in Node | Install and import a Node parser such as @xmldom/xmldom. |
| Data appears duplicated | textContent includes descendant text |
Select the specific child node whose text you need. |
| Modified XML is unsafe in the page | Parsed data was inserted as active markup | Sanitize or render as text; validate URLs, event-like attributes, and other values. |
9. Performance, reliability, and cost considerations
- Memory: DOM parsing creates an in-memory tree, so memory use grows with document size. Avoid parsing unnecessarily large feeds in a browser.
- Repeated queries: Cache a node or map repeated elements once instead of running the same selector inside a hot loop.
- Network reliability: Set a request timeout with
AbortController, retry only idempotent fetches, and distinguish transport errors from parse errors. - Validation: Reject malformed or structurally invalid documents early, before downstream work or database writes.
- Parser choice: Compare DOM versus object-tree output, namespace behavior, DTD/entity handling, diagnostics, runtime compatibility, maintenance, and security characteristics.
- Cost: Browser parsing itself has no service fee, but fetching, storing, and processing remote XML can consume bandwidth and compute. A hosted capture service is useful when your workflow also needs rendered pages or PDFs rather than raw XML.
10. Or skip the browser setup
If the XML is part of a page you need to document or inspect visually, ScreenshotNeo provides a single GET request for a PNG, JPEG, WebP, or PDF. Its capture flow accepts cookie and consent banners before removing more than 60 known consent platforms, newsletter popups, and chat widgets. You can turn each step off when needed. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers report the page verdict and billing result.

See the ScreenshotNeo API documentation for all options. A minimal JavaScript request is:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
The equivalent cURL and Python calls are:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)ScreenshotNeo also includes an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. It supports full-page and element captures, device presets, custom viewports, retina scale, dark mode, PDF paper sizes and page ranges, custom CSS and JavaScript, clicks, selector waits, delays, network-idle waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, configurable caching, signed links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs per call, and a usage API.
Plans include 1,000 screenshots per month free with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is available on every plan. Create a free ScreenshotNeo account.
11. FAQ
Does DOMParser throw on invalid XML?
Usually it returns a document containing a parsererror node. Check for that node before extraction.
Should I use text/xml or application/xml?
Both request XML parsing rules. application/xml is the conventional default for general XML.
Can I parse XML directly from a URL?
No. Fetch the response, verify its status, read it as text, and pass that text to the parser.
Is parsed XML safe to insert into HTML?
No. Parsing establishes structure, not safety. Treat extracted values and serialized markup as untrusted.
Which Node.js parser is best?
Choose based on whether you need a DOM or object tree, namespace and DTD behavior, diagnostics, runtime support, maintenance, and your security requirements.
How do I parse XML with a default namespace?
Use namespace-aware methods such as getElementsByTagNameNS() with the namespace URI instead of relying on an unqualified selector.


