How to Include Extensionless PNG Links in Pechkin HTML-to-PDF Output
Fix extensionless PNG images in Pechkin by checking URL typing, headers, renderer access, and safe embedding workarounds.
Short answer: an extensionless image URL can fail in Pechkin because the bundled wkhtmltopdf renderer may reject or mis-handle an image source whose path does not end in a recognized extension. This is a reported failure mode, not a rule that applies to every Pechkin build. First verify the exact Pechkin package and wkhtmltopdf binary, then check the image response, redirects, authentication, TLS, and renderer settings. If you control the route, test a .png-suffixed URL. If you cannot change the URL, fetch the bytes in your application and provide a correctly typed local or data resource.
Pechkin 0.5.8.1 is a .NET wrapper around the wkhtmltopdf static DLL, and NuGet lists that package as last updated on August 14, 2012. Your deployed wrapper may be a fork or may bundle a different binary, so reproduce the issue with the actual executable used in production. The upstream wkhtmltopdf project describes a headless Qt WebKit renderer that creates PDFs and images from HTML. See the Pechkin package metadata and wkhtmltopdf option reference before assuming that a setting or workaround is portable.
What “extensionless PNG” means
An extensionless URL has a shape such as https://cdn.example.com/image?id=42 rather than https://cdn.example.com/image.png. The server can still return valid PNG bytes with Content-Type: image/png. Browsers generally use the response and sniffing rules to display it. Older WebKit-based converters can apply additional URL or MIME assumptions.
A 2014 wkhtmltopdf issue reported ContentNotFoundError when an image source did not end with a valid extension. The issue reporter suggested that the renderer might be unable to determine the image type from the URL, but that explanation was a hypothesis rather than a maintainer-confirmed implementation detail. Treat the report as evidence of one historical failure, not a guarantee for every operating system, wrapper, or binary.
Diagnostic workflow
1. Identify the complete rendering stack
- Record the Pechkin package version and whether it is the original package or a fork.
- Locate the bundled or separately installed wkhtmltopdf binary.
- Run the binary directly with
wkhtmltopdf --version. - Capture the operating system, CPU architecture, and process account.
Differences between a developer laptop and a production worker often explain why the same HTML behaves differently.
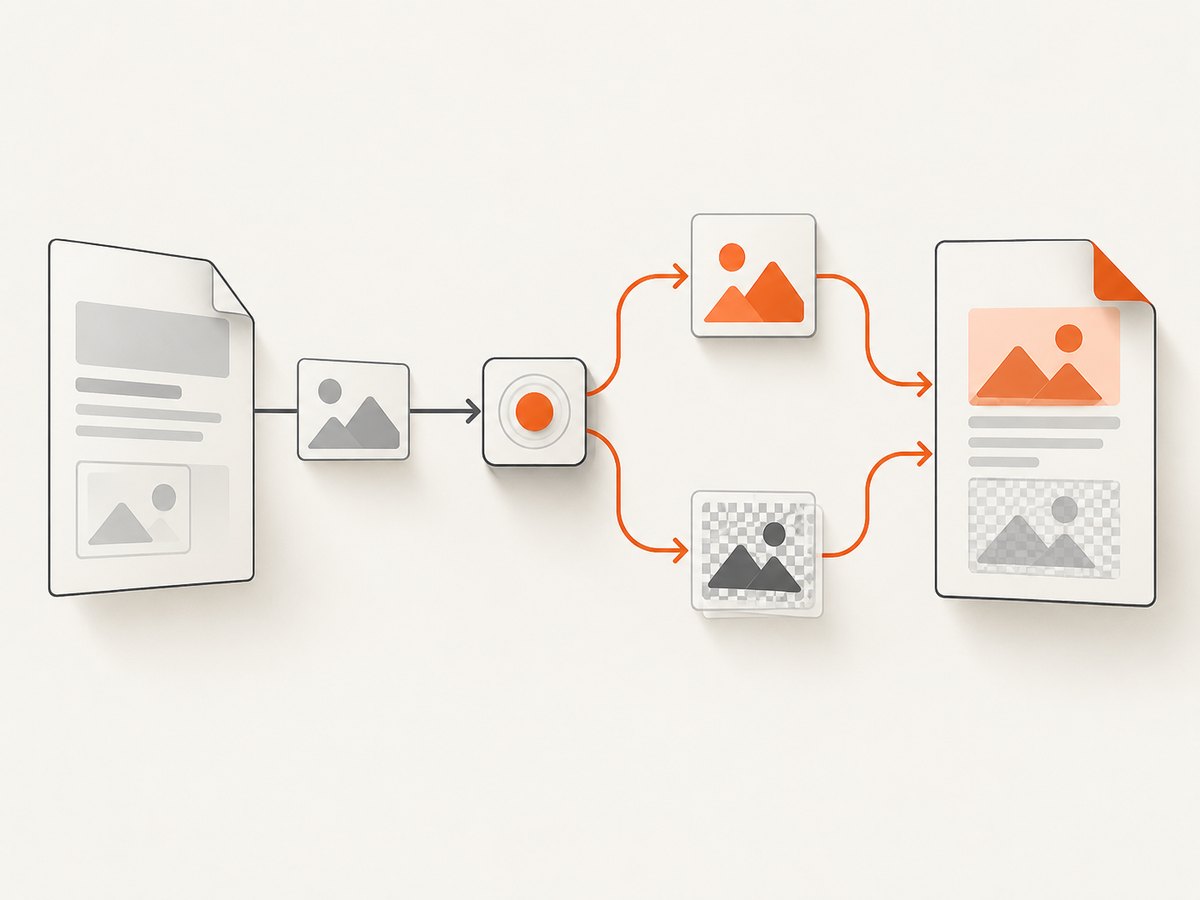
2. Inspect the image response from the conversion host
Run these checks on the same machine, container, or network where Pechkin runs:
curl -I -L 'https://cdn.example.com/image?id=42'
curl -L --fail --output /tmp/image.bin 'https://cdn.example.com/image?id=42'
file /tmp/image.bin
Check the final status, every redirect, the final Content-Type, and whether the body is really a PNG. A login page, JSON error, WAF challenge, or empty response can look like an image failure in the PDF log.
3. Check URL reachability and credentials
The renderer may not inherit your browser session, application cookies, proxy settings, or authorization headers. Test:
- DNS resolution from the worker.
- Outbound HTTPS access and certificate validation.
- Redirect targets, including redirects from HTTP to HTTPS.
- Required cookies, query signatures, bearer tokens, or IP allowlists.
- Whether the endpoint blocks the wkhtmltopdf user agent.
4. Verify image loading options
wkhtmltopdf exposes controls for image loading and load-error behavior. Ensure images have not been disabled and decide whether load errors should fail the conversion or be reported while producing a PDF. These options help separate a disabled-image configuration from a resource or URL-type problem; the documentation does not describe a universal extensionless-image switch.
Workaround A: expose a .png route
If your application owns the image endpoint, add a route whose path ends in .png while returning the same bytes and MIME type. Keep the old route available if other clients use it.
// ASP.NET Core example
[HttpGet("images/{id}.png")]
public async Task Png(string id)
{
    var bytes = await imageStore.ReadPngAsync(id);
    return File(bytes, "image/png");
}
Change the HTML to reference https://cdn.example.com/images/42.png. Confirm with curl -I that the response is 200 and Content-Type: image/png. This is a practical experiment supported by the reported failure pattern, not a guaranteed fix for every renderer.
Workaround B: fetch and embed the PNG
Fetching the resource in application code removes the renderer’s dependency on the remote URL. You can write a temporary file with a .png suffix or embed a data URL. Test size limits and cleanup behavior with your deployed binary.
Temporary local file
using System.Net.Http;

var bytes = await httpClient.GetByteArrayAsync("https://cdn.example.com/image?id=42");
var path = Path.Combine(Path.GetTempPath(), $"{Guid.NewGuid():N}.png");
await File.WriteAllBytesAsync(path, bytes);

var html = $"<html><body><img src=\"file:///{path.Replace("\\", "/\")}\" /></body></html>\";
// Pass html to your Pechkin conversion call, then delete path in a finally block.
Some builds restrict local-file access. If the image disappears, check the local-file option and the account’s filesystem permissions.
Data URL
var bytes = await httpClient.GetByteArrayAsync("https://cdn.example.com/image?id=42");
var base64 = Convert.ToBase64String(bytes);
var html = $"<img src=\"data:image/png;base64,{base64}\" />";
Data URLs avoid network access during conversion but increase HTML size by roughly one third after Base64 encoding. Large images can increase memory use or exceed limits in old WebKit builds.
Complete Pechkin example
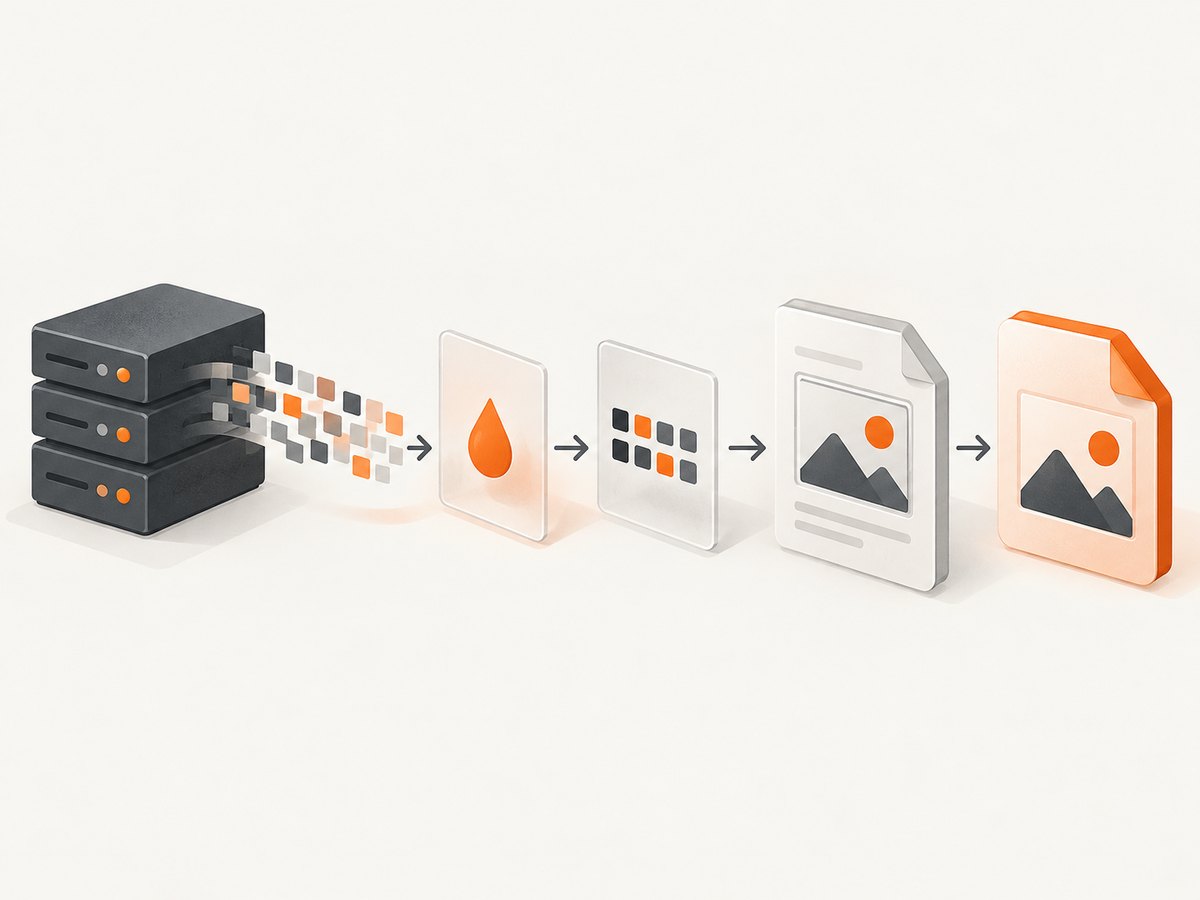
The following outline shows the important ordering: retrieve and validate the image, build HTML with a typed resource, then render. Adapt the converter construction to your Pechkin fork.
using System;
using System.IO;
using System.Net.Http;
using System.Threading.Tasks;
using Pechkin;
using Pechkin.Synchronized;

public static class PdfJob
{
    public static async Task<byte[]> RenderAsync(string imageUrl)
    {
        using var client = new HttpClient();
        using var response = await client.GetAsync(imageUrl);
        response.EnsureSuccessStatusCode();

        var contentType = response.Content.Headers.ContentType?.MediaType;
        if (!string.Equals(contentType, "image/png", StringComparison.OrdinalIgnoreCase))
            throw new InvalidDataException($"Expected image/png, received {contentType ?? "missing"}");

        var png = await response.Content.ReadAsByteArrayAsync();
        var data = Convert.ToBase64String(png);
        var html = $"<!doctype html><html><body>" +
                   $"<img src=\"data:image/png;base64,{data}\" />" +
                   "</body></html>";

        var global = new GlobalConfig();
        var settings = new ObjectConfig();
        using var converter = new SynchronizedPechkin(global);
        return converter.Convert(settings, html);
    }
}
Validate the magic bytes as well when the endpoint is untrusted. A PNG normally begins with 89 50 4E 47 0D 0A 1A 0A; MIME headers alone are not proof that the body is an image.
How to choose between the fixes
| Approach | Best when | Trade-offs |
|---|---|---|
| PNG-suffixed route | You control routing and want small HTML | Requires a route change; may not help if the real cause is auth or TLS |
| Temporary local PNG | The renderer can read local files | Needs secure temporary-file handling and cleanup |
| Data URL | The image is moderate in size and self-contained HTML is useful | More memory and larger HTML |
| Keep URL and diagnose | You cannot change the endpoint | Requires complete network, header, redirect, and renderer investigation |
Troubleshooting common errors
ContentNotFoundError
Cause: the historical wkhtmltopdf report associates this error with an image URL lacking a recognized extension, but the same message can indicate an unreachable resource. Fix: reproduce with the exact binary, inspect redirects and response bytes, then test a .png route or embedded bytes.
The PDF is created but the image is missing
Cause: images may be disabled, blocked by a network policy, rejected by authentication, or fetched after the renderer finishes. Fix: enable image loading, provide credentials through supported mechanisms, and use a wait strategy appropriate to your page. Embedding the bytes removes most timing and network variables.
The endpoint returns HTML instead of PNG
Cause: a login form, bot check, error page, or redirect target was saved as the image. Fix: inspect the final status and body with curl -L; supply the required cookie or authorization, or fetch the image in your application.
HTTPS images fail
Cause: certificate-chain, TLS, proxy, or old-binary compatibility issues. Fix: compare the renderer host’s certificate trust with curl and the browser. Historical community answers mention replacing Pechkin with TuesPechkin or installing OpenSSL for particular HTTPS symptoms. Those anecdotes concern TLS loading and do not establish a fix for extensionless URLs.
Data URLs fail or PDFs become unstable
Cause: oversized HTML, memory pressure, or limits in an old WebKit build. Fix: resize or compress the image, use a temporary file, and process large documents in smaller jobs.
It works locally but not in production
Cause: different binary versions, service accounts, network egress, filesystem permissions, or environment variables. Fix: log the renderer version, run the same command under the production account, and capture response headers from that host.
Reliability, performance, and cost considerations
- Reliability: prefetching lets you fail fast with a useful HTTP or MIME error instead of producing a partial PDF. Add bounded timeouts and cancellation for remote image requests.
- Performance: one remote fetch plus Base64 encoding adds CPU and memory work. Reuse
HttpClient, cache immutable images, and avoid embedding the same large image repeatedly. - Security: do not allow arbitrary user-provided URLs to become server-side fetches without SSRF protections. Restrict schemes, hosts, private IP ranges, redirects, and response sizes.
- Reproducibility: pin the wrapper and renderer binary. Package age matters because Pechkin 0.5.8.1 dates from 2012.
- Cost: self-hosted conversion cost is driven by your worker CPU, memory, storage, and network. A hosted renderer moves that operational work to an API but changes the deployment model; it does not prove a fix for this specific URL behavior.
Or skip the browser setup
If your goal is a reliable image or PDF capture rather than maintaining a wkhtmltopdf worker, ScreenshotNeo provides a website screenshot API and MCP server. It accepts a URL in one GET request and can return PNG, JPEG, WebP, or PDF. Cookie and consent banners, newsletter popups, and chat widgets are removed before capture; each step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);See the ScreenshotNeo API documentation for request options. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots each month without a card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
FAQ
Does every extensionless PNG fail in Pechkin?
No. The reported issue is version and environment evidence, not a universal specification. Test your exact binary and endpoint.
Will adding Content-Type: image/png always fix it?
No. Correct MIME headers are necessary for many clients, but the cited report does not prove that headers alone resolve URL typing in every build.
Should I install OpenSSL?
Only when diagnostics show a TLS or certificate problem. It is not an established extensionless-URL fix.
Can I use a hosted API for a PDF instead?
Yes, if changing the rendering deployment fits your requirements. Evaluate authentication, output options, retention, pricing, and network policy separately from this Pechkin issue.
What should I log for support?
Log the Pechkin and wkhtmltopdf versions, operating system, final image URL, status and content type, redirect chain, image byte count, renderer stderr, and whether the same URL works from the conversion host.


