How to Detect Page Height in PhantomJS for Full-Page Screenshots
Measure document height in PhantomJS, choose between viewportSize and clipRect, handle dynamic pages, and avoid cut-off full-page screenshots.
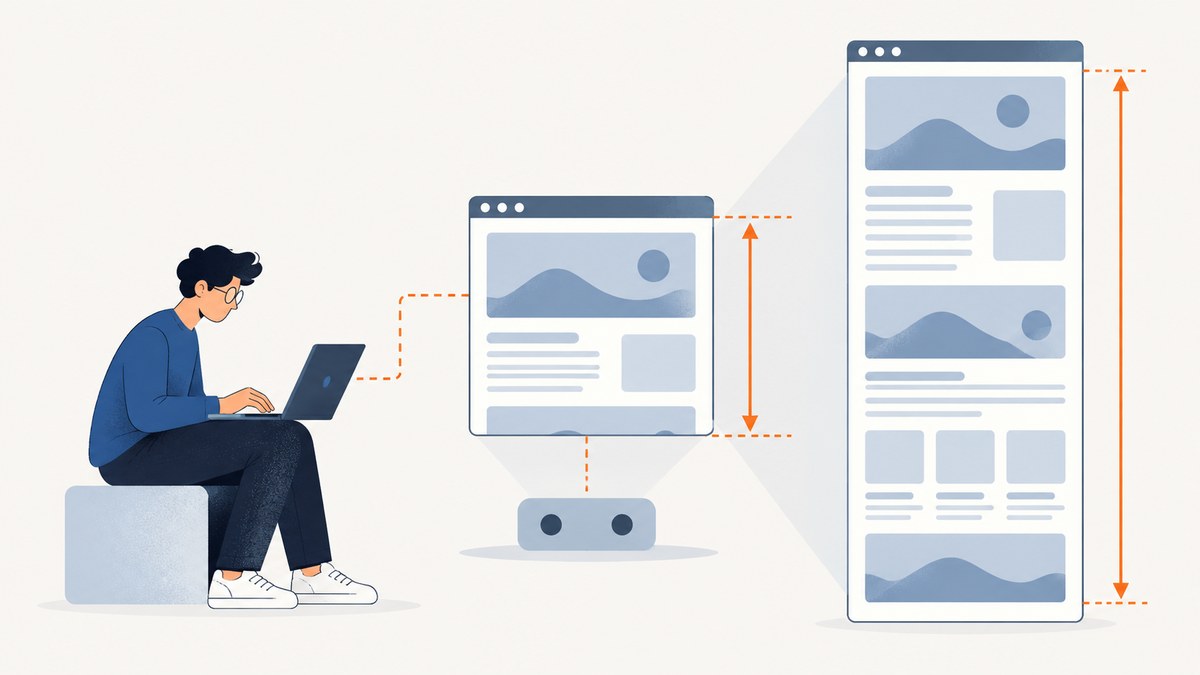
To detect page height in PhantomJS, run JavaScript inside the loaded page with page.evaluate() and measure the document’s scroll height. A practical cross-layout expression is:
var height = page.evaluate(function () {
  return Math.max(
    document.documentElement.scrollHeight,
    document.body ? document.body.scrollHeight : 0
  );
});
Use that value as the capture height by assigning it to page.clipRect.height, or set page.viewportSize.height to the measured value before calling page.render(). Measure only after the content you need has rendered. A successful page.open() callback means navigation succeeded; it does not guarantee that images, client-rendered components, or infinite-scroll content have finished changing the layout.
PhantomJS is a legacy headless browser, and its project homepage says development is suspended. The method below remains useful for maintaining an existing PhantomJS script, but evaluate whether a maintained browser is more suitable for new automation.
How the measurement works
document.documentElement.scrollHeight reports the full scrollable height of the root document element. Some pages expose a more useful value through document.body.scrollHeight, especially when older layout modes or body-level styling are involved. Taking the maximum avoids choosing the shorter value.
This is a DOM measurement, not a PhantomJS property named pageHeight. PhantomJS provides the page-context evaluation mechanism; the expression above is a browser technique applied through that mechanism. If scripts append content or images change their intrinsic dimensions after the first read, the measured height can become stale. In that case, wait for the relevant condition and measure again.
Complete PhantomJS example
Save this as full-page.js and run it with PhantomJS:
var system = require('system');
var webpage = require('webpage');

if (system.args.length < 3) {
  console.log('Usage: phantomjs full-page.js URL OUTPUT');
  phantom.exit(1);
}

var url = system.args[1];
var output = system.args[2];
var page = webpage.create();

page.viewportSize = {
  width: 1280,
  height: 800
};

page.open(url, function (status) {
  if (status !== 'success') {
    console.log('Unable to load page: ' + status);
    phantom.exit(1);
    return;
  }

  // Example delay. Replace this with a page-specific readiness check when possible.
  window.setTimeout(function () {
    var height = page.evaluate(function () {
      return Math.max(
        document.documentElement.scrollHeight,
        document.body ? document.body.scrollHeight : 0
      );
    });

    if (!height || height < 1) {
      console.log('Could not determine a usable document height');
      phantom.exit(1);
      return;
    }

    page.clipRect = {
      top: 0,
      left: 0,
      width: page.viewportSize.width,
      height: height
    };

    page.render(output);
    console.log('Captured ' + width + 'x' + height + ' to ' + output);
    phantom.exit(0);
  }, 500);
});
Run it with:
phantomjs full-page.js https://example.com full-page.pngThe documented PhantomJS controls are described in the viewportSize API, clipRect API, and render API.
Wait for the page before measuring
Do not assume that page.open is the final layout event. Single-page applications, lazy images, web fonts, advertisements, and API calls can all increase document height later.
Use a fixed delay for simple pages
A short delay is adequate for a static page with a few images:
window.setTimeout(capture, 1000);Treat the duration as an adjustable example. There is no universal delay that settles every page.
Wait for a selector
When the page has a reliable marker, poll for it instead of guessing:
function waitForSelector(selector, callback, started) {
  started = started || new Date().getTime();
  var found = page.evaluate(function (s) {
    return !!document.querySelector(s);
  }, selector);

  if (found) {
    callback(true);
    return;
  }

  if (new Date().getTime() - started > 15000) {
    callback(false);
    return;
  }

  window.setTimeout(function () {
    waitForSelector(selector, callback, started);
  }, 200);
}

page.open(url, function (status) {
  if (status !== 'success') {
    phantom.exit(1);
    return;
  }

  waitForSelector('#main-content', function (ready) {
    if (!ready) {
      console.log('Readiness selector did not appear');
      phantom.exit(1);
      return;
    }
    capture();
  });
});
The selector should represent the content you need, such as an article container or a chart wrapper. A selector that appears before its children finish rendering can still be too early.
Wait for images or application state
You can inspect image completion from the page context:
var imagesReady = page.evaluate(function () {
  var images = Array.prototype.slice.call(document.images);
  return images.every(function (img) {
    return img.complete && img.naturalWidth > 0;
  });
});
For client-rendered applications, expose a page-specific flag such as window.__SCREENSHOT_READY__ = true after the final render, then poll for that flag. This is more reliable than a delay when you control the application.
Choosing viewportSize or clipRect
| Method | What it controls | Use it when | Watch for |
|---|---|---|---|
viewportSize.height = height |
The browser viewport itself | The page layout should behave as if the viewport is as tall as the document | Viewport-dependent CSS, sticky elements, and media queries can change the layout |
clipRect.height = height |
The rectangle copied into the output | You want to preserve a normal viewport while capturing a taller region | The page may still need scrolling or extra rendering for lazy content |
Keeping a normal viewport and changing clipRect usually preserves the layout established at your chosen width and height. Enlarging the viewport can make responsive breakpoints, fixed positioning, and viewport units behave differently. Neither approach is universally correct; compare the resulting layout for your page.
Full-page capture with a second measurement
For pages that continue loading content, measure, allow a short settling period, and measure again:
function documentHeight() {
  return page.evaluate(function () {
    return Math.max(
      document.documentElement.scrollHeight,
      document.body ? document.body.scrollHeight : 0
    );
  });
}

var first = documentHeight();
window.setTimeout(function () {
  var second = documentHeight();
  var height = Math.max(first, second);
  page.clipRect = {
    top: 0,
    left: 0,
    width: page.viewportSize.width,
    height: height
  };
  page.render('full-page.png');
  phantom.exit();
}, 500);
For an infinite-scroll page, there may be no final height. Set a business rule: capture the initial loaded content, scroll and load a fixed number of batches, or stop when the height has remained unchanged for several checks.
Important edge cases
Lazy-loaded images
Images triggered by scrolling may not exist in the layout when you first measure. Scroll in increments, wait for each batch, then measure again. Be aware that scrolling can alter sticky headers and trigger animations.
Collapsed content and accordions
scrollHeight includes content that contributes to layout. Hidden panels with display:none do not contribute until opened. If your screenshot should include an accordion, click or expand it before measuring.
Fixed and sticky elements
A fixed header can appear on top of every portion of a tall capture, depending on how PhantomJS paints the clipped region. Hide it with page CSS or capture the page in segments if repeated overlays make the result unusable.
Very tall documents
The cited PhantomJS documentation does not define a universal maximum safe image height. Extremely tall single images can consume substantial memory or fail in the renderer. For long reports, split the page into vertical ranges and render several files, or produce a PDF using the separate paperSize configuration.
Fonts and layout shifts
Late font loading can change line wrapping and therefore page height. Wait until the font-dependent content is visible, or use a deterministic font stack for capture jobs.
Debugging and troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Screenshot is cut off | Height was measured before asynchronous content rendered | Wait for a selector, images, application state, or a longer page-specific delay, then re-measure |
| Height is zero or unexpectedly small | Measurement ran outside page context or the document has not loaded | Run the function inside page.evaluate after a successful page.open |
| Bottom content is missing | Lazy loading is triggered by scrolling | Scroll through the page, wait for new content, and measure again |
| Layout changes when using viewport height | Responsive CSS or viewport units depend on the enlarged viewport | Keep the normal viewport and set clipRect.height instead |
| Page never finishes | Network requests or scripts keep changing the page | Use a timeout, a readiness selector, and a defined maximum capture height |
| Output file is blank | Navigation failed, rendering happened too early, or the renderer ran out of resources | Check the status, log the measured dimensions, wait for readiness, and split very tall captures |
| Cookies or authentication are missing | The page requires session state | Configure cookies before navigation and verify the authenticated content with page.evaluate |
Performance, reliability, and cost
Height measurement itself is inexpensive; page loading and rendering dominate runtime. Keep the viewport width stable, block unnecessary third-party resources when your capture does not need them, and avoid repeated full-page renders while debugging. Log the URL, navigation status, measured height, output format, and elapsed time so failures can be diagnosed.
Reliability improves when readiness is tied to content rather than a universal sleep. Use bounded polling, handle navigation failures, and exit PhantomJS explicitly on every error path. Re-measure after known layout-changing events. For very long pages, segmented captures reduce memory pressure but require stitching or separate output handling.
A local PhantomJS script has no per-image API charge, but it still consumes compute, bandwidth, maintenance time, and an obsolete browser runtime. PhantomJS development is suspended, so modern sites may expose compatibility problems that require workarounds or migration.
Or skip the browser setup
ScreenshotNeo provides a hosted screenshot endpoint when you do not want to maintain a browser process. It supports full-page capture with lazy images loaded and accepts the common screenshot parameters used by other APIs.
Read the parameter reference in the ScreenshotNeo documentation. A minimal request is:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({
access_key: 'YOUR_API_KEY',
url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
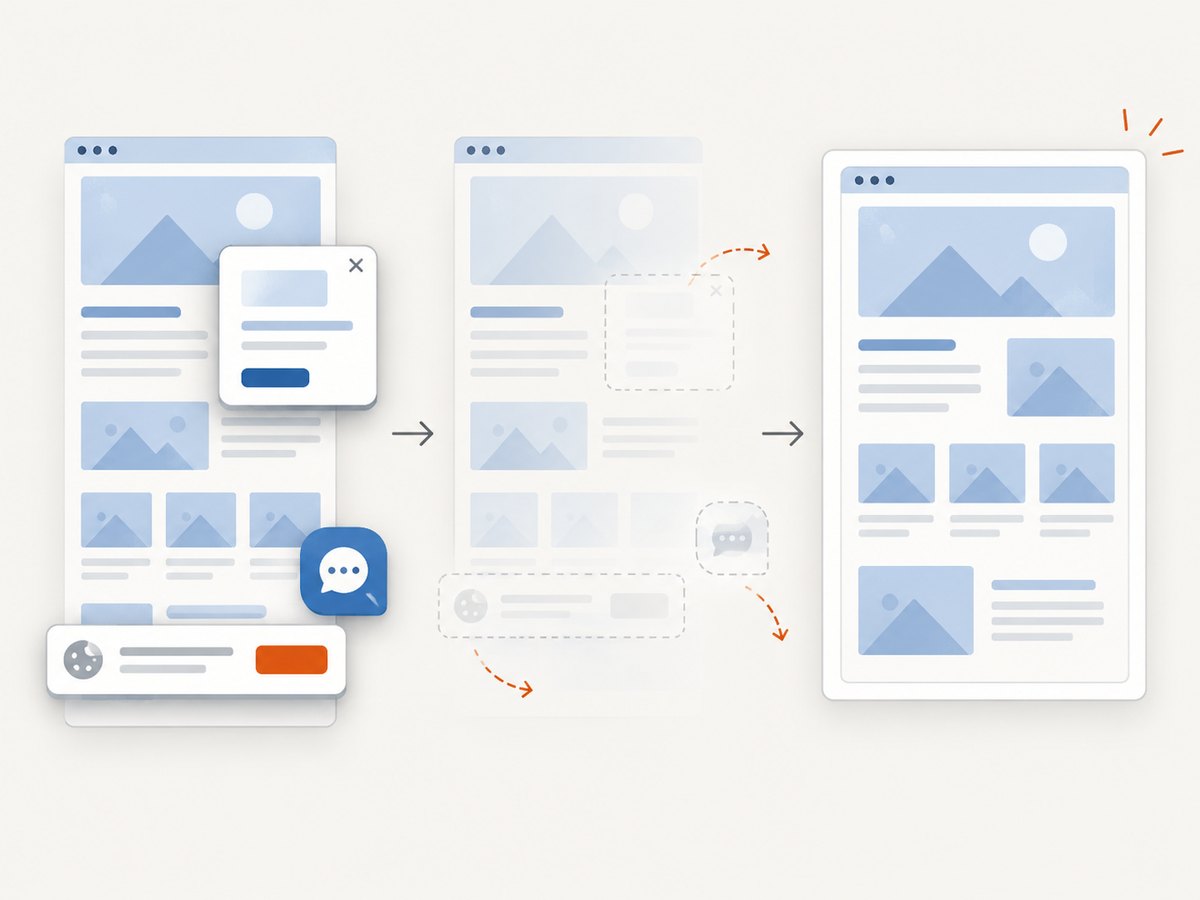
require('fs').writeFileSync('shot.webp', buffer);Before capture, ScreenshotNeo accepts cookie and consent banners like a visitor and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each cleanup step can be turned off. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing result with X-Page-Verdict and X-Billed. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 shots per month without a card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
FAQ
Does PhantomJS have a built-in page-height property?
No. Use DOM measurements inside page.evaluate, then pass the result to clipRect or viewportSize.
Should I use body.scrollHeight or documentElement.scrollHeight?
Read both and use the maximum. This handles common differences between document layouts.
Why does a successful page.open still produce an incomplete image?
Navigation success does not mean asynchronous rendering is finished. Wait for the content that matters, then measure.
Can I capture a PDF with the same height setting?
PDF output uses paper sizing through paperSize, which is separate from image clipping. Configure PDF dimensions independently.
Is PhantomJS suitable for a new screenshot service?
Its development is suspended. For new systems, compare maintained browser automation or a hosted API against your compatibility, operational, and cost requirements.


