Puppeteer Web Scraping: Common Questions Answered
Learn how to scrape JavaScript-rendered pages with Puppeteer, wait for reliable page states, choose selectors, handle errors, and extract useful data.
Puppeteer can scrape pages whose content is rendered by JavaScript because it controls a real browser. The reliable pattern is to navigate, check the response, wait for the page state you need, select stable elements, and extract only the fields you need. Avoid treating a fixed delay as proof that a page is ready.
This guide answers common questions about Puppeteer web scraping, including installation, selectors, synchronization, navigation errors, browser support, and practical performance choices. It uses JavaScript for the main examples, with Python and cURL options where they fit. Puppeteer itself is a JavaScript library; a Python example below calls a small Node.js scraper as a subprocess rather than pretending Puppeteer has a native Python API.
1. What is Puppeteer, and when should you use it?
Puppeteer is a JavaScript library that controls Chrome or Firefox using the Chrome DevTools Protocol (CDP) or WebDriver BiDi. It runs headless by default, though you can configure a visible browser. Its browser access makes it useful when important page content appears only after scripts run, when a workflow requires clicks or form submission, or when you need browser artifacts such as screenshots and PDFs. Puppeteer documentation describes those capabilities.
Use a simpler HTTP client and HTML parser when the required data is present in the server response and does not require browser execution. A browser has more startup, memory, and download costs. Puppeteer is appropriate when the page’s actual browser state matters: for example, a single-page app that fetches product data after load, a filter that must be applied before extraction, or content hidden behind a user interaction.
Scraping still needs to respect the site’s terms, access controls, and applicable law. Keep request rates reasonable and do not use browser automation to evade a CAPTCHA or access restriction.
2. Install Puppeteer and prepare a project
Install Node.js, create a project, and add Puppeteer:
mkdir puppeteer-scraper
cd puppeteer-scraper
npm init -y
npm install puppeteer
The package installation downloads compatible browser binaries. The Puppeteer installation guide gives approximate download sizes of 170 MB on macOS, 282 MB on Linux, and 280 MB on Windows. Your actual download and disk use can vary by platform and version. In managed build environments, package managers may block install scripts; if the browser did not download, consult the installation guide and run npx puppeteer browsers install or allow the install script.
Use an ES module file such as scrape.mjs. This complete example accepts a URL, waits for a meaningful product heading, extracts structured data, checks the HTTP response, and closes the browser even if something fails:
import puppeteer from 'puppeteer';

const url = process.argv[2] ?? 'https://example.com';
let browser;

try {
  browser = await puppeteer.launch({ headless: true });
  const page = await browser.newPage();
  await page.setViewport({ width: 1365, height: 900 });

  const response = await page.goto(url, {
    waitUntil: 'domcontentloaded',
    timeout: 30_000,
  });

  if (!response) {
    throw new Error('Navigation returned no main-resource response');
  }
  if (!response.ok()) {
    throw new Error(`Page returned HTTP ${response.status()}: ${url}`);
  }

  const heading = page.locator('h1').waitHandle();
  const handle = await heading;
  if (!handle) throw new Error('The page did not contain an h1');

  const result = await handle.evaluate((el) => ({
    title: el.textContent?.trim() ?? '',
    pageTitle: document.title,
    canonical: document.querySelector('link[rel="canonical"]')?.href ?? null,
  }));
  await handle.dispose();
  console.log(JSON.stringify(result, null, 2));
} finally {
  await browser?.close();
}
Run it with node scrape.mjs https://example.com. The example checks status before extracting. Puppeteer documents that in headless shell mode, page.goto does not reject solely because the server returned a valid HTTP error response such as 404 or 500. Inspect the response yourself. The page.goto reference also documents that it returns the main resource response.
3. Wait for the state you need
Navigation completion and application readiness are different events. A document can finish loading before a client-side request fills a results panel. Pick the wait condition that represents the data you need:
| Need | Use | Example |
|---|---|---|
| A known result or element | Locator or waitForSelector |
page.locator('.result').waitHandle() |
| A browser navigation | waitForNavigation |
Pair with the click using Promise.all |
| A page-specific condition | waitForFunction |
Wait until a result count is nonzero |
| Network quiet | waitForNetworkIdle |
Useful when requests settle after rendering |
| A specific request or response | waitForRequest or waitForResponse |
Wait for the endpoint that supplies the data |
Locators are recommended for interaction because they automatically wait for an element to exist and be ready for the action. For extraction, wait for a selector or condition that proves the target data is present. The interactions guide covers locators and selectors; the Page API documents page wait methods.
Wait for a rendered result
await page.goto('https://example.com/catalog', {
  waitUntil: 'domcontentloaded',
  timeout: 30_000,
});
await page.waitForSelector('[data-testid="product-card"]', {
  visible: true,
  timeout: 15_000,
});
const products = await page.$$eval('[data-testid="product-card"]', cards =>
  cards.map(card => ({
    name: card.querySelector('h2')?.textContent?.trim() ?? null,
    price: card.querySelector('.price')?.textContent?.trim() ?? null,
  }))
);
Wait for an application condition
await page.waitForFunction(() => {
  const status = document.querySelector('[data-testid="load-status"]');
  const cards = document.querySelectorAll('[data-testid="product-card"]');
  return status?.textContent?.includes('Complete') && cards.length > 0;
}, { timeout: 15_000 });
Use networkidle only when network quiet is relevant. Analytics, long polling, and streaming can keep connections open, while a quiet network does not guarantee that the exact data you need rendered. Fixed sleeps are brittle: a short delay races slow pages, and a long delay wastes time on fast ones.
4. Choose selectors that survive page changes
CSS selectors are the default and are usually the clearest choice when the site provides stable classes, IDs, or test attributes. Prefer semantic or stable attributes such as data-testid over generated class names that change between builds. Puppeteer also supports XPath, text, accessibility, and Shadow DOM selector syntax. Use these when the page structure makes ordinary CSS awkward; keep the selector close to the meaning of the content.
For a quick one-field extraction:
const text = await page.$eval('main h1', el => el.textContent?.trim() ?? '');$eval throws if no element matches. If absence is expected, use a nullable query pattern:
const price = await page.evaluate(() => {
  const el = document.querySelector('[data-testid="price"]');
  return el?.textContent?.trim() ?? null;
});
For many matching elements, evaluate once in the page rather than making many round trips:
const rows = await page.$$eval('table tbody tr', trs =>
  trs.map(tr => [...tr.querySelectorAll('td')].map(td => td.textContent?.trim() ?? ''))
);
5. Handle clicks, navigation, pagination, and SPAs
When a click triggers a document or History API navigation, register the navigation wait before clicking. Otherwise the navigation can begin before the listener exists:
await Promise.all([
  page.waitForNavigation({ waitUntil: 'domcontentloaded', timeout: 20_000 }),
  page.locator('a.next-page').click(),
]);
Some single-page applications update content without a conventional navigation event. In that case, wait for a page condition, a result selector, or the response associated with the action, then extract. A pagination loop should have a maximum page count, detect repeated URLs or repeated records, and stop when the next control is absent or disabled. Those guards prevent infinite loops and accidental collection of duplicate pages.
const seen = new Set();
const allRows = [];
for (let pageNumber = 0; pageNumber < 20; pageNumber++) {
  const current = page.url();
  if (seen.has(current)) break;
  seen.add(current);

  await page.waitForSelector('.result-row', { timeout: 10_000 });
  allRows.push(...await page.$$eval('.result-row', els =>
    els.map(el => el.textContent?.trim() ?? '')
  ));

  const next = await page.$('a.next-page:not([aria-disabled="true"])');
  if (!next) break;
  await Promise.all([
    page.waitForNavigation({ waitUntil: 'domcontentloaded' }).catch(() => null),
    next.click(),
  ]);
}
Adjust the navigation wait to the site’s actual behavior. For an SPA, replace it with a wait for a changed page number or result set; do not assume every click causes a document load.
6. Diagnose empty or incorrect data
An empty extraction usually means the selector did not match, the expected content had not rendered, the page showed an error or challenge, or the data lives in a different frame or shadow root. Start by checking what the browser actually received and rendered:
console.log('URL:', page.url());
console.log('Title:', await page.title());
console.log('HTML preview:', (await page.content()).slice(0, 1500));
console.log('Matches:', await page.locator('.result-row').count());
For local diagnosis, save a screenshot or inspect the page in headful mode. Check whether consent overlays, login requirements, locale settings, or responsive layout changed the page. Confirm selectors against the rendered DOM, not only the original source. If data appears after scrolling, scroll in controlled increments and wait for the new records after each increment; many sites lazy-load content.
Do not interpret a bot check or CAPTCHA as a normal empty result. Stop, lower request rates, and use an authorized access path. Avoid trying to bypass the challenge.
7. cURL and Python: when Puppeteer is the wrong layer
cURL cannot execute page JavaScript. It is useful for checking a server response or fetching a known public endpoint that already returns the data. This request prints response headers and the response body for inspection:
curl -L --max-time 30 -D response-headers.txt \
  -o response.html \
  https://example.com
For a JSON endpoint, inspect the response type and status rather than trying to parse a browser-rendered page from cURL. If the target requires JavaScript execution, use Puppeteer in Node.js.
Python does not run Puppeteer directly. One practical arrangement is to invoke the Node script from Python and parse its JSON output:
import json
import subprocess

result = subprocess.run(
    ["node", "scrape.mjs", "https://example.com"],
    check=True,
    capture_output=True,
    text=True,
    timeout=60,
)
record = json.loads(result.stdout)
print(record["title"])
For a page that does not require browser rendering, Python’s requests can fetch it directly:
import requests
from bs4 import BeautifulSoup

response = requests.get("https://example.com", timeout=30)
response.raise_for_status()
soup = BeautifulSoup(response.text, "html.parser")
print(soup.select_one("h1").get_text(strip=True))
8. Firefox, screenshots, PDFs, and other uses
Puppeteer v23.0.0 and later support Chrome and Firefox according to its FAQ. Chrome automation uses CDP, while Firefox defaults to WebDriver BiDi. Browser and protocol support can change, so check the current FAQ and version-specific documentation before relying on a particular combination.
Scraping is one use of Puppeteer. The project also documents screenshots, PDF generation, form submission, UI testing, performance tracing, network interception, and crawling single-page applications. If you need an archive or visual record rather than structured fields, screenshots or PDFs may be a better output than DOM parsing. Note that headless shell mode does not support navigation to a PDF document, as described in the navigation reference.
9. Or skip the browser setup
If your goal is a rendered page image rather than extracting structured fields, ScreenshotNeo provides a screenshot API and MCP server. A single GET request captures a URL as PNG, JPEG, WebP, or PDF. See the API documentation for options and formats.
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
import requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
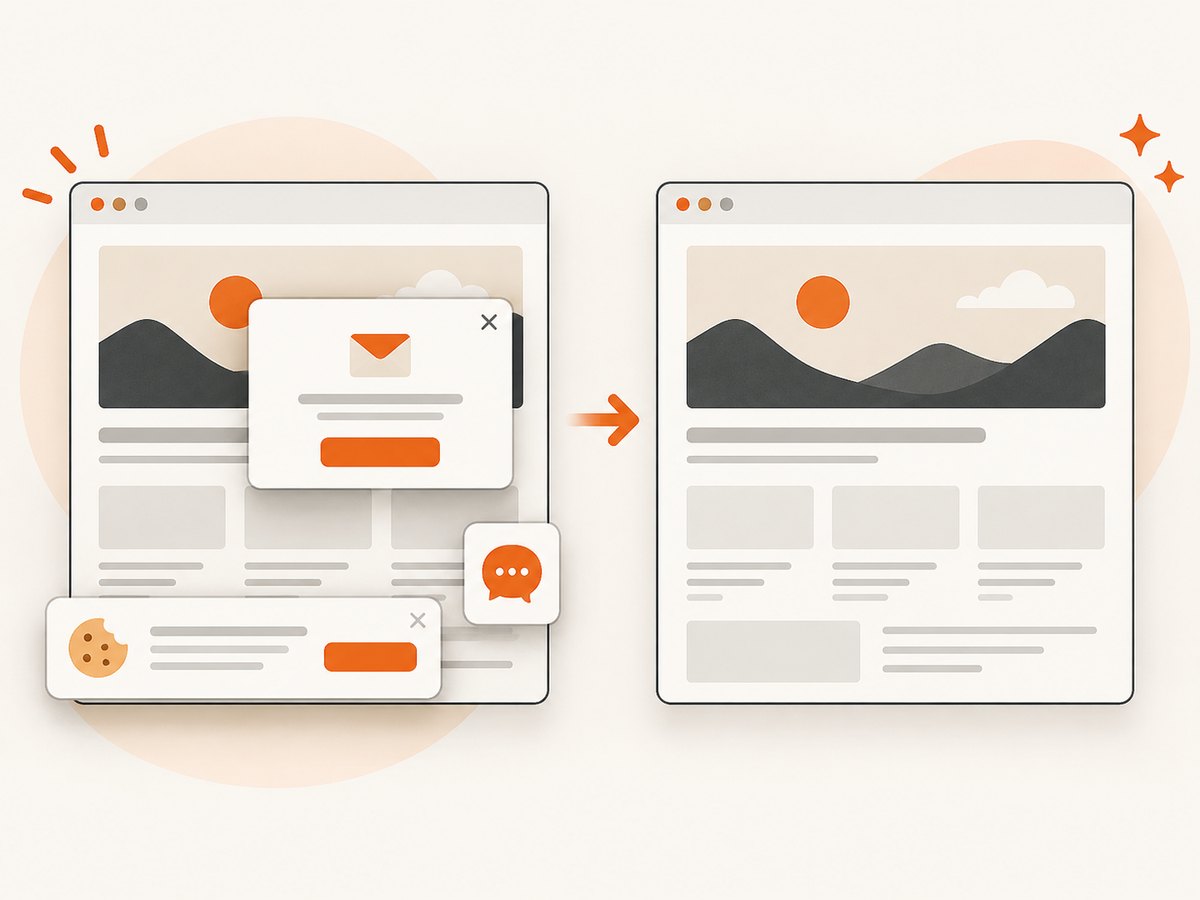
await import('node:fs/promises').then(fs => fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer())));ScreenshotNeo accepts cookie and consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets before the shot; each step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits cost nothing, and response headers report the page verdict and billing status. Its MCP server includes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. The free plan includes 1,000 shots a month with no card; paid plans start at $5 for 3,000 shots. Try it with a free ScreenshotNeo account.
10. Performance, reliability, and cost
Browser work costs more resources than a direct HTTP fetch. Launch one browser per worker or job batch and reuse it for multiple pages when isolation requirements allow; creating a browser for every URL repeats startup work. Close pages and browsers in finally blocks. Put explicit timeouts on navigation and waits, and cap concurrency to the memory available to the process. A large number of simultaneous pages can exhaust memory or trigger rate limits.
Keep extraction deterministic: use stable selectors, validate required fields, record the URL and status with each result, and make retries bounded. Retry transient timeouts or network errors with backoff, but do not blindly retry permanent 4xx errors or access challenges. Save enough diagnostics to distinguish a changed layout from a transport failure. Browser binary downloads also matter in CI: cache compatible browser installations where your build system supports it, and verify install scripts are allowed.
Cost includes compute, bandwidth, browser installation and maintenance, and engineering time spent handling layout changes and failures. A direct HTTP request is generally simpler where it yields the required content. A browser is justified when it provides necessary rendered state or interaction. For image-only capture at scale, compare the operational cost of maintaining browser workers with an API plan; ScreenshotNeo’s listed tiers are Free (1,000 monthly), Starter ($5 for 3,000), Growth ($15 for 15,000), Pro ($39 for 60,000), Scale ($99 for 250,000), and Business ($249 for 1,000,000). Yearly billing gives two months free, and every feature is on every plan.
11. Troubleshooting common Puppeteer errors
| Symptom | Likely cause | Fix |
|---|---|---|
| Browser executable missing | Install scripts were blocked or browser download did not complete | Run npx puppeteer browsers install and check installation settings |
| Navigation returns but page is 404/500 | HTTP error status is not necessarily a rejected navigation | Check response.status() and response.ok() |
| Timeout waiting for selector | Selector is wrong, content is delayed, or page state differs | Inspect URL, title, DOM, and screenshot; wait for the actual state |
| Click happened but next page was missed | Navigation wait was attached after the click | Start wait and click together in Promise.all |
| Network idle never occurs | Long-lived requests or polling keep the network active | Wait for the result selector or a specific response instead |
| Data is duplicated across pages | Pagination repeated a route or app state did not advance | Track visited URLs and page identifiers; stop on repeats |
| Works locally, fails in CI | Missing browser dependencies, blocked download, or resource limits | Install the browser during setup, check environment dependencies, lower concurrency |
| PDF navigation fails in headless shell | That mode does not support navigation to a PDF document | Use a supported workflow to obtain the PDF rather than navigating to it in headless shell |
12. Frequently asked questions
Can Puppeteer scrape a site without an API?
It can read content exposed in the browser DOM, but the site’s access rules still apply. Prefer an official API when one is available and permitted.
Should I save the whole page HTML?
Usually not. Extract the fields you need and preserve provenance such as URL, timestamp, and response status. Full HTML can be large and may include irrelevant or sensitive page data.
Can I use Puppeteer for screenshots instead of scraping?
Yes. Puppeteer supports screenshots and PDFs. If you only need a screenshot, a capture API can avoid maintaining the browser setup; see the ScreenshotNeo option above.
Why does my selector work in the browser inspector but not Puppeteer?
The automated page may be at a different URL, viewport, login state, or render timing. Log the live URL and inspect the DOM from the same run before changing the selector.


