How to Use For Loops Correctly with Pyppeteer
Learn how to loop through URLs with Pyppeteer using async/await, reliable cleanup, dynamic waits, troubleshooting, and ScreenshotNeo.
Use a regular Python for loop inside an async def function, and await every Pyppeteer coroutine in the loop. The loop is Python control flow, not a Pyppeteer method.
import asyncio
from pyppeteer import launch

async def main():
    browser = await launch()
    try:
        page = await browser.newPage()
        for url in ["https://example.com", "https://example.org"]:
            await page.goto(url, {"waitUntil": "networkidle2"})
            print(url, await page.title())
    finally:
        await browser.close()

asyncio.run(main())
This follows the setup in the Pyppeteer README. The finally block closes Chromium when an iteration fails.
How do I use a for loop with Pyppeteer?
- Put browser work in
async def. - Launch a browser and create a page.
- Iterate with
for item in items. - Await navigation, waits, selectors, evaluation, and extraction.
- Close pages and the browser in
finally.
Pyppeteer operations commonly return coroutines. Calling one without await gives you a coroutine object instead of a completed result. Pyppeteer is an unofficial Python port of Puppeteer, so check its current documentation for Python and JavaScript naming differences.
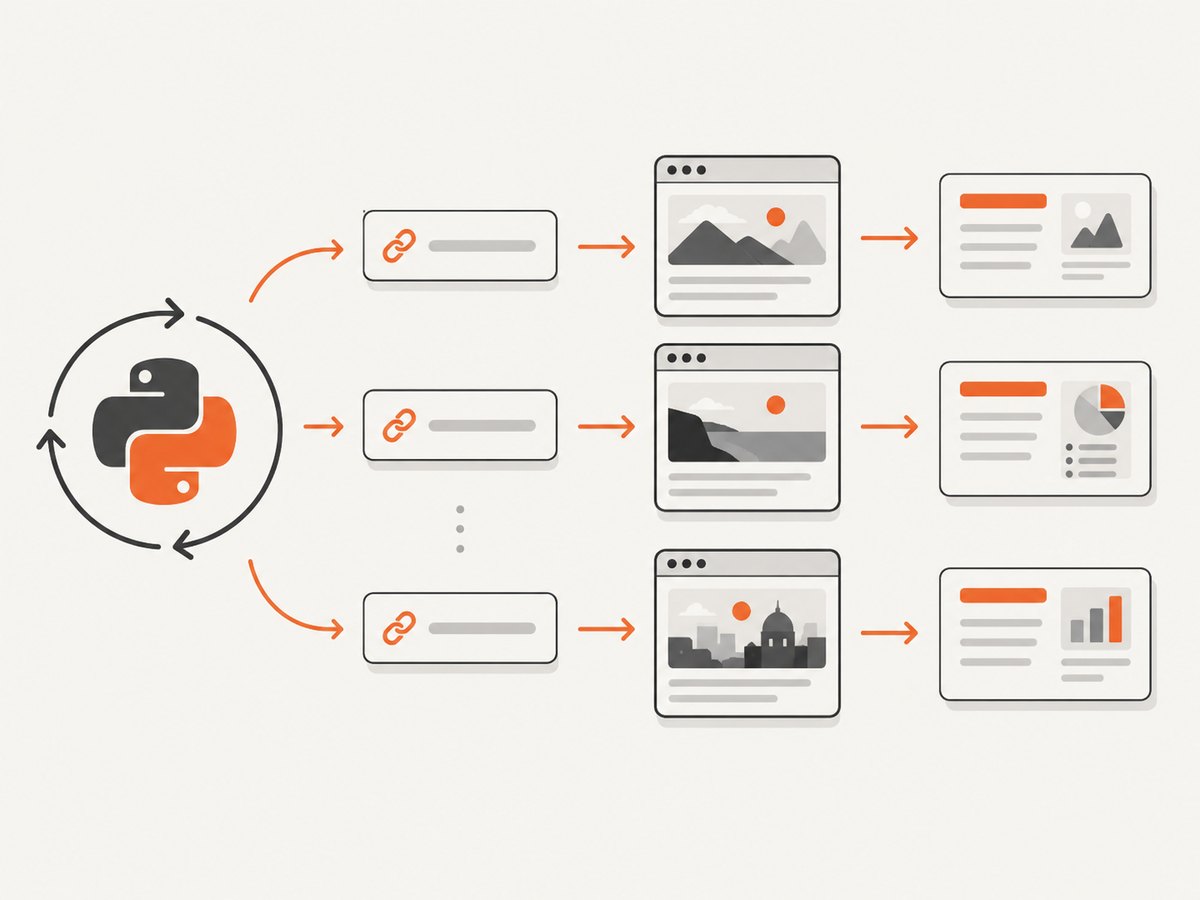
Loop through multiple URLs
import asyncio
from pyppeteer import launch

URLS = ["https://example.com", "https://example.org", "https://example.net"]

async def collect(urls):
    browser = await launch({"headless": True})
    results = []
    try:
        page = await browser.newPage()
        for url in urls:
            try:
                response = await page.goto(url, {"waitUntil": "domcontentloaded", "timeout": 30000})
                results.append({"url": url, "status": response.status if response else None, "title": await page.title(), "error": None})
            except Exception as exc:
                results.append({"url": url, "status": None, "title": None, "error": str(exc)})
    finally:
        await browser.close()
    return results

async def main():
    for result in await collect(URLS):
        print(result)

asyncio.run(main())
Use domcontentloaded for document readiness, load when load-event resources matter, or networkidle0/networkidle2 when the page settles. Set a timeout so one URL cannot block the batch indefinitely.
Where does await go inside a Pyppeteer loop?
for url in urls:
    await page.goto(url)
    await page.waitForSelector("main")
    heading = await page.querySelectorEval("h1", "el => el.textContent")
    html = await page.content()
    print(url, heading, len(html))
Pyppeteer uses names such as querySelector, querySelectorAll, and xpath; do not paste JavaScript Puppeteer syntax blindly.
Waiting for dynamic content
await page.waitForSelector(".product")waits for a required element.await page.waitFor(1000)is a fixed delay and is less robust.await page.waitForFunction("() => document.querySelectorAll('.product').length > 0")waits for a condition.
Python loop or page.evaluate?
Use Python iteration when items come from Python or each item needs navigation, waiting, or another Pyppeteer call. Use page.evaluate for a transformation inside the current document.
rows = await page.evaluate("""() => Array.from(
    document.querySelectorAll('table tbody tr'),
    row => Array.from(row.cells, cell => cell.textContent.trim())
)""")
page.evaluate accepts a JavaScript function or expression and returns its result. If automatic detection treats an expression as a function, pass force_expr=True:
count = await page.evaluate("document.querySelectorAll('.item').length", force_expr=True)A JavaScript loop in evaluate stays in one page; it does not replace a Python loop that navigates between URLs.
Useful patterns
Links from one page
links = await page.evaluate("""() => Array.from(document.querySelectorAll('a[href]'), a => a.href)""")
for link in links:
    await page.goto(link, {"waitUntil": "domcontentloaded"})
    print(await page.title())
Elements in the current page
cards = await page.querySelectorAll(".card")
for card in cards:
    print(await page.evaluate("el => el.textContent.trim()", card))
Fresh page per URL
for url in urls:
    page = await browser.newPage()
    try:
        await page.goto(url, {"waitUntil": "domcontentloaded"})
        print(await page.title())
    finally:
        await page.close()
Reuse one page when shared state is acceptable. Use separate pages when cookies, storage, or page state must be isolated.
Sequential versus concurrent loops
A loop with await is sequential: the next iteration starts after the current awaited calls finish. That is the clearest choice when order matters or one page is reused. Concurrency needs explicit task management, page ownership, exception collection, resource caps, and respect for site limits. The supplied Pyppeteer sources do not establish a universal safe concurrency limit.
Reliability checklist
| Area | Choice |
|---|---|
| Navigation | Pick the least strict waitUntil event that satisfies extraction. |
| Timeouts | Set navigation and selector timeouts; log URL and iteration. |
| Selectors | Prefer stable attributes and handle optional elements. |
| State | Reuse a page for speed; isolate pages when state can leak. |
| Cleanup | Close browser and temporary pages in finally. |
Troubleshooting
Coroutine was never awaited
You called a coroutine without await. Move it into async def and await it.
Event-loop errors
Notebook and server runtimes may own the loop. Use their integration model; use asyncio.run(main()) for a standalone script.
Navigation timeout
Slow resources or endless polling can prevent a network-idle event. Increase the timeout, use domcontentloaded, or wait for a specific selector.
Missing selector
The element may be late, absent, inside an iframe, or in shadow DOM. Wait for it, inspect frames, choose a stable selector, and handle optional content.
evaluate function/expression error
Automatic detection chose the wrong mode. Use force_expr=True for an expression or pass a JavaScript function string.
Chromium launch failure
Check the current README for executable and environment requirements, provide a valid executable path when needed, and record the launch exception.
Performance, reliability, and cost
- Reuse a browser and page when isolation is unnecessary.
- Prefer selector or condition waits over arbitrary sleeps.
- Extract multiple fields in one
evaluatecall. - Record per-URL errors so one failure is diagnosable.
- Each page consumes browser resources; cap concurrency deliberately.
- Your cost is the compute, memory, network, and Chromium maintenance of your runtime; no universal benchmark is established by the sources.
Or skip the browser setup
ScreenshotNeo provides a one-request screenshot API and an MCP server. Cookie/consent banners, newsletter popups, and chat widgets are removed before capture. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and X-Page-Verdict and X-Billed report the result. AI agents can call take_screenshot, get_page_info, and capture_pdf.
See the ScreenshotNeo docs. The same loop can call:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Options include full-page and element capture, dark mode, device and retina settings, PDFs, custom CSS and JavaScript, waits, headers/cookies, blocking rules, caching, signed links, async jobs, bulk capture, and usage reporting. Every feature is on every plan: 1,000 shots monthly free with no card; paid plans start at $5 for 3,000.
Create a free ScreenshotNeo account for 1,000 screenshots a month with no card.
FAQ
Is for a Pyppeteer method?
No. It is Python syntax around awaited browser calls.
Can one page handle every URL?
Yes, when shared cookies and storage are acceptable.
When should I use evaluate?
For a browser-side transformation of the current DOM; use Python iteration for navigation and orchestration.
Does Pyppeteer guarantee parallel safety?
No universal limit or recipe is established in the supplied sources; add concurrency only with explicit controls.


