Python CSS Selectors and How to Use Them
Learn CSS selectors in Python with Beautiful Soup, lxml, and selectolax, including runnable examples, syntax, troubleshooting, and dynamic-page options.
CSS selectors are patterns that identify elements in an HTML tree. In Python, you use them after parsing HTML with a library such as Beautiful Soup, lxml, or selectolax. The selector itself does not download a page, execute JavaScript, or create a rendered browser DOM. It only matches nodes that exist in the tree given to the selector engine.
For most scripts, the quickest path is Beautiful Soup:
from bs4 import BeautifulSoup

html = """
<article class="story">
  <h2>Example</h2>
  <a href="/read">Read more</a>
</article>
"""

soup = BeautifulSoup(html, "html.parser")

headings = soup.select("article.story h2")
first_link = soup.select_one("article.story a[href]")

print(headings[0].get_text(strip=True))
print(first_link["href"])
select() returns every match. select_one() returns the first match or None. Both methods are available on the soup object and on individual Tag objects, so you can scope a search to one section of a document.
What a CSS selector means
MDN describes selectors as patterns used by CSS rules to target elements. The same families of patterns are useful when searching parsed HTML. The parser and selector engine determine which parts of the CSS selector specification are supported; a selector copied from browser developer tools is not automatically portable to every Python package.

| Goal | Selector | Meaning |
|---|---|---|
| Match a tag | p |
Every paragraph element |
| Match a class | .product |
Elements whose class list contains product |
| Match an ID | #content |
The element with that ID |
| Match an attribute | [href] |
Elements that have an href attribute |
| Match an attribute pattern | [href^="https"] |
href values beginning with https |
| Find descendants | main a |
Links anywhere below main |
| Find direct children | ul > li |
li elements directly under ul |
| Match a position | li:nth-of-type(2) |
The second li among its siblings |
| Group alternatives | h1, h2 |
Either an h1 or an h2 |
See the MDN selector reference for the selector families and syntax definitions.
Using Beautiful Soup selectors
Install and parse HTML
python -m pip install beautifulsoup4 requestsimport requests
from bs4 import BeautifulSoup
response = requests.get("https://example.com", timeout=30)
response.raise_for_status()
soup = BeautifulSoup(response.text, "html.parser")
for link in soup.select("main a[href]"):
print(link.get_text(" ", strip=True), link["href"])Beautiful Soup’s documented selector interface is implemented by Soup Sieve, installed with Beautiful Soup. The project documentation calls CSS selector support “a convenience for people who already know the CSS selector syntax.”
Scope a selector to one element
article = soup.select_one("article.story")
if article is None:
    raise ValueError("story article was not found")

for heading in article.select("h2, h3"):
    print(heading.get_text(" ", strip=True))
Calling select() on a Tag searches only inside that tag. This prevents unrelated navigation, footer, or sidebar content from being included.
Read attributes safely
for image in soup.select("img[src]"):
    source = image.get("src")
    alt = image.get("alt", "")
    print(source, alt)
Use get() when an attribute may be missing. Direct indexing such as image["src"] raises KeyError if the attribute is absent.
Extract normalized text
node = soup.select_one(".price")
price_text = node.get_text(" ", strip=True) if node else None
The separator argument preserves readable spacing when text is split across nested elements. Always handle a missing match before reading text or attributes.
Using lxml and cssselect
lxml provides a CSSSelector class that compiles a CSS expression to XPath and can evaluate it against a document or element. Its Element.cssselect() method is a convenience API. The lxml documentation also notes that precompiling a selector or XPath expression can provide a substantial speedup in repeated workloads; treat that as library guidance and measure your own input.
python -m pip install lxml cssselectfrom lxml.cssselect import CSSSelector
from lxml.html import fromstring
html = "<main><p class='intro'>Hello</p></main>"
document = fromstring(html)
selector = CSSSelector("main > p.intro")
matches = selector(document)
print(matches[0].text_content())For a one-off query, the element convenience method is concise:
from lxml.html import fromstring

document = fromstring("<ul><li>A</li><li>B</li></ul>")
for item in document.cssselect("ul > li"):
    print(item.text_content())
Compile once for repeated searches
from lxml.cssselect import CSSSelector

select_cards = CSSSelector("article.card[data-id]")
for document in documents:
    for card in select_cards(document):
        print(card.get("data-id"))
The separate cssselect project translates CSS3 selector groups to XPath 1.0. Translation produces an XPath string; an XPath-capable library such as lxml must evaluate it.
from cssselect import HTMLTranslator, SelectorError

try:
    xpath = HTMLTranslator().css_to_xpath("div.content")
    print(xpath)
except SelectorError as exc:
    print(f"Invalid or unsupported selector: {exc}")
cssselect distinguishes syntax errors from selectors it cannot translate. Catch SelectorError at configuration or input boundaries rather than silently returning an empty result.
Selectolax as another option
selectolax is an HTML5 parser with a CSS selector interface, written in Cython. Its retrieved documentation identifies Lexbor as the preferred backend and describes the older Modest backend as deprecated. Backend and version details can change, so check the current project documentation before pinning a dependency.
python -m pip install selectolaxfrom selectolax.parser import HTMLParser
html = "<div class='product'><h2>Keyboard</h2></div>"
tree = HTMLParser(html)
for node in tree.css(".product h2"):
print(node.text(strip=True))Choose the library that fits your surrounding code: Beautiful Soup for a familiar search API, lxml when XPath integration and compiled selectors matter, or selectolax when you want an HTML5 parser with CSS selection. The cited projects do not establish a universal speed ranking.
Why a browser selector may fail in Python
- The HTML is different. Browser developer tools show a live DOM. Your parser may have received a different response, a redirect page, or an error document.
- JavaScript added the element. A plain HTTP response does not automatically include content created later by client-side code. A selector cannot match a node that is absent from the parsed tree.
- The selector uses unsupported syntax. Selector support varies between Soup Sieve, lxml/cssselect, and selectolax. Check each engine’s support documentation.
- The selector is too specific. Generated class names, deep ancestry, and positional assumptions break when a site changes its markup.
- You selected a class incorrectly. Use
.namefor a class,#namefor an ID, and[name]for an attribute.
Debug from the outside in:
print(response.status_code)
print(response.url)
print(response.text[:500])
print(len(soup.select("article")))
print(soup.select_one(".price"))
Start with a short selector such as .price or article a, then add one condition at a time. Save a representative response fixture so selector changes can be tested without repeatedly requesting a live site.
Reliable selector design
- Prefer stable semantic attributes such as
data-testid,data-id, or an application-specific class. - Use descendant selectors when intermediate wrappers are layout-only.
- Use direct-child selectors only when the HTML contract requires that exact structure.
- Guard every optional match and record missing fields rather than crashing an entire batch.
- Normalize URLs with
urllib.parse.urljoinwhen extracting relative links. - Keep selectors in named constants so markup changes have one maintenance point.
- Do not assume
nth-childremains stable when ads, featured items, or hidden nodes can be inserted.
from urllib.parse import urljoin

CARD_SELECTOR = "article.product[data-id]"

for card in soup.select(CARD_SELECTOR):
    title = card.select_one("h2, h3")
    link = card.select_one("a[href]")
    if not title or not link:
        continue
    record = {
        "id": card.get("data-id"),
        "title": title.get_text(" ", strip=True),
        "url": urljoin(response.url, link["href"]),
    }
    print(record)
Dynamic pages and rendered screenshots
If the target element appears only after JavaScript runs, fetch the rendered page with a browser automation tool, or capture a rendered page and inspect its HTML through a workflow designed for browser execution. A parser alone cannot create that runtime state.
Or skip the browser setup
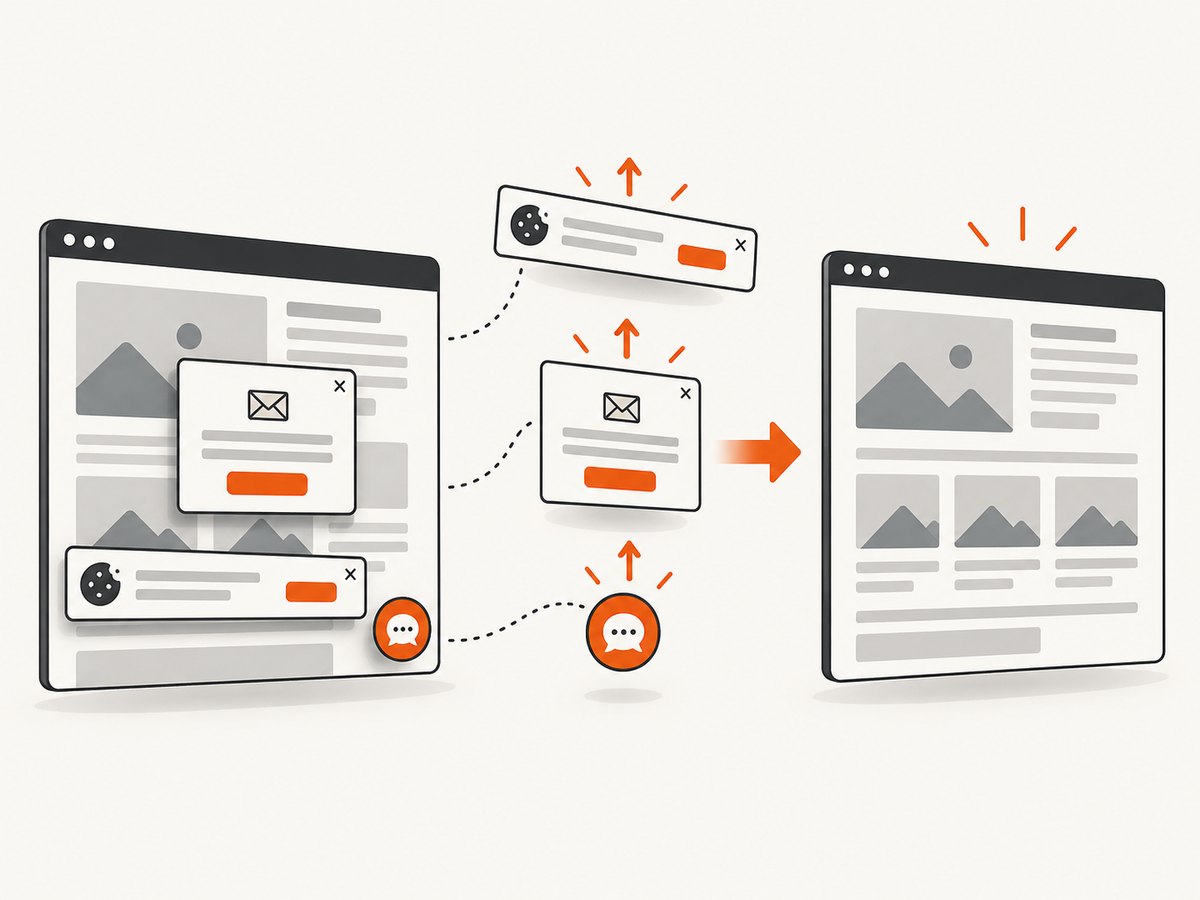
ScreenshotNeo provides a website screenshot API and MCP server. One GET request returns a PNG, JPEG, WebP, or PDF. It can accept cookie banners before capture and remove more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, and the response identifies the result with X-Page-Verdict and X-Billed headers.
cURL:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
Python:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('shot.webp', buffer);
See the ScreenshotNeo API documentation for the full option set. Relevant controls include full-page capture with lazy images loaded, CSS element capture, dark mode, 12 device presets or custom viewports, retina scale, PDF paper sizes and page ranges, custom CSS and JavaScript, clicks, selector or network-idle waits, request and resource blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, configurable cache TTL, signed image links, asynchronous jobs with signed webhooks, bulk capture for up to 100 URLs, a usage API, and an OpenAPI specification. Existing parameter names used by other screenshot APIs also work to ease migration.
An MCP server exposes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. Plans include 1,000 free shots each month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
Performance, reliability, and cost notes
- Parsing cost: parse once and reuse the tree for several selectors. Compile lxml selectors when applying the same expression repeatedly.
- Network reliability: set explicit request timeouts, call
raise_for_status(), and retry only transient failures with backoff. - Input size: avoid loading unnecessarily large documents when the source can provide a focused endpoint or fragment.
- Selector reliability: add fixture-based tests for representative markup and monitor the rate of missing matches.
- Screenshot cost: ScreenshotNeo bills only clean shots; failed loads, bot checks, blank pages, timeouts, and cache hits are not billed. Cache TTL, bulk calls, and asynchronous jobs can reduce repeated work, while response verdict headers make accounting inspectable.
Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
select() returns an empty list |
Element is absent from the parsed HTML | Print the response prefix, status, final URL, and a simpler selector. |
select_one() returns None |
No match or a changed class/ID | Check the markup and guard the optional result. |
| Browser selector works, parser selector fails | Live DOM differs from the HTTP response | Use rendered capture or obtain the underlying data endpoint. |
lxml raises SelectorError |
Invalid or unsupported CSS expression | Reduce the selector and check cssselect/lxml support. |
KeyError on an attribute |
Matched element lacks that attribute | Use node.get("attribute") and handle None. |
| Wrong text is extracted | Selector includes nested navigation or hidden content | Scope to the article/card and normalize with get_text(" ", strip=True). |
| Screenshot is blank or blocked | Bot check, timeout, failed load, or consent overlay | Inspect ScreenshotNeo’s X-Page-Verdict and X-Billed headers; adjust waits, headers, or blocking options. |
FAQ
Are CSS selectors XPath?
No. CSS selectors and XPath are different query languages. lxml and cssselect can translate CSS selectors into XPath so lxml can evaluate them.
Which Python library should I start with?
Start with Beautiful Soup when you want the most approachable API. Choose lxml when XPath interoperability or repeated compiled queries is central. Consider selectolax when its parser and backend fit your deployment.
Can a selector execute JavaScript?
No. It searches an already parsed tree. JavaScript-generated content requires a browser-rendering step or another source that contains the generated data.
Why does nth-child change unexpectedly?
It depends on sibling position. Inserted advertisements, wrappers, or hidden elements can change that position. Prefer semantic classes or stable data attributes.
How do I avoid paying for failed screenshots?
With ScreenshotNeo, bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response reports its page verdict and billing status.


