How to Build a Website Monitoring Script in Python
Build a reliable Python website monitor with timeouts, retries, content checks, stateful alerts, security controls, and production guidance.
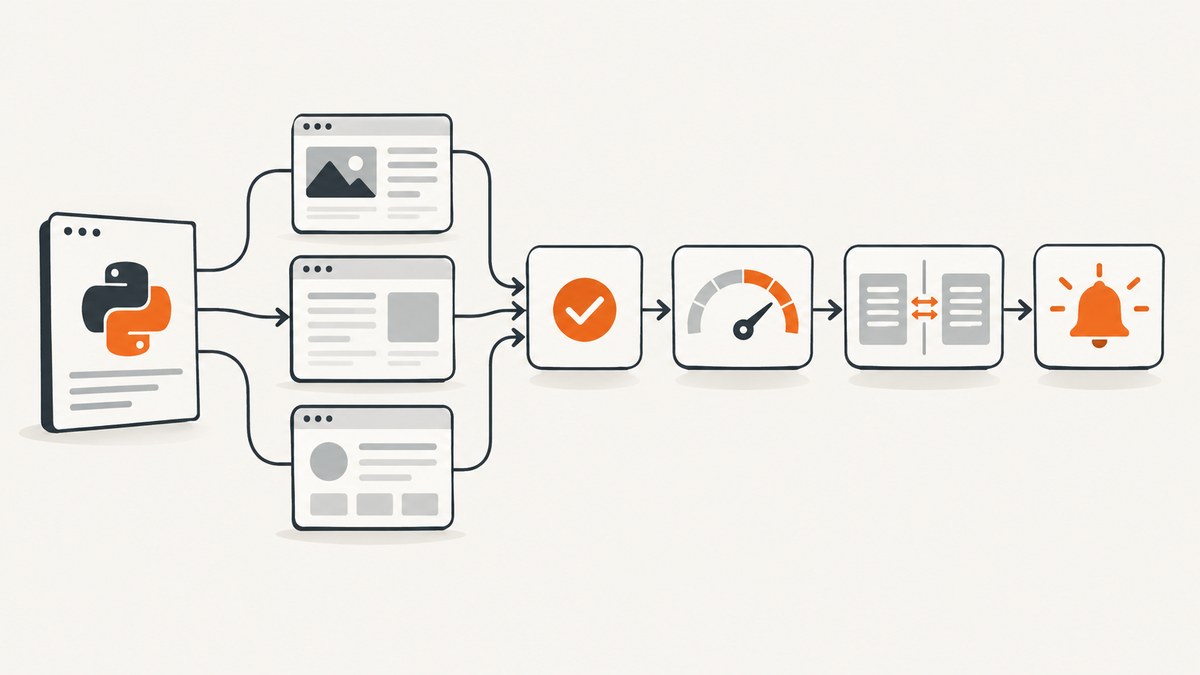
A useful website monitor does more than request a URL and check for status 200. It needs explicit timeouts, exception handling, redirect and latency reporting, optional content checks, persistent state, transition-based alerts, safe scheduling, and protections against monitoring the wrong destination.
This guide builds a complete Python monitor with those pieces. It uses a persistent requests.Session, bounded retries, health policies, normalized content hashes, JSON state, and webhook notifications.
1. Install the dependencies
python -m venv .venv
source .venv/bin/activate       # Windows: .venv\\Scripts\\activate
pip install requests
The monitor uses the Requests HTTP library. Requests exposes status codes, redirects, timeouts, exceptions, TLS verification, and connection reuse through sessions.
2. Define monitored URLs and health policies
Keep the URL and its expected policy together. A policy can require accepted status codes and an optional text marker. A marker catches cases where a server returns HTTP 200 but serves an error page or incomplete response.
MONITORS = [
    {
        "name": "Example home page",
        "url": "https://example.com/",
        "accepted_statuses": {200},
        "required_text": None,
        "timeout": (5, 20),       # connect timeout, read timeout
        "allow_redirects": True,
    },
    {
        "name": "Application health page",
        "url": "https://app.example.com/health",
        "accepted_statuses": {200},
        "required_text": "healthy",
        "timeout": (5, 10),
        "allow_redirects": False,
    },
]
Decide how redirects should be classified before deployment. Some sites intentionally redirect HTTP to HTTPS; others should never redirect from a health endpoint. Record both the original and final URL.
3. Complete monitoring script
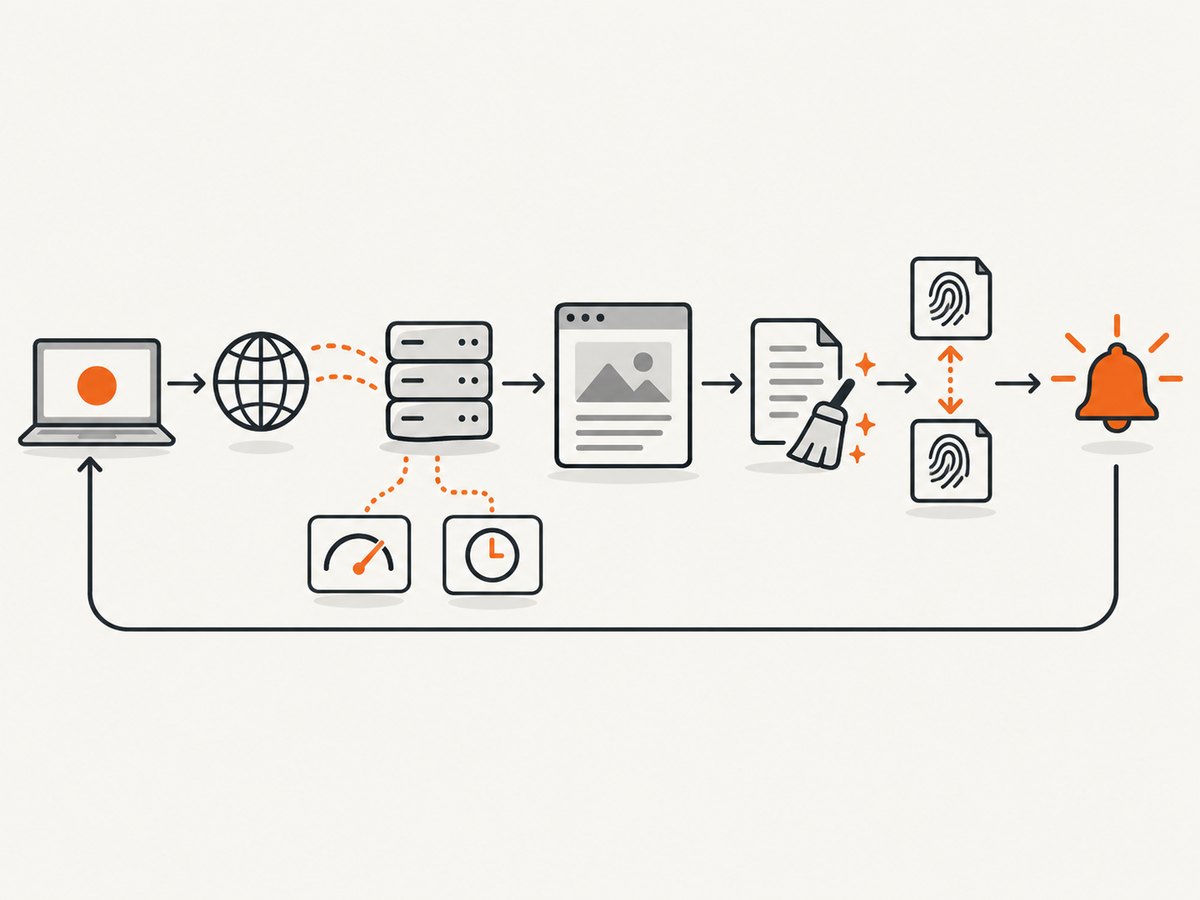
Save this as monitor.py. It records status, elapsed time, redirect destination, response size, exception details, and content results. It alerts only when a monitor changes state.
#!/usr/bin/env python3
import hashlib
import json
import logging
import os
import re
import sys
import time
from dataclasses import asdict, dataclass
from datetime import datetime, timezone
from pathlib import Path
from typing import Optional

import requests
from requests.adapters import HTTPAdapter
from urllib3.util.retry import Retry

STATE_FILE = Path(os.getenv("MONITOR_STATE_FILE", "monitor-state.json"))
WEBHOOK_URL = os.getenv("MONITOR_WEBHOOK_URL")
USER_AGENT = os.getenv(
    "MONITOR_USER_AGENT",
    "website-monitor/1.0 (+https://example.com/monitor-info)",
)

MONITORS = [
    {
        "name": "Example home page",
        "url": "https://example.com/",
        "accepted_statuses": {200},
        "required_text": None,
        "timeout": (5, 20),
        "allow_redirects": True,
    },
]

logging.basicConfig(
    level=os.getenv("LOG_LEVEL", "INFO"),
    format="%(asctime)s %(levelname)s %(message)s",
)
log = logging.getLogger("website-monitor")


@dataclass
class CheckResult:
    name: str
    url: str
    checked_at: str
    outcome: str
    status_code: Optional[int] = None
    final_url: Optional[str] = None
    elapsed_ms: Optional[float] = None
    content_hash: Optional[str] = None
    exception_type: Optional[str] = None
    exception_message: Optional[str] = None
    detail: Optional[str] = None


def utc_now():
    return datetime.now(timezone.utc).isoformat()


def load_state():
    if not STATE_FILE.exists():
        return {}
    try:
        return json.loads(STATE_FILE.read_text())
    except (OSError, json.JSONDecodeError) as exc:
        log.warning("Could not read state file: %s", exc)
        return {}


def save_state(state):
    temporary = STATE_FILE.with_suffix(".tmp")
    temporary.write_text(json.dumps(state, indent=2, sort_keys=True))
    temporary.replace(STATE_FILE)


def normalize_content(text):
    # Remove common volatile values before comparing pages.
    text = re.sub(r"\\b20\\d{2}[-/]\\d{1,2}[-/]\\d{1,2}\\b", "", text)
    text = re.sub(r"\\b\\d{1,2}:\\d{2}(?::\\d{2})?\\b", "", text)
    text = re.sub(r"\\s+", " ", text).strip()
    return text


def content_hash(response):
    normalized = normalize_content(response.text)
    return hashlib.sha256(normalized.encode("utf-8", "replace")).hexdigest()


def build_session():
    session = requests.Session()
    retry = Retry(
        total=2,
        connect=2,
        read=2,
        status=0,                 # Do not retry HTTP failures by default.
        backoff_factor=0.5,
        allowed_methods=frozenset({"GET", "HEAD"}),
        raise_on_status=False,
    )
    adapter = HTTPAdapter(max_retries=retry, pool_connections=10, pool_maxsize=10)
    session.mount("https://", adapter)
    session.mount("http://", adapter)
    session.headers.update({"User-Agent": USER_AGENT, "Accept": "text/html,application/xhtml+xml"})
    return session


def check_one(session, policy):
    started = time.perf_counter()
    try:
        response = session.get(
            policy["url"],
            timeout=policy.get("timeout", (5, 20)),
            allow_redirects=policy.get("allow_redirects", True),
            verify=True,
        )
        elapsed_ms = round((time.perf_counter() - started) * 1000, 1)
        digest = content_hash(response)
        accepted = response.status_code in policy.get("accepted_statuses", {200})
        required = policy.get("required_text")
        marker_ok = required is None or required in response.text

        if not accepted:
            outcome = "client_error" if 400 <= response.status_code < 500 else "server_error" if response.status_code >= 500 else "unexpected_status"
            detail = f"HTTP {response.status_code}"
        elif not marker_ok:
            outcome, detail = "unexpected_content", "required text was not found"
        else:
            outcome, detail = "healthy", None

        return CheckResult(
            name=policy["name"], url=policy["url"], checked_at=utc_now(),
            outcome=outcome, status_code=response.status_code,
            final_url=response.url, elapsed_ms=elapsed_ms,
            content_hash=digest, detail=detail,
        )
    except requests.exceptions.ConnectTimeout as exc:
        outcome = "connect_timeout"
    except requests.exceptions.ReadTimeout as exc:
        outcome = "read_timeout"
    except requests.exceptions.SSLError as exc:
        outcome = "tls_failure"
    except requests.exceptions.ConnectionError as exc:
        outcome = "dns_or_connection_failure"
    except requests.exceptions.RequestException as exc:
        outcome = "request_failure"
    except Exception as exc:
        outcome = "unexpected_exception"

    elapsed_ms = round((time.perf_counter() - started) * 1000, 1)
    return CheckResult(
        name=policy["name"], url=policy["url"], checked_at=utc_now(),
        outcome=outcome, elapsed_ms=elapsed_ms,
        exception_type=type(exc).__name__, exception_message=str(exc),
    )


def notify(message):
    if not WEBHOOK_URL:
        log.warning(message)
        return
    try:
        response = requests.post(WEBHOOK_URL, json={"text": message}, timeout=(5, 10))
        response.raise_for_status()
    except requests.RequestException as exc:
        log.error("Notification failed: %s", exc)


def main():
    state = load_state()
    session = build_session()
    changed = False

    for policy in MONITORS:
        result = check_one(session, policy)
        current = asdict(result)
        previous = state.get(policy["name"], {})
        previous_outcome = previous.get("outcome")
        previous_hash = previous.get("content_hash")

        if previous_outcome and previous_outcome != result.outcome:
            notify(f"{result.name}: {previous_outcome} -> {result.outcome} ({result.url})")
        if (
            result.outcome == "healthy"
            and previous_hash
            and result.content_hash != previous_hash
        ):
            notify(f"{result.name}: meaningful content change detected ({result.url})")

        log.info("%s: %s status=%s elapsed_ms=%s", result.name, result.outcome, result.status_code, result.elapsed_ms)
        state[policy["name"]] = current
        changed = True

    if changed:
        save_state(state)


if __name__ == "__main__":
    try:
        main()
    except KeyboardInterrupt:
        sys.exit("Interrupted")
Run it once with python monitor.py. The first run creates the state file; later runs can detect recovery, failure transitions, and content changes.
4. Understand the result classifications
| Outcome | Meaning | Typical action |
|---|---|---|
| healthy | Status and optional marker passed | Record latency and continue |
| client_error | 4xx response | Check authentication, URL, or access policy |
| server_error | 5xx response | Alert after the chosen retry policy |
| unexpected_content | Status passed but required text was absent | Inspect deployments and upstream failures |
| connect_timeout | Connection could not be established in time | Check DNS, firewall, and origin capacity |
| read_timeout | Server connected but did not finish responding | Check application latency and response size |
| tls_failure | Certificate or TLS negotiation failed | Inspect certificate chain, hostname, and expiration |
| dns_or_connection_failure | DNS lookup or socket connection failed | Check DNS records and network access |
Status code alone is insufficient. A redirect can be valid or a defect, and a 200 response can contain an outage page. Keep the final URL, response time, and content policy in the result.
5. Schedule checks without notification floods
Run the script from the host operating system or a Python scheduler. Keep the interval within the site’s terms, robots guidance, and capacity. The state file makes alerts transition-based instead of sending the same failure repeatedly.
cron
*/5 * * * * cd /opt/site-monitor && /opt/site-monitor/.venv/bin/python monitor.py >> monitor.log 2>&1systemd timer
# /etc/systemd/system/site-monitor.service
[Unit]
Description=Website monitor

[Service]
Type=oneshot
WorkingDirectory=/opt/site-monitor
ExecStart=/opt/site-monitor/.venv/bin/python monitor.py

# /etc/systemd/system/site-monitor.timer
[Unit]
Description=Run website monitor every five minutes

[Timer]
OnBootSec=2min
OnUnitActiveSec=5min

[Install]
WantedBy=timers.target
6. Monitor content changes safely
Hash a stable region rather than an entire page when possible. Full-page hashes change because of clocks, rotating ads, counters, recommendations, CSRF tokens, and personalization. Parse the relevant HTML with an HTML parser, select a stable element, remove known volatile nodes, normalize whitespace, and then hash the result.
Do not treat every content change as an outage. Separate health checks from change detection and require a meaningful transition before notifying.
7. Retries, pooling, and scale
A persistent session reuses connections. For larger monitors, urllib3 provides pooling, retry helpers, redirect handling, compression, proxy support, TLS verification, and thread-safe components; see the urllib3 documentation. Its retry policy should distinguish transient connection failures from deterministic HTTP failures, use exponential backoff, and cap attempts.
Do not retry every 4xx or 5xx response automatically. Retries multiply traffic and can hide a persistent failure. Add jitter when many workers run on the same schedule. Bound concurrency with a small worker pool and respect each site’s rate limits.
8. Security and operational controls
- Keep TLS certificate verification enabled. Disable it only for a documented, controlled test.
- Use an honest User-Agent and provide an information page when appropriate.
- Store webhook URLs, API keys, cookies, and authorization values in environment variables or a secret manager.
- Never log credentials or full sensitive response bodies.
- If users can submit URLs, allow only
httpandhttps, validate hostnames, and block loopback, private, link-local, metadata, and other reserved destinations. This prevents server-side request forgery. - Set response-size limits if monitoring untrusted targets.
- Check authorization, terms, and robots guidance before polling a site.
9. Troubleshooting
| Symptom | Cause | Fix |
|---|---|---|
| The process hangs | No timeout was set | Set separate connect and read timeouts on every request. |
| Repeated duplicate alerts | Every run sends a notification | Persist the prior outcome and alert only on transitions. |
| False content changes | Dynamic timestamps or ads are included | Select a stable region and normalize volatile values. |
| HTTP 200 but the service is broken | Error page returned with success status | Require a stable marker or structured health response. |
| Too many requests | Polling is too frequent or retries are unbounded | Increase the interval, cap retries, add backoff and jitter. |
| SSL verification error | Expired, mismatched, or incomplete certificate chain | Fix the certificate or trust store; keep verification enabled. |
| DNS failures | Missing, stale, or unreachable DNS record | Check authoritative DNS, resolver logs, and network policy. |
| Redirect classified incorrectly | Redirect policy was not explicit | Set allow_redirects and accepted final URLs for the endpoint. |
| State file is corrupt | Process stopped during a write | Use the temporary-file replacement pattern shown above and restore from backup if needed. |
10. When a script is no longer enough
A custom script fits a small URL list, a known schedule, and simple alert rules. Consider a monitoring platform when you need persistent history, dashboards, concurrent probes, DNS/SSL/port checks, content-change detection, coordinated alert routing, reports, Prometheus metrics, or built-in SSRF protections. The website-monitoring-automation project documents these types of capabilities.
11. Or skip the browser setup
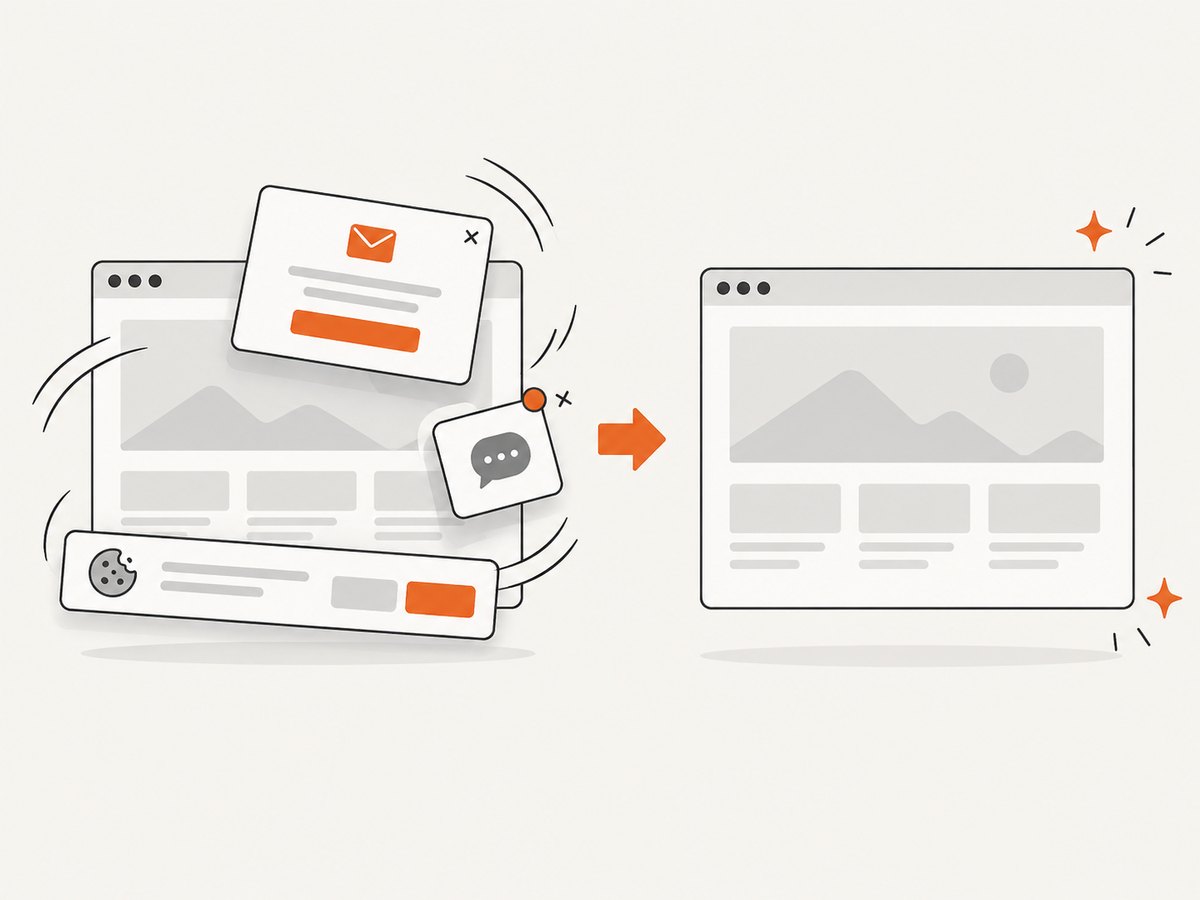
If you need screenshots as part of visual monitoring, ScreenshotNeo provides a website screenshot API and MCP server. It accepts one GET request and returns PNG, JPEG, WebP, or PDF. Before capture it can accept cookie banners and remove more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the page verdict and billing status in X-Page-Verdict and X-Billed headers.
See the ScreenshotNeo API documentation for all options. Basic call:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const fs = require('node:fs');
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
fs.writeFileSync('shot.webp', Buffer.from(await res.arrayBuffer()));ScreenshotNeo also supports full-page capture with lazy images loaded, CSS element capture, dark mode, device presets, custom viewports, retina scale, PDF options, custom CSS and JavaScript, clicks, selector waits, delays, network-idle waits, request blocking, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, TTL caching, signed links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs per call, a usage API, and an OpenAPI specification. Its MCP server includes take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients.
Free usage includes 1,000 screenshots per month with no card. Paid plans start at $5 for 3,000 shots, and every feature is available on every plan. Create a free ScreenshotNeo account.
12. FAQ
Should I use HEAD instead of GET?
HEAD is cheaper when the server implements it correctly, but it cannot validate page content and some servers handle it incorrectly. Use GET for content checks and compare results.
How should I choose timeouts?
Use a short connect timeout and a read timeout that matches the endpoint’s normal response behavior. Always bound both; there is no safe infinite wait in a monitoring loop.
Should redirects count as healthy?
That depends on the endpoint. Follow redirects for normal public pages, but explicitly validate the final URL or reject redirects for health endpoints where they indicate misconfiguration.
How do I monitor authenticated pages?
Use a dedicated low-privilege account and keep cookies or authorization values in a secret manager. Redact them from logs and validate that the monitor cannot be redirected to an untrusted host.
When should I add a monitoring service?
Move when you need many probe types, persistent history, metrics, reports, concurrent checks, or coordinated alert routing that would be costly to maintain in one script.


