How to Render CSS-Embedded Images in iTextSharp HTML-to-PDF Conversion
Render CSS images reliably in iTextSharp: XML Worker setup, pdfHTML migration, data URIs, resource paths, troubleshooting, and working C# examples.
Direct answer: For legacy iTextSharp (iText 5), use XML Worker instead of the obsolete HTMLWorker when your XHTML depends on CSS. Pass well-formed, finished XHTML and make every stylesheet and image resource resolvable. XML Worker is not a browser: it does not execute JavaScript or render an arbitrary live web page. For newer projects, evaluate iText pdfHTML; its official .NET example demonstrates Base64 images in an HTML <img>, but that example does not prove that every legacy XML Worker version supports a data URI inside CSS background-image. Test the exact XML Worker version and markup you deploy.
1. Choose the conversion path
| Path | Use it when | Verify first |
|---|---|---|
| iTextSharp 5 + XML Worker | You maintain an existing .NET application and convert controlled XHTML with supported CSS. | XML Worker version, XHTML validity, supported CSS properties, resource paths, and whether the image is an <img> or a CSS background. |
| iText pdfHTML | You can use a newer iText add-on and need broader HTML/CSS support. | The feature list for your release, .NET integration, base URI for relative resources, JavaScript requirements, and licensing. |
iText documents HTMLWorker as limited and says it does not parse CSS files. XML Worker is the documented iText 5 XHTML/CSS route: iText XML Worker guidance.
2. Minimal XML Worker conversion in C#
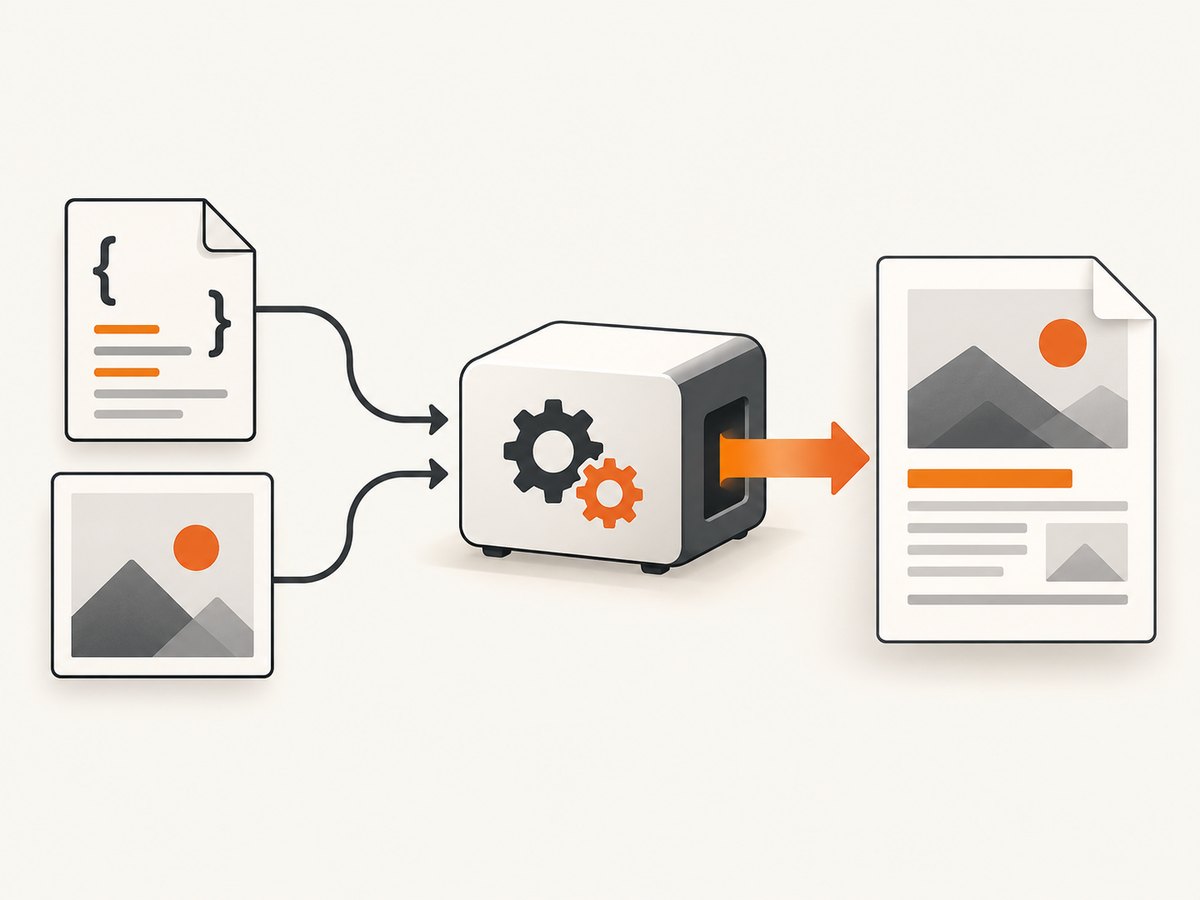
This example converts a complete XHTML string with an inline CSS background. It uses the documented XMLWorkerHelper.GetInstance().ParseXHtml call. Replace the image data with a case that matches your application.
using System;
using System.IO;
using iTextSharp.text;
using iTextSharp.text.pdf;
using iTextSharp.tool.xml;

public static class PdfRenderer
{
    public static void Render(string outputPath)
    {
        const string html = @"<!DOCTYPE html>
<html xmlns='http://www.w3.org/1999/xhtml'>
<head>
  <meta charset='UTF-8' />
  <style>
    @page { margin: 36pt; }
    body { font-family: Helvetica, sans-serif; }
    .hero {
      height: 180px;
      background-image: url('data:image/png;base64,REPLACE_WITH_BASE64');
      background-repeat: no-repeat;
      background-position: center;
      background-size: contain;
    }
  </style>
</head>
<body>
  <div class='hero'></div>
  <h1>Report</h1>
</body>
</html>";

        using (var stream = new FileStream(outputPath, FileMode.Create, FileAccess.Write))
        using (var document = new Document(PageSize.A4))
        {
            var writer = PdfWriter.GetInstance(document, stream);
            document.Open();
            using (var reader = new StringReader(html))
            {
                XMLWorkerHelper.GetInstance().ParseXHtml(writer, document, reader);
            }
            document.Close();
        }
    }
}
XML Worker expects finished XHTML. Generate the final markup before conversion, close the document after parsing, and keep the writer/document lifecycle valid.
3. Supplying CSS and images as resources
For external stylesheets or image files, use an overload that receives CSS and HTML streams, and provide paths that the converter can resolve. A relative URL such as images/header.png only works when the resource provider or working directory maps it correctly.
using System.IO;
using iTextSharp.text;
using iTextSharp.text.pdf;
using iTextSharp.tool.xml;
using iTextSharp.tool.xml.pipeline;
using iTextSharp.tool.xml.pipeline.css;
using iTextSharp.tool.xml.pipeline.html;
using iTextSharp.tool.xml.pipeline.end;
using iTextSharp.tool.xml.pipeline.html dual;

// Simpler documented stream overload:
using (var htmlReader = File.OpenText("report.xhtml"))
using (var cssReader = File.OpenText("report.css"))
using (var document = new Document(PageSize.A4))
using (var output = new FileStream("report.pdf", FileMode.Create))
{
    var writer = PdfWriter.GetInstance(document, output);
    document.Open();
    XMLWorkerHelper.GetInstance().ParseXHtml(writer, document, cssReader, htmlReader);
    document.Close();
}
Use the overloads available in the XML Worker package version installed in your project; signatures differ between releases. Keep the XHTML, CSS, and image files in a known directory and test with absolute paths first to separate CSS problems from path problems.
4. Data URI images: HTML img versus CSS backgrounds
These are separate compatibility tests:
<img src="data:image/png;base64,..." />puts the image in the HTML element itself.background-image: url("data:image/png;base64,...")asks the CSS parser and resource resolver to load a data URI from a CSS property.
The official pdfHTML FAQ confirms inline Base64 images for pdfHTML and shows HtmlConverter.ConvertToPdf; it does not establish equivalent support for every XML Worker version or for CSS backgrounds. The exact XML Worker/data-format/property combination remains version-dependent.
// pdfHTML (.NET) form documented by iText
using System.IO;
using iText.Html2pdf;

public static void ConvertWithPdfHtml(string html, string destination)
{
    using (var output = new FileStream(destination, FileMode.Create))
    {
        HtmlConverter.ConvertToPdf(html, output);
    }
}
See the official Base64 example in iText’s pdfHTML knowledge base. Its feature coverage is versioned; the cited FAQ identifies pdfHTML 6.3.3 with iText Core 9.7.0, so check the release you actually use in the feature FAQ.
5. Make external resources resolvable
For pdfHTML, supply a base URI when HTML contains relative CSS, fonts, or images. The .NET repository documents that a base URI is required to resolve relative paths.
using iText.Html2pdf;
using iText.Kernel.Pdf;

var properties = new ConverterProperties();
properties.SetBaseUri(Path.GetFullPath("wwwroot"));
using (var pdf = new PdfWriter("report.pdf"))
{
    HtmlConverter.ConvertToPdf(File.ReadAllText("wwwroot/report.html"), pdf, properties);
}
Prefer a controlled local resource directory or an explicit resource resolver. Do not assume the converter can fetch authenticated URLs, execute application templates, or run browser code.
6. A repeatable debugging workflow
- Confirm which engine is running. If the input relies on CSS files, replace
HTMLWorkerwith XML Worker or evaluate pdfHTML. - Log the exact XHTML string sent to the converter. Verify closed tags, quoted attributes, a single root element, and an XHTML namespace.
- Replace the CSS background with a plain colored block. If the block appears, the layout works and the image loading path is the suspect.
- Replace the background with a local PNG using an absolute path. Then test a relative path with the intended base directory.
- Test an HTML
<img>data URI separately from a CSS data URI. - Reduce the document to one element and one image. Add CSS properties back one at a time.
- Check the exact XML Worker or pdfHTML version and consult its feature list. Do not infer legacy behavior from a newer pdfHTML example.
7. Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| Text renders but CSS does not | HTMLWorker is being used, or CSS is outside its limited support. |
Use XML Worker for the iText 5 workflow, or migrate to pdfHTML. |
| Background is blank | Unsupported CSS property, malformed declaration, or unresolved URL. | Test a local absolute image, simplify to background-image, and verify the resolver. |
<img> works but background does not |
The engine supports inline HTML images but not that CSS data URI combination. | Use <img> where layout allows, embed the image through a supported resource path, or validate the exact version before migrating. |
| External image missing | Relative path has no base URI, or the converter cannot access the URL. | Set a base URI/resource resolver and test with a local file. |
| Malformed XML exception | HTML is browser-tolerant but not well-formed XHTML. | Close every element, escape ampersands, quote attributes, and include the XHTML namespace. |
| Dynamic page is empty | XML Worker does not execute JavaScript or server-side ASP/JSP. | Render the final HTML first, or use a browser capture workflow. |
| PDF file is locked or truncated | Document was not closed or the stream lifecycle is incorrect. | Close the document after parsing and dispose streams after conversion. |
8. Performance, reliability, and cost considerations
- Inline Base64 increases HTML size and memory use. For repeated or large images, a resolvable local resource can be more manageable.
- Keep images at the resolution needed for the PDF; oversized source files increase processing and output size.
- Cache immutable CSS and image bytes in your application, but invalidate the cache when assets change.
- Set application-level timeouts around network resource acquisition. XML Worker and pdfHTML are conversion libraries, not browser navigation services.
- For deterministic output, pin library versions, fonts, CSS, and resource files, then run a small fixture document in CI.
- Licensing and supported features differ between iTextSharp 5/XML Worker and current pdfHTML. Review the applicable iText terms before selecting a migration path.
9. Or skip the browser setup
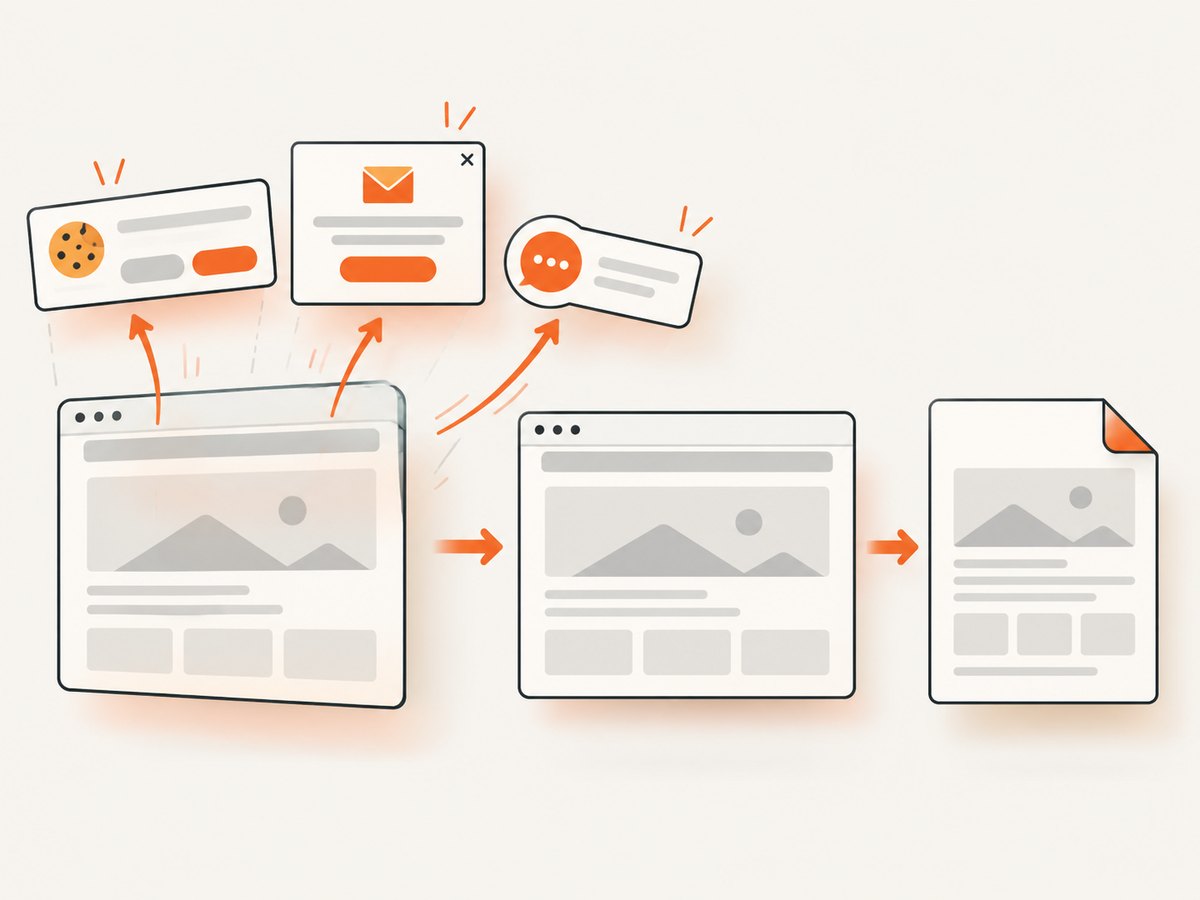
If your real requirement is a screenshot or PDF of a live page rather than server-side HTML-to-PDF conversion, ScreenshotNeo provides a single request to capture a URL. It accepts consent banners before capture and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be disabled. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. It also offers an MCP server for AI agents and PDF capture.
Read the parameter details in the ScreenshotNeo documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);One thousand screenshots per month are free with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
10. FAQ
Does XML Worker run JavaScript?
No. It processes supplied XHTML and CSS; it is not a browser engine.
Can I assume CSS background-image data URIs work?
No. Validate the exact XML Worker version, CSS property, and data format. Official pdfHTML evidence for an HTML <img> data URI does not prove legacy CSS-background support.
Should I migrate to pdfHTML?
Consider it when you need newer HTML/CSS support and can meet its version and licensing requirements. Check the release-specific feature list first.
Why does a browser preview work while the PDF does not?
Browsers execute JavaScript, resolve web resources, and tolerate invalid HTML. XML Worker expects finished, well-formed XHTML and supported CSS.
What is the fastest isolation test?
Convert one XHTML element with a local absolute PNG, then test the same image as an HTML <img> and as a CSS background.


