How to Save a Generated PDF to Amazon S3 in Java
Upload a generated PDF to Amazon S3 with Java SDK 2.x, streams, metadata, encryption, retries, multipart strategy, and troubleshooting.

Direct answer: generate the PDF, keep the output as a local Path or an InputStream, then upload it with the AWS SDK for Java. When the PDF is already on disk, AWS SDK for Java 2.x’s S3Client.putObject with a Path is the simplest and most memory-efficient option. When the generator emits bytes directly, use RequestBody.fromInputStream with the exact content length, or use a documented content-stream or multipart approach when the length is unknown.
This article covers the upload step. Your PDF library remains application-specific: the AWS sources establish how S3 receives a file or stream, not how a PDF is produced.
1. The complete workflow
- Generate the PDF with the library already used by your project.
- Retain the result as a
Path,File, byte array, or stream. - Configure AWS credentials and the bucket’s region using the normal SDK credential chain.
- Choose the destination bucket and object key, such as
reports/2026/invoice-123.pdf. - Build a
PutObjectRequestwith the bucket, key, and useful metadata. - Upload the file or stream and treat the operation as successful only after the SDK call returns.
- Apply the access, encryption, retention, and overwrite policy required by your application.
An S3 object is identified by a bucket and key. The key looks like a path, but it is an object name inside the bucket; it is not a local filesystem location. Uploading another PDF to the same key replaces the current object unless you use versioning or choose unique keys.
2. Upload a generated PDF from a Java Path (SDK 2.x)
Use this approach when your PDF generator writes a file. The SDK reads the path as the request body instead of requiring you to load the entire document into a byte array.
import java.nio.file.Path;
import java.nio.file.Paths;

import software.amazon.awssdk.core.sync.RequestBody;
import software.amazon.awssdk.regions.Region;
import software.amazon.awssdk.services.s3.S3Client;
import software.amazon.awssdk.services.s3.model.PutObjectRequest;

public final class PdfToS3 {
    public static void main(String[] args) {
        String bucket = System.getenv("S3_BUCKET");
        String key = "reports/2026/invoice-123.pdf";
        Path pdfPath = Paths.get("/tmp/invoice-123.pdf");

        if (bucket == null || bucket.isBlank()) {
            throw new IllegalStateException("S3_BUCKET is required");
        }

        try (S3Client s3 = S3Client.builder()
                .region(Region.US_EAST_1)
                .build()) {

            PutObjectRequest request = PutObjectRequest.builder()
                    .bucket(bucket)
                    .key(key)
                    .contentType("application/pdf")
                    .build();

            s3.putObject(request, pdfPath);
            System.out.printf("Uploaded s3://%s/%s%n", bucket, key);
        }
    }
}
Add the AWS SDK v2 S3 module to your build. With Maven:
<dependency>
  <groupId>software.amazon.awssdk</groupId>
  <artifactId>s3</artifactId>
  <version>2.x.x</version>
</dependency>
Use the version managed by your project’s dependency management rather than copying an outdated number. The SDK’s default credential provider chain can read environment variables, shared AWS config files, workload identity, or an instance/task role. The bucket must already exist, and the caller needs permission to write the chosen key.
Generate first, then upload
The PDF library can write to any temporary or permanent path. The following shape keeps generation and storage separate:
Path pdfPath = Paths.get("/tmp/report.pdf");

// Replace this with the PDF library used by your application.
// pdfGenerator.writeReport(report, pdfPath);

PutObjectRequest request = PutObjectRequest.builder()
        .bucket(bucket)
        .key("reports/2026/report.pdf")
        .contentType("application/pdf")
        .build();

s3.putObject(request, pdfPath);
Use a unique temporary filename, close the PDF writer before uploading, and delete temporary files in a finally block when they are no longer needed.
3. Upload when the PDF is an InputStream
Some generators write to a stream rather than a file. SDK 2.x accepts an input stream through RequestBody.fromInputStream, but the length must be exact.

import java.io.InputStream;
import software.amazon.awssdk.core.sync.RequestBody;
import software.amazon.awssdk.services.s3.model.PutObjectRequest;

long contentLength = /* exact number of PDF bytes */;

PutObjectRequest request = PutObjectRequest.builder()
        .bucket(bucket)
        .key("reports/2026/streamed-report.pdf")
        .contentType("application/pdf")
        .build();

try (InputStream pdf = pdfGenerator.openPdfStream()) {
    s3.putObject(request, RequestBody.fromInputStream(pdf, contentLength));
}
Do not estimate the length. A value smaller than the real stream can truncate the object; a value larger than the stream can cause an upload failure or a connection that waits for bytes that will never arrive. If the generator does not expose the length, choose one of these strategies:
- Have the generator write to a temporary file and use the path upload.
- Buffer into memory only when documents are known to be small.
- Use the SDK’s documented
ContentStreamProvideror transfer/multipart facility for unknown-length or large payloads.
Byte arrays
byte[] pdfBytes = pdfGenerator.render(report);
PutObjectRequest request = PutObjectRequest.builder()
        .bucket(bucket)
        .key("reports/2026/report.pdf")
        .contentType("application/pdf")
        .build();

s3.putObject(request, RequestBody.fromBytes(pdfBytes));
This is convenient but creates a memory cost proportional to the whole PDF. Avoid it for large reports or concurrent jobs.
4. Metadata, keys, and overwrite behavior
| Decision | Practical guidance |
|---|---|
| Content type | Set application/pdf when consumers should download or display the object as a PDF. This is application metadata, not a requirement for S3 acceptance. |
| Object key | Use stable prefixes such as reports/2026/customer-42/invoice-123.pdf for listing and lifecycle rules. |
| Repeat uploads | The same key replaces the current object. Use unique IDs, timestamps, or bucket versioning when history matters. |
| Cache behavior | Add cacheControl only when your delivery layer has a deliberate caching policy. |
| Custom metadata | Store searchable business identifiers in a database or object tags; user metadata is not a substitute for an index. |
Encryption and access
New S3 uploads use SSE-S3 by default according to AWS documentation. If policy requires SSE-KMS, configure the request with the required KMS key and ensure the caller can use that key. Keep the bucket private unless public delivery is intentional; grant the application only the write permissions it needs. A typical least-privilege policy limits s3:PutObject to a specific bucket prefix and avoids granting bucket-wide administrative actions.
PutObjectRequest request = PutObjectRequest.builder()
        .bucket(bucket)
        .key(key)
        .contentType("application/pdf")
        .serverSideEncryption("aws:kms")
        .ssekmsKeyId(System.getenv("S3_KMS_KEY_ID"))
        .build();
Only add these fields when your bucket and IAM policy are configured for them.
5. SDK 1.x: keep the API separate
Projects still using AWS SDK for Java 1.x use different classes and a different client method. The file upload shape is:
import java.io.File;
import com.amazonaws.services.s3.AmazonS3;

File pdf = new File("/tmp/report.pdf");
AmazonS3 s3 = /* build your SDK 1.x client */;
s3.putObject(bucketName, "reports/2026/report.pdf", pdf);
Do not mix SDK 1.x imports with SDK 2.x request builders. If you are migrating, make the client and request-body changes together and remove unused version 1 dependencies.
6. Large PDFs and multipart uploads
S3 documents a 5 GB maximum for a single-operation SDK, REST API, or CLI upload. Multipart upload supports objects from 5 MB through 50 TB. The S3 console has a separate documented single-file limit of 160 GB. For ordinary generated reports, a path-based putObject is usually adequate. For very large PDFs, unreliable networks, or a requirement to retry individual parts, use the SDK’s documented transfer or multipart upload support.
Multipart design should include an abort policy for interrupted uploads, a sensible part size, retries with backoff, and completion verification. Do not start multipart solely to avoid calculating a small stream’s length; writing to a temporary file is often simpler.
7. Verification and reliability checklist
- Confirm the bucket name and region are correct.
- Close the PDF writer before opening the file for upload.
- Use an exact content length for streams.
- Log the bucket and key, never secret credentials.
- Retry transient network or service errors with bounded exponential backoff.
- Use an idempotent key strategy so a retry does not create an unintended duplicate.
- For sensitive documents, verify encryption, bucket policy, and access logs in the deployment environment.
- Check the returned result or issue a normal metadata verification when downstream processing requires proof that the object exists.
8. Common errors and fixes
| Error or symptom | Likely cause | Fix |
|---|---|---|
AccessDenied |
The IAM principal cannot write the key, or a bucket/KMS policy denies it. | Grant the narrow s3:PutObject permission for the target prefix and, for SSE-KMS, key-use permission. |
NoSuchBucket |
Bucket name is wrong, deleted, or not visible in the configured account. | Check the account, spelling, and deployment configuration. |
PermanentRedirect or region errors |
The client region does not match the bucket. | Build the client with the bucket’s region or use the SDK’s region discovery approach. |
| Truncated PDF | Stream content length was smaller than the actual bytes. | Provide the exact length or upload a file path. |
| Upload hangs or fails at the end | Declared stream length is larger than the bytes produced. | Measure the complete output, spool to disk, or use an unknown-length content provider. |
NoSuchFileException |
The generator has not closed or flushed the file, or the temporary file was deleted early. | Close generation first and keep the file until the upload completes. |
| PDF downloads as generic data | Content type was omitted or overwritten. | Set contentType("application/pdf") and inspect object metadata. |
| Memory pressure | Large PDFs are held in byte arrays or many jobs run concurrently. | Use path uploads, limit concurrency, and select multipart for large objects. |
| Duplicate business records | Retries create a new random key each time. | Derive an idempotent key from the report identity or use a database record to track attempts. |
9. Performance and cost notes
Path uploads avoid an application-sized byte-array copy. Stream uploads avoid a temporary file but require correct length handling. Multipart adds coordination overhead but improves recovery for large objects. S3 billing depends on storage, requests, data transfer, and any selected storage or encryption services; the Java upload method does not eliminate those service charges. Keep temporary files on fast local storage, reuse an SDK client rather than constructing one per request, and set concurrency according to available memory and network capacity.
10. Or skip the browser setup
If the PDF source is a web page, you can capture it directly with ScreenshotNeo and then save the returned PDF bytes to S3 in the same way. Its API is a separate capture step: request the PDF, write the response to a file or stream, and upload that output with the Java code above. See the ScreenshotNeo API documentation for request options.
import java.io.InputStream;
import java.net.URI;
import java.net.http.HttpClient;
import java.net.http.HttpRequest;
import java.net.http.HttpResponse;
import java.nio.file.Files;
import java.nio.file.Path;

HttpRequest request = HttpRequest.newBuilder()
        .uri(URI.create("https://api.screenshotneo.com/v1/shot?access_key=YOUR_API_KEY&url=https%3A%2F%2Fstripe.com&format=pdf"))
        .GET()
        .build();

HttpResponse<byte[]> response = HttpClient.newHttpClient()
        .send(request, HttpResponse.BodyHandlers.ofByteArray());
if (response.statusCode() / 100 != 2) {
    throw new IllegalStateException("ScreenshotNeo returned HTTP " + response.statusCode());
}
Path pdfPath = Files.createTempFile("page-", ".pdf");
Files.write(pdfPath, response.body());
// Upload pdfPath with S3Client.putObject(...), as shown above.
The same capture endpoint can be called with cURL:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpFor a PDF, request the PDF format supported by the API and choose a .pdf output filename. Python:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const bytes = Buffer.from(await res.arrayBuffer());
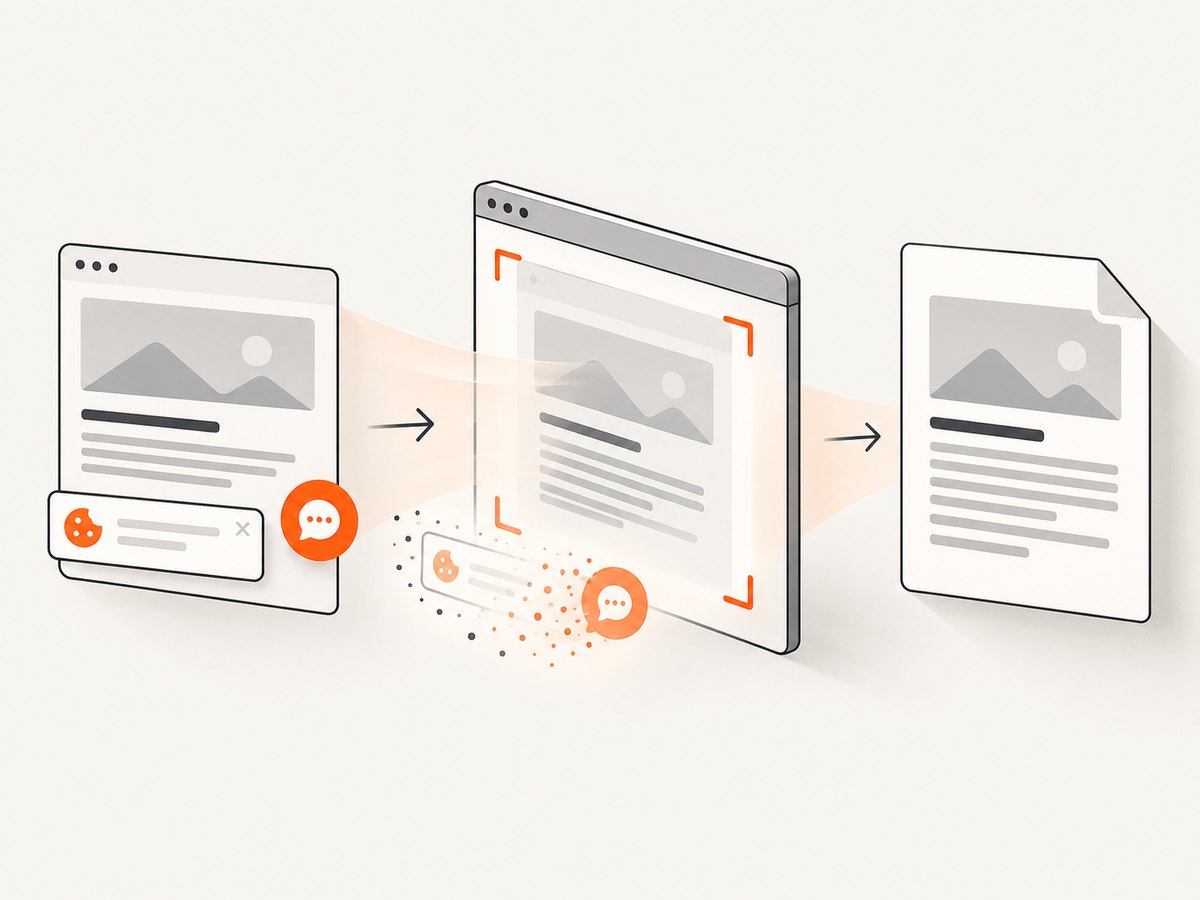
ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture; bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing status. Its MCP server provides take_screenshot, get_page_info, and capture_pdf tools for AI agents. One thousand screenshots per month are free with no card, and paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
11. FAQ
Can I upload without saving a temporary file?
Yes. Use RequestBody.fromInputStream with an exact length, or a suitable unknown-length content provider. A temporary file is often safer for large or library-generated PDFs.
Does the S3 key need a .pdf suffix?
No. The suffix is useful for humans and integrations, but S3 accepts any key. Set the content type explicitly when clients depend on it.
Should every upload use SSE-KMS?
Use the encryption mode required by your security policy. SSE-S3 is the documented default for new uploads; SSE-KMS adds key-management controls and corresponding permissions.
When should I choose SDK 1.x?
Use the version already supported by your application. For new code, keep the examples and dependencies on SDK 2.x unless a project constraint requires v1.
Can a retry safely repeat the upload?
Yes when the key is intentionally idempotent. Decide whether replacement or versioned history is correct before adding retries.


