How to Scrape Amazon Product Pages
Learn the compliant ways to obtain Amazon product information, from manual research and the Associates API to careful page capture.
Short answer: first decide whether you need product information, a visual snapshot, or a permitted affiliate workflow. Amazon’s marketplace terms can restrict automated extraction and reuse, while the Product Advertising API is available only to eligible Associates who follow its license. Amazon’s robots.txt documentation describes how Amazon’s own crawlers access other sites; it does not authorize third parties to crawl Amazon product pages.
This guide shows a practical decision process, a small Python collector for pages you are authorized to access, API-oriented alternatives, implementation details, failure handling, and a visual-capture option with ScreenshotNeo. It does not provide CAPTCHA bypasses, fingerprint workarounds, proxy-rotation recipes, or instructions for evading access controls.
1. Clarify what “scrape” means for your project
Teams use the word scrape for several different jobs. Your safest implementation depends on the output you actually need.
| Goal | Best starting point | Key limitation |
|---|---|---|
| Check one product manually | Amazon page in a browser | Slow to repeat; content changes |
| Build an affiliate display | Amazon Associates Product Advertising API | Requires an Associates account, application, and license compliance |
| Archive a visual state | Authorized browser capture or ScreenshotNeo | An image is not structured product data |
| Build a large catalog or price database | Written permission or a licensed data source | Terms, reuse, freshness, and retention need explicit review |
Write down the marketplace, fields, update frequency, intended audience, retention period, and whether you will display or republish the result. A one-off internal review and a public database of prices are materially different uses.
2. Is scraping Amazon allowed?
There is no single worldwide yes-or-no answer in the supplied sources. Contractual terms, program rules, and local law can differ by marketplace and use.
Amazon UK’s Conditions of Use say: “You may not utilise any data mining, robots, or similar data gathering and extraction tools to extract (whether once or many times) for re-utilisation any substantial parts of the content of any Amazon Service, without our express written consent.” The same page discusses publishing a database containing substantial parts of the service, including prices and product listings. That is Amazon UK wording; check the conditions for the marketplace you use and obtain professional advice for a legal conclusion. Read the Amazon UK Conditions of Use.
Do not infer that a page being publicly viewable grants permission to collect, copy, aggregate, or republish it. Also keep marketplace terms separate from Amazon Associates rules. Associates participation requirements prohibit artificially generated clicks or impressions and sessions created by robots or software programs. Review the Associates participation requirements.
3. Does Amazon’s robots.txt allow scraping?
No. Amazon’s About Amazonbot documentation explains how Amazon-listed crawlers visit other websites and how site owners can use the Robots Exclusion Protocol. It covers Amazon’s crawler behavior, caching, and bot-specific directives. It is not a permission statement for an independent program to crawl Amazon retail pages. Read Amazon’s Amazonbot documentation.
A robots.txt file is a technical signal, not a universal license. Before making requests, identify the applicable contract, authentication requirements, rate limits, and your own legal and compliance obligations.
4. The official route: Amazon Associates Product Advertising API
Amazon Associates describes Product Advertising API access as conditional. You need an open Associates account, compliance with the Associates Operating Agreement, and an application for API access followed by compliance with the API license. See the Product Advertising API documentation.
The program license is narrow. Product Advertising Content is supplied for program purposes, principally advertising an Amazon site and driving sales there. Policies address display, caching, extraction, and reuse. API credentials are not general permission to copy product pages, create an unrestricted catalog, or republish content elsewhere. Read the current license and specifications immediately before implementation. Review Associates policies.
API eligibility and rate planning
The Associates help page states an initial allowance of 1 request per second. It describes increases tied to qualifying shipped revenue of $4,600 in a trailing 30-day period, up to a stated maximum of 10 requests per second. These are policy figures, not a performance guarantee, and may change. Verify the current page before designing a queue or committing to a volume.
- Authenticate only from a server-side component; never expose keys in browser JavaScript.
- Cache only as the current license permits. Do not assume that a generic HTTP cache policy is allowed for product content.
- Store the product identifier, retrieval time, marketplace, and license-relevant metadata with each record.
- Use exponential backoff for throttling and stop on repeated authorization failures.
- Render content according to the program’s current linking, attribution, and display rules.
5. A cautious DIY workflow for authorized pages
Use this workflow only where you have permission and where the result is compatible with the applicable terms.
- Define fields. Prefer a small schema such as ASIN, title, displayed price, availability, rating, and retrieval time. Mark missing values as unknown.
- Choose a source. Use the official API for Associates content. For a page you own or are expressly authorized to collect, use normal HTTP or a browser.
- Identify the marketplace. Keep country domains and currency separate; do not silently merge values from different storefronts.
- Set a conservative schedule. Respect published limits, your agreement, and server capacity. A queue with bounded concurrency is easier to stop and audit.
- Validate output. Check status codes, content type, expected selectors, currency, and timestamp. Save an error record instead of treating an empty field as zero.
- Minimize retention. Keep only fields and history required for the stated purpose, and delete records when your policy or license requires it.
Python example: authorized HTML page
import time
import requests
from bs4 import BeautifulSoup

url = "https://example.com/product-you-own"
headers = {"User-Agent": "authorized-research/1.0"}

response = requests.get(url, headers=headers, timeout=30)
response.raise_for_status()
if "text/html" not in response.headers.get("content-type", ""):
    raise RuntimeError("Expected HTML")

soup = BeautifulSoup(response.text, "html.parser")
def text(selector):
    node = soup.select_one(selector)
    return node.get_text(" ", strip=True) if node else None

record = {
    "title": text("h1"),
    "price": text("[data-price]"),
    "retrieved_at": time.strftime("%Y-%m-%dT%H:%M:%SZ", time.gmtime()),
}
print(record)
Selectors in this example are placeholders for a site you control or are authorized to access. Amazon’s markup can change, and a selector that works today is not a contract for tomorrow. Do not add code that defeats a challenge page or access control.
cURL example
curl --fail --location --max-time 30 \
  -H 'User-Agent: authorized-research/1.0' \
  'https://example.com/product-you-own'
Node.js example
const response = await fetch('https://example.com/product-you-own', {
  headers: { 'User-Agent': 'authorized-research/1.0' },
  signal: AbortSignal.timeout(30_000)
});
if (!response.ok) throw new Error(`HTTP ${response.status}`);
const html = await response.text();
console.log(html.length);
6. Browser rendering, JavaScript, and edge cases
Some product pages render price or availability after JavaScript runs. A plain HTTP client then receives a shell, consent wall, bot check, or incomplete content. A permitted browser workflow should wait for a specific selector, record navigation errors, and close the browser after each bounded job.
- Consent banners: follow the site’s permitted interaction rules. Do not claim that accepting consent grants a right to copy the page.
- Localization: set the intended locale and timezone, then record currency and region.
- Variants: a parent listing can change when a size or color is selected. Store the selected variation identifier.
- Unavailable products: distinguish “out of stock,” “not found,” and “request failed.”
- Pagination: stop at a documented boundary; do not recursively follow every link by default.
- Dynamic pricing: save retrieval time and treat a price as a time-stamped observation.
- Images and reviews: content may have separate licensing and display rules. Do not assume API access covers every asset.
7. Or skip the browser setup
When your requirement is a visual record of a permitted URL, ScreenshotNeo returns a PNG, JPEG, WebP, or PDF from one GET request. It can wait for selectors or network idle, load lazy images, capture one CSS-selected element, apply custom CSS or JavaScript, set cookies and headers, choose a device or viewport, use dark mode, block selected resources, and cache with a TTL you choose. Its API also supports async jobs, signed webhooks, bulk capture, usage reporting, and an MCP server with take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. See the ScreenshotNeo documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com/product-you-own -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://example.com/product-you-own"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com/product-you-own' });
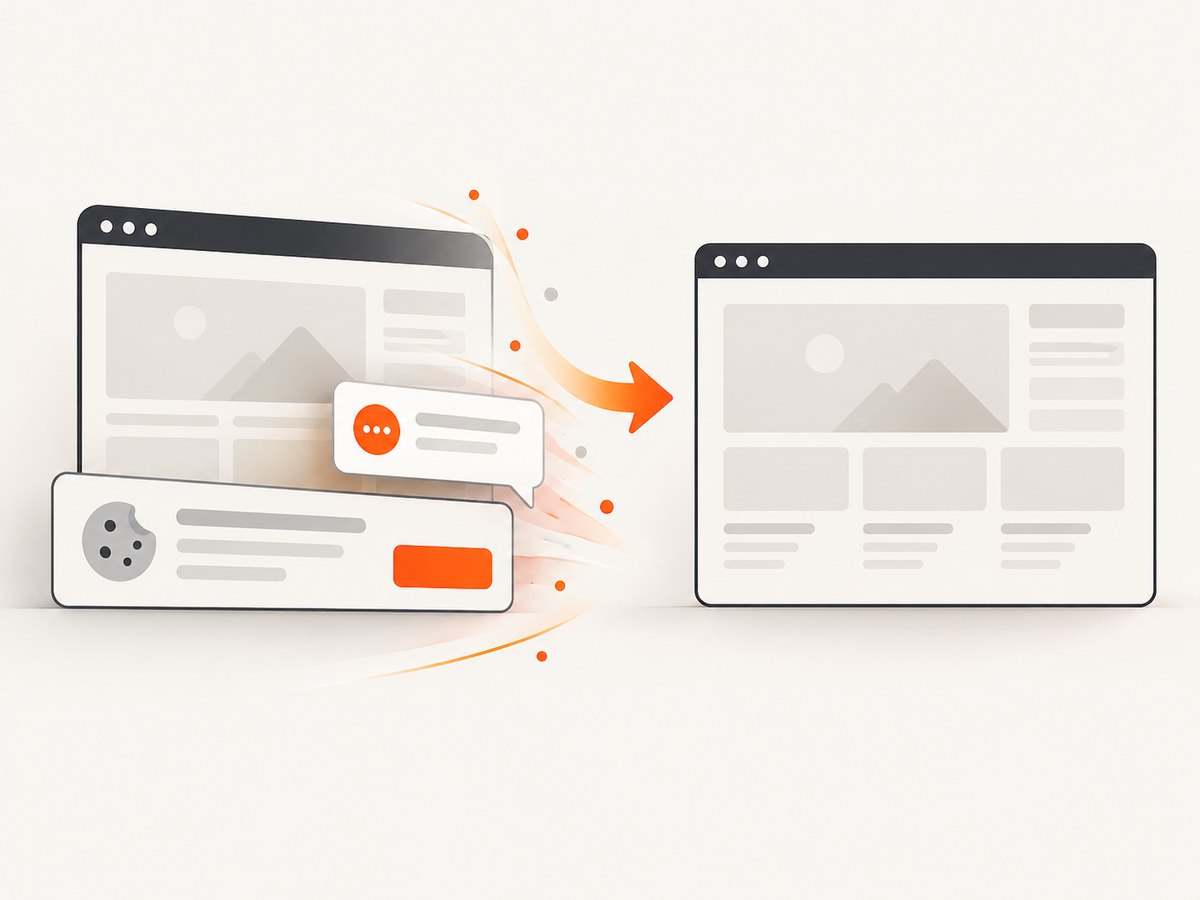
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Cookie banners, newsletter popups, and chat widgets are removed before the shot, with each step configurable. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed; response headers report the page verdict and billing status. Use the service only for URLs you are allowed to capture, and remember that an image does not grant rights to republish Amazon content.
There are 1,000 screenshots each month on the free plan with no card. Paid plans start at $5 for 3,000 shots; every feature is on every plan. Create a free ScreenshotNeo account.
8. Reliability, performance, and cost controls
Reliability checklist
- Use timeouts on every request and a bounded retry policy.
- Retry transient network errors and 429 responses with exponential backoff; do not retry permanent 4xx authorization errors indefinitely.
- Persist job state so a process restart does not duplicate work.
- Record response status, source URL, marketplace, parser version, and retrieval time.
- Alert on sudden increases in empty fields, challenge pages, or changed currencies.
Performance checklist
- Prefer the official API when it provides the fields you need; a rendered browser page costs more time and resources.
- Use a queue and conservative concurrency aligned with the documented allowance.
- Request only necessary fields and avoid downloading unrelated assets.
- For screenshots, use a viewport capture when full-page output is unnecessary; use lazy-image loading only when the page requires it.
- Use caching only where your license and freshness requirements allow it.
Cost model
Your total cost includes API or service fees, browser CPU and memory, storage, bandwidth, engineering maintenance, and compliance review. A failed parser can be more expensive than a slower parser because it silently produces bad data. ScreenshotNeo bills only clean shots; failed loads, bot checks, blank pages, timeouts, and cache hits are free, and the response identifies the verdict and billing state.
9. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| 403 or access denied | Permission, policy, or access-control issue | Stop retries; verify authorization and use an approved API or source. |
| 200 response with no product fields | JavaScript shell, consent page, or changed markup | Inspect content type and page title; use an authorized browser flow or official API. |
| 429 too many requests | Rate limit exceeded | Reduce concurrency, add backoff, and check current Associates limits. |
| Price is wrong | Different locale, variant, currency, or time | Set region explicitly and store variant, currency, and timestamp. |
| Screenshot is blank | Navigation timeout, blocked resource, or page verdict failure | Increase a selector or network-idle wait, inspect verdict headers, and test the URL manually. |
| Unexpected bill | Request produced a clean capture | Read X-Page-Verdict and X-Billed; use caching and targeted captures. |
10. Practical decision checklist
- Have you identified the exact Amazon marketplace and current terms?
- Is your purpose allowed under the applicable contract and, if relevant, Associates license?
- Can the official API provide the fields without collecting page HTML?
- Are retention, display, attribution, and refresh rules documented?
- Do your jobs stop on authorization failures and respect rate limits?
- Are you capturing a visual artifact rather than claiming structured-data rights?
11. FAQ
Can I scrape one Amazon page for personal research?
A single request does not answer every contractual or legal question. Check the marketplace terms, your purpose, and whether you will retain, share, or republish the result.
Does an Associates account permit general scraping?
No. API access and Product Advertising Content are governed by a limited program license and current specifications.
Can robots.txt be used as permission?
No. Amazon’s robots documentation concerns Amazon’s own crawlers visiting other sites.
Is ScreenshotNeo an Amazon product-data API?
No. It is a screenshot and PDF service. Use it for an authorized visual capture, then handle the resulting image under the rights that apply to the source page.
What should I do when the rules change?
Recheck the marketplace terms, Associates license, API limits, and your data-retention policy before deploying a new collector.


