How to Scrape BBC Sports Pages
BBC Sport discourages scraping. Learn the permitted alternatives: RSS, permission-based access, and safe page capture for authorized use.
Short answer: do not build a scraper that crawls BBC Sport pages or systematically extracts article content without permission. BBC’s published guidance says page content may be downloaded for personal, non-commercial use, while other use requires prior written permission. A robots.txt commentary surfaced through a third-party mirror also says, “Please use our site like a human, not a robot,” and states that scraping, crawling, and systematic extraction are disallowed. Treat that robots.txt text as an operational signal, not a legal ruling, and verify the live BBC robots.txt and Terms of Use before implementation.
If you need headlines in an application, use a current BBC Sport RSS feed subject to the BBC Terms of Use. If you need article text, structured data, commercial reuse, or a dependable API, request permission or an authorized data arrangement. The BBC Developer Portal currently says access to its APIs and documentation is limited to registered BBC employees.
What “scraping BBC Sport” can mean
Developers use “scrape” to describe several different jobs. They have different permission and engineering requirements:
| Goal | Safer route | What to verify |
|---|---|---|
| Show current headlines | BBC Sport RSS | Current feed URL, attribution, caching and reproduction rules in the BBC Terms of Use |
| Download pages for personal research | Manual or low-volume access | Personal, non-commercial scope and current BBC rules |
| Republish article text or images | Written permission or a licensed feed | Rights, territory, duration, attribution and commercial use |
| Build a commercial sports product | Authorized data provider or BBC agreement | Service-level, redistribution and rate terms |
| Capture a visual snapshot of a page you are allowed to use | Authorized browser capture | Copyright, access permission and whether the page permits automated viewing |
BBC’s published position
The BBC Sport information page says users may download page content for personal, non-commercial use, and that other use requires prior written permission. This is the key distinction for an application: downloading a page for your own reading is different from collecting article bodies, storing them, indexing them, or showing them to your users.
A robots.txt passage returned in the research was hosted by a third-party mirror, Well-Known.dev, rather than directly opened from the BBC domain. It reports language against scraping, crawling and systematic extraction. Check the live BBC robots.txt and the current BBC Terms of Use immediately before deploying. Robots.txt is not a court decision, and it does not grant permission where copyright or contract terms require it.
BBC Sport describes RSS as “special kind of web page, designed to be read by computers rather than people.” RSS is useful for headline updates, but it does not automatically grant a right to reproduce full articles, images or video. The BBC Developer Portal also currently states that API access and documentation are limited to registered BBC employees. A legacy BBC developer page lists sport headline feeds, but that old list is not proof that those exact endpoints still work.
Recommended decision process
- Define the smallest data need. Headlines and links may fit RSS. Full article text, images, match data or historical archives need a separate rights review.
- Check the current rules. Read the live robots.txt, Terms of Use and the RSS page. Record the date and the exact feed URL you intend to use.
- Choose an authorized source. Use RSS for permitted headline updates, obtain written permission for broader reuse, or use a provider that licenses the data you need.
- Design for change. Feed URLs, fields and terms can change. Keep the source URL in configuration and make parsing tolerant of missing fields.
- Store only what you are allowed to store. Keep identifiers, titles, links and timestamps when that is permitted. Avoid copying article bodies unless your agreement explicitly allows it.
Using BBC Sport RSS for headline updates
Because the research did not verify a current endpoint, do not paste a legacy URL into production. Find the current feed from the BBC Sport RSS information page, put it in an environment variable, and test it manually. The examples below parse a feed without crawling individual article pages.
Step 1: configure the feed
export BBC_SPORT_RSS_URL='https://REPLACE_WITH_CURRENT_BBC_FEED_URL'Keep the URL outside your source code so it can be changed without redeploying. Fetch it over HTTPS, identify your application in the User-Agent, and use a conservative refresh interval that follows the published terms.
Step 2: fetch and inspect with cURL
curl --fail --silent --show-error --location \
  --user-agent 'my-headline-reader/1.0 (contact: ops@example.com)' \
  "$BBC_SPORT_RSS_URL"
This command retrieves the feed document only. It does not request every linked article. Save a copy during development so you can inspect namespaces and field names, then remove test data according to your retention policy.
Step 3: parse with Python
import os
import time
import requests
import feedparser

feed_url = os.environ['BBC_SPORT_RSS_URL']
headers = {'User-Agent': 'my-headline-reader/1.0 (contact: ops@example.com)'}
response = requests.get(feed_url, headers=headers, timeout=20)
response.raise_for_status()

feed = feedparser.parse(response.content)
if feed.bozo:
    raise RuntimeError(f'Feed XML could not be parsed: {feed.bozo_exception}')

items = []
for entry in feed.entries:
    items.append({
        'title': entry.get('title', '').strip(),
        'url': entry.get('link', '').strip(),
        'published': entry.get('published', ''),
        'summary': entry.get('summary', '').strip(),
    })

for item in items:
    print(item['title'], item['url'])
Install the dependencies with pip install requests feedparser. Treat summaries as source-provided content: whether you may display or store them depends on the current BBC terms. If you only need a link list, discard the summary field.
Step 4: parse with Node.js
import Parser from 'rss-parser';

const feedUrl = process.env.BBC_SPORT_RSS_URL;
if (!feedUrl) throw new Error('BBC_SPORT_RSS_URL is required');

const parser = new Parser({
  headers: {
    'User-Agent': 'my-headline-reader/1.0 (contact: ops@example.com)'
  },
  timeout: 20000
});

const feed = await parser.parseURL(feedUrl);
for (const item of feed.items) {
  console.log({
    title: item.title ?? '',
    url: item.link ?? '',
    published: item.isoDate ?? item.pubDate ?? ''
  });
}
Install it with npm install rss-parser. Do not follow each link automatically unless your permission and use case cover that page access.
Step 5: schedule responsibly
Run a small number of scheduled feed requests rather than a tight polling loop. Use conditional requests when the server supplies ETag or Last-Modified; a 304 Not Modified response means you can keep the existing result. Cache the last successful document, add exponential backoff for transient failures, and stop retrying on a permanent HTTP error until you have investigated it.
Data handling and compliance checklist
- Write down whether the project is personal, non-commercial or commercial.
- Record the current BBC Terms of Use and RSS guidance that your review relied on.
- Keep the original item URL and display clear attribution where required.
- Set a deletion period for stored titles, summaries and metadata.
- Do not remove copyright notices, bypass bot checks, defeat access controls or rotate identities to avoid restrictions.
- Do not present RSS as a general BBC data API.
- Ask the BBC for written permission before reproducing full articles, images, video, large archives or commercial feeds.
Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| 403 or 401 response | The resource requires permission, blocks the request, or the URL is wrong. | Stop automated retries. Check the current BBC rules and use RSS or an authorized source. |
| 404 for a feed URL | A legacy feed endpoint changed or was removed. | Find the current RSS page and update configuration. Do not assume old documentation is current. |
| XML parse error | The response is HTML, a block page, truncated XML or an unexpected format. | Log status and content type, inspect a redacted sample, and confirm the endpoint manually. |
| Empty item list | The feed has no entries, uses namespaces your parser does not expose, or the response is cached incorrectly. | Inspect the raw XML, handle namespaces, and verify the feed timestamp before changing code. |
| Duplicate headlines | The feed was re-read without a stable key. | Deduplicate by canonical link or a hash of the source identifier and title. |
| Content complaints | Your app is displaying more material than your terms permit. | Remove unauthorized article text or images and request permission before restoring them. |
| Rate or reliability problems | Polling too often, no timeout, or no backoff. | Use scheduled requests, timeouts, conditional GET, bounded retries and a stale-but-labeled cache. |
Performance, reliability and cost
RSS is usually cheaper and more reliable than loading every article page because one document contains the update list. Keep connection and read timeouts finite, reuse HTTP connections, and cap response size before parsing. A feed fetch should be idempotent: the same response can be processed repeatedly without creating duplicate records.
Use a queue when downstream work is expensive. The fetcher can store a small normalized record, while a separate worker handles notifications or indexing. Monitor fetch status, parse failures, item counts and the age of the newest item. An unexpected zero-item feed should alert you instead of silently deleting your existing headlines.
There is no research-backed scrape rate, feed count or performance benchmark to quote here. Do not invent one. Follow the BBC’s current instructions and any written agreement you receive. Your main cost is application infrastructure and, if applicable, a licensed data service; avoiding unauthorized crawling also avoids building a fragile system around blocked pages.
Or skip the browser setup
If you have permission to capture a BBC Sport page visually—for example, an internal review, a permitted personal archive or a page you own—ScreenshotNeo can return a screenshot or PDF with one request. It is a capture tool, not permission to copy BBC content, so keep your rights review separate.
See the ScreenshotNeo API documentation for all options. A basic call is:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://www.bbc.com/sport -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://www.bbc.com/sport"}, timeout=90)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://www.bbc.com/sport' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const file = Buffer.from(await res.arrayBuffer());
await Bun.write('shot.webp', file);ScreenshotNeo accepts PNG, JPEG, WebP or PDF output and supports full-page capture, lazy-image loading, element selection, device presets, custom viewports, dark mode, retina scale, custom CSS and JavaScript, clicks, selector waits, delays, network-idle waits, blocked resource types, custom headers, cookies, user agents, timezone, geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs, webhooks, bulk capture and a usage API.
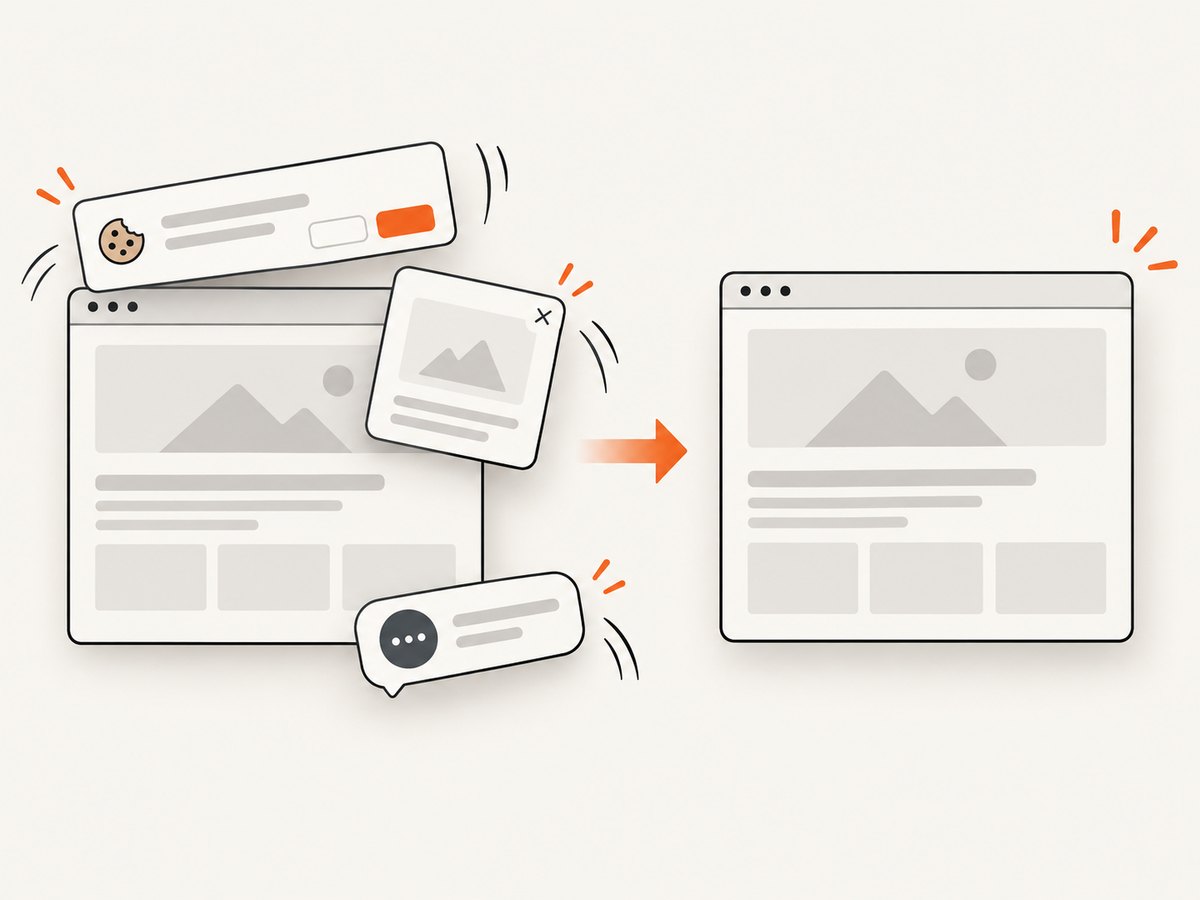
Its clean-shot workflow accepts consent banners before capture and removes more than 60 known consent platforms, newsletter popups and chat widgets; each step can be disabled. Bot checks, blank pages, timeouts, failed loads and cache hits are not billed, and response headers identify the page verdict and billing result. An MCP server provides take_screenshot, get_page_info and capture_pdf for Claude, Cursor and other MCP clients.
The Free plan includes 1,000 shots per month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free. Create a free ScreenshotNeo account to try an authorized capture workflow.
FAQ
Can I scrape BBC Sport for a school project?
Personal, non-commercial use may be permitted under BBC guidance, but check the current Terms of Use and robots.txt first. Keep the scope small and do not republish protected material.
Does BBC Sport have an RSS feed?
BBC Sport offers RSS and describes how feeds work. Verify the current endpoint and follow the BBC Terms of Use; old endpoint lists may be obsolete.
Can I use BBC Sport data in my app?
For headline updates, investigate RSS. For article text, images, commercial use or a dependable API, seek written permission or an authorized provider.
Is the BBC Developer Portal a public sports API?
The current portal statement says access to its APIs and documentation is limited to registered BBC employees, so do not assume public access.
Can ScreenshotNeo bypass BBC restrictions?
No. It can capture a page you are authorized to access. It does not grant rights, defeat access controls or turn a screenshot into a license to reproduce content.
Final checklist
- Confirm your intended use and permission scope.
- Read the live BBC Terms of Use and robots.txt.
- Use a verified RSS endpoint for headline updates.
- Do not crawl linked pages or copy full articles without authorization.
- Add timeouts, caching, conditional requests, backoff and monitoring.
- For an authorized visual snapshot, use ScreenshotNeo and keep the capture rights documented.


