How to Scrape Bricomarché Product Pages
Bricomarché’s current robots.txt disallows general crawlers from /fr/p/. Learn how to seek authorized product data and structure it responsibly.
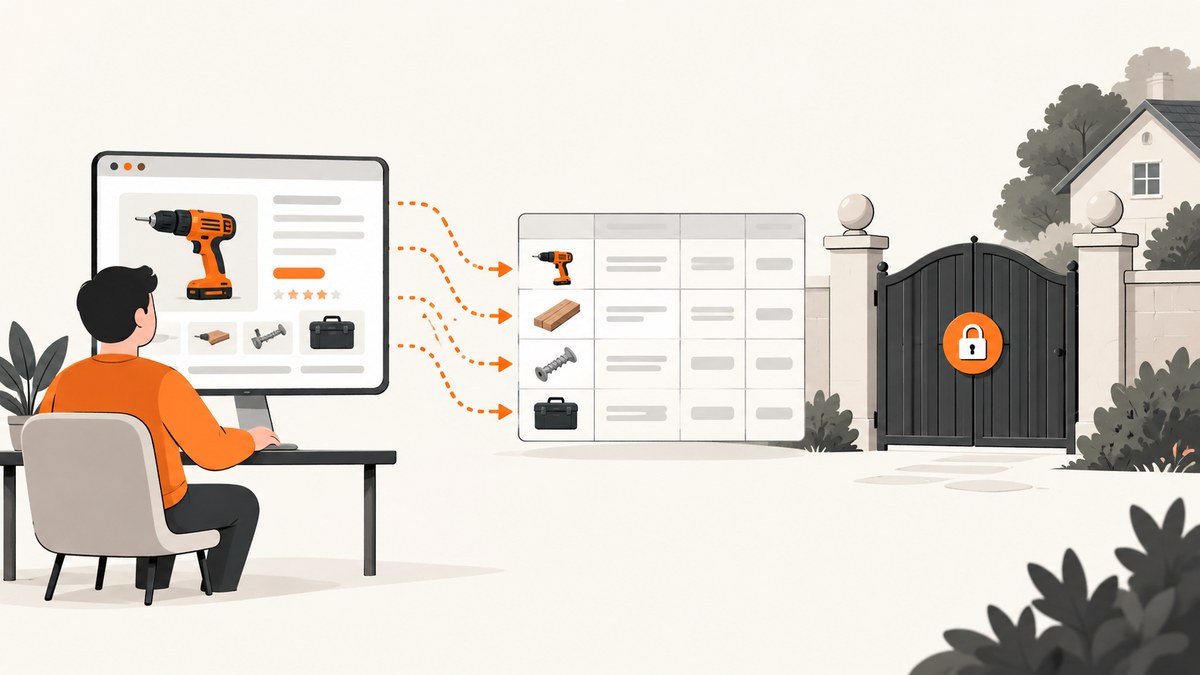
Direct answer: As of 29 September 2026, Bricomarché’s robots.txt has Disallow: /fr/p/ under User-agent: *. Do not crawl those product paths as a general crawler under the current rules. First ask Bricomarché for an approved feed, export, API, or written permission. Named crawler allowances in the file apply to those crawler identities; they do not grant general permission to another scraper. Recheck the file and applicable terms immediately before any authorized collection.
If access is authorized, preserve the offer context along with product details: seller, fulfillment channel, store or geographic scope, observed price and availability, retrieval time, and source URL. Prices and stock are snapshots, not durable product facts. This guide explains the access boundary, what product pages may describe, how to request authorized data, and how to build a parser against a local fixture without implying that Bricomarché’s live pages were inspected or that any code below is approved to access them.
1. Check access before writing a scraper
Bricomarché’s current robots file disallows the general crawler group from /fr/p/. It also disallows paths relating to cart, checkout, accounts, search, and some query-filter patterns. It lists a sitemap and separate allowances for GPTBot, ClaudeBot, PerplexityBot, Perplexity-User/1.0, and Google-Extended. Those are crawler-specific directives; they are not a general grant of access to readers or permission to impersonate those crawlers.
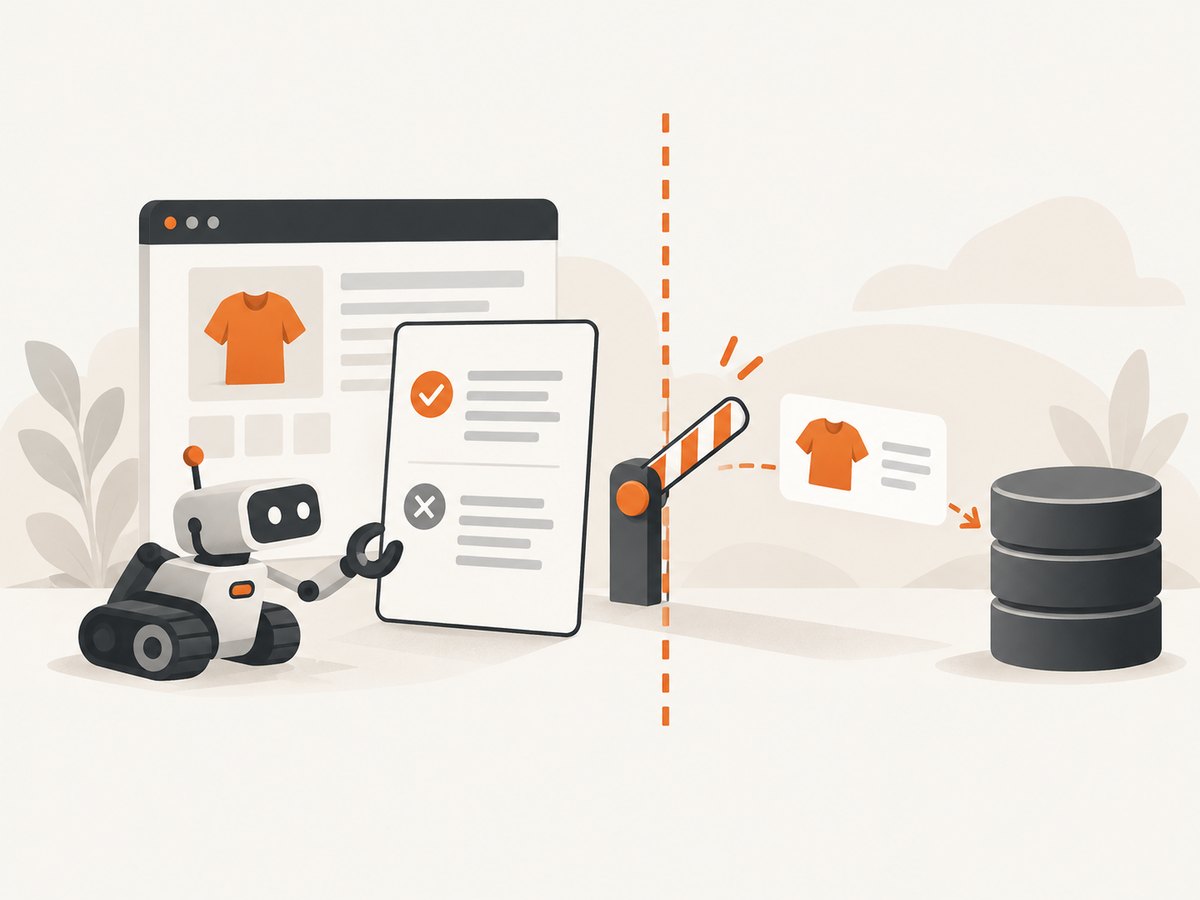
Robots directives can change. Before collection, inspect the live file for the precise hostname and path, review the terms that apply to the intended sales channel, and identify your crawler accurately. Robots.txt is a crawler directive, not by itself a legal ruling or a data-access agreement. The research for this article did not establish a legal interpretation, private agreement, or permission for scraping.
- Check the current robots file. Confirm the target host, relevant user-agent group, and exact path rules. Do not assume a rule observed today will remain current.
- Review the terms for the data and offer type. Bricomarché’s online sales terms cover certain home-delivery offers; pickup and marketplace purchases have separate conditions.
- Request an approved source. Ask for a product feed, export, documented API, or written permission that states what data and collection method are allowed. A supplier contact form is a contact route, not evidence that product data access is available.
- Keep the scope narrow. If authorization is granted, collect only the fields needed, keep request rates low, identify the crawler accurately, and do not access logged-in or personal-account data unless permission clearly covers it.
The research did not verify a public product API, export, feed, or scraping authorization. Until the site approves a source or grants permission, do not automate requests to the disallowed product path. Do not rotate identities, use proxies to evade the rule, bypass CAPTCHAs, manipulate sessions, or otherwise try to defeat access controls.
2. What information can a product page contain?
Bricomarché’s online sales terms describe product details as including product name, composition, functions, technical characteristics, TTC price and, where applicable, manufacturer warranty information. The terms say: “Le descriptif détaillé de chaque produit est accessible en cliquant sur la dénomination ou la photographie attachée au produit.” This describes how customers access a detailed description; it does not establish a scraper interface or stable page structure. The cited CGV version is dated 29 April 2026.
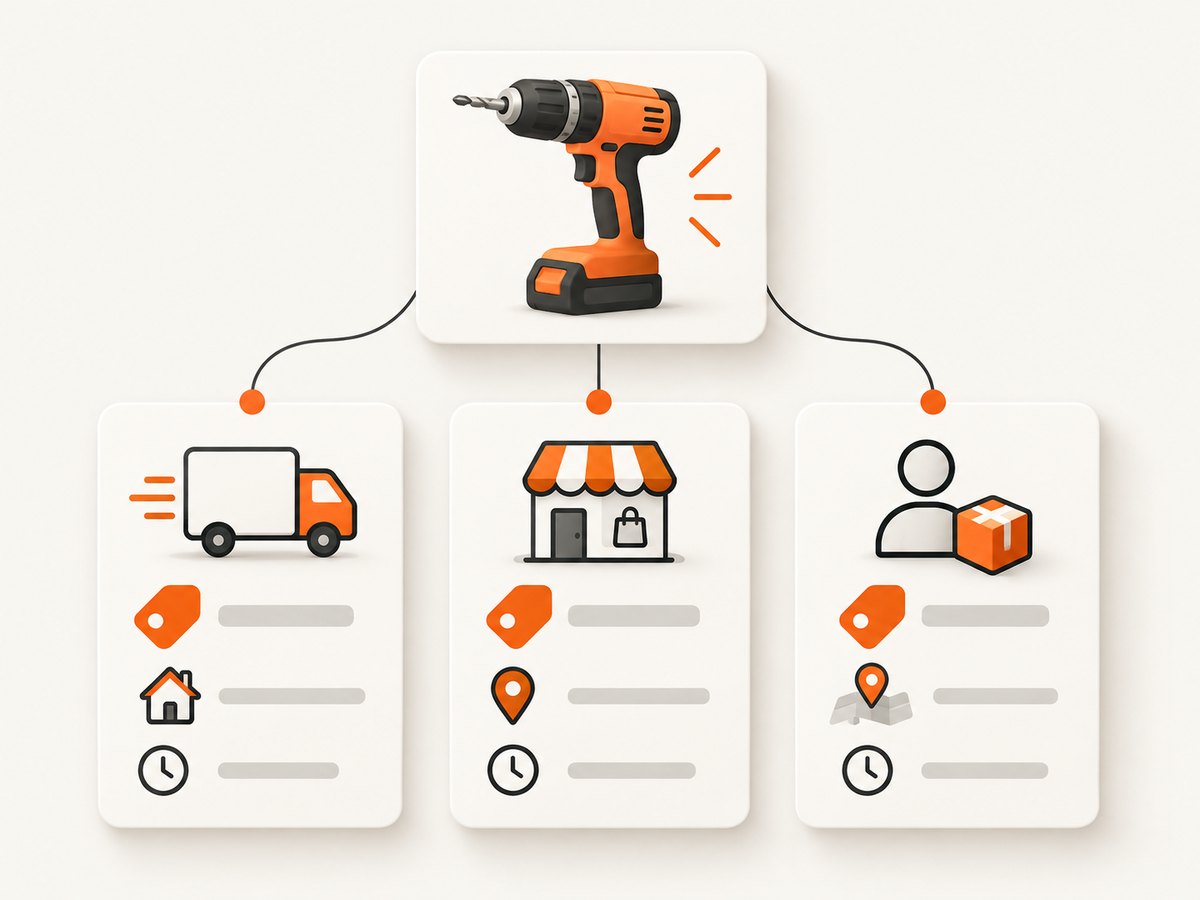
A product page may show or relate to more than one kind of offer. The terms distinguish home delivery marked “Livré à domicile” and “Vendu par Bricomarché” from store-operated pickup and marketplace partner offers. Marketplace sellers are third-party professionals and are responsible for their own descriptions and offer information. Do not flatten these into one supposedly first-party Bricomarché record.
For an authorized research dataset, a practical schema is:
| Field | What to record | Why it matters |
|---|---|---|
source_url |
Exact permitted page or approved feed record URL | Lets a reviewer trace the observation. |
retrieved_at |
Timestamp including timezone | Price and availability can change. |
product_name |
Displayed name | Core product identity, as stated by the source. |
brand_model |
Brand or model only when stated | Avoid inferring an identifier that is not shown. |
description |
Necessary description/specification text | Keep the source wording and provenance clear. |
price, currency |
Displayed amount, currency, and whether shown TTC | Prices vary and should not be treated as permanent. |
seller, offer_type |
Seller identity and home delivery, store pickup, or marketplace context | Offer terms and responsibility differ. |
scope |
Store or geographic context, if relevant and permitted | Availability and price may depend on location. |
availability |
Observed stock/delivery indication, if provided | It is a point-in-time observation. |
These fields are an editorial recommendation for traceable research, not fields mandated by Bricomarché. Minimize retained personal data and avoid collecting it unless the permission explicitly includes it.
3. Choose an authorized data source and collection method
Prefer a site-approved feed or export
A feed or export avoids guessing at page markup and often provides a clearer scope and update process. Ask whether it includes seller, fulfillment channel, price, stock, locale/store scope, update timestamps, and any restrictions on retention or republication. Confirm whether marketplace offers are included and how third-party seller data should be attributed. Do not infer that such a feed exists: none was verified in the research.
Use HTTP parsing only when permitted
If the site authorizes particular pages and those pages contain the needed content in their HTML, a conventional HTTP client and HTML parser are usually the smaller implementation. Browser automation is only relevant when authorized content requires client-side rendering or browser interaction. This research did not inspect Bricomarché’s live product DOM or test a scraper against it. No CSS selector, JSON-LD property, endpoint, pagination behavior, or product URL pattern is asserted here.
The runnable example below demonstrates a safe development technique: parse a local HTML fixture whose structure you control. It makes no network request and is not a Bricomarché page. Replace its selectors only after the source owner has approved access and you have verified the permitted source’s actual structure.
4. Build and parse a local fixture
Create a small fixture so your extraction logic, schema, and error handling can be developed without contacting the site.
Fixture: product.html
<article class="product">
  <h1 class="name">Example garden tool</h1>
  <div class="description">Example description for parser development.</div>
  <span class="price">19.90</span>
  <span class="currency">EUR</span>
  <span class="seller">Example seller</span>
  <span class="offer-type">Example channel</span>
</article>
Python parser using Beautiful Soup
Install the parser with python -m pip install beautifulsoup4. Save the fixture above as product.html, then save and run this script. The selectors are specific to the fixture, not Bricomarché.
from datetime import datetime, timezone
from pathlib import Path
from bs4 import BeautifulSoup

html = Path("product.html").read_text(encoding="utf-8")
soup = BeautifulSoup(html, "html.parser")

def text_or_none(selector):
    node = soup.select_one(selector)
    return node.get_text(" ", strip=True) if node else None

record = {
    "source_url": "local-fixture://product.html",
    "retrieved_at": datetime.now(timezone.utc).isoformat(),
    "product_name": text_or_none(".name"),
    "description": text_or_none(".description"),
    "displayed_price": text_or_none(".price"),
    "currency": text_or_none(".currency"),
    "seller": text_or_none(".seller"),
    "offer_type": text_or_none(".offer-type"),
}

required = ("product_name", "displayed_price", "seller", "offer_type")
missing = [field for field in required if not record[field]]
if missing:
    raise ValueError(f"Fixture is missing required fields: {', '.join(missing)}")

print(record)
For production work, validate and normalize values only after retaining the source observation. Prices need an explicit currency and locale-aware parsing; a displayed amount is not enough to infer a durable numeric value. Keep the original text where practical so conversion errors can be diagnosed.
cURL for a permitted, authorized source
Only after authorization, a basic request can retrieve a page whose URL and access method are explicitly permitted. This template does not name a Bricomarché product URL or claim that the site permits it. Do not use it against the currently disallowed /fr/p/ path as a general crawler.
curl --fail --silent --show-error \
  --user-agent "AuthorizedResearchBot/1.0 (contact: you@example.org)" \
  "https://approved.example/path" \
  --output permitted-page.html
Node.js parsing for the same fixture
This local example uses the built-in filesystem API and requires no parser package:
import { readFile } from 'node:fs/promises';

const html = await readFile('product.html', 'utf8');
const get = (className) => {
  const match = html.match(new RegExp(`<[^>]*class="${className}"[^>]*>(.*?)</`, 's'));
  return match?.[1]?.trim() ?? null;
};

const record = {
  source_url: 'local-fixture://product.html',
  retrieved_at: new Date().toISOString(),
  product_name: get('name'),
  description: get('description'),
  displayed_price: get('price'),
  currency: get('currency'),
  seller: get('seller'),
  offer_type: get('offer-type'),
};

const required = ['product_name', 'displayed_price', 'seller', 'offer_type'];
const missing = required.filter((key) => !record[key]);
if (missing.length) throw new Error(`Missing fixture fields: ${missing.join(', ')}`);
console.log(record);
This deliberately limited regular-expression parser is suitable only for the simple fixture shown. For authorized real HTML, use a proper HTML parser and test against saved, permitted samples; HTML nesting, entities, and markup variation make regular expressions brittle.
5. Or skip the browser setup
If your authorized workflow needs a screenshot of a page for visual review or a rendered record, ScreenshotNeo is a website screenshot API and MCP server from Yorker Media. One GET request returns PNG, JPEG, WebP, or PDF output. A screenshot is a visual capture, not a substitute for permission to collect a disallowed page or a structured product feed.
For an authorized target URL, the one-call request is:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://example.com/authorized-page \
  -o shot.webp
See the ScreenshotNeo API documentation for request options. Cookie banners, popups, and chat widgets are removed before the shot; bot checks, blank pages, and failed loads are never billed. Its MCP server lets AI agents take screenshots. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Use it only with URLs you are authorized to capture.
Sign up for 1,000 free screenshots a month, with no card required.
6. Reliability, performance, and cost controls
- Refresh volatile fields. Price, promotion, stock, fulfillment, and offer availability can change. Timestamp every observation and refresh close to the point when a comparison is published.
- Keep offers separate. A retailer home-delivery offer, store pickup offer, and marketplace partner offer may have different terms, sellers, prices, and availability. Do not combine them under one price without context.
- Make missing data visible. Store a missing or unavailable value as such. Do not silently reuse an old price or infer stock from a product description.
- Use conservative request behavior. Follow the approved scope and rate limits. Stop on access-denied responses, unexpected challenges, or signs that the permission does not cover the requested content.
- Track provenance. Keep source URL, retrieval timestamp, parser version, and authorization scope with each batch. This helps reproduce a record without misrepresenting a snapshot as current.
- Budget the full workflow. No supported request-rate, accuracy, catalog-size, or performance figures were found. Estimate cost only after the approved source, volume, refresh schedule, and any licensed feed terms are known. Avoid increasing crawl volume to compensate for uncertain selectors.
7. Troubleshooting
| Symptom | Likely cause | Action |
|---|---|---|
/fr/p/ is disallowed in robots.txt |
The current general crawler rule covers the product path. | Do not crawl it as a general crawler. Request written permission or an approved data source. |
| A named bot has a separate allowance | The rule is specific to that crawler identity. | Do not claim that allowance for your own scraper or impersonate that bot. Obtain your own authorization. |
| The requested feed or API cannot be found | No public API, feed, or export was verified by this research. | Ask Bricomarché directly; do not guess hidden endpoints from browser traffic. |
Fixture parser returns None |
Fixture markup differs from the sample, or a selector/class was changed. | Inspect the local fixture and update selectors; add a test case for missing fields. |
| Price parses inconsistently | Locale punctuation, currency, or TTC context was discarded. | Retain the displayed string and currency, then apply an explicit locale-aware conversion. |
| Two records for one item disagree | They may represent distinct sellers, channels, store scopes, or retrieval times. | Compare offer context and timestamps; preserve separate observations instead of selecting one silently. |
| Page returns a challenge or access-denied response | Access may be restricted or your authorization may not cover the request. | Stop automated requests and contact the site owner. Do not bypass the challenge. |
8. FAQ
Does robots.txt prove that scraping is illegal?
No legal conclusion follows from the crawler directive alone. It is an access signal that should be respected in the workflow; obtain site-specific permission and legal advice where needed.
Can I use the sitemap to collect product pages?
The robots file lists a sitemap, but that does not override the disallow rule or establish authorization to crawl product paths. Ask for an approved source or permission.
Can I rely on product price or stock in an old dataset?
Only as a dated historical observation with seller and channel context. Recheck current offers before making a current price or availability claim.
Is a screenshot enough to build a product database?
No. A screenshot records rendered appearance. For structured fields and repeatable research, use an authorized feed or permitted source with a documented schema.
Sources and scope
- Bricomarché robots.txt, checked 29 September 2026. Its directives are current crawler rules, not a permission contract.
- Bricomarché online sales terms (CGV), version dated 29 April 2026, cited in the research dossier for product descriptions, home-delivery offers, and channel-specific pricing.
- Bricomarché marketplace terms, cited in the dossier for third-party sellers and responsibility for their offer descriptions.
The research did not verify the live product DOM, selectors, JSON-LD fields, a public API/feed/export, scraping permission, or private agreements. Check robots rules, terms, and offer details again near collection and publication.


