How to Scrape Sports Pages From Cadena SER
Build a respectful Cadena SER sports scraper with RSS-first discovery, robots.txt checks, resilient parsing, deduplication, and compliance safeguards.
Short answer: start with Cadena SER’s RSS feeds for sports discovery, then fetch article HTML only when the feed does not contain a field you need. Before every crawl plan, read https://cadenaser.com/robots.txt, obey the current rules, identify your client, keep concurrency low, cache responses, and stop when the site repeatedly returns errors. Store canonical URLs and content hashes so refreshes update records instead of creating duplicates.
This guide shows a complete Python implementation, equivalent cURL and Node.js requests, extraction from RSS, JSON-LD and semantic HTML, retry and caching policies, and the operational details that matter when collecting sports headlines from Cadena SER Deportes. It is designed for internal indexing, alerts, research and other uses that respect SER’s terms. Do not republish full articles or audio, bypass CAPTCHAs or paywalls, or attempt to access accounts and protected systems.
1. Choose RSS before scraping article HTML
RSS usually gives you the fields needed for discovery with fewer requests: title, URL, publication time, summary and sometimes an author or category. The SER Deportivos page exposes RSS as a distribution option, and SER’s privacy policy explicitly discusses RSS subscriptions. Inspect the sports landing page and its metadata to find the feed URL, then record which fields it actually supplies.
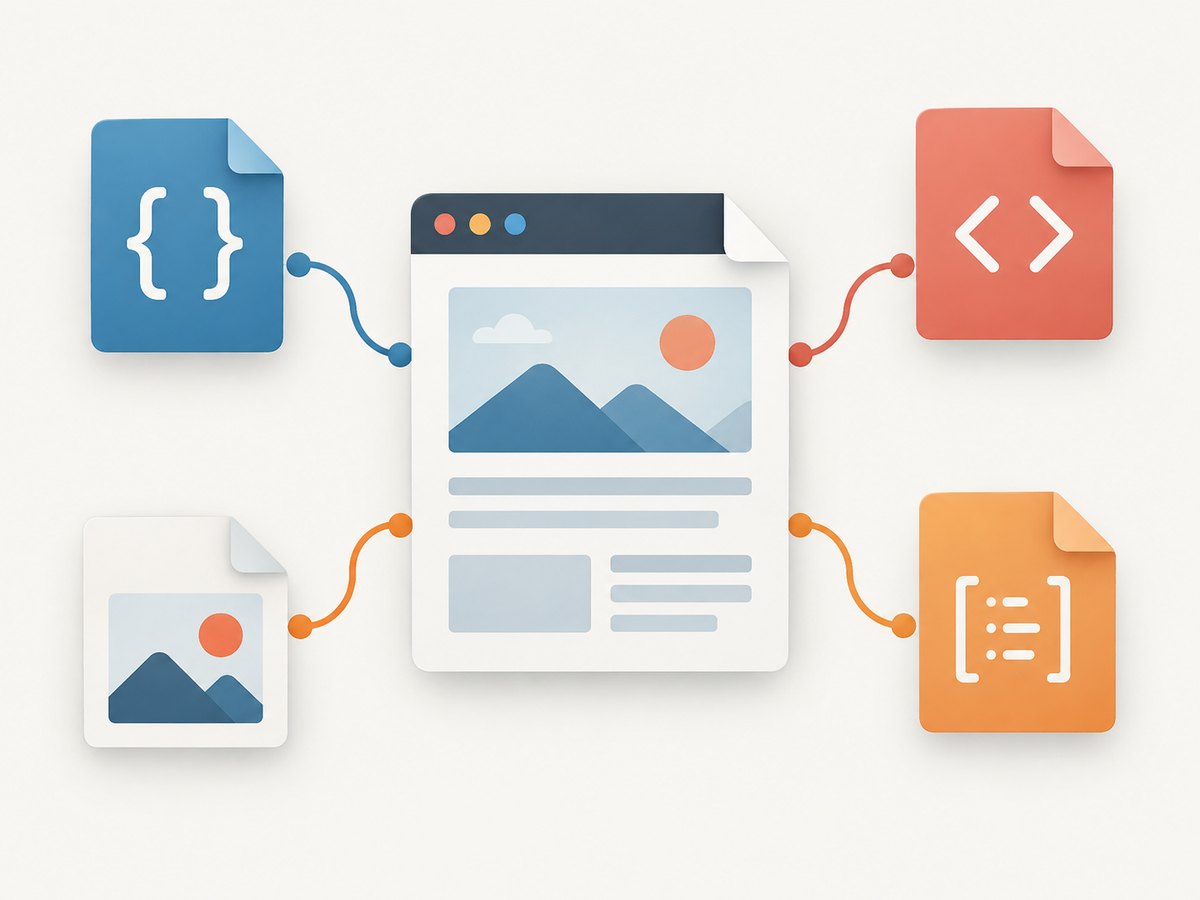
| Need | Best source | Why |
|---|---|---|
| New story discovery | RSS | Small responses and predictable polling |
| Canonical URL and complete metadata | Article HTML | Read JSON-LD and canonical link tags |
| Body text or a short permitted excerpt | Article HTML | Only when your use case requires it |
| Historical or high-volume collection | Evaluate a managed API | Compare terms, cost, geography and retention first |
Do not assume a feed URL is permanent. Discover it from current page metadata, test the response content type, and save the time and URL of each discovery. Poll feeds more frequently than full pages; once an article has stayed unchanged through several checks, stop fetching it.
2. Check robots.txt and legal controls
Fetch robots.txt at runtime, parse the user-agent groups, and exclude every path disallowed for your client. A September 2026 third-party snapshot reported 12 disallowed paths, but that is a dated observation rather than a permanent SER rule. Your crawler must use the live file.
import urllib.robotparser

ROBOTS_URL = 'https://cadenaser.com/robots.txt'
USER_AGENT = 'ExampleSportsIndexer/1.0 (+mailto:ops@example.org)'

rp = urllib.robotparser.RobotFileParser(ROBOTS_URL)
rp.read()

if not rp.can_fetch(USER_AGENT, 'https://cadenaser.com/deportes/'):
    raise RuntimeError('robots.txt disallows this URL for the configured client')
Read SER’s legal notice before deployment. It states that SER reserves the right to deny or withdraw access to its website. Keep your traffic appropriate, honor those controls, and stop a crawl when access is withdrawn or the site signals that your behavior is unwanted. SER’s privacy policy describes IP and navigation data, including the service used and usage timing, so protect crawler logs and retain them only as long as your documented purpose requires.
3. A complete RSS-first scraper in Python
The following program discovers items from a configured RSS URL, normalizes links, deduplicates by canonical URL, and optionally fetches an article for missing metadata. Install dependencies with pip install requests feedparser beautifulsoup4. Replace FEED_URL after inspecting the current SER sports page; the example deliberately does not hard-code an unverified feed address.
from __future__ import annotations

import hashlib
import json
import re
import time
from datetime import datetime, timezone
from pathlib import Path
from urllib.parse import parse_qsl, urlencode, urljoin, urlsplit, urlunsplit

import feedparser
import requests
from bs4 import BeautifulSoup

FEED_URL = 'https://example.org/current-ser-sports-feed.xml'
START_URL = 'https://cadenaser.com/deportes/'
USER_AGENT = 'ExampleSportsIndexer/1.0 (+mailto:ops@example.org)'
TIMEOUT = 30
CACHE_DIR = Path('cache')
DB_PATH = Path('stories.json')
TRACKING_KEYS = {'utm_source', 'utm_medium', 'utm_campaign', 'utm_term', 'utm_content', 'gclid', 'fbclid'}

session = requests.Session()
session.headers.update({'User-Agent': USER_AGENT, 'Accept': 'application/rss+xml, application/xml, text/html;q=0.9'})
CACHE_DIR.mkdir(exist_ok=True)


def normalize_url(raw: str) -> str:
    parts = urlsplit(raw)
    query = [(k, v) for k, v in parse_qsl(parts.query, keep_blank_values=True) if k not in TRACKING_KEYS]
    path = parts.path or '/'
    if path != '/' and path.endswith('/'):
        path = path[:-1]
    return urlunsplit((parts.scheme.lower(), parts.netloc.lower(), path, urlencode(query), ''))


def cache_path(url: str) -> Path:
    return CACHE_DIR / (hashlib.sha256(url.encode()).hexdigest() + '.json')


def get(url: str, attempts: int = 4) -> requests.Response:
    for n in range(attempts):
        response = session.get(url, timeout=TIMEOUT)
        if response.status_code not in (429, 500, 502, 503, 504):
            response.raise_for_status()
            return response
        if n == attempts - 1:
            response.raise_for_status()
        delay = min(60, 2 ** n) + 0.25 * n
        time.sleep(delay)
    raise RuntimeError('unreachable')


def jsonld_metadata(soup: BeautifulSoup) -> dict:
    for tag in soup.select('script[type="application/ld+json"]'):
        try:
            value = json.loads(tag.string or tag.get_text())
        except json.JSONDecodeError:
            continue
        candidates = value if isinstance(value, list) else [value]
        for item in candidates:
            if isinstance(item, dict) and ('headline' in item or item.get('@type') in ('NewsArticle', 'Article')):
                return item
    return {}


def parse_article(url: str) -> dict:
    response = get(url)
    soup = BeautifulSoup(response.text, 'html.parser')
    data = jsonld_metadata(soup)
    canonical_tag = soup.select_one('link[rel="canonical"]')
    canonical = normalize_url(canonical_tag.get('href')) if canonical_tag and canonical_tag.get('href') else normalize_url(url)
    title = data.get('headline') or (soup.select_one('h1').get_text(' ', strip=True) if soup.select_one('h1') else None)
    author = data.get('author')
    if isinstance(author, dict):
        author = author.get('name')
    published = data.get('datePublished')
    section = data.get('articleSection')
    extract = data.get('description') or ''
    if not extract:
        paragraph = soup.select_one('article p')
        extract = paragraph.get_text(' ', strip=True) if paragraph else ''
    return {'canonical_url': canonical, 'headline': title, 'author': author, 'published_at': published, 'section': section, 'extract': extract[:500], 'retrieved_at': datetime.now(timezone.utc).isoformat(), 'content_hash': hashlib.sha256(response.text.encode()).hexdigest()}


def main() -> None:
    feed_response = get(FEED_URL)
    feed = feedparser.parse(feed_response.content)
    old = json.loads(DB_PATH.read_text()) if DB_PATH.exists() else {}
    for entry in feed.entries:
        link = normalize_url(entry.get('link', ''))
        if not link or 'cadenaser.com' not in urlsplit(link).netloc:
            continue
        record = {'canonical_url': link, 'headline': entry.get('title'), 'author': entry.get('author'), 'published_at': entry.get('published'), 'section': 'sports', 'extract': entry.get('summary', '')[:500], 'retrieved_at': datetime.now(timezone.utc).isoformat()}
        if not record['headline'] or not record['published_at']:
            record.update(parse_article(link))
        record['content_hash'] = hashlib.sha256(json.dumps(record, sort_keys=True).encode()).hexdigest()
        old[link] = record
        time.sleep(1.0)
    DB_PATH.write_text(json.dumps(old, ensure_ascii=False, indent=2))


if __name__ == '__main__':
    main()
The parser treats JSON-LD as the first choice because fields such as headline, datePublished, author, articleSection and mainEntityOfPage are more stable than CSS class names. It falls back to a semantic h1 and the first article paragraph. Markup can change, so keep selectors short and alert when extraction returns empty fields.
4. Equivalent requests with cURL and Node.js
Use cURL to inspect a feed or article manually during development. Include a descriptive client identity and save headers so you can see caching signals.
curl --fail-with-body --max-time 30 \
  -A 'ExampleSportsIndexer/1.0 (+mailto:ops@example.org)' \
  -H 'Accept: application/rss+xml, application/xml, text/html;q=0.9' \
  -D response.headers \
  'https://cadenaser.com/deportes/' -o response.html
Node.js 18 or newer includes fetch. This example implements bounded retries and a delay for rate limiting responses.
const wait = ms => new Promise(resolve => setTimeout(resolve, ms));

async function get(url) {
  for (let attempt = 0; attempt < 4; attempt++) {
    const res = await fetch(url, {
      headers: {
        'user-agent': 'ExampleSportsIndexer/1.0 (+mailto:ops@example.org)',
        'accept': 'application/rss+xml, application/xml, text/html;q=0.9'
      }
    });
    if (![429, 500, 502, 503, 504].includes(res.status)) {
      if (!res.ok) throw new Error(`HTTP ${res.status} for ${url}`);
      return res;
    }
    if (attempt === 3) throw new Error(`repeated HTTP ${res.status} for ${url}`);
    await wait(Math.min(60000, 2 ** attempt * 1000));
  }
}

const response = await get('https://cadenaser.com/deportes/');
const html = await response.text();
console.log(html.length);
5. Normalize, deduplicate and refresh safely
- Prefer the page’s canonical link over the feed URL.
- Lowercase scheme and host, remove fragments and known tracking parameters, and normalize trailing slashes.
- Use the normalized canonical URL as the primary key.
- Store a content hash. If the URL exists but the hash changes, create a revision or update timestamp instead of a second story.
- Save retrieval time, source URL, HTTP status and parser version for audits.
For larger stores, hash the canonical URL as the database key. Send conditional requests with If-None-Match and If-Modified-Since when SER supplies ETag or Last-Modified headers. A 304 response avoids downloading an unchanged page. Poll RSS on a schedule appropriate to your use case, then fetch only new or recently changed articles.
6. Request pacing, privacy and compliance checklist
- Start with one request at a time while validating selectors.
- Use a descriptive User-Agent with a monitored contact address.
- Set connection and total timeouts; never leave sockets unbounded.
- Back off exponentially for 429 and 5xx responses, adding jitter for multiple workers.
- Cache successful responses and stop after repeated failures.
- Do not bypass bot checks, CAPTCHAs, authentication, paywalls or rate limits.
- Keep only the minimum excerpt needed for indexing or a permitted display, and link to the original story.
- Restrict access to IP and navigation logs and define a deletion period.
- Recheck robots.txt, terms, feed availability and markup before each production rollout.
7. Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| 403 or 429 | Requests are too frequent, unidentified or disallowed | Read live robots.txt, lower concurrency, identify the client, back off and stop if errors continue |
| Feed parses with zero entries | Wrong URL, HTML returned, malformed XML or a changed feed | Check status and Content-Type, inspect the body, rediscover RSS metadata and validate XML |
| Missing headline or date | Feed omits fields or JSON-LD shape changed | Use canonical HTML, inspect JSON-LD graphs, then fall back to semantic elements and alert on empty output |
| Duplicate stories | Tracking parameters, alternate paths or redirects | Follow redirects, normalize URLs, prefer canonical and upsert by normalized key |
| Many timeouts | Slow response, network issue or an intentional block | Use bounded timeouts, one retry policy, caching and a circuit breaker; do not increase concurrency |
| Content changes between runs | Article edited after publication | Compare content hashes and store revisions with retrieval timestamps |
8. When a managed API is appropriate
If you need many URLs, multiple regions, scheduled retries or centralized extraction, compare a managed service against your own worker. Evaluate coverage of required fields, freshness, request volume, blocking risk, operating cost, data retention, geography and recovery when markup changes. A Crawlbase cookbook describes an API-oriented cadenaser.com/deportes workflow and reports a 99.4% success rate for its own accounts in August 2026; that is a dated, vendor-reported result rather than a guarantee. Validate current terms and run your own representative trial.
Or skip the browser setup
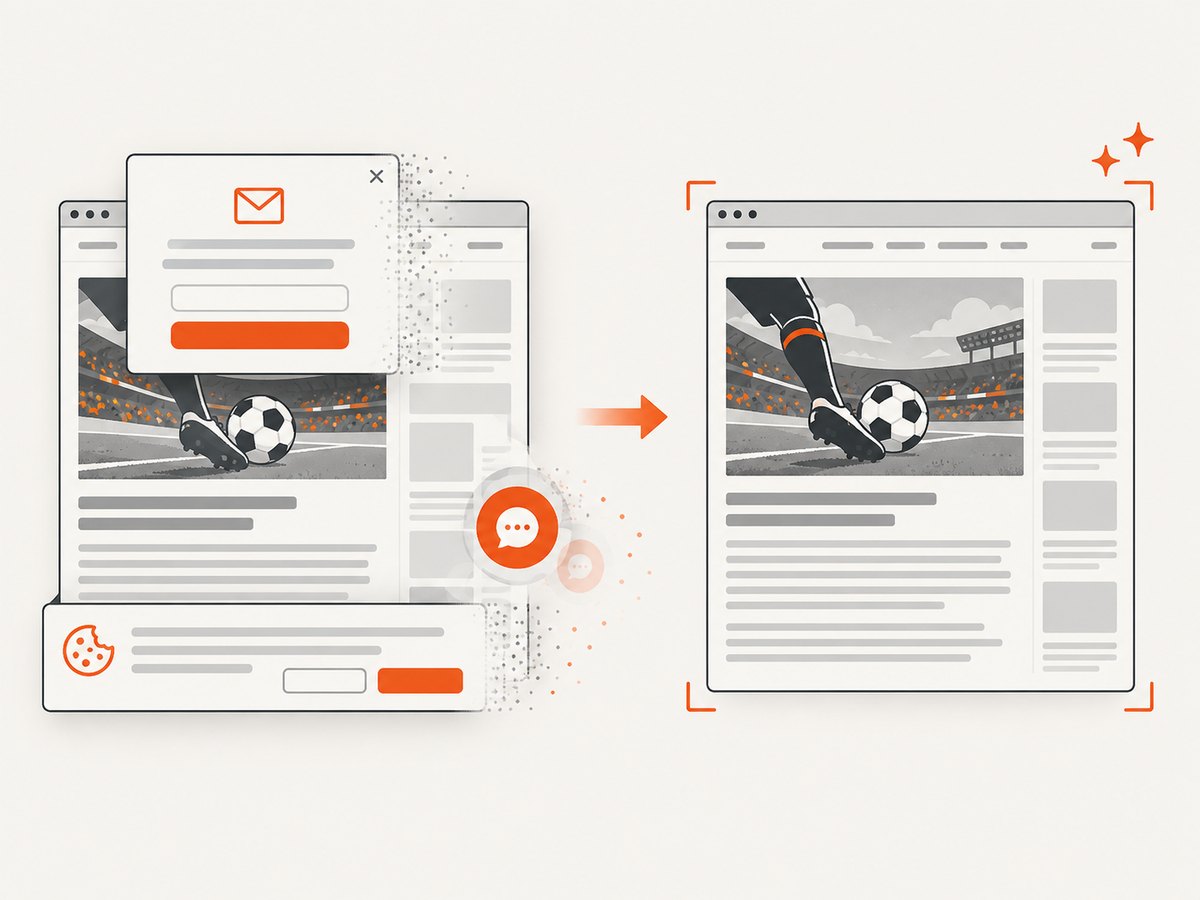
For a rendered snapshot of a SER sports page, ScreenshotNeo provides one GET request that returns PNG, JPEG, WebP or PDF. It can accept cookie and consent banners as a visitor and remove more than 60 known consent platforms, newsletter popups and chat widgets before capture; each step can be disabled. Bot checks, blank pages, timeouts, failed loads and cache hits are not billed, and the response identifies the page verdict and billing state in X-Page-Verdict and X-Billed headers.
See the ScreenshotNeo API documentation for all options. This is a screenshot request, so it complements an RSS or HTML scraper when you need a visual record or want to inspect rendered content.
curl -G 'https://api.screenshotneo.com/v1/shot' -d access_key=YOUR_API_KEY --data-urlencode url=https://cadenaser.com/deportes/ -o ser-deportes.webpimport requests
r = requests.get('https://api.screenshotneo.com/v1/shot', params={'access_key': 'YOUR_API_KEY', 'url': 'https://cadenaser.com/deportes/'}, timeout=90)
r.raise_for_status()
open('ser-deportes.webp', 'wb').write(r.content)
print(r.headers.get('X-Page-Verdict'), r.headers.get('X-Billed'))const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://cadenaser.com/deportes/' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`HTTP ${res.status}`);
const fs = await import('node:fs/promises');
await fs.writeFile('ser-deportes.webp', Buffer.from(await res.arrayBuffer()));
console.log(res.headers.get('X-Page-Verdict'), res.headers.get('X-Billed'));ScreenshotNeo also offers full-page capture with lazy images loaded, CSS-element capture, custom JavaScript and CSS, waits for selectors or network idle, request blocking, custom headers and cookies, device presets, PDF output, caching with a chosen TTL, signed links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs per call, a usage API and an MCP server with take_screenshot, get_page_info and capture_pdf for Claude, Cursor and other MCP clients. The Free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
FAQ
Can I scrape every Cadena SER sports article?
Only where the current robots.txt, legal terms and your use case allow it. Scope requests to the fields and pages you need, and stop when access is denied.
Is RSS enough for a news alert?
Often yes for discovery. Fetch HTML only to fill fields the feed does not provide or to verify a changed story.
Should I store full article text?
Usually no. Store metadata and a short permitted extract, retain the canonical URL, and link readers to SER.
How often should I poll?
Choose an interval based on freshness needs, then reduce article fetches with ETag, Last-Modified and content-hash checks. Increase frequency only when your measured need justifies the extra traffic.
What should happen after repeated errors?
Open a circuit breaker, record the status and timestamp, notify an operator if necessary, and resume slowly after checking robots.txt and site guidance.


