How to Scrape Content Pages from Corporate Websites
A practical guide to discovering, politely crawling, and extracting corporate blogs, news, and resource pages with Python—while respecting site rules and privacy.
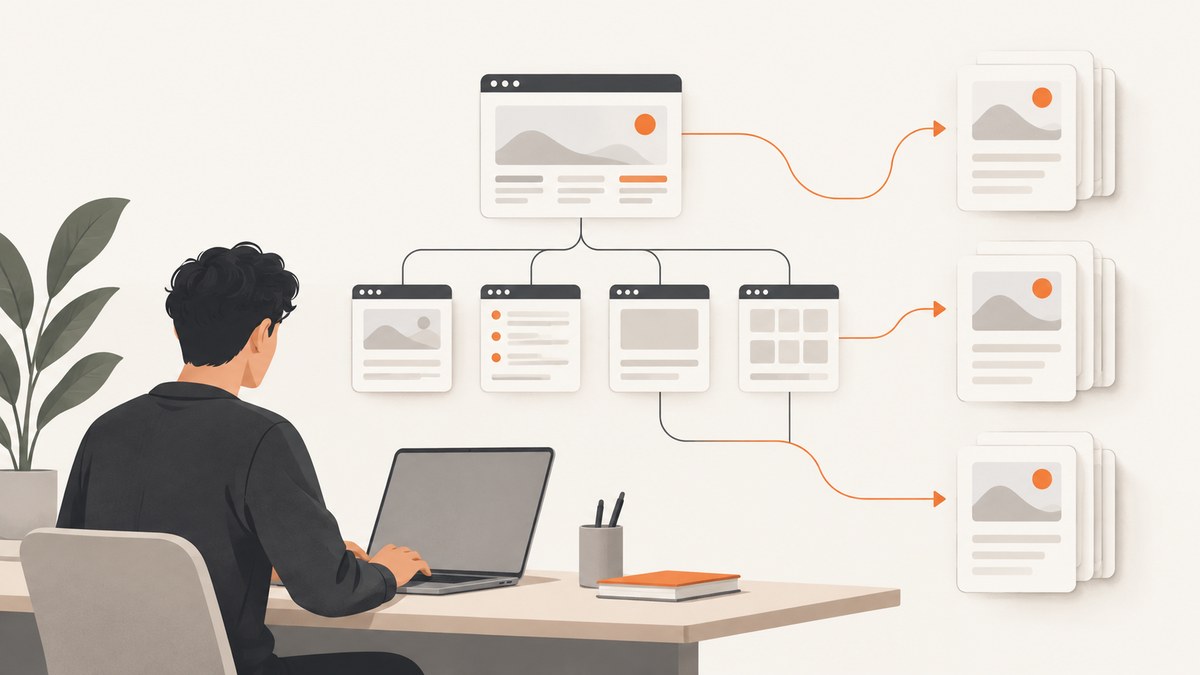
To scrape corporate content pages, first define which sections and fields you need, then check the site’s terms, robots.txt, sitemaps, feeds, and APIs. For permitted public pages, discover URLs from sitemaps, fetch them politely, parse semantic fields from HTML, and save both extracted data and provenance. Use a regular HTTP client for stable server-rendered pages; use Scrapy when you need a recurring crawl, pipelines, and deduplication. For JavaScript-rendered pages, prefer a documented endpoint or feed; use browser automation only when permitted.
This guide builds a small Python crawler that reads sitemap URLs and extracts article metadata. It also covers scope, privacy, validation, errors, and when a screenshot helps diagnose a page whose content is rendered in the browser.
1. Define scope before collecting
“All content pages” is not a precise crawl scope. A corporate website might contain a blog, press releases, investor news, case studies, resource downloads, job listings, and support articles. These sections have different formats, freshness requirements, and privacy implications.
Write down the crawl contract before sending requests:
- Page types: for example, blog posts and press releases, excluding search results and login pages.
- Allowed hosts and paths: decide whether subdomains and linked document hosts are in scope.
- Fields: title, canonical URL, author, publication and update dates, headings, body, tags, language, and linked assets.
- Freshness and retention: how often to revisit pages and how long to keep raw HTML or extracted records.
- Personal data: whether bylines, biographies, comments, or contact details are necessary for the stated purpose.
- Output: JSON Lines, a database, or another structured destination, plus required audit metadata.
Keep the scope narrow enough to explain why each field is needed. If the purpose changes, review the scope and site rules again.
2. Check site rules and preferred access
Before crawling, inspect the exact host and protocol you intend to fetch. Read its terms and API documentation, then check https://example.com/robots.txt, sitemap references, RSS or Atom feeds, and navigation. Use the company’s documented API, export, or feed when one serves the purpose; it is usually a clearer interface than parsing page markup.
Robots rules are scoped to the host, protocol, and port where the file is served. A robots file may point to a sitemap or publish a crawl delay. These directives are crawler guidance, not access control and not permission to collect restricted material. A crawler should respect the site’s stated rules and stop when it encounters repeated blocks.
Privacy and legal considerations depend on jurisdiction, purpose, data, and access conditions. The European Data Protection Board says GDPR applies when scraping involves processing personal data, and highlights purpose limitation, transparency, minimisation, reliable sources, timestamps, and validation. CNIL notes that scraping is not inherently prohibited under GDPR, while recommending that collectors exclude sites that object through terms, CAPTCHAs, or robots.txt. Treat these as reasons to assess the actual collection, not as blanket authorization. Do not bypass authentication, CAPTCHAs, paywalls, or technical blocks. Prefer excluding personal data unless it is necessary and lawfully collected.
3. Discover corporate content URLs
Start with the site root’s robots file and follow every listed sitemap. A sitemap index can reference child sitemaps; those may contain thousands of URLs. Filter discovered links against your allowed hosts and content paths before fetching pages. Also inspect feeds and navigation, and retain canonical links found in each page to consolidate duplicates.

Exclude paths and parameters that are outside the agreed scope, such as account pages, internal search, tracking parameters, and duplicate pagination variants. Do not assume every sitemap URL is an article: validate page type after retrieval.
The script below is a deliberately small starting point for a permitted, low-volume crawl. It fetches sitemap XML, filters to a chosen path prefix, requests pages with an identifying user agent, and extracts common article fields. It writes one JSON record per line and records retrieval time, HTTP status, parser version, and a content hash. Install dependencies with python -m pip install requests beautifulsoup4.
import hashlib
import json
import time
from datetime import datetime, timezone
from urllib.parse import urlparse
from urllib.robotparser import RobotFileParser

import requests
from bs4 import BeautifulSoup

ROOT = "https://example.com"
ROBOTS_URL = ROOT + "/robots.txt"
USER_AGENT = "ExampleResearchCrawler/1.0 (contact: crawler@example.org)"
ALLOWED_HOST = "example.com"
CONTENT_PREFIXES = ("/blog/", "/news/", "/resources/")
PARSER_VERSION = "1"
DELAY_SECONDS = 2
TIMEOUT = 20

session = requests.Session()
session.headers.update({"User-Agent": USER_AGENT})

# Read and honor this host's published robots directives.
robots_response = session.get(ROBOTS_URL, timeout=TIMEOUT)
robots_response.raise_for_status()
robots = RobotFileParser()
robots.set_url(ROBOTS_URL)
robots.parse(robots_response.text.splitlines())

sitemap_urls = [
    line.split(":", 1)[1].strip()
    for line in robots_response.text.splitlines()
    if line.lower().startswith("sitemap:")
]
if not sitemap_urls:
    sitemap_urls = [ROOT + "/sitemap.xml"]

def get_xml_urls(sitemap_url):
    response = session.get(sitemap_url, timeout=TIMEOUT)
    response.raise_for_status()
    soup = BeautifulSoup(response.content, "xml")
    # Handles both sitemap indexes (loc children) and URL sets.
    return [loc.get_text(strip=True) for loc in soup.find_all("loc")]

def sitemap_page_urls(urls):
    pages = []
    for url in urls:
        if urlparse(url).netloc == ALLOWED_HOST and url.lower().endswith(".xml"):
            pages.extend(sitemap_page_urls(get_xml_urls(url)))
        else:
            parsed = urlparse(url)
            if parsed.scheme in ("http", "https") and parsed.netloc == ALLOWED_HOST:
                if parsed.path.startswith(CONTENT_PREFIXES):
                    pages.append(url)
    return pages

def text_or_none(node):
    return node.get_text(" ", strip=True) if node else None

seen = set()
for sitemap in sitemap_urls:
    for url in sitemap_page_urls(get_xml_urls(sitemap)):
        if url in seen or not robots.can_fetch(USER_AGENT, url):
            continue
        seen.add(url)
        time.sleep(DELAY_SECONDS)
        try:
            response = session.get(url, timeout=TIMEOUT)
            status = response.status_code
            if status in (403, 429):
                # Stop rather than retrying access restrictions or rate limits.
                break
            response.raise_for_status()
        except requests.RequestException as exc:
            print(json.dumps({"url": url, "error": str(exc)}))
            continue

        soup = BeautifulSoup(response.text, "html.parser")
        canonical_tag = soup.select_one('link[rel="canonical"]')
        canonical = canonical_tag.get("href") if canonical_tag else url
        title = text_or_none(soup.select_one("article h1")) or text_or_none(soup.title)
        article = soup.select_one("article") or soup
        for node in article.select("nav, footer, aside, script, style, noscript"):
            node.decompose()
        body = text_or_none(article)
        date_tag = soup.select_one("time[datetime]")
        author_tag = soup.select_one('[rel="author"], [itemprop="author"]')
        headings = [h.get_text(" ", strip=True) for h in article.select("h2, h3")]
        digest = hashlib.sha256(response.content).hexdigest()
        record = {
            "url": url,
            "canonical_url": canonical,
            "title": title,
            "author": text_or_none(author_tag),
            "published_or_updated": date_tag.get("datetime") if date_tag else None,
            "headings": headings,
            "body": body,
            "retrieved_at": datetime.now(timezone.utc).isoformat(),
            "http_status": status,
            "parser_version": PARSER_VERSION,
            "content_sha256": digest,
        }
        print(json.dumps(record, ensure_ascii=False))
Replace the example host, contact, path prefixes, and user agent with accurate values for the project. Check the sitemap format and site structure: the code demonstrates discovery, but real sitemap indexes can be nested or compressed, and a site may publish multiple content hosts. Add those deliberately rather than broadening scope automatically.
4. Choose the right extraction method
HTTP plus BeautifulSoup
For server-rendered pages and a small set of URLs, a simple HTTP client plus BeautifulSoup is easy to inspect and adapt. Requests retrieves the HTML; BeautifulSoup lets you select elements and normalize text. The main weakness is that selectors and page templates can change. Use site-specific selectors and validate required fields instead of treating every response as a valid article.
Scrapy for recurring multi-page crawls
Use Scrapy when the job spans many sections, needs scheduled runs, structured output, retry settings, item pipelines, or crawl-wide deduplication. Model article extraction as an item, and keep fetching rules and parsing rules distinct. Store failed records and run logs for review. Scrapy does not make a crawl permitted by itself; the same scope, rate limits, and stop conditions apply.
APIs, feeds, and JavaScript-rendered pages
If a page’s text is absent from the returned HTML, first look for a documented API, RSS/Atom feed, or permitted JSON endpoint. These interfaces can offer more stable fields and pagination than rendered markup. If no suitable interface exists and browser automation is allowed, render only the needed pages, keep concurrency low, and avoid interacting with access controls. Browser rendering costs more time and resources than parsing static HTML.
When a page’s visible state matters—for example, checking whether a cookie banner obscures content—a screenshot can help debug the rendering. ScreenshotNeo is a website screenshot API and MCP server from Yorker Media. Its capture options include waits, selector capture, custom CSS, and JavaScript. A screenshot is useful for visual inspection, but it does not replace the semantic text extraction and provenance fields in a crawler.
5. Extract fields and preserve provenance
Prefer semantic markup and structured metadata over brittle positional selectors. Common sources include the article’s h1, canonical link, time element, author metadata, headings, body container, tags, and JSON-LD. Site templates vary, so check multiple candidates and record when a value is missing instead of silently inventing one.
Remove navigation, cookie dialogs, related-story modules, and footers from the extracted body using site-specific rules. A generic “main” or “article” selector is a useful start, not a guarantee. Preserve linked documents and their URLs as asset references; only download them if they are in scope and permitted.
For every record, keep the source URL, canonical URL, retrieval timestamp, response status, parser version, and a content hash. The raw HTML can be retained when the purpose and retention policy allow it. Hashes or field-level snapshots make it possible to identify layout changes, repeated content, and meaningful updates.
6. Be polite and resilient
Send a descriptive user agent with a contact route, cap concurrency, respect published crawl delays, and cache responses. For transient network failures and server errors, use a small retry count with exponential backoff and jitter. Avoid retrying 401, 403, or 429 responses automatically: these may indicate a restriction or a request to slow down. Stop or reduce scope when you receive repeated blocks.
For recurring jobs, use conditional requests such as If-Modified-Since or If-None-Match when the server provides validators. A 304 response means the stored version is still current, so you can skip parsing and avoid needless transfer. Deduplicate by normalized canonical URL and content hash. Keep crawl frequency tied to how quickly the source changes; a daily crawl of infrequently updated pages increases load without necessarily improving the dataset.
7. Validate and monitor each run
- Confirm status is successful and redirects remain within approved hosts.
- Check that canonical URLs remain in scope and do not multiply query-string variants.
- Validate dates, language, and required fields; flag missing or implausible values.
- Ensure sitemap pagination and nested indexes terminate without duplicate loops.
- Compare hashes or field-level diffs and alert on sudden missing-body rates or selector failures.
- Log request counts, errors, response times, and the URLs skipped by scope or robots rules.
Track changes in both site behavior and your own purpose. If a layout change breaks extraction, pause that parser path and repair it before treating empty or malformed records as real content. If the organization objects or access conditions change, stop and reassess.
8. Troubleshooting
| Symptom | Likely cause | What to do |
|---|---|---|
| No sitemap URLs found | The robots file omits a sitemap, the sitemap has another location, or the site uses a feed. | Check navigation and documented feeds; try the sitemap location linked from the site. Do not guess at hidden endpoints. |
| XML parser returns no locations | The response is HTML, compressed, namespaced differently, or an error page. | Check status, content type, and response body. Use an XML parser that handles namespaces and gzip where needed. |
| Every request returns 403 or 429 | The site is refusing or limiting automated access. | Stop the crawl, review terms and published guidance, and seek an approved API or permission. Do not rotate identities or bypass the block. |
| Title or body is missing | The selector does not match this template, or content is rendered client-side. | Inspect the returned HTML and structured data. Find a permitted API/feed; if unavailable, use approved browser automation sparingly. |
| Duplicate articles appear | Tracking parameters, alternate hosts, redirects, or print pages create URL variants. | Normalize URLs, follow redirects carefully, and deduplicate by canonical URL and content hash. |
| Dates conflict or look implausible | Updated date is mistaken for published date, timezone omitted, or metadata is stale. | Keep source date fields distinct, record the raw value, normalize timezone explicitly, and flag uncertain dates. |
| Text contains navigation or consent copy | The chosen body container includes site boilerplate. | Use page-specific selectors and remove known boilerplate nodes before collecting text; review sample records after template changes. |
9. Performance, reliability, and cost
For a small collection, the principal costs are engineering time, transfer, and storage. At larger scale, browser rendering, recurring recrawls, and operational monitoring add compute and maintenance. There is no reliable universal request rate or success rate for corporate sites: each host, scope, and permission model differs. Tune concurrency conservatively and measure response times and errors on the target host.
Reliability comes from being explicit about failure. Store failed URLs and statuses, retry only transient failures, and make reruns idempotent through URL and content-hash deduplication. Cache pages and use conditional requests where available. Keep the parser version beside each record so later changes can be traced.
For browser-based visual checks or screenshot artifacts, ScreenshotNeo’s API can capture a page as PNG, JPEG, WebP, or PDF. It bills only clean shots: bot checks/CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing, with verdict and billing details in response headers. Its pricing is Free for 1,000 shots per month, then Starter $5 for 3,000, Growth $15 for 15,000, Pro $39 for 60,000, Scale $99 for 250,000, and Business $249 for 1,000,000; yearly billing gives two months free. Every feature is on every plan. See the [ScreenshotNeo site](https://screenshotneo.com) and [API documentation](https://screenshotneo.com/docs/).
Or skip the browser setup
If you need a screenshot to inspect a rendered page, call ScreenshotNeo with one GET request:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpCookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, and failed loads are never billed. An MCP server lets AI agents use screenshot tools. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. This is for visual capture, while your crawler remains responsible for permitted text extraction and audit records. Get [1,000 free screenshots a month with no card](https://screenshotneo.com/account/sign-up/).
10. A compact run checklist
- Define page types, fields, hosts, freshness, retention, and whether personal data is needed.
- Review terms, robots rules, sitemap references, feeds, and official APIs.
- Filter sitemap URLs to the agreed content paths and deduplicate before fetching.
- Use an identifying user agent, conservative request pacing, caching, and clear stop conditions.
- Extract semantic fields and preserve retrieval time, status, parser version, and hash.
- Validate required fields and review sample records and diffs on every run.
11. Frequently asked questions
Can robots.txt tell me every content URL?
No. It may list sitemap locations and crawler guidance, but it is not a complete catalog or a permission grant. Combine permitted sitemaps with feeds and navigation.
Should I scrape the company’s employee biographies too?
Only if they are necessary for a clearly defined purpose and your collection complies with applicable privacy rules and site terms. Otherwise exclude personal data from scope.
How often should a corporate content crawl run?
Set frequency based on the source’s update cadence and your need for freshness. Use caching and conditional requests to avoid fetching unchanged pages.
What should I do if the site changes its layout?
Use missing-field and content-size checks to detect the change, pause affected extraction, inspect a sample page, then update and version the parser before resuming.
Further reading
- Google: robots.txt introduction and sitemaps overview.
- European Data Protection Board: guidance on web scraping and personal data.
- CNIL: scraping publicly accessible personal data.
- Ryan Mitchell, Web Scraping with Python, 3rd Edition, covering parsing, crawling, APIs, JavaScript, storage, and legal considerations.