How to Scrape Every Product from an E-Commerce Site
Build a verifiable product crawl from sitemaps, authorized APIs, and pagination, then extract, deduplicate, and reconcile every record.

To scrape every product from an e-commerce site, first define exactly which catalog you mean, then build a measurable inventory of product URLs from the site’s sitemap and any documented catalog API. Use category or search pagination to fill gaps, fetch only pages you are authorized to access, extract a stable schema, and reconcile discovered URLs against successful records and failures. A browser is needed only when the product data is rendered client-side and cannot be obtained through an authorized API or the HTML response.
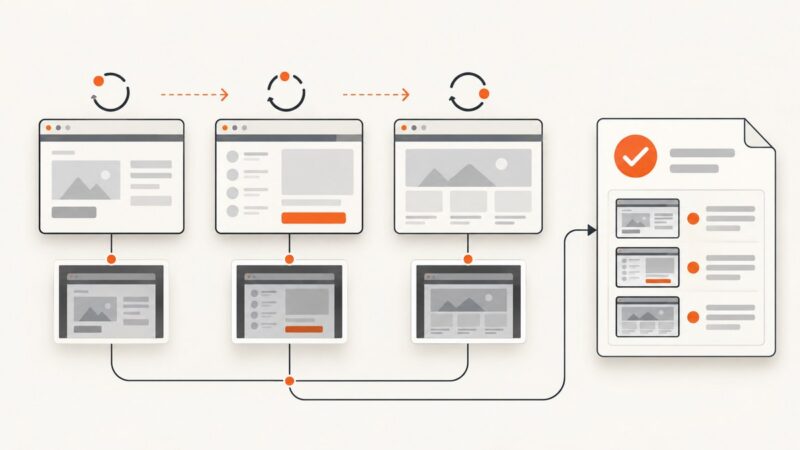
This guide covers a repeatable crawl workflow using Python and Scrapy, with runnable patterns for sitemap discovery, paginated APIs, extraction, deduplication, retries, and validation. Completeness is not a feeling: it is a countable relationship between URLs found, URLs fetched, product records parsed, and exceptions resolved.
1. Define the catalog boundary and permission
Before making requests, write down the crawl’s scope. “Every product” could mean all products in one language, all items currently in stock, every regional storefront, or every variant as a separate record. Those definitions produce different inventories.
- Host and paths: name the exact domain and allowed product URL patterns.
- Geography and language: specify storefront, currency, locale, and any regional variants.
- Variant policy: decide whether size/color variants are separate products or child rows under a parent.
- Stop condition: use a published total, API total, exhausted pagination token, or complete sitemap inventory.
- Permission: crawl only pages you own or are authorized to access. Check the site’s terms, authentication boundaries, and robots.txt before fetching. AWS says its Web Crawler defaults to disallow when robots.txt is missing; Amazon’s Product Discovery bot also respects robots.txt.
Robots rules are a crawl policy signal, not a substitute for authorization. Do not attempt to bypass a disallow rule, login wall, CAPTCHA, or other access control. If you are crawling your own store, coordinate the allowed paths and request rate with its operator.
2. Find product URLs before crawling pages
Start with robots.txt and sitemap files. A sitemap is generally a cleaner discovery source than clicking through the storefront because it can enumerate product URLs without depending on category navigation, sorting, or page layout. Sitemaps may point to other sitemaps, so parse the index recursively or use a framework that supports nested maps.

Scrapy’s official SitemapSpider documentation describes sitemap discovery from robots.txt, nested sitemaps, and rules that route URL patterns such as /product/ to a parser. The following small Python script is useful when you want to inspect one sitemap index and collect its URL entries. Install dependencies with python -m pip install requests.
from urllib.parse import urljoin
import xml.etree.ElementTree as ET
import requests

BASE = "https://shop.example"
ROBOTS = urljoin(BASE, "/robots.txt")
HEADERS = {"User-Agent": "CatalogAuditBot/1.0 (contact: ops@example.com)"}

def sitemap_locations(xml_text):
    root = ET.fromstring(xml_text)
    # Ignore the XML namespace by comparing local tag names.
    for node in root.iter():
        if node.tag.rsplit("}", 1)[-1] in {"loc"} and node.text:
            yield node.text.strip()

def fetch_xml(url):
    response = requests.get(url, headers=HEADERS, timeout=30)
    response.raise_for_status()
    return response.text

robots = fetch_xml(ROBOTS)
seeds = [line.split(":", 1)[1].strip() for line in robots.splitlines()
         if line.lower().startswith("sitemap:")]
seen_maps, product_urls = set(), set()
pending = list(seeds)
while pending:
    sitemap_url = pending.pop()
    if sitemap_url in seen_maps:
        continue
    seen_maps.add(sitemap_url)
    xml_text = fetch_xml(sitemap_url)
    root = ET.fromstring(xml_text)
    kind = root.tag.rsplit("}", 1)[-1]
    locations = list(sitemap_locations(xml_text))
    if kind == "sitemapindex":
        pending.extend(locations)
    else:
        product_urls.update(u for u in locations if "/product/" in u)

print(f"sitemaps={len(seen_maps)} product_urls={len(product_urls)}")
for url in sorted(product_urls):
    print(url)
Replace the example host, contact identity, and product path rule for a site you are permitted to crawl. Production XML handling should also set limits for response size and sitemap count, validate that each URL remains in the allowed host/path scope, and handle compressed sitemap files where the source uses them. A site’s sitemap may omit products, include retired URLs, or represent variants in a way that differs from your intended schema; treat it as an inventory source to validate, not an unquestionable truth.
3. Fill sitemap gaps with pagination or an authorized API
If the site documents a catalog endpoint or provides an API credential for your use, prefer that interface to HTML page parsing. It commonly provides stable product IDs, variant relationships, totals, or continuation tokens. Follow its documented limits and authentication rules.
Otherwise, traverse category or search pagination within the allowed scope. Stop on a documented total, a missing next-page token, or an empty page. Do not assume page numbers continue forever or that a zero-result page means the crawl is complete if the interface has hidden categories or filters.
Here is a generic offset/limit loop. It assumes an authorized JSON API returning items and total; adjust keys to the actual documented response. Scrapy.io’s documented pagination uses offset, limit (maximum 100), and total, advancing offsets until rows are collected.
import requests

API = "https://api.shop.example/v1/products"
headers = {"Authorization": "Bearer YOUR_AUTHORIZED_TOKEN"}
limit, offset = 100, 0
all_items = []
while True:
    response = requests.get(API, headers=headers,
                            params={"limit": limit, "offset": offset}, timeout=30)
    response.raise_for_status()
    payload = response.json()
    items = payload["items"]
    all_items.extend(items)
    total = payload.get("total")
    offset += len(items)
    if not items or (total is not None and offset >= total):
        break
print(f"collected {len(all_items)} API rows")
Cursor APIs should use the returned cursor exactly as documented rather than deriving an offset. If pages can change while you crawl, record a run timestamp and use a snapshot/version token if offered; otherwise reconcile a second inventory pass because inserts and deletes can shift offsets.
4. Choose the fetch path: HTML, API, or browser
For each URL source, record how its fields are fetched. Prefer server-rendered HTML or an authorized JSON/API response. Use browser rendering only for fields created client-side after JavaScript runs. A browser can reveal rendered content, but it does not discover the full catalog by itself; URL discovery and a stop condition are still required.

Use a rendering fallback selectively. A page that needs JavaScript may also require waiting for a product selector, lazy image loading, or a known application state. Apply the same host scope, consent, authentication, and rate constraints to rendered requests. Save the response path used for each record so discrepancies can be investigated later.
5. Extract a stable product schema
Keep normalized fields separate from the raw source. A practical product record includes:
- Canonical URL and product ID or SKU.
- Title, brand, category breadcrumbs, and product description if in scope.
- Price as a decimal string, currency code, and availability status.
- Variant identifiers and parent product ID.
- Image URLs, not downloaded image bytes unless required.
- Source timestamp, HTTP status, fetch method, and raw-response location.
For JSON, map documented fields directly. For HTML, inspect the page structure and select stable attributes or structured data; avoid selectors based on fragile visual positions. Save raw HTML or JSON alongside the parsed row so you can rerun extraction after a selector change without re-fetching every page.
A Scrapy project is useful for larger crawls because it supports request scheduling, retries, throttling, and sitemap spiders. A minimal spider can route discovered product URLs through a parser:
import scrapy
from scrapy.spiders import SitemapSpider

class ProductsSpider(SitemapSpider):
    name = "products"
    sitemap_urls = ["https://shop.example/robots.txt"]
    sitemap_rules = [(r"/product/", "parse_product")]
    custom_settings = {
        "USER_AGENT": "CatalogAuditBot/1.0 (contact: ops@example.com)",
        "ROBOTSTXT_OBEY": True,
        "CONCURRENT_REQUESTS": 2,
        "DOWNLOAD_DELAY": 1.0,
        "RETRY_TIMES": 3,
        "AUTOTHROTTLE_ENABLED": True,
    }

    def parse_product(self, response):
        yield {
            "url": response.url,
            "canonical_url": response.css('link[rel="canonical"]::attr(href)').get(),
            "title": response.css("h1::text").get(),
            "sku": response.css('[itemprop="sku"]::attr(content)').get(),
            "http_status": response.status,
            "source_timestamp": response.headers.get("Date", b"").decode(),
            "raw_response": response.url,  # Replace with a durable object-store key.
        }
Create and run a project with scrapy startproject catalog, put the spider in its spiders directory, and execute scrapy crawl products -O products.jsonl. The selectors above are examples: inspect the permitted site’s HTML and adjust them. For production, write raw response bodies to durable storage rather than recording the URL as a raw-response pointer.
6. Deduplicate, validate, and prove coverage
URL normalization should remove known tracking parameters while preserving parameters that select a real product or variant. Normalize host casing and default ports, resolve relative links, and use canonical URLs where trustworthy. Deduplicate by both normalized canonical URL and stable product ID; URL-only dedupe can retain duplicate paths, while ID-only dedupe can incorrectly merge variants.
Compare counts at each stage, ideally per sitemap, category, locale, and run:
| Stage | Count to retain | What a gap may mean |
|---|---|---|
| Discovered | Unique in-scope URLs | Missing sitemap or pagination branch |
| Fetched | URLs with a completed response | Timeouts, blocks, or transient server errors |
| Parsed | Valid product records | Changed page template or selector |
| Failed / skipped | URL, reason, attempts, last status | Needs retry, review, or documented exclusion |
Validate required fields such as title, ID/SKU, currency, and availability according to your schema. Flag malformed prices, unexpected currency changes, missing canonical URLs, and records with an unknown template. A crawl is complete only relative to its stated boundary and stop condition. Keep an explicit exclusion list for redirects, out-of-scope URLs, unavailable products, and disallowed paths.
7. Store results and plan recrawls
Persist append-only crawl events and maintain a current product table or export. Record run ID, discovered URL, attempt count, response status, parse version, and the reason for any exclusion. Checkpoint after each batch so a process restart resumes from known work rather than repeating the entire catalog.
For recurring jobs, define what counts as a change: price, availability, title, image list, or any field. Schedule incremental recrawls if the source provides trustworthy modification metadata; otherwise periodically recheck the URL inventory and crawl changed or stale records. Hosted crawlers can reduce orchestration work. Scrapy.io documents sync and async runs, polling, dataset retrieval, schedules, and tool discovery. AWS Bedrock Web Crawler is another option for teams already using AWS, with sitemap seeds, authentication, crawl limits, and incremental synchronization. Check each provider’s current terms, limits, and pricing before choosing.
8. Or skip the browser setup
If your workflow needs screenshots for visual review or a page’s rendered appearance, ScreenshotNeo provides a website screenshot API and MCP server. It does not replace product URL discovery or structured data extraction; use it for rendered page capture alongside the crawl. Its one-request API can return PNG, JPEG, WebP, or PDF, and it supports full-page capture with lazy images, element capture, viewport/device settings, wait conditions, custom CSS and JavaScript, headers, cookies, and other capture options. See the ScreenshotNeo API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
Cookie banners are accepted and removed before the shot, along with known newsletter popups and chat widgets; each cleanup step can be turned off. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers report the page verdict and billing status. An MCP server gives AI agents tools for screenshots, page information, and PDF capture. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Sign up for 1,000 free screenshots a month, with no card required.
Performance, reliability, and cost
Set conservative concurrency and rate limits first, then adjust only with authorization and evidence that the source can handle the load. Retries should target transient failures such as timeouts or temporary server errors, use exponential backoff with jitter, and have a maximum attempt count. Do not retry permanent errors indefinitely. Cache or checkpoint successful responses so a restart does not repeat work; respect the site’s cache directives and any API-specific policy.
Measure throughput by stage: discovered URLs per minute, fetch success rate, parse success rate, retry count, and cost per completed valid record. Browser rendering usually consumes more resources and time than parsing static HTML, so reserve it for URLs that need it. For an authorized API, use its published pagination and rate limits. For hosted services, compare coverage, rendering needs, operational burden, control over selectors and storage, compliance controls, recurring cost, and incremental recrawl support. There is no universal cost estimate: volume, rendering requirements, retention, and provider pricing determine it.
Reliability comes from recoverability. Keep raw payloads, batch checkpoints, run identifiers, retry logs, and a reconciliation report. If the source changes mid-run, report the inventory timestamp and run duration; do a second inventory pass or use a source snapshot if available.
Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| Products are missing despite a successful crawl | Sitemap omits URLs, hidden categories, or pagination was not exhausted | Compare sitemap URLs with category/API totals; add documented pagination and report the boundary. |
| Repeated products or variants merge together | Tracking URLs, canonicalization, or ID-only dedupe is wrong | Normalize known tracking keys, retain variant identifiers, and dedupe by URL plus product/variant key. |
| Many 403 or CAPTCHA responses | Access is disallowed or the source applies bot controls | Stop and confirm permission and allowed access method with the site owner; do not bypass controls. |
| 429 responses or rising timeouts | Request rate/concurrency is too high, or the service is overloaded | Reduce concurrency, honor retry guidance, add backoff and jitter, and resume from checkpoints. |
| Product fields are blank | Selectors changed, response is a shell, or fields require JavaScript | Inspect a saved raw response; use documented structured data/API or selectively render and wait for a stable selector. |
| Pagination skips or repeats records | Offset pages shifted during updates or the wrong stop rule was used | Prefer cursors/snapshots; record IDs per page, reconcile totals, and repeat inventory after changes settle. |
| Sitemap parse errors | Compressed files, namespaces, malformed XML, or oversized responses | Use a sitemap-aware crawler, handle gzip and XML namespaces, cap response size, and log the failing map. |
FAQ
Is a sitemap enough to prove I found every product?
No. It is a strong discovery source, but compare it with documented catalog totals, API results, and category pagination where permitted. State the boundary and reconcile differences.
Should each size or color be its own product?
That depends on the downstream use. Define a parent/variant model before crawling and preserve variant IDs even if the export groups them.
Can I scrape products that require an account?
Only if you are authorized to access them. Use the site’s approved authentication method and keep credentials out of logs and source control.
Do screenshots provide product data?
A screenshot is an image of the rendered page, not a structured catalog record. Extract fields from authorized HTML or APIs; use screenshots for visual checks or documentation.
How do I know the crawl is done?
When the defined inventory source reaches its documented stop condition and every in-scope URL is accounted for as parsed, failed, or explicitly excluded.