How to Scrape Posts from Facebook Groups
Learn what Facebook permits, how to research group posts safely, and how to process authorized exports without brittle scraping.

Short answer: Seeing a post in a public Facebook group does not automatically give you permission to collect it with software. For one-off research, use Facebook’s built-in Groups Search and search tools. For recurring collection, first verify that Meta documents an authorized product or permission for your exact group, account, data fields, geography, and purpose. If you already have an authorized export, process that file locally instead of scraping Facebook’s pages.
Meta states that “using automation to get data from Facebook without our permission” violates its terms. Its enforcement description mentions rate limits, activity-pattern detection, account disabling, legal demands, litigation, and dataset takedown requests. This guide explains the practical workflow, the historical API context, and code for handling data you are allowed to possess.
1. Decide whether you need discovery or collection
These are different jobs:
| Goal | Appropriate first step | What to verify |
|---|---|---|
| Find discussions for personal research | Search Facebook Groups manually | Read the complete thread and its context |
| Analyze posts from a group you administer | Check Meta’s current developer products | Current approval, admin consent, fields, retention and export rules |
| Build a monitoring system | Obtain documented authorization before implementation | Coverage, refresh limits, privacy obligations and failure handling |
| Use an existing dataset | Process the supplied CSV or JSON | That the provider had permission and your use matches its scope |
Public visibility and collection rights are separate. Meta explains that public-group content can be viewed by people on and off Facebook, while private-group content is limited to members. Visibility is not a blanket license for automated collection.
2. Use Facebook’s native search for one-off research
- Open Facebook Groups and select the group relevant to your question.
- Search several precise terms, names, product versions, dates and spelling variants.
- Open promising results and read surrounding replies, edits and linked material.
- Record the post URL, visible date, group name and the reason it matches your query.
- Save only the minimum notes needed for your purpose, and do not redistribute member information.
Meta’s April 2026 engineering description says Groups Search combines a lexical path for exact or close matches with a semantic path for conceptually related posts. That means a second query using the idea behind a discussion can find a relevant post even when it does not contain your original wording. The article describes Facebook’s internal search system; it does not provide an external export API.

Search checklist
- Try the exact phrase, a shorter phrase and synonyms.
- Search product names with and without punctuation.
- Repeat the search after narrowing to the specific group.
- Check the post date and whether the discussion was edited.
- Keep a human-readable research log rather than copying an entire group.
3. Understand the historical Groups API situation
Older tutorials often describe a Facebook Groups API. Meta’s 2018 platform update said third-party apps using the Groups API needed Facebook approval and group-admin approval. It also described restrictions on member lists and on identifying authors unless a member allowed access. That was a historical explanation, not proof that those endpoints remain available.
A third-party mirror of Meta’s Graph API v19 changelog reported that Groups API capabilities and related permissions were deprecated and scheduled for removal on April 22, 2024. Because the official developer page was rate-limited during the research pass, treat that date as a reported changelog detail and verify the current Meta for Developers documentation before writing code.
Do not build against an old endpoint because a blog post still ranks in search. Confirm all of the following in current official documentation:
- The product or permission is currently offered.
- Your app is eligible for it and can complete any review.
- The group administrator can grant the required approval.
- The fields you need are exposed.
- Your use, retention period and geography are covered.
- Rate limits, deletion callbacks and audit requirements are documented.
4. What not to do
Do not bypass a login, join a private group without permission, defeat a checkpoint or CAPTCHA, rotate accounts to avoid limits, disguise browser automation, or copy posts faster than the site allows. Do not present a third-party scraper as Meta-approved unless the provider can document that authorization for your exact use.
Meta’s own description of scraping enforcement says it detects behavior patterns associated with automation and may disable accounts, send cease-and-desist letters, pursue litigation or request that hosting providers remove scraped datasets. This is Meta’s policy and enforcement account, not individualized legal advice.
5. Process an authorized CSV export with Python
If a group administrator or an approved product gives you a CSV export, you can analyze it without requesting Facebook pages. The script below expects a file named posts.csv. It tolerates common column names, normalizes dates, removes duplicate IDs and writes a filtered result.
from __future__ import annotations

import csv
import hashlib
from datetime import datetime
from pathlib import Path

INPUT = Path("posts.csv")
OUTPUT = Path("posts_filtered.csv")
TERMS = {"refund", "outage", "billing"}


def pick(row, *names):
    for name in names:
        value = row.get(name)
        if value:
            return value.strip()
    return ""


def stable_id(row):
    raw = pick(row, "post_id", "id", "url", "permalink")
    if raw:
        return raw
    text = "|".join(row.get(k, "") for k in sorted(row))
    return hashlib.sha256(text.encode("utf-8")).hexdigest()


def parse_date(value):
    if not value:
        return None
    for fmt in ("%Y-%m-%d", "%Y-%m-%dT%H:%M:%S%z", "%m/%d/%Y"):
        try:
            return datetime.strptime(value, fmt)
        except ValueError:
            pass
    return None

seen = set()
with INPUT.open(newline="", encoding="utf-8-sig") as source, \\
     OUTPUT.open("w", newline="", encoding="utf-8") as dest:
    reader = csv.DictReader(source)
    fields = reader.fieldnames or []
    writer = csv.DictWriter(dest, fieldnames=fields)
    writer.writeheader()

    for row in reader:
        record_id = stable_id(row)
        if record_id in seen:
            continue
        seen.add(record_id)

        text = pick(row, "text", "message", "post_text").lower()
        if not any(term in text for term in TERMS):
            continue

        date_value = pick(row, "created_time", "created_at", "date")
        if date_value and parse_date(date_value) is None:
            continue
        writer.writerow(row)

print(f"Wrote {len(seen)} unique records examined to {OUTPUT}")
Run it with python filter_posts.py. Adapt the column aliases only after inspecting the export schema. Keep the original file unchanged so you can reproduce your analysis, and document who supplied it and what permission covered it.
6. Equivalent local processing with Node.js
This example reads newline-delimited JSON (posts.ndjson) and writes matching records. It performs no network requests.
import { createReadStream, createWriteStream } from 'node:fs';
import { createInterface } from 'node:readline';

const terms = ['refund', 'outage', 'billing'];
const seen = new Set();
const input = createInterface({
  input: createReadStream('posts.ndjson', 'utf8'),
  crlfDelay: Infinity
});
const output = createWriteStream('posts_filtered.ndjson', 'utf8');

for await (const line of input) {
  if (!line.trim()) continue;
  const post = JSON.parse(line);
  const id = String(post.id ?? post.post_id ?? post.url ?? JSON.stringify(post));
  if (seen.has(id)) continue;
  seen.add(id);
  const text = String(post.text ?? post.message ?? '').toLowerCase();
  if (terms.some(term => text.includes(term))) {
    output.write(JSON.stringify(post) + '\n');
  }
}
output.end();
console.log(`Examined ${seen.size} unique records`);
7. cURL and Python for an authorized file endpoint
If your approved data provider gives you a documented download URL, use its authentication and retention rules. The following commands are generic file transfers; they are not Facebook endpoints:
curl --fail --location --output posts.csv \\
  --header "Authorization: Bearer YOUR_AUTH_TOKEN" \\
  "https://approved-provider.example/export.csv"
import requests
url = "https://approved-provider.example/export.csv"
r = requests.get(
url,
headers={"Authorization": "Bearer YOUR_AUTH_TOKEN"},
timeout=60,
)
r.raise_for_status()
with open("posts.csv", "wb") as f:
f.write(r.content)Replace the placeholder host only with a URL supplied in current provider documentation. Never guess an endpoint from an old tutorial.
8. Data design, privacy and reliability
Store the minimum useful fields
Prefer a post ID, permalink, creation time, group identifier, text needed for the research question and a source-permission record. Avoid exporting member lists, profile details or private replies when they are not necessary. Hash internal identifiers only when you do not need to reconcile them later; hashing is not a substitute for a lawful purpose.
Make processing repeatable
- Record the export timestamp and schema version.
- Use stable IDs to deduplicate retries.
- Keep malformed rows in a quarantine file with an error reason.
- Normalize timestamps to UTC while retaining the original value.
- Log counts, not full post text, in routine application logs.
- Define deletion jobs for data that is withdrawn or no longer needed.
Expect incomplete coverage
Search results can omit older, deleted, restricted or semantically ambiguous posts. An export may use different date formats, omit edits or contain duplicate records. Report the scope and retrieval date in any analysis so readers do not mistake a sample for a complete group history.
9. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| A tutorial’s endpoint returns an error | Legacy Groups API or permission was removed | Check current Meta documentation and app eligibility before changing code. |
| You can see a post but cannot export it | Viewing permission differs from collection permission | Ask the group administrator or use a documented authorized product. |
| CSV rows appear duplicated | Export contains retries or edits as separate rows | Deduplicate on the documented post ID and retain the newest permitted version. |
| Dates fail to parse | Mixed locale or ISO formats | Inspect the schema, parse known formats explicitly and quarantine unknown values. |
| Search misses an obvious discussion | Different wording, privacy limits or indexing delay | Try semantic synonyms, search inside the group and verify manually. |
| Your account is challenged or disabled | Automation or activity patterns triggered enforcement | Stop automated collection, review Meta’s notices and use an authorized route. |
10. Performance and cost notes
Local CSV or NDJSON processing is usually bounded by file size and disk throughput. Stream records instead of loading a large export into memory, index stable IDs once, and filter early when you do not need every field. Network collection has additional costs: authentication, retries, rate limits, pagination, storage, review and deletion handling. A faster script does not make an unauthorized method acceptable.
For a small research question, manual search is often the lowest-cost and most reliable option because it avoids building a collector that may break when Facebook changes its interface. For recurring analysis, budget for permission review, monitoring and data-governance work before estimating compute costs.
11. Or skip the browser setup
ScreenshotNeo is useful when your workflow needs a visual record of a page you are authorized to view, rather than a structured Facebook post dataset. It accepts one GET request and returns a PNG, JPEG, WebP or PDF. See the ScreenshotNeo documentation for the complete parameter list.
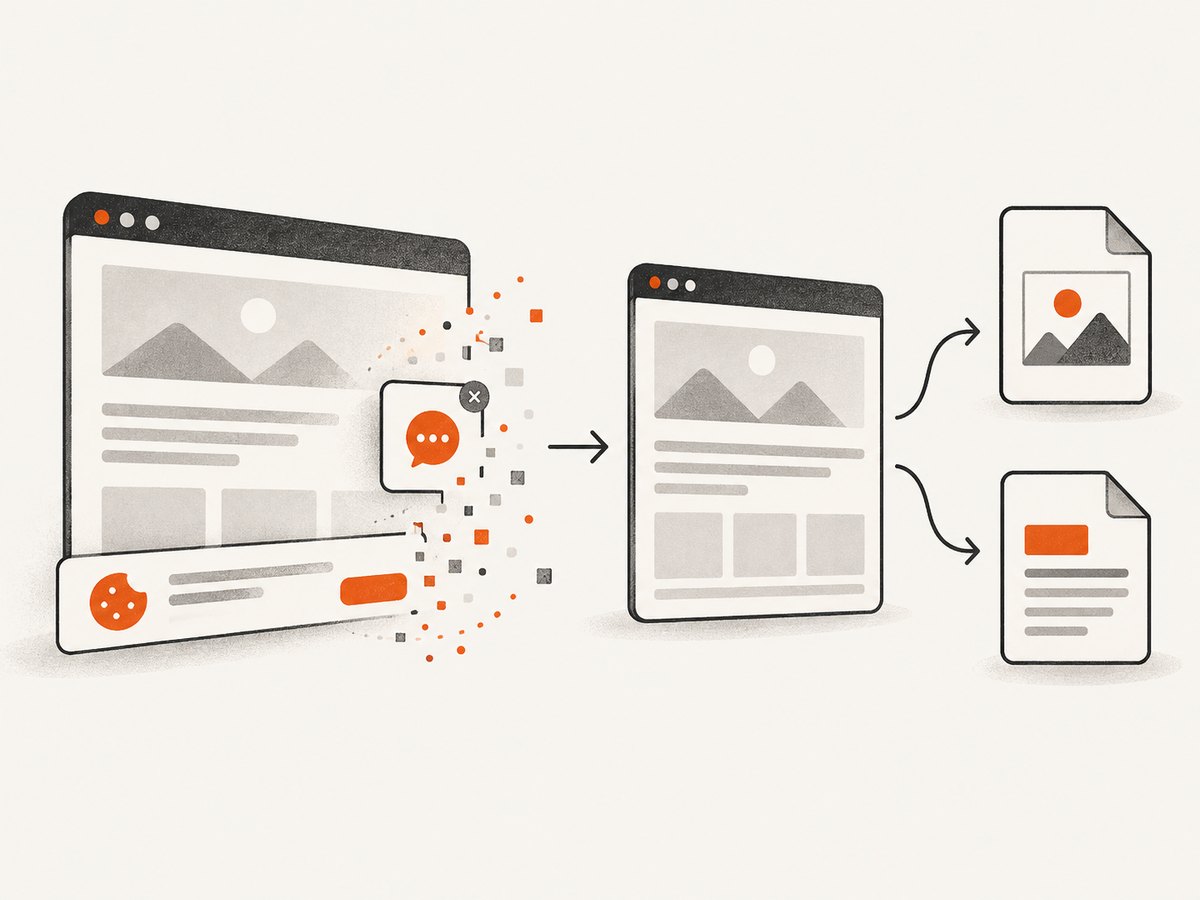
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests; r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90); open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Before capture, ScreenshotNeo can accept cookie or consent banners and remove more than 60 known consent platforms, newsletter popups and chat widgets; each step can be disabled. Bot checks, blank pages, timeouts, failed loads and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. Its MCP server provides take_screenshot, get_page_info and capture_pdf tools for Claude, Cursor and other MCP clients. The free plan includes 1,000 screenshots per month without a card; paid plans start at $5 for 3,000.
Create a free ScreenshotNeo account to get started.
12. FAQ
Can I scrape posts from a public Facebook group?
Public visibility does not by itself authorize automated collection. Check Meta’s current terms and documented permissions for your exact use.
Does Facebook still have a Groups API?
A historical Groups API required Facebook review and group-admin approval. Older capabilities were reported as deprecated in 2024; verify the current official developer documentation.
Can I use browser automation for a private group?
Only within documented authorization from Meta and the group, with member privacy and retention requirements satisfied. Do not bypass access controls.
Is a screenshot a substitute for a post export?
No. A screenshot preserves visual context but is not a structured, searchable dataset and may omit content below the captured viewport unless full-page capture is enabled.
How should I cite a group discussion?
Record the permalink, group name, visible date, access date and the authorization or research basis, while limiting copied personal information.


