How to Scrape Google Jobs in 2026
Google has no stable public Jobs scraping endpoint. Learn the compliant workflow for collecting authorized job data and exporting it reliably.
Direct answer: Google does not document a stable public endpoint for scraping the Google Jobs panel. Google says automated queries and scraping Search results without express permission violate its spam policies and Terms of Service. A defensible 2026 workflow is to collect data from employer career pages, your own job pages, or an authorized feed/API, then normalize the listings and export them to CSV.
If you own the listings, publish one page per job with JobPosting structured data, make that markup visible and consistent with the page, and notify Google about changes through the Indexing API. If you have written permission to collect another source, document the permitted URLs, geography, refresh rate, rate limits, retention period, and attribution requirements before writing code.
1. What “scraping Google Jobs” means in 2026
The Google Jobs panel is a Search presentation layer. Its markup, localization, pagination and anti-automation behavior can change. Google’s spam policies describe automated queries and scraping Search results without express permission as machine-generated traffic. Google’s Terms of Service also restrict automated access that violates machine-readable instructions and prohibit scraping content that does not belong to you.
Google does not publish a supported “Google Jobs scraper” endpoint. Google API terms add separate restrictions: unless expressly permitted, you may not scrape content returned from Google APIs, build databases from it, or retain permanent copies beyond allowed cache periods.
| Source | When it is appropriate | Main risk |
|---|---|---|
| Your own career pages | You control the pages and data rights | Schema and deployment mistakes |
| Employer pages with permission | A contract or written permission defines collection | Terms, rate limits and retention must be followed |
| Licensed jobs feed or API | The provider documents provenance and rights | Coverage, geography and resale limits vary |
| Google Search or Jobs result scraping | Only where Google has expressly authorized the access | Policy exposure, breakage and unstable markup |
2. The supported path for job owners
Google’s JobPosting documentation says the markup belongs on the most specific page describing one job. Google recommends JSON-LD, validation with the Rich Results Test and URL Inspection, and consistency between structured data and visible content.
The Indexing API documentation limits supported pages to those containing JobPosting or BroadcastEvent structured data. It can notify Google when a URL is new, updated or removed. Google states: “For job posting URLs, we recommend using the Indexing API instead of sitemaps because the Indexing API prompts Googlebot to crawl your page sooner.”
Minimal JobPosting JSON-LD
<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "JobPosting",
  "title": "Backend Engineer",
  "description": "Build and operate APIs for our product.",
  "datePosted": "2026-09-01",
  "validThrough": "2026-10-01T23:59:59Z",
  "employmentType": "FULL_TIME",
  "hiringOrganization": {
    "@type": "Organization",
    "name": "Example Employer",
    "sameAs": "https://example.com",
    "logo": "https://example.com/logo.png"
  },
  "jobLocation": {
    "@type": "Place",
    "address": {
      "@type": "PostalAddress",
      "addressLocality": "Austin",
      "addressRegion": "TX",
      "addressCountry": "US"
    }
  },
  "identifier": {
    "@type": "PropertyValue",
    "name": "Example Employer",
    "value": "ENG-1234"
  }
}
</script>
3. A compliant collection workflow
- Define the permitted source. Record whether the source is your own pages, an authorized feed/API or employer pages whose terms permit collection. Write down geography, language, refresh cadence and retention.
- Prefer structured data. Parse JSON-LD
JobPostingobjects when present. Preserve the source URL and exact retrieval timestamp. - Normalize fields. Store a stable internal ID, identifier, title, hiring organization, date posted, valid-through date, employment type, location, salary when supplied, canonical URL and source employer.
- Keep evidence. Retain the raw JSON or an integrity hash, parser version and retrieval time so later corrections can be audited.
- Deduplicate. Merge reposts only when employer, title, location and identifier or canonical URL support the merge. Keep every source URL that contributed fields.
- Respect controls. Read each site’s
robots.txtand terms. Robots.txt manages crawler access and traffic; it is not authentication. Google’s robots specification documents a 500 KiB file-size limit and generally up-to-24-hour caching. - Monitor change. Track parser failures, schema changes, HTTP status changes, duplicate rates and stale
validThroughvalues. - Publish provenance. Include source employer, source URL, retrieval time and last-seen time in exports. Do not call a listing open solely because it appeared in an earlier result.
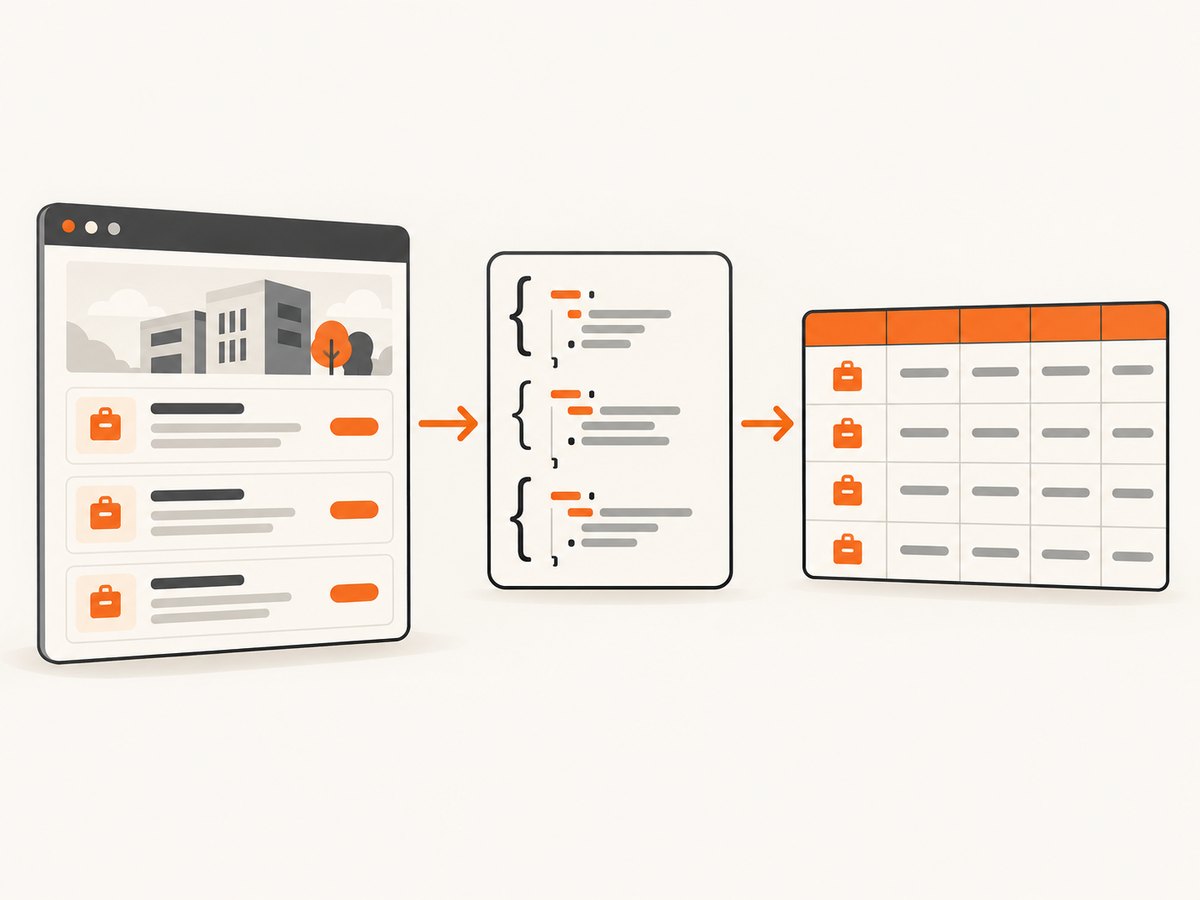
4. Python collector for authorized employer pages
The following script fetches pages you are authorized to collect, extracts JSON-LD, keeps only JobPosting objects and writes a CSV. It does not query Google Search or bypass access controls.
#!/usr/bin/env python3
import csv
import hashlib
import json
import sys
from datetime import datetime, timezone
from urllib.parse import urljoin

import requests
from bs4 import BeautifulSoup

HEADERS = {"User-Agent": "AuthorizedJobCollector/1.0 (+contact@example.com)"}
TIMEOUT = 30


def jsonld_objects(soup):
    for tag in soup.select('script[type="application/ld+json"]'):
        try:
            value = json.loads(tag.string or tag.get_text())
        except json.JSONDecodeError:
            continue
        values = value if isinstance(value, list) else [value]
        for item in values:
            if isinstance(item, dict) and item.get("@type") == "JobPosting":
                yield item


def text(value):
    if isinstance(value, dict):
        return value.get("name") or value.get("value") or ""
    return value or ""


def location(item):
    loc = item.get("jobLocation") or {}
    if isinstance(loc, list):
        loc = loc[0] if loc else {}
    address = loc.get("address", {}) if isinstance(loc, dict) else {}
    if isinstance(address, str):
        return address
    parts = [address.get(k, "") for k in ("streetAddress", "addressLocality", "addressRegion", "postalCode", "addressCountry")]
    return ", ".join(p for p in parts if p)


def collect(url):
    response = requests.get(url, headers=HEADERS, timeout=TIMEOUT)
    response.raise_for_status()
    soup = BeautifulSoup(response.text, "html.parser")
    retrieved = datetime.now(timezone.utc).isoformat()
    raw_hash = hashlib.sha256(response.content).hexdigest()
    rows = []
    for item in jsonld_objects(soup):
        org = item.get("hiringOrganization") or {}
        identifier = item.get("identifier") or {}
        rows.append({
            "source_url": response.url,
            "retrieved_at": retrieved,
            "raw_sha256": raw_hash,
            "title": item.get("title", ""),
            "employer": text(org),
            "job_id": text(identifier),
            "date_posted": item.get("datePosted", ""),
            "valid_through": item.get("validThrough", ""),
            "employment_type": text(item.get("employmentType")),
            "location": location(item),
            "salary": json.dumps(item.get("baseSalary", ""), ensure_ascii=False),
            "canonical_url": item.get("url") or response.url,
        })
    return rows


if __name__ == "__main__":
    urls = sys.argv[1:]
    if not urls:
        raise SystemExit("usage: python collect_jobs.py https://employer.example/jobs/role")
    rows = []
    for url in urls:
        try:
            rows.extend(collect(url))
        except requests.RequestException as exc:
            print(f"failed {url}: {exc}", file=sys.stderr)
    fields = ["source_url", "retrieved_at", "raw_sha256", "title", "employer", "job_id", "date_posted", "valid_through", "employment_type", "location", "salary", "canonical_url"]
    with open("jobs.csv", "w", newline="", encoding="utf-8") as output:
        writer = csv.DictWriter(output, fieldnames=fields)
        writer.writeheader()
        writer.writerows(rows)
Run it
python -m pip install requests beautifulsoup4
python collect_jobs.py \
  https://careers.example.com/jobs/backend-engineer \
  https://careers.example.com/jobs/data-engineer
cat jobs.csv
5. cURL and Node.js equivalents
For a one-off authorized page, cURL can preserve the raw response for inspection:
curl --fail --location --user-agent 'AuthorizedJobCollector/1.0 (+contact@example.com)' \
  'https://careers.example.com/jobs/backend-engineer' \
  --output job.html
Node.js can fetch and parse JSON-LD with Cheerio:
import { writeFile } from 'node:fs/promises';
import * as cheerio from 'cheerio';

const url = process.argv[2];
if (!url) throw new Error('usage: node collect.mjs https://employer.example/jobs/role');
const response = await fetch(url, {
  headers: { 'user-agent': 'AuthorizedJobCollector/1.0 (+contact@example.com)' }
});
if (!response.ok) throw new Error(`${response.status} ${response.statusText}`);
const html = await response.text();
const $ = cheerio.load(html);
const jobs = [];
$('script[type="application/ld+json"]').each((_, element) => {
  try {
    const value = JSON.parse($(element).text());
    for (const item of (Array.isArray(value) ? value : [value])) {
      if (item?.['@type'] === 'JobPosting') jobs.push(item);
    }
  } catch {}
});
await writeFile('jobs.json', JSON.stringify({ source_url: response.url, jobs }, null, 2));
console.log(`wrote ${jobs.length} job postings`);
6. Exporting, deduplication and updates
A useful export includes one row per current source record plus provenance. Recommended columns are:
| Column | Purpose |
|---|---|
canonical_url |
Stable page identity |
employer, job_id |
Employer and source identifier |
retrieved_at, last_seen_at |
Freshness and audit trail |
title, location, employment_type |
Normalized search fields |
date_posted, valid_through |
Lifecycle dates |
salary |
Preserve only when supplied by the source |
raw_sha256, parser_version |
Change detection and reproducibility |
Use employer + job_id as the strongest deduplication key. If no identifier exists, require agreement on canonical URL, employer, title and location before merging. Keep a source URL history instead of overwriting evidence. Mark a record closed only after the source indicates removal, an expired validThrough, or a documented absence policy.
7. If you own the listings: notify Google
After publishing or changing a page, validate the structured data with Google’s Rich Results Test and URL Inspection. Use the Indexing API only for supported JobPosting or BroadcastEvent pages. Send notifications for URL updates and removals, and keep your own publication state as the source of truth.
8. Browser automation: when it is justified
Some authorized career sites render jobs only after JavaScript runs. In that case, use a normal browser session against the permitted employer domain, wait for the job container, extract the rendered JSON-LD or visible fields, and stop on consent, login, CAPTCHA or access-denied pages. Do not rotate proxies, spoof fingerprints or bypass a CAPTCHA to defeat controls.
import asyncio
from playwright.async_api import async_playwright

async def main(url):
    async with async_playwright() as p:
        browser = await p.chromium.launch()
        page = await browser.new_page()
        await page.goto(url, wait_until="networkidle", timeout=60_000)
        for script in await page.locator('script[type="application/ld+json"]').all():
            try:
                print(await script.text_content())
            except Exception:
                pass
        await browser.close()

asyncio.run(main("https://careers.example.com/jobs/backend-engineer"))
9. Or skip the browser setup
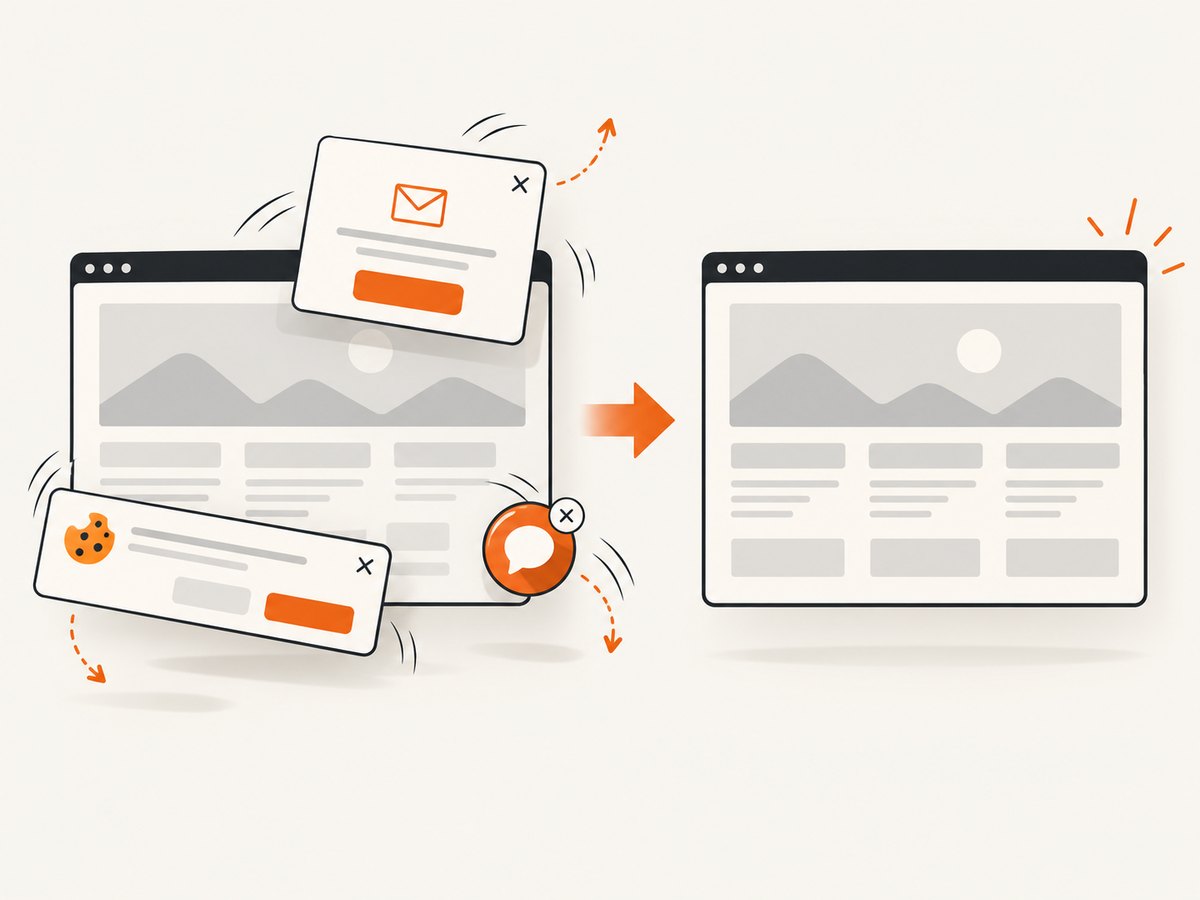
If your task is to capture an authorized employer page for review or archiving, ScreenshotNeo provides one GET request that returns PNG, JPEG, WebP or PDF. Its consent step accepts cookie banners and removes more than 60 known consent platforms, newsletter popups and chat widgets before capture; each step can be turned off. Bot checks, blank pages, timeouts, failed loads and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. It also offers an MCP server with take_screenshot, get_page_info and capture_pdf for Claude, Cursor and other MCP clients.
See the ScreenshotNeo API documentation for all options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Free accounts include 1,000 screenshots each month with no card. Paid plans start at $5 for 3,000 screenshots. Create a free ScreenshotNeo account.
10. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
No JobPosting objects found |
Page has no JSON-LD, uses a different type, or renders it after JavaScript | Inspect raw HTML, use an authorized browser session, or ask the employer for a feed |
| HTTP 403 or 429 | Permission, rate limit or access policy | Stop, review terms and robots.txt, reduce cadence, and obtain written authorization |
| Duplicate rows | Reposts, tracking URLs or multiple source pages | Normalize canonical URLs and deduplicate with employer plus identifier evidence |
| Expired jobs remain | Stale export or ignored validThrough |
Re-fetch on the permitted cadence and track last-seen state |
| Salary is missing | The source did not supply salary fields | Preserve an empty value; do not infer compensation |
| Consent dialog blocks capture | Client-side banner or regional consent requirement | Handle it as a normal visitor where permitted, or use ScreenshotNeo’s consent handling |
| Screenshot is blank | Page timeout, bot check or failed load | Inspect X-Page-Verdict, wait for a selector or network idle, and fix the source page |
11. Performance, reliability and cost
- Fetch only what you need. Use the source’s permitted refresh interval and conditional requests where supported.
- Separate discovery from detail. Keep a queue of known URLs, then fetch individual pages for full structured data.
- Make jobs idempotent. Hash raw payloads, store parser versions and upsert by a stable source key.
- Bound concurrency. Parallel requests can trigger limits and make failures harder to replay.
- Measure freshness. Track retrieval age, parse success, duplicate rate and stale postings.
- Budget managed services by successful captures. ScreenshotNeo bills only clean shots; bot checks, blank pages, timeouts, failed loads and cache hits cost nothing.
- Verify provider rights. For any managed jobs API, confirm authorization, data provenance, coverage, retention, geography and affiliate terms independently.
12. Legal and operational checklist
- Have written permission or a documented ownership basis for every source.
- Read terms, robots.txt and rate limits before collecting.
- Do not present CAPTCHA evasion, proxy rotation or fingerprint spoofing as normal practice.
- Keep source URL, retrieval time, raw hash and parser version.
- Honor deletion, retention and attribution requirements.
- Label exports with last-seen time and source employer.
- Re-check policy and contract terms when scope, geography or volume changes.
13. FAQ
Is there an official Google Jobs scraping API?
Google does not document a stable public endpoint for scraping the Jobs panel. The supported Google APIs in this area are for indexing pages containing eligible structured data, not for downloading a Jobs database.
Can I scrape Google Jobs if the results are publicly visible?
Public visibility alone does not grant permission for automated access. Google’s policies address automated Search access and scraping without express permission.
Can robots.txt make a page private?
No. Robots.txt is a crawler instruction and traffic-management mechanism, not authentication or a security boundary.
What is the safest replacement for Google Jobs scraping?
Use employer career pages, a licensed feed, or a provider that can document its authorization and data rights. Preserve provenance so users can verify each listing.
Should I store the full source response?
Store raw JSON or an integrity hash when your terms and retention policy allow it. A hash plus parser version provides change evidence without requiring permanent copies of every response.
How do I capture a job page for an internal report?
Use a permitted browser session or a screenshot service such as ScreenshotNeo, then retain the source URL and capture time alongside the image or PDF.


