How to Scrape ImmobilienScout24.de Real Estate Data in 2026
ImmoScout24 terms prohibit automated scraping. Learn the licensed API route, German database-right issues, compliant workflows, and practical code.
Direct answer: ordinary automated scraping of ImmobilienScout24.de is not permitted under the platform’s published consumer and B2B terms. Those terms prohibit scripts, bots, crawlers, search-mask bypasses, data mining, and comparable extraction methods. They also restrict building a database or commercially exploiting queried data. A compliant project should begin with a written license, the platform’s API process, or another authorization that explicitly covers access, purpose, retention, display, and reuse.
This is a 2026 access and compliance guide, not an evasion tutorial. Technical ability to fetch a listing page, a low request rate, a business account, or a robots.txt interpretation does not create permission. Before collecting any data, confirm the currently applicable ImmoScout24 agreement and obtain project-specific legal advice for commercial or research deployments.
1. What ImmoScout24’s rules mean
The consumer terms state that users may make individual records visible through the supplied online search masks. They prohibit automated queries by scripts, bots, crawlers, software that bypasses the search mask, and comparable measures, including data mining and data extraction. The same terms restrict using queried information to build a database or for commercial exploitation. Read the current ImmoScout24 terms before planning an implementation.
The B2B terms contain materially similar restrictions. A business account should not be treated as a scraping exception. The relevant question is whether your contract or a separate written license authorizes the proposed access and use.
ImmoScout24 also publishes API terms and documentation. That is a distinct, licensed route; documentation alone does not grant eligibility. The API terms found for this research are marked 15 August 2022, so verify the current agreement, enrollment process, pricing, rate limits, permitted fields, and retention rules before relying on any detail.
Consumer terms, §8.2: “Eine automatisierte Abfrage durch Skripte, Bots, Crawler, o.ä., durch Umgehung der Suchmaske, durch Suchsoftware oder vergleichbare Maßnahmen (insbesondere Data Mining, Data Extraction) sind nicht gestattet.”
2. Can you legally scrape ImmobilienScout24?
There is no universal yes-or-no answer for every project, but the published terms make an important baseline clear: automated website extraction is prohibited by contract. A lawful design normally needs one of these foundations:
- A licensed API agreement. Confirm that your organization and use case are accepted, then follow the contract’s authentication, display, storage, and deletion rules.
- Written permission for a defined project. Ask for explicit authorization covering endpoints or pages, fields, frequency, users, retention, analysis, and redistribution.
- First-party or user-authorized data. If an owner or customer supplies listing data directly, document that source and the rights to process it.
Do not rely on a business subscription, a public page, a browser session, or a successful HTTP response as evidence of permission. Terms, contract scope, privacy obligations, and database rights are separate questions.
3. German database rights: the issue beyond terms
Germany’s Urheberrechtsgesetz (UrhG) defines a database in §87a as independently accessible elements arranged systematically or methodically where obtaining, verifying, or presenting the contents requires substantial investment. Under §87b, the database maker has exclusive rights over the whole database or a qualitatively or quantitatively substantial part. The statute also addresses repeated and systematic extraction of insubstantial parts when it conflicts with normal exploitation or unreasonably prejudices the maker’s interests. See the official texts for §87a UrhG and §87b UrhG.
These provisions do not mean every page fetch is automatically unlawful, and a low request rate does not automatically make extraction permissible. Your purpose, scale, repetition, contracts, and the material collected matter. Obtain legal review before launching a commercial database, price-history service, lead product, or research archive.
4. The official API route
The API documentation shows an expose lookup pattern such as .../search/v1.0/expose/{expose_id}. The documentation describes a design intended to protect user data and support GDPR compliance. It does not itself promise access or define your license.
Questions to settle before writing code
- Which legal entity signs the agreement, and which applications are covered?
- Is the permitted purpose retrieval and display for an end customer, internal analysis, or something else?
- Which fields may be displayed, transformed, cached, or exported?
- Are personal details, owner information, contact data, or images restricted?
- What retention period applies? The surfaced 2022 API terms state that stored API data must be deleted after 24 hours; verify whether that remains current.
- What are the request limits, authentication method, incident process, and attribution requirements?
- Can you build derived statistics or a searchable database, or is that expressly excluded?
Configuration checklist
| Area | Implementation decision |
|---|---|
| Credentials | Store API keys or OAuth secrets in a secret manager; never commit them. |
| Scope | Allow only endpoints and fields named in the agreement. |
| Retention | Set automatic deletion jobs to the contractual limit; log deletion results. |
| Privacy | Minimize personal data and document a lawful basis. |
| Display | Show required attribution and freshness information. |
| Reliability | Use bounded retries for transient failures and preserve request IDs. |
5. A compliant API client skeleton
The following examples are deliberately endpoint-neutral. Set IMMO_API_BASE to the base URL supplied in your current licensed agreement. Do not substitute the public website URL or attempt to discover undocumented endpoints.
cURL
export IMMO_API_BASE="https://api.example.invalid"
export IMMO_TOKEN="YOUR_LICENSED_TOKEN"
export EXPOSE_ID="YOUR_EXPOSE_ID"

curl --fail-with-body --silent --show-error \
  -H "Authorization: Bearer ${IMMO_TOKEN}" \
  -H "Accept: application/json" \
  "${IMMO_API_BASE}/search/v1.0/expose/${EXPOSE_ID}"
Python
import os
import time
import requests

base = os.environ["IMMO_API_BASE"].rstrip("/")
token = os.environ["IMMO_TOKEN"]
expose_id = os.environ["EXPOSE_ID"]
url = f"{base}/search/v1.0/expose/{expose_id}"

for attempt in range(3):
    response = requests.get(
        url,
        headers={"Authorization": f"Bearer {token}", "Accept": "application/json"},
        timeout=30,
    )
    if response.status_code not in (429, 500, 502, 503, 504):
        response.raise_for_status()
        data = response.json()
        print(data)
        break
    if attempt == 2:
        response.raise_for_status()
    time.sleep(2 ** attempt)
Node.js
const base = process.env.IMMO_API_BASE.replace(/\/$/, '');
const token = process.env.IMMO_TOKEN;
const exposeId = process.env.EXPOSE_ID;

const res = await fetch(`${base}/search/v1.0/expose/${encodeURIComponent(exposeId)}`, {
  headers: {
    Authorization: `Bearer ${token}`,
    Accept: 'application/json'
  },
  signal: AbortSignal.timeout(30000)
});

if (!res.ok) {
  throw new Error(`API request failed: ${res.status} ${await res.text()}`);
}
console.log(await res.json());
These clients do not authorize access, expand your license, or permit bulk collection. Keep the code behind an allow-list of approved operations, validate response fields, and prevent users from turning an end-customer lookup into an unrestricted crawler.
6. If you have written permission for a web capture
Some projects receive authorization to capture a small set of pages for visual documentation, regression review, or an owner-supplied workflow. In that case, define the URL list, frequency, retention, and display rights in writing. Respect authentication, consent, personal-data minimization, and the prohibition on bypassing bot checks or access controls. Record the authorization alongside the job configuration.
7. Or skip the browser setup
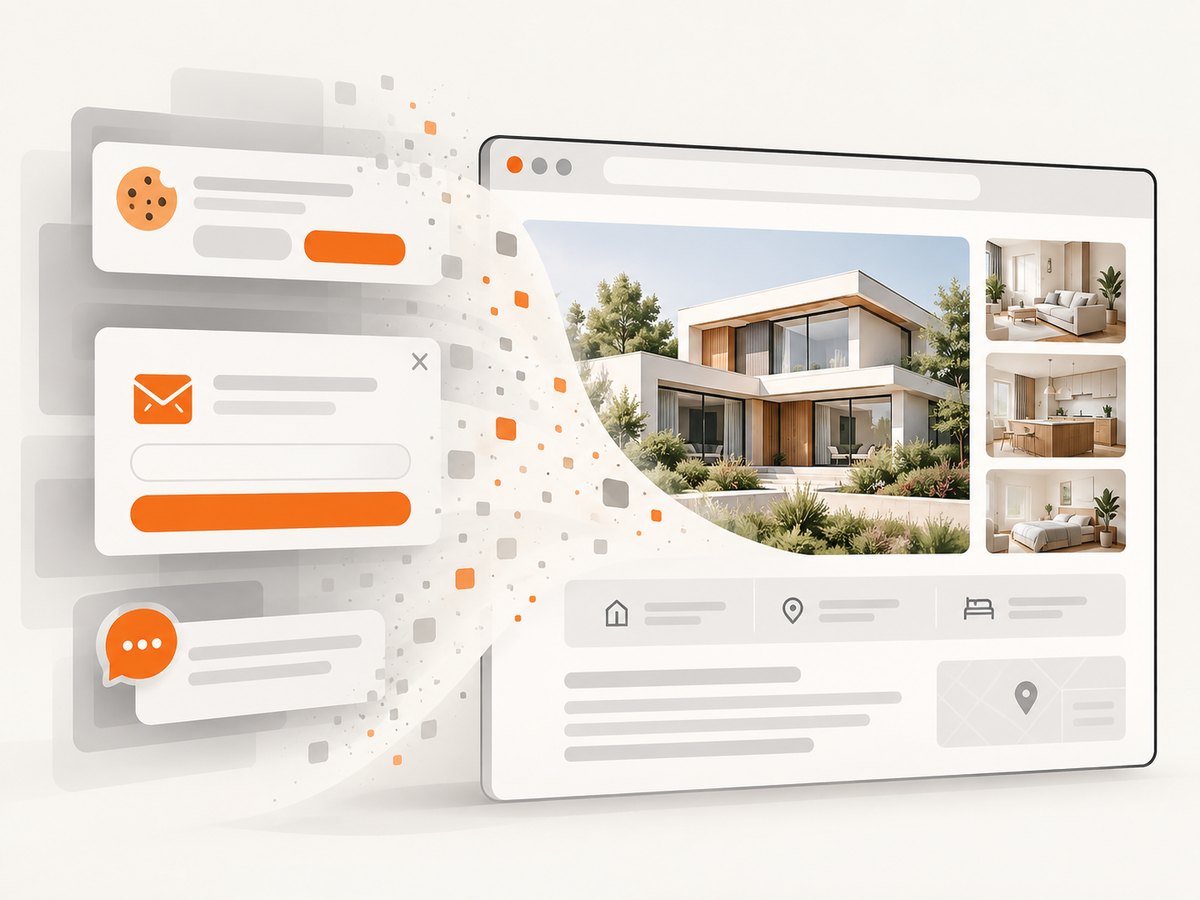
For authorized pages, ScreenshotNeo provides a website screenshot API. It is useful when the deliverable is a visual record rather than a structured property database. Cookie and consent banners are accepted before capture, then more than 60 known consent platforms, newsletter popups, and chat widgets can be removed. Each step can be disabled. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing status.
See the ScreenshotNeo API docs for the full option set. A basic capture is one GET request:
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://www.immobilienscout24.de -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://www.immobilienscout24.de"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://www.immobilienscout24.de' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo supports full-page captures with lazy images loaded, CSS-selector element shots, dark mode, 12 device presets and custom viewports, retina scale, PDF output with paper size, margins, landscape and page ranges, custom CSS and JavaScript, clicks, selector or network-idle waits, blocking rules, custom headers and cookies, timezone and geolocation, transparent backgrounds, image resizing, configurable caching, signed links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs per call, a usage API, and an OpenAPI specification. It also accepts parameter names used by other screenshot APIs, which can simplify migration.
An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. Use it only for pages and purposes you are authorized to access.
There are 1,000 free shots each month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free, and every feature is included on every plan. Create a free ScreenshotNeo account.
8. Reliability, performance, and cost planning
Reliability
- Prefer a documented, licensed interface over a workflow that depends on bypassing controls.
- Persist request IDs, status codes, timestamps, and the contract version used.
- Retry only transient failures with exponential backoff; never retry authorization failures indefinitely.
- Make deletion jobs observable and alert when they fail.
Performance
- Request only fields needed for the approved display.
- Use bounded concurrency that stays within contractual limits.
- Cache only when the agreement permits it, with an enforced TTL.
- For screenshots, wait on a meaningful selector or network idle instead of an unnecessarily long fixed delay.
Cost
Your API contract may charge by request, field, or plan; confirm the current schedule directly with ImmoScout24. For ScreenshotNeo, only clean shots are billed, while bot checks, blank pages, timeouts, failed loads, and cache hits cost nothing. The usage API and X-Billed response header help reconcile consumption.
9. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| 403 or 401 | Missing, expired, or unauthorized credentials | Check the licensed token, allowed entity, clock, and endpoint scope. |
| 429 | Rate limit exceeded | Reduce concurrency, honor retry headers, and ask for an approved quota. |
| 404 expose | Invalid ID or the record is no longer available | Validate IDs and handle deletion without substituting a crawler. |
| Data cannot be stored | Retention or field restrictions | Apply an allow-list and automated deletion policy. |
| Screenshot shows a consent dialog | Consent handling or removal step disabled | Review ScreenshotNeo options and confirm the page is authorized. |
| Screenshot is blank | Timeout, bot check, failed load, or client-side rendering | Inspect verdict headers, increase a permitted wait, or treat it as an unsuccessful capture. |
| Unexpected personal data | Overbroad fields or page state | Minimize collection, redact output, and revisit the legal basis. |
10. A launch checklist
- Write the use case and audience in one paragraph.
- Obtain the current terms and a signed authorization or API agreement.
- List every field, endpoint, display surface, and retention period.
- Document privacy, security, deletion, and incident procedures.
- Implement rate limits, retries, logging, and access controls.
- Test with synthetic or owner-provided records first.
- Review changes to terms before expanding scope.
11. FAQ
Does a business account permit scraping?
No. The B2B terms also restrict automated querying and reuse. Only a separate authorization or license can change the permitted scope.
Can I scrape slowly to stay compliant?
Slowing requests may reduce operational load, but it does not override a contractual prohibition.
Is the ImmoScout24 API guaranteed to be available?
No current availability, pricing, or enrollment terms were established here. Confirm them directly and check the agreement date.
Can I keep API data indefinitely?
Do not assume that. The surfaced API terms dated 15 August 2022 state a 24-hour storage limit; verify the contract you actually sign.
Is ScreenshotNeo a property-data API?
No. It produces screenshots or PDFs and page information. Use a licensed ImmoScout24 data interface for structured listing data, and ScreenshotNeo when an authorized visual capture is the required output.


