How to Scrape JavaScript-Generated Map Data With Pyppeteer
Use Pyppeteer to wait for rendered map data or network responses, extract only authorized fields, and avoid brittle selectors and timing errors.
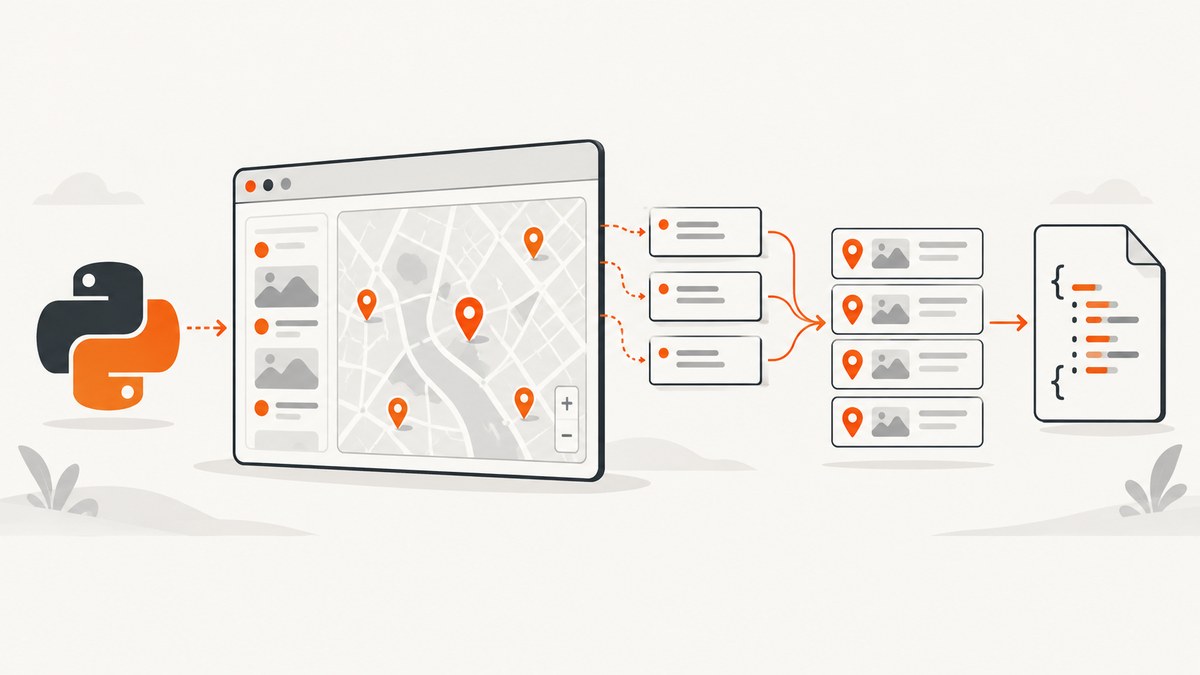
Short answer: let the map page run its JavaScript, wait for a signal tied to the map data, then extract structured values from either the rendered DOM or the response that contains the data. Pyppeteer can navigate pages, evaluate JavaScript, query selectors, observe network events, and wait for matching responses. Use it only for a target you are authorized to access, and check the provider’s official API and terms before collecting or reusing map data.
Important maintenance note: Pyppeteer’s own repository describes it as an unofficial Python port of Puppeteer and currently warns that the project is unmaintained, recommending that readers consider playwright-python as an alternative. Verify that its Python, Chromium, and deployment compatibility fit your project before choosing it for new or long-lived work. See the Pyppeteer repository README and its 0.0.25 API reference.
What JavaScript-generated map scraping involves
A map that appears after navigation usually has at least two layers:
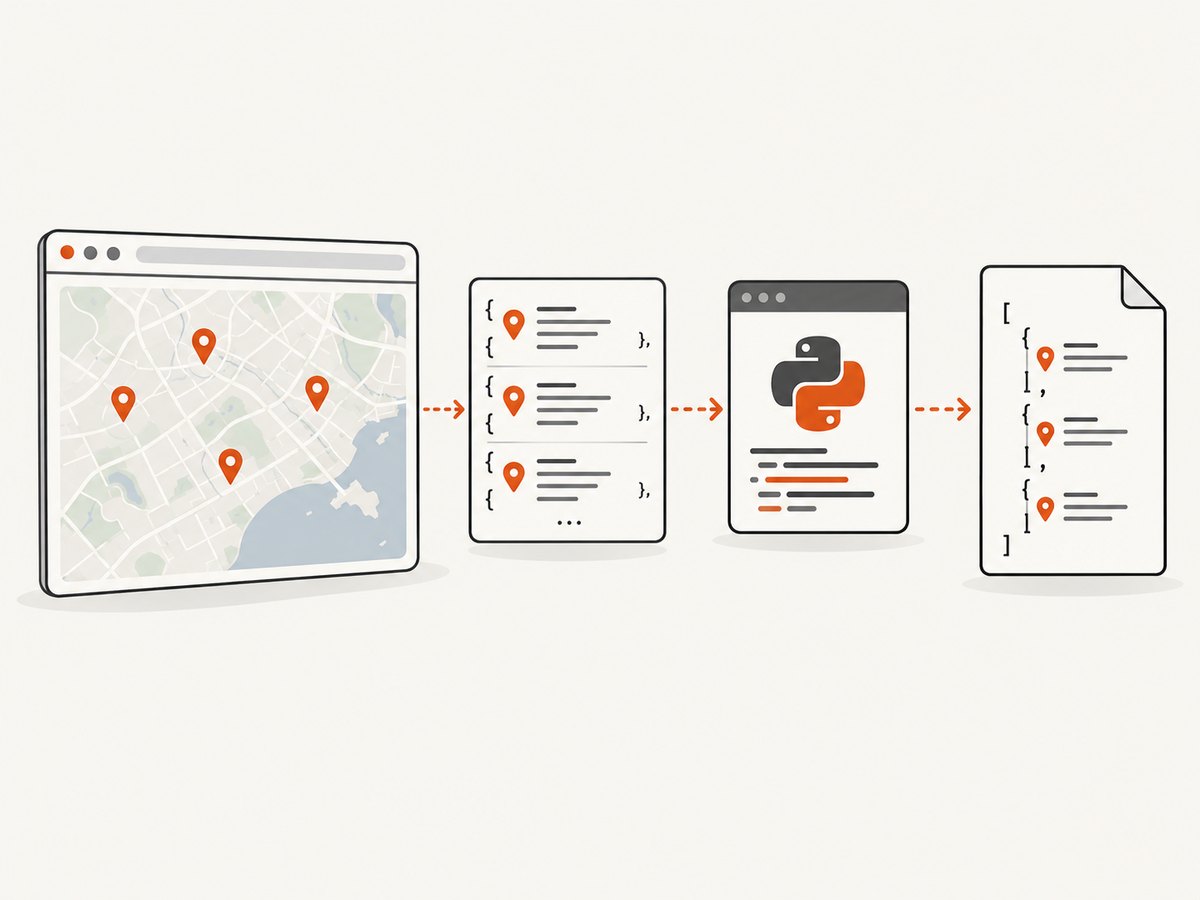
- Rendered state: marker labels, accessible names, cards, tables, or other elements that JavaScript inserts into the DOM.
- Data traffic: JSON, text, or binary responses fetched after the initial document loads.
Start with the rendered state because it is closest to what an authorized user can see and is often less coupled to private application internals. If the needed values are not represented in the DOM, identify the relevant response and parse only the fields required for your stated purpose. A screenshot or pixel-coordinate scrape is rarely appropriate when the page exposes semantic elements or a response.
Before you write code
- Confirm that automated access and the intended reuse of the data are allowed by the provider’s terms, robots guidance, contract, or written permission.
- Prefer the provider’s documented API when it supplies the data you need. An undocumented endpoint can change without notice even when a browser currently uses it.
- Define the smallest field set you need, such as marker ID, latitude, longitude, and displayed name. Avoid retaining unrelated personal or proprietary data.
- Identify a readiness signal. A generic
loadevent only means the navigation reached that stage; a map can still be fetching tiles or marker data. - Plan for rate limits, retries, browser resource usage, and a clear stop condition.
Install Pyppeteer and launch Chromium
python -m venv .venv
# macOS/Linux
source .venv/bin/activate
# Windows PowerShell: .venv\\Scripts\\Activate.ps1

python -m pip install --upgrade pip
pip install pyppeteer
The Pyppeteer README says Python 3.8 or later is required and that the first run can download Chromium if a compatible executable is not already available. The repository gives an approximate download size of about 150 MB; treat that as a setup estimate rather than a permanent binary-size guarantee.
Method 1: extract markers from the rendered DOM
This method is appropriate when the page creates stable, semantic elements for markers, results, or an associated list. Replace the example URL and selector with values from the authorized target.
import asyncio
import json
from pyppeteer import launch

URL = "https://example.com/map"

async def main():
    browser = await launch(
        headless=True,
        args=["--no-sandbox", "--disable-setuid-sandbox"],
    )
    page = await browser.newPage()
    await page.setViewport({"width": 1440, "height": 900, "deviceScaleFactor": 1})

    try:
        await page.goto(URL, {"waitUntil": "domcontentloaded", "timeout": 60_000})

        # Replace this selector with an element that indicates map data is ready.
        await page.waitForSelector("[data-marker]", {"timeout": 30_000})

        markers = await page.evaluate("""() => {
            return Array.from(document.querySelectorAll('[data-marker]')).map(el => ({
                id: el.getAttribute('data-marker'),
                name: el.getAttribute('aria-label') || el.textContent.trim(),
                latitude: el.getAttribute('data-lat'),
                longitude: el.getAttribute('data-lng')
            }));
        }""")

        print(json.dumps(markers, indent=2, ensure_ascii=False))
    finally:
        await browser.close()

if __name__ == "__main__":
    asyncio.get_event_loop().run_until_complete(main())
Pyppeteer’s Python API uses querySelector(), querySelectorAll(), and querySelectorAll()-style evaluation rather than Puppeteer’s JavaScript-only $ and $$ examples. The repository also documents short forms such as J(), JJ(), and Jx(). Returning a list of dictionaries from evaluate() is less brittle than reading screen coordinates.
When the map stores coordinates in attributes or styles
Some interfaces put values in data-* attributes, accessibility attributes, inline styles, or a nearby result card. Inspect the element and its parent before writing a selector:
details = await page.evaluate("""() => {
    const el = document.querySelector('[data-marker]');
    if (!el) return null;
    return {
        html: el.outerHTML,
        parentText: el.parentElement ? el.parentElement.innerText : null,
        attributes: Array.from(el.attributes).map(a => [a.name, a.value])
    };
}""")
print(json.dumps(details, indent=2))
Use the output to identify a stable attribute or an associated accessible label. Do not depend on generated class names, canvas pixels, or a DOM path that changes whenever the front-end bundle is rebuilt.
Method 2: capture the response that contains map data
If markers are drawn on a canvas or the DOM contains no useful values, inspect authorized browser traffic and wait for a response characteristic that identifies the intended data. The API reference documents waitForResponse(), response events, and response methods such as text(), json(), and buffer().
import asyncio
import json
from pyppeteer import launch

URL = "https://example.com/map"

async def main():
    browser = await launch(headless=True, args=["--no-sandbox"])
    page = await browser.newPage()

    try:
        # Replace the predicate with a URL characteristic found during
        # inspection of the permitted target. Check the response format too.
        response_wait = page.waitForResponse(
            lambda response: "/map-data" in response.url
            and response.request.method == "GET",
            {"timeout": 45_000},
        )
        await page.goto(URL, {"waitUntil": "domcontentloaded", "timeout": 60_000})
        response = await response_wait

        content_type = (response.headers or {}).get("content-type", "").lower()
        if "json" not in content_type:
            raise RuntimeError(f"Unexpected content type: {content_type}")

        payload = await response.json()
        # Select only fields needed by your authorized use case.
        records = [
            {
                "id": item.get("id"),
                "name": item.get("name"),
                "latitude": item.get("latitude"),
                "longitude": item.get("longitude"),
            }
            for item in payload.get("markers", [])
        ]
        print(json.dumps(records, indent=2, ensure_ascii=False))
    finally:
        await browser.close()

if __name__ == "__main__":
    asyncio.get_event_loop().run_until_complete(main())
The /map-data string and markers field above are placeholders. Do not assume a provider uses either name. Identify the response by inspecting the authorized page, then validate its status, content type, and schema before parsing it.
Observe responses while investigating
async def log_response(response):
    if "map" in response.url.lower():
        print(response.status, response.request.method, response.url)

page.on("response", lambda response: asyncio.ensure_future(log_response(response)))
Keep logging bounded and remove it in production. Response listeners can reveal request URLs and status codes, but access to a URL does not grant permission to reuse its contents.
Choose the right readiness condition
| Condition | Use it when | Limit |
|---|---|---|
domcontentloaded |
The initial HTML is enough to begin watching the map. | JavaScript data may not have arrived. |
load |
Images and subresources needed by the page should be loaded. | Later XHR or fetch calls can still be pending. |
networkidle0 |
The target becomes quiet and this is a meaningful readiness signal. | Polling, analytics, or long-lived connections can prevent idleness. |
networkidle2 |
You need a looser network-idle signal. | A map request can still be in flight. |
waitForSelector() |
A visible marker list or map state element proves readiness. | It fails if the selector is unstable or never rendered. |
waitForResponse() |
A known response supplies the data. | The predicate must distinguish the correct response. |
Prefer a signal tied to the data you need. A short explicit delay can be a fallback for an authorized target with no better signal, but it is less reliable than waiting for a selector or response.
Useful Pyppeteer options
Navigation and timeouts
await page.goto(
    URL,
    {
        "waitUntil": "domcontentloaded",
        "timeout": 60_000,
        "referer": "https://example.com/",
    },
)
page.setDefaultNavigationTimeout(60_000)
page.setDefaultTimeout(30_000)
Use the smallest timeout that accommodates the target’s normal behavior. Separate navigation timeout from the map-data timeout so failures tell you which phase stopped.
Viewport, user agent, cookies, and headers
await page.setViewport({"width": 1365, "height": 768, "deviceScaleFactor": 1})
await page.setUserAgent("AuthorizedMapResearch/1.0")
await page.setExtraHTTPHeaders({"Accept-Language": "en-US,en;q=0.9"})
await page.setCookie({"name": "region", "value": "us", "domain": "example.com"})
Only send headers, cookies, or identity information that the provider permits. A viewport can change responsive markup and therefore the selector you need.
Evaluate JavaScript safely
value = await page.evaluate("() => document.querySelector('#map-status')?.textContent")
expression = await page.evaluate("1 + 2", force_expr=True)
The Pyppeteer README notes that evaluate() accepts a JavaScript string and tries to determine whether it is an expression or a function. If an expression is interpreted incorrectly, use force_expr=True.
Click, scroll, and lazy-loaded markers
await page.click("button[data-load-more]")
await page.waitForSelector("[data-marker]", {"timeout": 20_000})
await page.evaluate("window.scrollTo(0, document.body.scrollHeight)")
Interact only when the permitted workflow requires it. For maps that load markers by viewport or after a zoom, perform the documented interaction, then wait for the resulting selector or response.
Handle common map edge cases
- Canvas rendering: extract the backing response or an accompanying result list; OCR and pixel sampling are last resorts and usually lose structure.
- Virtualized lists: only visible rows may exist in the DOM. Scroll in the permitted interface and deduplicate records by a stable ID.
- Pagination: stop when the provider’s next-page control is disabled or the documented API reports no more records.
- Multiple responses: match URL, method, status, and content type together. A tile image and a JSON marker response may share a path fragment.
- Locale-dependent values: preserve the source value and record the locale or timezone used if formatting affects interpretation.
- Infinite polling: do not wait forever for network idle. Use a response or visible-state predicate and a hard deadline.
- Consent or sign-in: follow the provider’s permitted user flow. Do not bypass access controls, bot checks, or authentication barriers.

Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
TimeoutError on goto() |
Slow navigation, blocked resource, or an unsuitable wait condition. | Check the URL and status, increase the timeout modestly, and begin with domcontentloaded while waiting separately for map readiness. |
| Selector timeout | The selector is wrong, responsive markup differs, or the map has not rendered. | Inspect the live DOM, verify viewport and locale, and wait for a state element tied to the target. |
| Empty marker list | Markers are virtualized, canvas-rendered, hidden until interaction, or stored in a response. | Inspect surrounding elements and authorized responses; trigger the required documented interaction. |
waitForResponse() never resolves |
The request occurred before the wait was installed, or the predicate is too broad or too narrow. | Create the wait before navigation or the triggering click and log candidate responses temporarily. |
| JSON parsing fails | The response is HTML, compressed/binary, an error body, or a different schema. | Check status and content-type, then use text() or buffer() for inspection before parsing. |
| Chromium launch fails | Browser download, executable path, sandbox, or container permissions. | Confirm the first-run download completed, set an approved executable path if needed, and use the container’s documented sandbox configuration. |
| Works locally but not in production | Different Python/Chromium versions, fonts, viewport, network policy, or missing system libraries. | Pin compatible versions, log environment details, and run a small authorized smoke check in the deployment image. |
| Duplicate records | Repeated responses, viewport reloads, or pagination overlap. | Deduplicate by a provider-defined stable ID and retain the source page or response timestamp. |
Performance, reliability, and cost
Performance
- Reuse one browser process and create pages per job when isolation allows; launching Chromium for every marker set adds startup overhead.
- Wait for the required response or selector instead of an unnecessarily long global delay.
- Extract fields in one
evaluate()call rather than making a round trip for every marker. - Keep the viewport and interaction scope to what the target needs, while respecting provider limits.
- Do not enable request interception casually. Current Puppeteer documentation says intercepted requests stall until they are continued, answered, aborted, or completed from cache; historical Pyppeteer behavior may differ, so verify the version you deploy.
Reliability
- Use bounded retries only for transient navigation or network failures, with backoff and a total job deadline.
- Validate response status, content type, required fields, and record counts before saving output.
- Record the target URL, retrieval time, selector or response predicate, and library/browser versions so schema changes are diagnosable.
- Fail closed when the page presents an unexpected login, consent, bot check, or error page. Do not treat it as map data.
Cost
Pyppeteer itself is installed through Python packaging, while Chromium consumes CPU, memory, storage, and bandwidth. Your provider may also impose quotas or charge for its official API. Browser automation does not remove those obligations; check the provider’s current terms and pricing.
Or skip the browser setup
If you need a clean visual capture of the map page rather than structured marker data, ScreenshotNeo provides a single-request screenshot API. It does not turn a map image into a data feed, so use the Pyppeteer or official-API workflow above for structured extraction.
ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. Its MCP server gives Claude, Cursor, and other MCP clients take_screenshot, get_page_info, and capture_pdf tools.
See the ScreenshotNeo API documentation for options and authentication:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com/map -o map.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://example.com/map"}, timeout=90)
r.raise_for_status()
open("map.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com/map' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
require('node:fs').writeFileSync('map.webp', buffer);There are 1,000 screenshots per month free with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
FAQ
Can Pyppeteer read map data from a canvas?
Not directly as structured records. Look for an accompanying DOM list or the authorized response that supplied the canvas data. A canvas screenshot contains pixels, not reliable marker fields.
Should I wait for networkidle0?
Only when the page becomes genuinely idle. Map polling and analytics can keep it busy. A matching response or visible map-ready element is usually more precise.
Is a successful script proof that scraping is allowed?
No. Technical access and permission to collect or reuse data are separate questions. Use the provider’s official API and current terms for the target.
Is Pyppeteer still a good choice for a new project?
Its repository currently warns that it is unmaintained and points readers toward considering playwright-python. Compare maintenance, browser compatibility, deployment requirements, and the target provider’s permitted access route before deciding.
How do I keep extracted data small?
Project only the required fields in the browser or immediately after parsing, deduplicate by a stable identifier, and avoid storing unrelated response payloads.


