How to Scrape JavaScript-Generated Values with Puppeteer
Use Puppeteer to wait for JavaScript-rendered data, extract values reliably, and handle empty results, timeouts, lists, and dynamic pages.
To scrape a value generated by JavaScript with Puppeteer, load the page in a real browser, wait for the specific element or value to be ready, then read it with $eval, $$eval, or evaluate. Do not assume the initial HTML response contains data that the page creates after its scripts run. A selector or value-based wait is usually more reliable than sleeping for a guessed number of milliseconds.
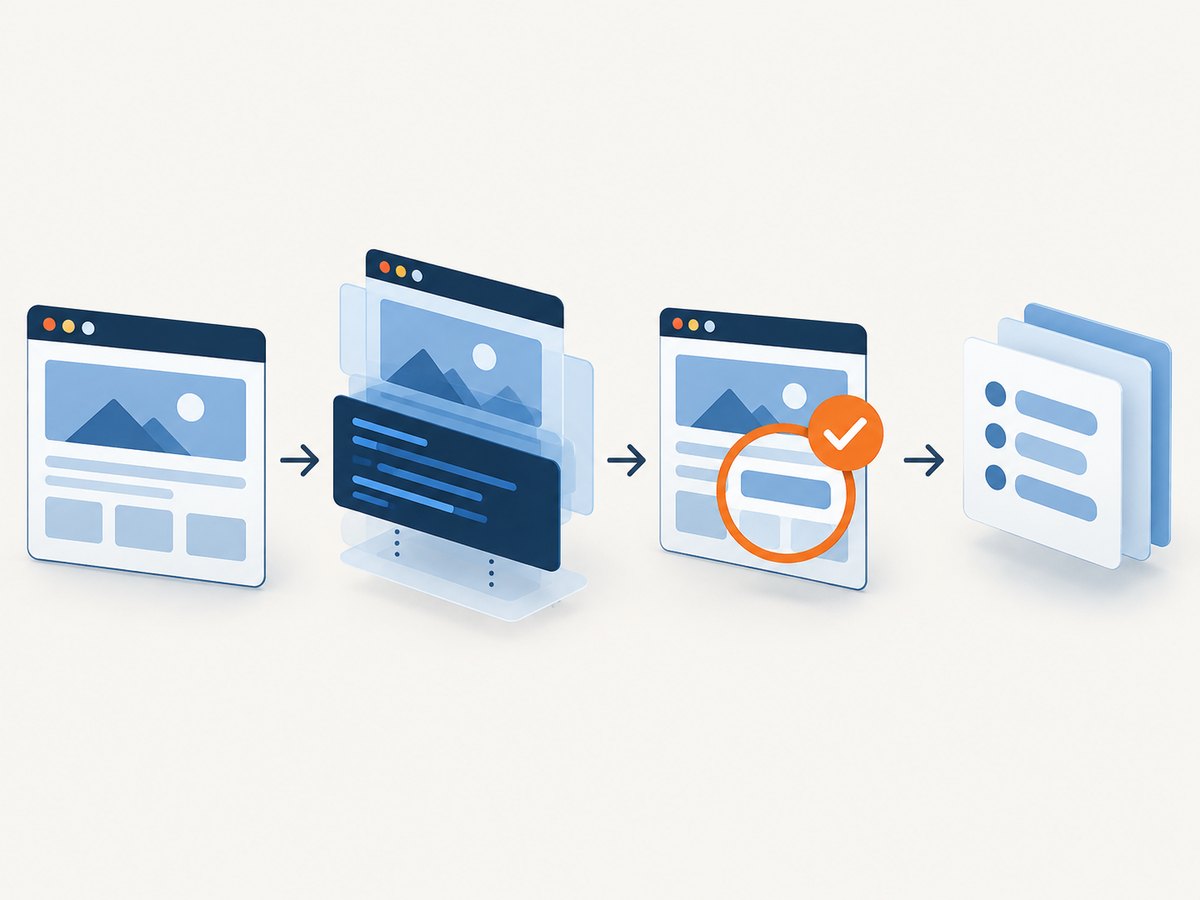
This guide shows a complete runnable example, ways to wait for values and lists, handling for iframes and shadow DOM, and fixes for common empty-result and timeout problems. Puppeteer controls Chrome or Firefox and runs page JavaScript in a browser context. See the official getting-started guide and Page API.
1. Install Puppeteer and run a basic scraper
Use a supported Node.js version, create a project, and install Puppeteer. The puppeteer package downloads a compatible Chrome for Testing by default. If your environment manages its own browser, see the connection notes below.
mkdir puppeteer-scraper
cd puppeteer-scraper
npm init -y
npm install puppeteer
Save the following as scrape.mjs. It navigates to a product page, waits for a visible price element, extracts its text, validates it, and closes the browser even if navigation or extraction fails.
import puppeteer from 'puppeteer';

const url = 'https://example.com/product';
const selector = '[data-price]';
const browser = await puppeteer.launch({ headless: true });

try {
  const page = await browser.newPage();
  page.setDefaultTimeout(15_000);
  await page.goto(url, { waitUntil: 'domcontentloaded', timeout: 30_000 });
  await page.waitForSelector(selector, { visible: true, timeout: 15_000 });

  const price = await page.$eval(
    selector,
    el => el.textContent?.trim() ?? ''
  );
  if (!price) throw new Error(`Price element ${selector} was empty`);

  console.log({ url, price });
} finally {
  await browser.close();
}
Replace the example URL and selector with the target page and a selector for the rendered value. A semantic attribute such as data-price, a stable ID, or an accessible role is generally less fragile than a CSS class used only for styling. Avoid selecting the first vaguely matching element if the page has multiple prices.
2. Choose a wait that describes readiness
Navigation completion and application readiness are different events. page.goto can return after a document milestone while the frontend is still fetching data or updating the DOM. The right wait describes the condition that makes your target value usable.
| Wait | Use it when | Tradeoff |
|---|---|---|
waitForSelector |
A known element is inserted into the DOM. | Existence alone does not guarantee its text is final. |
waitForFunction |
The element exists, but its text, attribute, or state changes later. | The predicate must be specific and safe to evaluate repeatedly. |
waitForNetworkIdle |
Network quiescence is useful as an additional signal. | Analytics, polling, sockets, or long requests can delay or mislead it. |
| Fixed delay | A site has a known delay with no observable readiness signal. | It may waste time or still finish too early. |
Wait for an element
waitForSelector resolves when the selector matches. Set visible: true when the element must be visible; use hidden: true to wait for it to disappear or become hidden. The documented default timeout is 30 seconds, while timeout: 0 disables the timeout. Prefer a bounded timeout in scraping jobs so a broken page cannot hang a worker indefinitely. If the selector does not appear before the timeout, Puppeteer throws.
await page.waitForSelector('[data-result]', {
  visible: true,
  timeout: 12_000
});
Wait for text or an attribute to become meaningful
If the node appears with placeholder content and is updated later, wait for the data itself. waitForFunction polls a predicate in the page context until it returns a truthy value or times out.
await page.waitForFunction(
  () => {
    const el = document.querySelector('[data-total]');
    const value = el?.textContent?.trim();
    return value && value !== 'Loading…' && /^\$\d/.test(value);
  },
  { timeout: 15_000 }
);
const total = await page.$eval('[data-total]', el => el.textContent.trim());
In an evaluated function, Node.js variables are not automatically available inside the browser. Pass values as arguments instead of closing over them:
const selector = '[data-total]';
await page.waitForFunction(
  sel => document.querySelector(sel)?.textContent?.trim().length > 0,
  { timeout: 10_000 },
  selector
);
Use network idle carefully
waitForNetworkIdle waits until network activity has remained idle for its configured idle period, and always waits at least that period. It tells you about network activity, not whether your application has rendered the particular value. A page with polling may never become idle; a page can also become quiet before a delayed render runs. Use it as a supporting signal, then wait for the target selector or predicate.
await page.goto(url, { waitUntil: 'domcontentloaded' });
await page.waitForNetworkIdle({ idleTime: 500, timeout: 10_000 });
await page.waitForSelector('[data-price]', { visible: true });
Navigation’s waitUntil option controls when navigation is considered complete (for example, domcontentloaded or load). Pick the earliest useful milestone and synchronize separately on the data. Waiting for the full load event can include slow images and other resources unrelated to the value.
3. Extract a single value, attributes, or a list
Use $eval when exactly one matching element is expected. It throws if there is no match, which makes a missing selector visible as an error rather than silently returning a wrong value.
const result = await page.$eval('[data-product]', el => ({
  name: el.querySelector('.name')?.textContent?.trim() ?? '',
  price: el.querySelector('[data-price]')?.textContent?.trim() ?? '',
  sku: el.getAttribute('data-sku') ?? ''
}));
Use $$eval to map all matching nodes in one browser evaluation. This is useful for result cards, rows, or repeated values.
const rows = await page.$$eval('[data-row]', nodes =>
  nodes.map(node => ({
    name: node.querySelector('.name')?.textContent?.trim() ?? '',
    value: node.getAttribute('data-value') ?? ''
  }))
);
if (rows.length === 0) throw new Error('No result rows were rendered');
console.log(rows);
To read a non-text property, use the same browser-side callback:
const imageUrl = await page.$eval(
  '[data-product] img',
  img => img.currentSrc || img.getAttribute('src') || ''
);
const link = await page.$eval(
  '[data-product] a',
  anchor => anchor.href
);
Page.evaluate runs a function in the page context and waits for a returned promise to resolve. Use it when the extraction spans several nodes or when you need to read a page-level state already exposed to the browser. Return serializable data such as strings, numbers, arrays, or plain objects; DOM nodes themselves are not ordinary JSON results.
const summary = await page.evaluate(() => ({
  title: document.title,
  canonical: document.querySelector('link[rel=canonical]')?.href ?? '',
  text: document.querySelector('[data-summary]')?.textContent?.trim() ?? ''
}));
4. Handle selectors, frames, and shadow roots
Prefer selectors that express meaning: data attributes, labels, roles, or stable IDs. Puppeteer supports CSS and additional selector strategies such as text, accessibility attributes, XPath, and shadow-root traversal. The page interactions guide documents selector options. When a selector suddenly stops working, inspect the live DOM and check whether a frontend update changed its structure.
Values inside an iframe
A page-level selector does not automatically search inside every frame. Find the frame by URL or another stable characteristic, then perform the same wait-and-extract sequence there.
const frame = page.frames().find(f => f.url().includes('/embedded-data'));
if (!frame) throw new Error('Data frame was not found');
await frame.waitForSelector('[data-value]', { visible: true, timeout: 10_000 });
const value = await frame.$eval('[data-value]', el => el.textContent?.trim() ?? '');
Cross-origin frames are still separate browsing contexts. Locate and evaluate in the correct Puppeteer frame; do not expect the parent document’s JavaScript to read a cross-origin frame’s contents.
Values in a shadow root
Regular document queries do not cross a shadow boundary. Use Puppeteer’s supported shadow-root selector syntax where suitable, or evaluate through the host’s shadowRoot when the root is open.
const value = await page.evaluate(() => {
  const host = document.querySelector('product-card');
  return host?.shadowRoot?.querySelector('[data-price]')?.textContent?.trim() ?? '';
});
Closed shadow roots do not expose shadowRoot to page JavaScript. In that case, look for an accessible host-level attribute, an application data endpoint, or another supported page interface.
5. Interact before extraction when the page requires it
Some values are loaded only after consent, a click, scrolling, selecting a variant, pagination, or expanding a panel. Reproduce the necessary visitor action, then wait for the result condition. A wait cannot make an interaction-dependent value appear by itself.
await page.goto(url, { waitUntil: 'domcontentloaded' });
await page.locator('button[data-variant="large"]').click();
await page.waitForFunction(() => {
  const price = document.querySelector('[data-price]')?.textContent?.trim();
  return price && price !== '—';
}, { timeout: 10_000 });
const price = await page.$eval('[data-price]', el => el.textContent.trim());
For lazy-loaded lists, scroll the relevant container or page and wait for additional rows. For pagination, extract each page only after confirming the next page’s data has replaced the prior results. Avoid assuming that a click succeeded merely because the click promise resolved.
6. Validate and save the result
Scraped text is untrusted input. Normalize whitespace, check required fields, and parse values with an explicit locale and format expectation. Keep the original string if normalization could discard meaningful details such as currency or units.
const raw = await page.$eval('[data-price]', el => el.textContent?.trim() ?? '');
const match = raw.match(/^\$([0-9]+(?:\.[0-9]{2})?)$/);
if (!match) throw new Error(`Unexpected price format: ${JSON.stringify(raw)}`);
const priceUsd = Number(match[1]);
console.log({ raw, priceUsd });
Do not use a US-dollar regular expression on a localized price without adapting it. Decimal separators, currency placement, non-breaking spaces, and units vary. Preserve both the source text and parsed representation when downstream decisions depend on the value.
7. Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
waitForSelector times out |
Wrong selector, content is in another frame, or interaction is required. | Inspect the rendered DOM, check frames and shadow roots, and perform the needed action before waiting. |
| Selector matches but value is empty | The node is a placeholder or text is filled later. | Wait for non-empty, final-looking text with waitForFunction. |
| Value is stale after clicking | The click did not change the app state, or extraction ran before rendering. | Wait for a specific changed value or state marker; verify the selected option. |
| Navigation hangs | Waiting for networkidle or load on a page with long-lived activity or slow resources. |
Use domcontentloaded and a separate bounded data wait. |
| Text differs from what is visible | Hidden duplicate elements or formatting nodes are included. | Target the visible container and inspect innerText versus textContent. |
| Works locally but not in deployment | Missing browser dependencies, sandbox policy, fonts, or different viewport. | Use a compatible installed browser, install required system libraries, set the viewport explicitly, and inspect launch logs. |
| Browser process remains open | An exception bypassed cleanup. | Put browser.close() in a finally block and bound all waits. |
For diagnosis, take a screenshot and save await page.content() after the readiness wait. Compare that rendered DOM with the selector and what you see in a normal browser. Do not log cookies, authorization headers, or private page content into shared logs.
8. Performance, reliability, and cost considerations
Browser automation has startup, navigation, script, and rendering costs. Reuse a browser process for a batch of pages when appropriate, while creating an isolated page or browser context per task to avoid state leaking between jobs. Close pages and contexts, limit concurrency to available memory and CPU, and avoid loading resources irrelevant to the extracted value only after confirming that blocking them does not break the application.
Reliability comes from bounded waits, explicit readiness conditions, validation, and clear failure categories. Retry transient navigation failures selectively; do not blindly retry a bad selector or invalid response forever. Record the URL, elapsed stage, selector or predicate, and failure class while redacting sensitive data. Use a stable viewport and locale when layout or formatting affects the result.
There is no universal wait duration or performance figure for all sites. Choose timeouts based on the page and job requirements, and use observed outcomes to tune them. Short arbitrary delays can reduce throughput while still producing flaky results. Network-idle waits can consume time without proving the target value is ready.
9. Or skip the browser setup
If you need a clean visual capture of a JavaScript-rendered page rather than custom DOM extraction, ScreenshotNeo offers a website screenshot API and MCP server. Its API captures a URL as PNG, JPEG, WebP, or PDF; see the API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
import requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({
access_key: 'YOUR_API_KEY',
url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
await import('node:fs/promises').then(fs => fs.writeFile('shot.webp', Buffer.from(await res.arrayBuffer())));ScreenshotNeo removes cookie banners, newsletter popups, and chat widgets before capture, with each step configurable. Bot checks, blank pages, failed loads, timeouts, and cache hits are never billed, and response headers identify the page verdict and billing status. Its MCP server provides take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients. The free plan includes 1,000 screenshots monthly with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
10. Frequently asked questions
Can I scrape JavaScript values with plain HTTP?
Only if the value is present in the response or available from a data endpoint you can request directly. If the site computes or inserts it in the browser, a browser runtime or the underlying supported data interface is needed.
Should I scrape an API instead of the rendered DOM?
If the page uses a public, documented endpoint and its terms allow your use, consuming structured data can be simpler. Do not assume an internal endpoint is stable or authorized; the rendered page remains the observable source for browser-driven workflows.
Can Puppeteer extract a screenshot as well as values?
Yes. Puppeteer can capture page screenshots, but this guide focuses on reading DOM data. For URL-to-image or PDF capture without managing a browser process, see ScreenshotNeo’s API options in the section above.


