How to Scrape a Paginated Website With Python
Learn how to crawl paginated websites with Requests and Beautiful Soup, handle next links, JavaScript pagination, retries, duplicates, and exports.
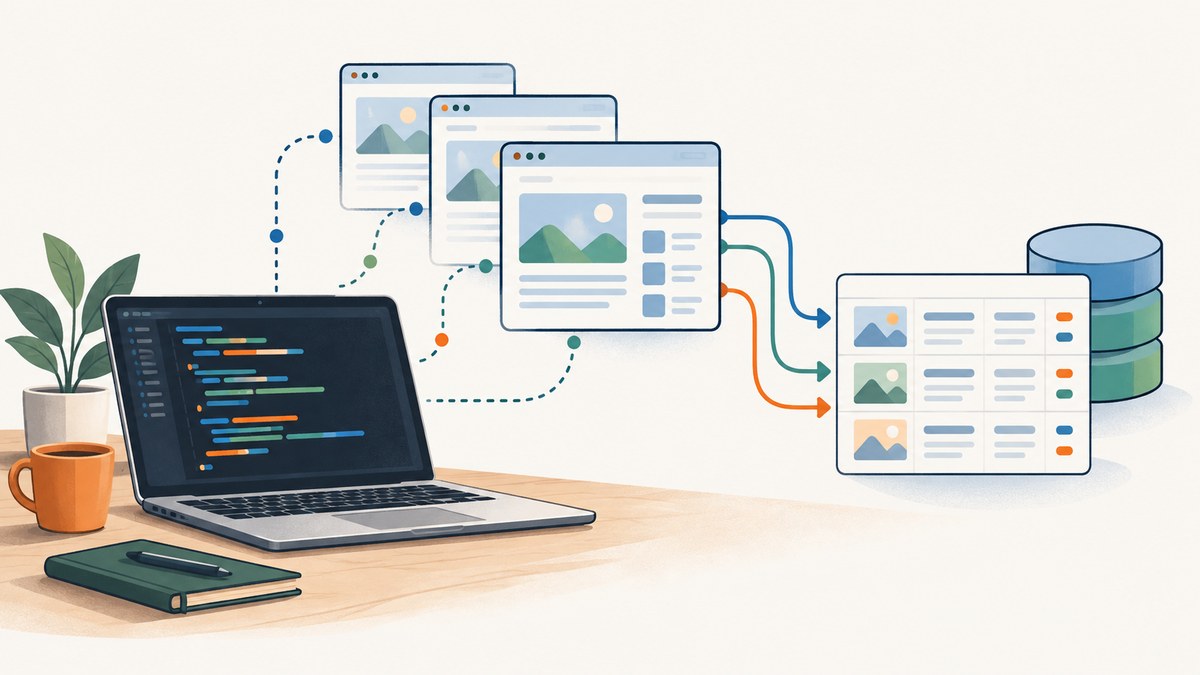
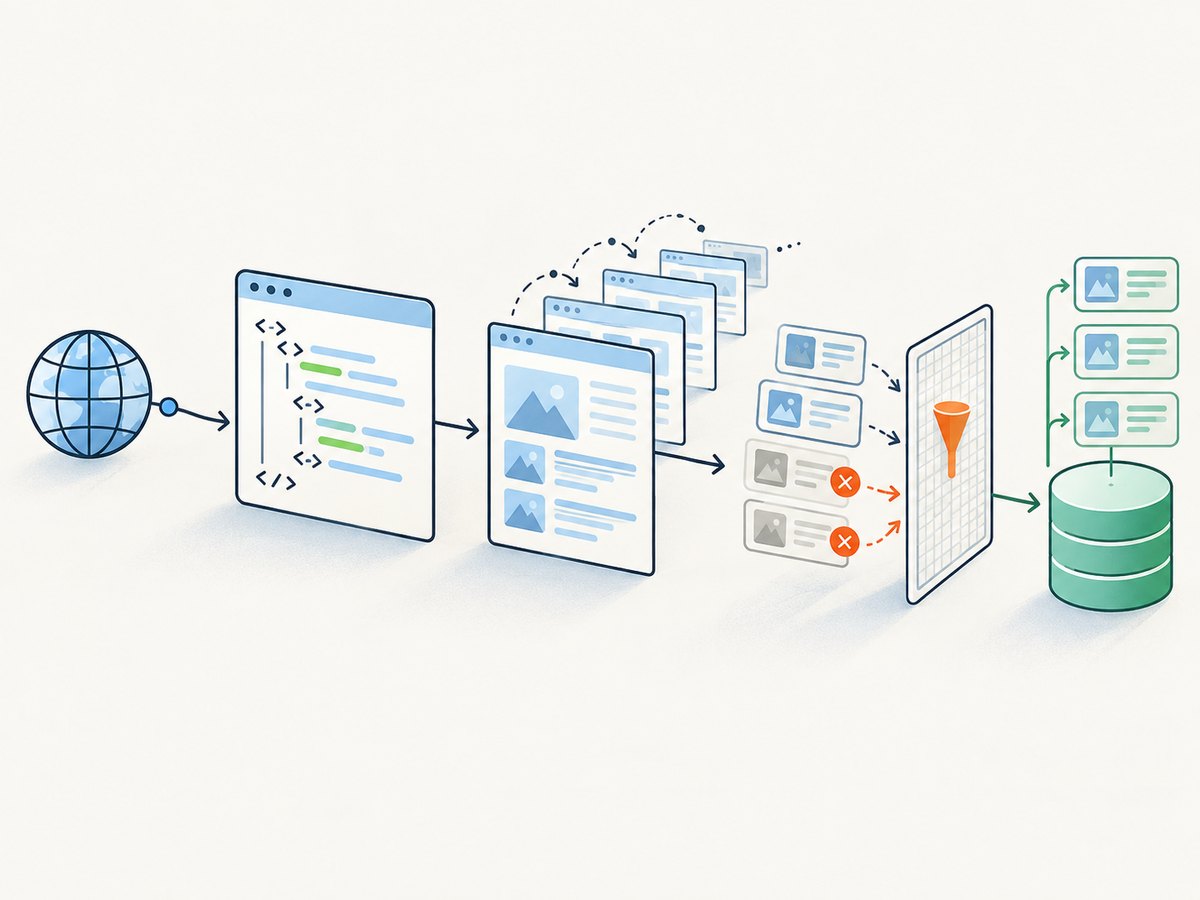
To scrape a paginated website with Python, fetch each page with a persistent requests.Session, parse records with Beautiful Soup, follow the site’s real pagination link, and stop when there is no next page or no new data. Add timeouts, status checks, rate limits, retries, duplicate detection, validation, and incremental output before using the crawler beyond a small experiment.
This guide shows a complete crawler for server-rendered HTML, explains numbered and cursor pagination, and covers the point where Requests can no longer see the data because JavaScript renders it. Before crawling, read the target’s robots.txt, terms, and any applicable privacy or data-protection requirements. A robots.txt file is an access signal and traffic-management instruction; Google describes it as telling crawlers which URLs they can access (Google Search Central).
1. Inspect one page before writing the crawler
Do not assume that ?page=2 is the correct URL. Open one permitted page in a browser and inspect its HTML. Identify:
- The container for one record, such as
article.item,tr.product, orli.result. - Stable fields inside that container, such as a title, URL, price, date, or identifier.
- The next-page control. Prefer
<a rel="next">; otherwise find a link whose accessible text or class clearly means “next.” - Whether the links are absolute or relative, and whether they contain a cursor, offset, or page number.
- Whether the initial HTML already contains the records. View source or download the response to check; the browser’s rendered DOM can include content that was not in the HTTP response.
Use browser developer tools to confirm selectors against several records. A selector that only works for the first card, or depends on a generated class name, will make the crawl silently incomplete.
2. Install the Python dependencies
python -m venv .venv
source .venv/bin/activate        # Windows: .venv\\Scripts\\activate
python -m pip install requests beautifulsoup4 lxml
Beautiful Soup’s documentation supports Python’s built-in html.parser, lxml, and html5lib. The parser changes how malformed markup is repaired. The example uses lxml because it is generally faster; use html.parser when you need to minimize dependencies.
3. A complete paginated crawler
Save this as scrape_items.py. Replace the example URL and selectors after inspecting the permitted target. It follows discovered links instead of guessing page numbers, persists each page’s records, retries transient failures, and prevents duplicate records.
import csv
import json
import logging
import random
import time
from pathlib import Path
from urllib.parse import urljoin

import requests
from bs4 import BeautifulSoup
from requests.adapters import HTTPAdapter
from urllib3.util.retry import Retry

START_URL = "https://example.com/items"
OUTPUT_JSON = Path("items.json")
OUTPUT_CSV = Path("items.csv")
MAX_PAGES = 100
REQUEST_TIMEOUT = (10, 30)  # connect timeout, read timeout
MIN_DELAY = 1.0

logging.basicConfig(level=logging.INFO, format="%(levelname)s %(message)s")


def make_session():
    session = requests.Session()
    session.headers.update({
        "User-Agent": "ExampleResearchCrawler/1.0 (+https://example.com/contact)"
    })
    retry = Retry(
        total=4,
        connect=4,
        read=4,
        status=4,
        backoff_factor=1.5,
        status_forcelist=(429, 500, 502, 503, 504),
        allowed_methods=frozenset({"GET"}),
        respect_retry_after_header=True,
    )
    session.mount("https://", HTTPAdapter(max_retries=retry))
    session.mount("http://", HTTPAdapter(max_retries=retry))
    return session


def clean_text(node):
    return node.get_text(" ", strip=True) if node else None


def parse_page(html, page_url):
    soup = BeautifulSoup(html, "lxml")
    records = []

    for card in soup.select("article.item"):
        title_node = card.select_one("h2, h3")
        link_node = card.select_one("a[href]")
        title = clean_text(title_node)
        href = link_node.get("href") if link_node else None
        if not title or not href:
            logging.warning("Skipped a record with a missing title or URL")
            continue
        item_url = urljoin(page_url, href)
        records.append({"title": title, "url": item_url})

    next_node = soup.select_one('a[rel="next"]')
    if not next_node:
        # Adapt this fallback only after confirming it is the real control.
        next_node = soup.select_one("a.next, a[aria-label*='Next']")
    next_url = None
    if next_node and next_node.get("href"):
        next_url = urljoin(page_url, next_node["href"])
    return records, next_url


def save_json(rows):
    OUTPUT_JSON.write_text(json.dumps(rows, ensure_ascii=False, indent=2), encoding="utf-8")


def save_csv(rows):
    with OUTPUT_CSV.open("w", newline="", encoding="utf-8") as handle:
        writer = csv.DictWriter(handle, fieldnames=["title", "url"])
        writer.writeheader()
        writer.writerows(rows)


def crawl():
    session = make_session()
    url = START_URL
    seen_pages = set()
    seen_records = set()
    rows = []

    for page_number in range(1, MAX_PAGES + 1):
        if not url or url in seen_pages:
            break
        seen_pages.add(url)
        logging.info("Fetching page %s: %s", page_number, url)

        response = session.get(url, timeout=REQUEST_TIMEOUT)
        response.raise_for_status()
        records, next_url = parse_page(response.text, response.url)

        new_count = 0
        for record in records:
            key = record["url"]
            if key in seen_records:
                continue
            seen_records.add(key)
            rows.append(record)
            new_count += 1

        # Persist after every page so a later failure does not discard progress.
        save_json(rows)
        save_csv(rows)
        logging.info("Found %s records (%s new); total %s", len(records), new_count, len(rows))

        if not records or new_count == 0:
            logging.info("Stopping: page produced no new records")
            break
        url = next_url
        if url:
            time.sleep(MIN_DELAY + random.random() * 0.5)

    return rows


if __name__ == "__main__":
    rows = crawl()
    print(f"Saved {len(rows)} unique records")
Run it with python scrape_items.py. The example assumes each record is an article.item with a heading and link. Change only the selectors and field mapping required by the target. Keep the URL normalization through urljoin; it handles relative links such as /items?page=2.
4. Pagination patterns and how to handle them
Next and previous links
A semantic next link is the most resilient option:
next_link = soup.select_one('a[rel="next"]')
next_url = urljoin(current_url, next_link["href"]) if next_link else None
If the site uses a button, inspect its surrounding HTML. A button may contain a hidden URL, a cursor in a data-* attribute, or no URL at all because JavaScript performs a request. Do not invent an href based on its label.
Numbered page URLs
Generate page numbers only after confirming the pattern manually. For a URL such as https://example.com/items?page=2, use urllib.parse.urlencode or a known template and still stop on an empty page, repeated records, or MAX_PAGES. Some sites start at zero, use offset, or encode filters in a signed query string.
Load-more controls and cursor pagination
“Load more” often calls an endpoint with a cursor. Inspect the browser Network panel for the request, response format, and required headers. If an official documented API exists, prefer it. A cursor can expire, so persist the last successful response and handle a cursor that repeats as a stop condition.
Filtering and preserving query parameters
Keep the original query string when following links. Pagination links can carry filters, sort order, locale, or authentication state. Use the returned link as the source of truth rather than reconstructing it from the path.
5. Extract and validate fields defensively
Beautiful Soup provides select, select_one, find, and find_all. Use optional extraction for fields that are genuinely optional and validate required fields before writing. Normalize whitespace with get_text(" ", strip=True), parse dates explicitly, and retain the source URL for auditability.
def parse_price(card):
    node = card.select_one(".price")
    if not node:
        return None
    raw = node.get_text(" ", strip=True).replace(",", "")
    return raw

record = {
    "title": clean_text(card.select_one("h2")),
    "price": parse_price(card),
    "detail_url": urljoin(page_url, card.select_one("a[href]")["href"]),
}
if not record["title"] or not record["detail_url"]:
    continue
Choose a stable identity key. A canonical detail URL is often better than the title because titles can repeat. If no URL exists, combine an external ID with the page’s collection name. Keep a set of seen keys to avoid duplicates caused by featured items, overlapping pages, or a broken next link.
6. JavaScript-rendered pagination
Requests and Beautiful Soup parse only the HTML returned by the server. If the rows appear only after JavaScript runs, first inspect network requests for an official API or embedded JSON. An API response is usually lighter and more stable than driving a browser. Check whether the data is present in a <script type="application/ld+json"> block or another embedded state object.
When browser execution is genuinely required, use Playwright or Selenium. Wait for a specific record selector, click the control, and collect the rendered HTML or data. Browser automation consumes more CPU and memory, is slower, and requires managing browser binaries and timing. It is appropriate when pagination, authentication, or content depends on client-side execution that you cannot replace with an authorized endpoint.
from playwright.sync_api import sync_playwright

with sync_playwright() as p:
    browser = p.chromium.launch(headless=True)
    page = browser.new_page()
    page.goto("https://example.com/items", wait_until="networkidle")
    while True:
        for card in page.locator("article.item").all():
            print(card.locator("h2").inner_text())
        button = page.locator("button:has-text('Next')")
        if not button.is_visible() or not button.is_enabled():
            break
        button.click()
        page.wait_for_load_state("networkidle")
    browser.close()
Treat this as a template: selectors, wait conditions, and whether a full navigation occurs depend on the site. Respect access controls and stop when the site returns an explicit denial.
7. Reliability, rate limits, and incremental storage
- Timeouts: Always set connect and read timeouts. A request without a timeout can hang indefinitely.
- Retries: Retry connection failures and transient 429 or 5xx responses with exponential backoff. Do not blindly retry 401, 403, or other explicit denials.
- Rate limits: Add a delay between pages, honor
Retry-After, and reduce concurrency when the site slows down. - Caching: Cache downloaded pages during development so selector changes do not repeatedly hit the target.
- Persistence: Write after each page to JSON, CSV, SQLite, or your queue. Include crawl time and source URL when reproducibility matters.
- Observability: Log page URL, status, record count, new-record count, and stop reason. A successful process with zero records is an extraction failure, not success.
For larger crawls, SQLite gives you uniqueness constraints and resumability without loading the entire result set into memory. Use a database transaction per page and a unique key on the record identifier.
8. Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| Every page returns 403 | The site denies the request, requires authentication, or detects your client. | Stop and review terms and access rules. Use an authorized API or contact the owner; do not try to bypass the denial. |
| 429 Too Many Requests | Your request rate exceeded the site’s limit. | Honor Retry-After, slow down, reduce concurrency, and resume later. |
| Records list is empty | Selectors do not match, or rows are JavaScript-rendered. | Print a response sample, compare it with view source, verify selectors, then inspect network calls. |
| Only the first page is saved | The next selector is wrong or the href is missing. | Inspect the pagination HTML and log the discovered next URL before fetching. |
| Duplicate records | Pages overlap, featured records repeat, or the next URL loops. | Track seen page URLs and stable record IDs or canonical URLs. |
| Unicode is corrupted | Incorrect decoding or writing with a platform default. | Use response.encoding when needed and write files with encoding="utf-8". |
| Request hangs | No timeout, slow server, or stalled connection. | Set connect/read timeouts and retry only transient failures. |
| Parser behaves differently locally | Malformed HTML is repaired differently by parser. | Pin dependencies and choose lxml, html.parser, or html5lib deliberately. |
9. Performance and cost decisions
For static pages, Requests plus Beautiful Soup is lightweight because it transfers HTML without launching a browser. Parsing only the record containers and saving incrementally keeps memory predictable. Concurrency can improve throughput, but it also increases load and the chance of rate limiting; use it only when the site permits it and cap workers conservatively.
Browser automation costs more CPU, memory, startup time, and operational maintenance. An official API can reduce all three, but it may impose authentication, quotas, or different pagination semantics. The cheapest design is the one that retrieves only the fields and pages you need, caches pages during development, and resumes instead of restarting after a failure.
10. Or skip the browser setup
If your actual goal is to obtain clean screenshots of paginated pages, a hosted capture API can remove browser installation and rendering code. ScreenshotNeo accepts one GET request and returns a PNG, JPEG, WebP, or PDF. See the ScreenshotNeo API documentation for the complete options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
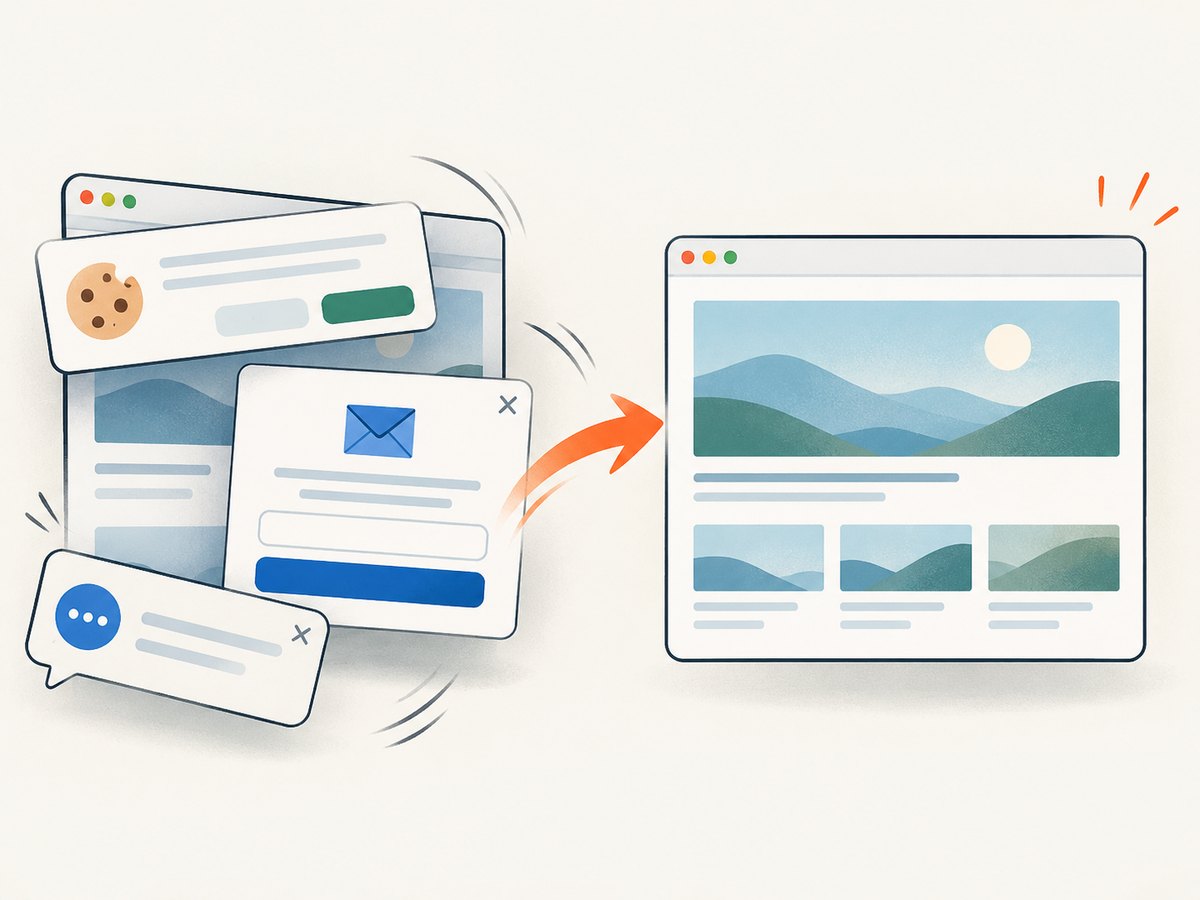
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, failed loads, timeouts, and cache hits are never billed, and response headers identify the page verdict and whether it was billed. ScreenshotNeo also provides an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
11. FAQ
How do I scrape multiple pages with Python?
Fetch a page, parse its records, find the next URL, and repeat until the next link disappears or no new records are found. Keep sets for visited pages and record IDs.
Should I use Selenium for every paginated site?
No. Use Requests and Beautiful Soup when the response contains the records. Use an official API or embedded JSON when available; use Playwright or Selenium only when browser execution is necessary.
Is scraping a paginated website legal?
It depends on the site, jurisdiction, data, and purpose. Read the terms, robots.txt, and applicable privacy obligations, and stop on explicit denial or rate-limit responses.
How can I resume after a crash?
Persist after each page and store visited URLs or record IDs. On restart, load those values and continue from the next undiscovered URL.
Why are my page numbers missing records?
The site may use cursors, overlap pages, sort dynamically, or require a filter parameter. Follow discovered pagination links and compare record IDs between adjacent pages.


