How to Scrape Real Estate Listings from Property Websites
A practical guide to permission, authorized collection, parsing, deduplication and monitoring for real estate listings—with runnable Python examples and safer source options.
To collect real estate listings reliably, first confirm that the source permits your intended collection and use. Prefer a licensed API, MLS or broker feed when one is available. If you have written authorization to collect from pages, build a conservative collector that preserves raw evidence, timestamps each observation, normalizes fields, deduplicates records and tracks changes.
This guide shows how to design that authorized workflow in Python, how to evaluate official data access, and how to use screenshots to inspect pages when visual review helps. It does not grant permission to scrape any site. A page being publicly visible does not establish a right to copy, store, display or resell its contents.
1. Decide what you need and whether you may collect it
Before writing a parser, specify what data you need and what you will do with it. The same listing may be subject to restrictions on data access, storage, display, attribution and redistribution. Photos, descriptions, agent details, branding and video can also have distinct copyright, trademark, privacy or contract restrictions.
| Decision | Write it down |
|---|---|
| Coverage | Geography, sale or rental, property types and source websites |
| Fields | Listing ID, address, price, beds, baths, area, status and any agent or media fields |
| Purpose | Internal analysis, private application, public display, resale or another use |
| Operations | Refresh cadence, retention period, expected volume and error handling |
| Rights | Attribution, branding, storage, display, derivative use and redistribution terms |
Treat each field and asset as licensed content until the source agreement says what is allowed. NAR Policy Statement 7.85 says listing brokers should own or have authority to license listing content submitted to an MLS, including photographs, descriptions, pricing and other listing details. That policy illustrates why a listing’s presence on a page alone does not settle reuse rights.
2. Check official access before building a scraper
Review the source’s current Terms of Use, API documentation, robots.txt, and applicable partner or MLS agreement. Terms and agreements govern contractual use; robots instructions communicate crawler preferences and are not a substitute for permission.
For example, Realtor.com’s Move Network Terms prohibit scraping and other automated collection without express written permission. Zillow Group documents APIs for home valuations, property details and homes posted for sale, with API licensing and branding obligations. Check the live terms and the specific API agreement before relying on either statement; terms can change.
Compare source options against the same criteria:
- Permission: Are your fields, purpose, storage and planned redistribution allowed?
- Coverage and completeness: Do the source and schema cover your geography and required fields?
- Freshness: Is there a documented update mechanism and a clear meaning for status?
- Reliability and limits: What rate limits, service expectations and failure behavior apply?
- Cost and operations: Include engineering time, monitoring, contract fees and support needs.
- Attribution and rights: Can you display, retain, transform or commercialize each field and asset?
An official API or licensed MLS/broker feed is often the cleanest production starting point because its schema and permitted use can be defined in documentation or a contract. That does not mean every API allows every use: read its license, attribution and display requirements.
3. Get authorization and record its limits
If the source requires authorization, obtain it before collecting. Keep a record of the account or agreement, API credentials, approved fields, rate limits, attribution language, retention window, allowed uses and redistribution rules. Make those limits part of your collector’s configuration and publishing checks.
Do not bypass authentication, CAPTCHA challenges, paywalls or other technical controls. Stop collection when access is denied, errors repeat, or a policy or agreement changes. Ask the source for access or use another permitted data source.
4. Build a conservative authorized collector in Python
The example below is a template for a source that has expressly authorized HTML collection. It expects a page whose listing cards expose stable data-listing-id attributes and semantic fields. Replace the selectors with ones documented or approved for your source. It does not attempt to evade blocks, and it stops on denial or unexpected responses.
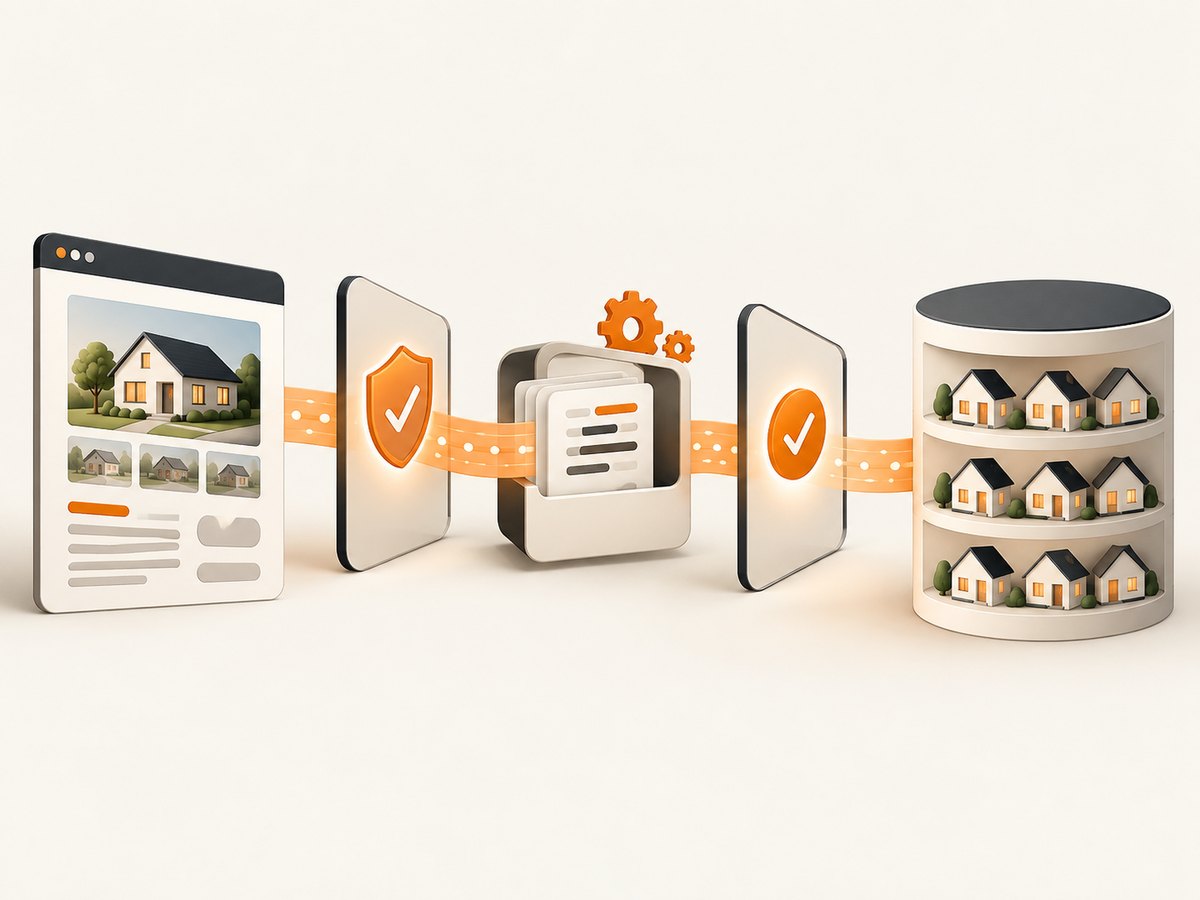
Install the dependency:
python -m pip install requests beautifulsoup4Save as collect.py and run SOURCE_URL=https://authorized.example/listings python collect.py after configuring the URL and selectors for your permitted source:
import json
import os
import time
from datetime import datetime, timezone
from decimal import Decimal, InvalidOperation
from urllib.parse import urljoin, urlparse

import requests
from bs4 import BeautifulSoup

SOURCE_URL = os.environ["SOURCE_URL"]
ALLOWED_HOST = urlparse(SOURCE_URL).hostname
USER_AGENT = "AuthorizedListingCollector/1.0 (contact: data-team@example.com)"
TIMEOUT_SECONDS = 20
MAX_RETRIES = 3

session = requests.Session()
session.headers.update({"User-Agent": USER_AGENT, "Accept": "text/html"})

def fetch(url):
    for attempt in range(MAX_RETRIES):
        response = session.get(url, timeout=TIMEOUT_SECONDS)
        if response.status_code in (401, 403, 429):
            raise RuntimeError(f"Access denied or rate limited: HTTP {response.status_code}; stop and review authorization")
        if response.status_code >= 500 and attempt + 1 < MAX_RETRIES:
            time.sleep(2 ** attempt)
            continue
        response.raise_for_status()
        if "text/html" not in response.headers.get("Content-Type", ""):
            raise RuntimeError("Expected HTML; inspect the authorized source schema")
        return response
    raise RuntimeError("Retry limit reached")

def text_or_none(card, selector):
    node = card.select_one(selector)
    return node.get_text(" ", strip=True) if node else None

def parse_price(raw):
    if not raw:
        return None
    # Preserve the source text; normalize only when its currency/format is known.
    digits = "".join(ch for ch in raw if ch.isdigit() or ch == ".")
    try:
        return str(Decimal(digits)) if digits else None
    except InvalidOperation:
        return None

def parse(html, page_url):
    soup = BeautifulSoup(html, "html.parser")
    observed_at = datetime.now(timezone.utc).isoformat()
    rows = []
    for card in soup.select("[data-listing-id]"):
        anchor = card.select_one("a[href]")
        href = urljoin(page_url, anchor["href"]) if anchor else None
        if href and urlparse(href).hostname != ALLOWED_HOST:
            href = None
        raw_price = text_or_none(card, ".listing-price")
        rows.append({
            "source_listing_id": card.get("data-listing-id"),
            "source_url": href,
            "address_raw": text_or_none(card, ".listing-address"),
            "price_raw": raw_price,
            "price_normalized": parse_price(raw_price),
            "beds_raw": text_or_none(card, ".listing-beds"),
            "baths_raw": text_or_none(card, ".listing-baths"),
            "area_raw": text_or_none(card, ".listing-area"),
            "status_raw": text_or_none(card, ".listing-status"),
            "observed_at": observed_at,
            "parser_version": "1.0",
        })
    return rows

response = fetch(SOURCE_URL)
records = parse(response.text, response.url)
with open("listings.jsonl", "a", encoding="utf-8") as output:
    for record in records:
        output.write(json.dumps(record, ensure_ascii=False) + "\n")
print(f"Appended {len(records)} authorized observations to listings.jsonl")
The selectors are deliberately source-specific placeholders; a real implementation must use the authorized source’s documented schema or inspect its permitted markup. The price normalizer preserves the raw value and makes only a limited numeric conversion. Do not infer currency or units from punctuation without knowing the source locale. For production, write to a database with a unique key and a separate observation-history table rather than appending indefinitely to one file.
What to store for each observation
- Source listing ID when provided, plus canonical source URL.
- Raw field values and normalized values side by side.
- Observed-at timestamp in UTC, parser version and source identifier.
- Currency, area units and address components only when confidently interpreted.
- A snapshot or field-level history sufficient to explain price and status changes, within the agreement’s retention limits.
5. Normalize, deduplicate and track listing changes
Prefer the source’s stable listing ID as the primary identifier. If none exists, combine the canonical source URL with a carefully normalized address, but do not assume that an address uniquely identifies a listing: a property can be relisted, and multiple units can share an address.
Normalize without discarding evidence. Keep original price text next to parsed amount and currency; preserve original address next to parsed components; retain area units; and store the source status verbatim alongside your internal mapping. Define how unknown, withdrawn, pending, sold and relisted states map to your application. A missing page is not automatically proof that a property sold or became unavailable.
For history, save timestamped observations or field changes. A useful record can answer what the source showed at a particular time, which parser produced it and why your system concluded a status changed. Delete raw data on the schedule authorized by the source.
6. Validate and monitor the pipeline
Run checks before records reach downstream users:
- Required ID or URL exists and belongs to an expected source.
- Price parses under the known locale and currency; flag unexpected symbols or ranges.
- Beds, baths and area are plausible for your dataset, without silently coercing missing values.
- Geocoding confidence and address components meet the product’s threshold.
- Status transitions are allowed by your state model or are sent for review.
- Record counts, missing-field rates and parser failures stay within expected bounds.
Compare samples to the source page, alert on sudden changes in extraction yield, and version parser changes. Keep enough authorized raw evidence to diagnose a discrepancy, then expire it on schedule. If the page structure changes, pause or quarantine suspect records rather than publishing malformed data.
7. Use screenshots for visual review
A screenshot can help an operator compare a rendered page with extracted fields when a parser is suspected of drifting. It is a visual debugging aid; it does not grant permission to collect or republish the underlying listing, text, image or contact details. Review the source’s terms and your agreement before capturing pages, and keep screenshots only as allowed.
For a DIY browser capture, Playwright can render an authorized page and save a full-page image. Install it with python -m pip install playwright and playwright install chromium:
import asyncio
from playwright.async_api import async_playwright

async def main():
    async with async_playwright() as p:
        browser = await p.chromium.launch(headless=True)
        page = await browser.new_page(viewport={"width": 1440, "height": 1000})
        await page.goto("https://authorized.example/listing", wait_until="domcontentloaded", timeout=30000)
        await page.screenshot(path="listing.png", full_page=True)
        await browser.close()

asyncio.run(main())
Use a URL for which you have permission and replace the example address. For dynamic pages, wait for a specific authorized page element instead of adding a long fixed delay. Respect the source’s access limits; do not use browser automation to circumvent a block.
Or skip the browser setup
ScreenshotNeo is a website screenshot API and MCP server. For an authorized URL, one request returns an image or PDF. Its capture options include full-page screenshots, selector-based element capture, device and viewport settings, waiting conditions, custom headers and cookies, and PDF output. See the ScreenshotNeo API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://authorized.example/listing -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://authorized.example/listing"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://authorized.example/listing' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot request failed: ${res.status}`);
await Bun.write('shot.webp', res);ScreenshotNeo accepts cookie or consent banners like a visitor and removes more than 60 known consent platforms, newsletter popups and chat widgets before capture; each step can be turned off. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads and cache hits are not billed, and response headers identify the page verdict and billing status. Its MCP server provides take_screenshot, get_page_info and capture_pdf for Claude, Cursor and other MCP clients. The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000. These capture features do not change your rights to access or use the target listing.
Sign up for 1,000 free screenshots a month, with no card required.
Performance, reliability and cost
For an authorized collector, the cheapest reliable request is often the one you avoid: use caching and conditional requests when the source supports them, and refresh at the interval your use case and agreement permit. Keep concurrency conservative and within documented limits. Use exponential backoff for transient server errors, but do not retry access denials or rate limits in a tight loop. A 429 response is a signal to slow or stop according to the source’s rules.
Separate fetch, parse, validation and persistence stages so a temporary source outage does not corrupt stored history. Make writes idempotent using a source ID and observation timestamp. Record response status and parser version, and alert on failures or unusual record counts. Keep secrets out of source code and logs. A screenshot service may simplify visual capture operations, but account for API usage and keep the authorization review separate from technical cost.
Compare total cost rather than request price alone: feed or API fees, development and maintenance, monitoring, storage, support, and the cost of correcting bad or unauthorized records. Licensed access may define scope and schema clearly; scraping can require ongoing parser upkeep and creates additional permission work. The appropriate choice depends on the agreement and requirements.
Troubleshooting
| Symptom | Likely cause | Safe next step |
|---|---|---|
| HTTP 401 or 403 | Missing credentials, access not authorized or permission changed | Stop collection; check the agreement and credentials or contact the source. |
| HTTP 429 | Rate limit reached | Stop or back off as the documented policy requires; reduce concurrency and refresh frequency. |
| HTTP 5xx or timeout | Temporary source or network failure | Retry a small number of times with exponential backoff; preserve prior data and alert if failures continue. |
| Zero records parsed | Markup or schema changed, wrong page, or content rendered differently | Pause publication, inspect an authorized sample, and update a versioned parser. |
| Prices look wrong | Locale, currency, separators or price labels differ | Preserve raw values; parse with known source locale and currency, and quarantine ambiguous values. |
| Duplicates appear | URL variation, relisting or missing stable source ID | Canonicalize permitted URLs, use source IDs where available and model relistings explicitly. |
| Status flips unexpectedly | Transient missing page or different source status semantics | Do not infer a final state from one miss; require validated observations and retain history. |
| Screenshot is blank or incomplete | Page rendering delay, blocked access or content outside the captured viewport | Confirm authorized access, wait for a relevant selector and choose full-page capture where appropriate. |
FAQ
Is it legal to scrape Zillow or Realtor.com?
That depends on the current terms, permissions, applicable agreements and your intended use. Realtor.com’s terms prohibit automated collection without express written permission; Zillow’s terms restrict reproducing or publicly displaying listing data and images except where permitted. Obtain written authorization or use a licensed access path, and seek jurisdiction-specific legal advice when needed.
Can I republish listing photos if they appear on a public page?
Visibility does not establish reuse rights. Photos, descriptions, agent details, logos and video can have separate rights and contractual limits. Publish only assets and fields your license permits, with required attribution and takedown controls.
Should I use an API or scrape HTML?
Start by checking for an official API, MLS feed or broker agreement that covers your fields and purpose. Use HTML collection only where expressly authorized and where the source’s permitted schema and operating limits are understood.
How do I know when a listing is truly gone?
Use the source’s documented status and update semantics. A missing page or a single failed fetch is not enough to conclude that a listing sold or became unavailable; retain observations and validate transitions.


