How to Scrape Social Media with Python in 2026
Learn how to collect social data with Python using approved APIs, OAuth, pagination, rate limits, retention rules, and reliable workflows.
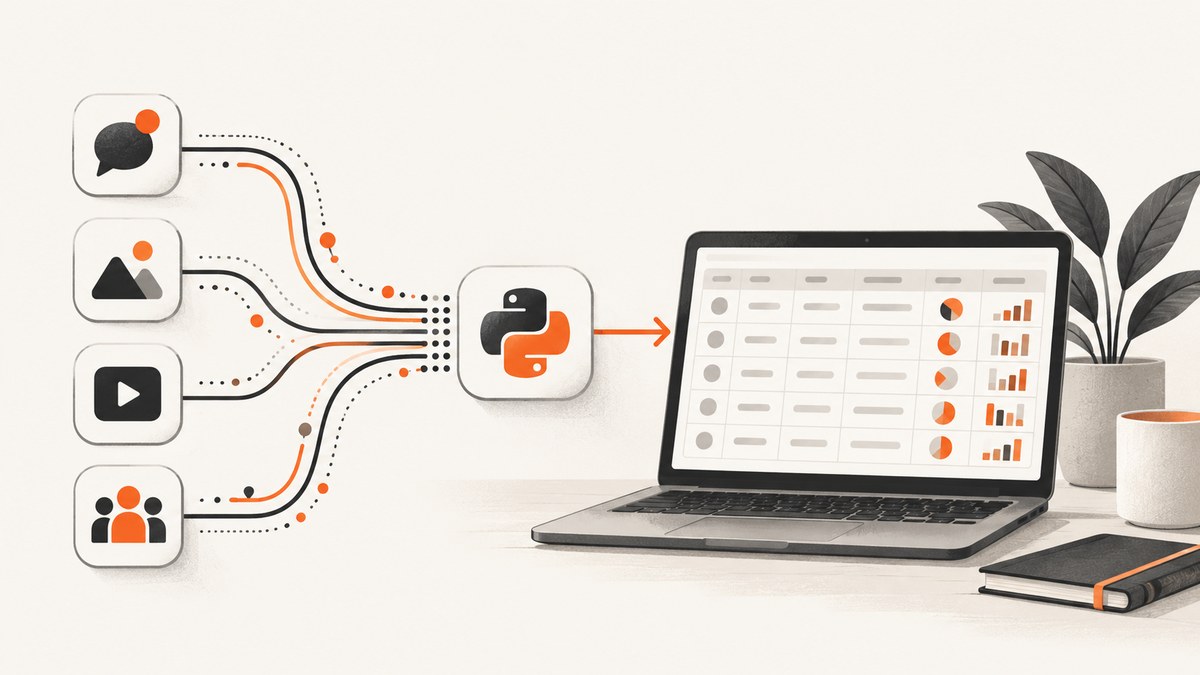
Direct answer: In 2026, the dependable way to scrape social media with Python is to use each platform’s documented API, obtain the required app approval and OAuth credentials, request only permitted fields, follow rate limits, paginate carefully, and retain collection time and source IDs. “Public” does not automatically mean “permitted to automate.” A browser scraper can violate platform terms, miss data behind authentication, and produce an unstable dataset.
This guide shows a platform-neutral Python workflow, then explains the important differences between X, Reddit, TikTok Research Tools, Meta platforms, and YouTube. It is written for authorized collection: public-post research, moderation workflows, reporting, and other uses allowed by the platform and your agreement.
1. Define the collection before writing code
Write down five things:
- Platform: X, Reddit, TikTok, or another service.
- Fields: for example, post ID, author ID, text, created time, public engagement counts, and permalink.
- Purpose: research, internal analytics, moderation, journalism, or a commercial product.
- Eligibility: whether your account, organization, or research project qualifies for the API.
- Retention: how long you need the records and how you will remove deleted content.
This prevents a common failure mode: building a collector first and discovering that the desired fields, purpose, or volume are not allowed. Keep sensitive data out unless it is necessary and explicitly permitted.
2. API access differs by platform
| Platform | Access and authentication | Operational details | Use caution about |
|---|---|---|---|
| X | Register an application. X documents public account and post endpoints; non-public information such as Direct Messages requires additional user-granted permissions. See X’s API overview. | Use the endpoint and pagination documented for your product tier. Store response IDs and timestamps. | Do not assume public-post access grants private data or every search capability. |
| Register an OAuth application and send a descriptive, unique User-Agent. Use the OAuth identity issued for your client. See Reddit’s Data API guidance. | Reddit documents 100 queries per minute per OAuth client ID for eligible free access, averaged over a 10-minute window. Monitor rate-limit headers. | Reddit says scraping without an authorized agreement may violate policy. Commercial or other unapproved use can require a separate agreement; remove content users delete. | |
| TikTok Research Tools | For qualifying independent or academic non-profit researchers. Apply and wait for approval; a developer account alone is not enough. | Documentation lists 1,000 requests and up to 100,000 records per day across Research APIs. Followers and Following endpoints can describe up to 2 million records per day through up to 20,000 calls. | Archived video data can lag: new videos may take up to 48 hours to appear and view or follower counts up to 10 days to update. Commercial users are directed to other API opportunities. |
| Meta (Facebook and Instagram) | Meta distinguishes authorized scraping from unauthorized automation. Confirm current Graph API products, permissions, and review requirements in Meta’s developer documentation before implementation. | This research does not establish current endpoint coverage or quotas. | Do not copy an Instagram or Facebook example from an old blog post and assume it is still valid. |
| YouTube | Verify current YouTube Data API documentation for credentials, scopes, endpoints, and quotas. | No current YouTube endpoint or quota details are asserted here. | Do not infer YouTube rules from another platform. |
Platform rules change. Recheck the live developer documentation, terms, eligibility, quotas, and retention requirements immediately before production deployment. Reddit also warns that some legacy API material may be outdated.
3. Set up a safe Python project
Use a virtual environment and keep credentials outside source control:
python -m venv .venv
# macOS/Linux
source .venv/bin/activate
# Windows PowerShell: .venv\\Scripts\\Activate.ps1
python -m pip install requests python-dotenv
Create a .env file that is ignored by Git:
SOCIAL_ACCESS_TOKEN=replace_me
SOCIAL_API_URL=https://api.example.com/v1/posts
The URL above is a placeholder. Replace it with the exact endpoint from the platform’s current documentation. Never put a client secret or token in a notebook that will be shared.
4. A reusable Python collector
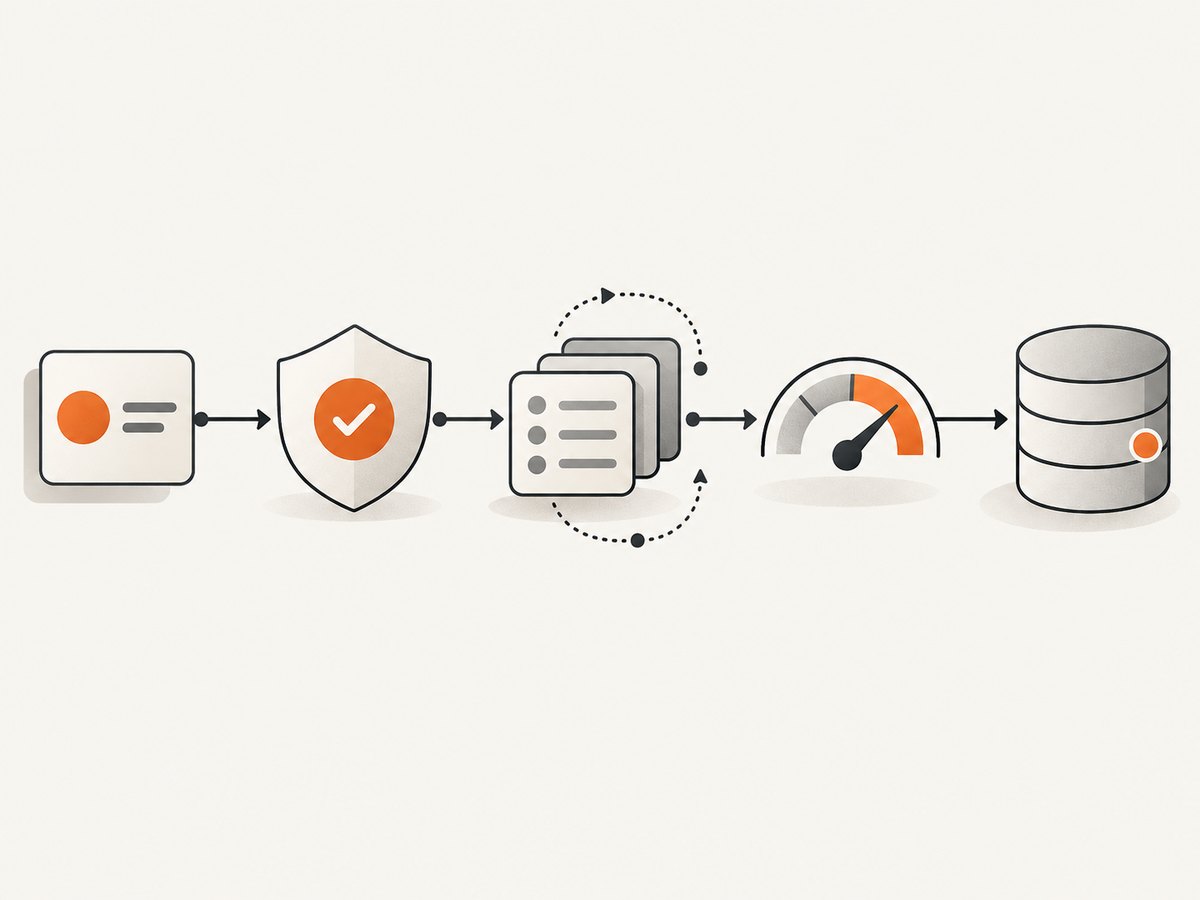
The following script is deliberately endpoint-neutral. It handles authentication, bounded retries, response validation, pagination, provenance, and a collection timestamp. Map the parameter names to the selected platform’s official API before running it.
import json
import os
import time
from datetime import datetime, timezone

import requests
from dotenv import load_dotenv

load_dotenv()
API_URL = os.environ["SOCIAL_API_URL"]
TOKEN = os.environ["SOCIAL_ACCESS_TOKEN"]

session = requests.Session()
session.headers.update({
    "Authorization": f"Bearer {TOKEN}",
    "Accept": "application/json",
    # Use the platform-approved descriptive value where required.
    "User-Agent": "authorized-research-collector/1.0 contact@example.org",
})

def get_page(params):
    for attempt in range(4):
        response = session.get(API_URL, params=params, timeout=30)
        if response.status_code == 200:
            return response.json(), response.headers
        if response.status_code in (429, 500, 502, 503, 504):
            retry_after = response.headers.get("Retry-After")
            delay = float(retry_after) if retry_after else min(2 ** attempt, 30)
            time.sleep(delay)
            continue
        response.raise_for_status()
    raise RuntimeError("The API remained unavailable after bounded retries")

def collect(query, max_pages=10):
    records = []
    next_cursor = None
    collected_at = datetime.now(timezone.utc).isoformat()

    for _ in range(max_pages):
        params = {
            "query": query,
            "limit": 100,
            # Replace this with the documented cursor parameter if needed.
        }
        if next_cursor:
            params["cursor"] = next_cursor

        payload, headers = get_page(params)
        for item in payload.get("data", []):
            records.append({
                "source_id": item.get("id"),
                "raw": item,
                "collected_at": collected_at,
            })

        # Adapt these keys to the API’s documented pagination response.
        next_cursor = (payload.get("meta") or {}).get("next_cursor")
        if not next_cursor:
            break

        remaining = headers.get("x-rate-limit-remaining")
        if remaining == "0":
            reset = headers.get("x-rate-limit-reset")
            if reset and reset.isdigit():
                time.sleep(max(int(reset) - int(time.time()), 0))
            else:
                time.sleep(2)

    return records

if __name__ == "__main__":
    rows = collect(query="python")
    with open("social-records.jsonl", "w", encoding="utf-8") as output:
        for row in rows:
            output.write(json.dumps(row, ensure_ascii=False) + "\\n")
    print(f"Wrote {len(rows)} records")
Why store the raw object and collected_at? APIs revise fields, counts change, and archived datasets can arrive late. Provenance lets you explain which response produced an analysis and rerun transformations without making another request.
5. Authentication patterns
OAuth user access
Some endpoints require a user to authorize scopes. Complete the platform’s authorization-code or device flow, exchange the code using the documented token endpoint, and store the resulting token securely. Request the smallest scopes possible. A token for public posts does not imply permission to read private messages, followers, email addresses, or deleted content.
Application-only access
Other public-data endpoints accept an application bearer token. Keep the application identity separate from a user identity and record which credential class produced each dataset. If an endpoint returns a 401 or 403, read the platform’s permission error before changing code.
Reddit-specific hygiene
Reddit requires registered OAuth, a unique descriptive User-Agent, and truthful client identity. Monitor the rate-limit headers and remove records that users delete when the applicable policy requires it. Do not rotate identities to evade a quota.
6. Pagination, quotas, and freshness
Never assume one response contains all matches. Follow the documented cursor, page token, or time-window mechanism until the API signals completion. Put a hard maximum on pages and records so a broad query cannot run indefinitely.
- Read response headers such as remaining quota and reset time when available.
- On HTTP 429, honor
Retry-Afteror the documented reset timestamp. - Use exponential backoff for transient 5xx responses, with a maximum retry count.
- Persist the cursor after each successful page so a process restart can resume.
- Record the API’s own update time when provided. TikTok Research data is archived, so a result can be valid while still being delayed.
TikTok’s documented figures—1,000 requests and up to 100,000 records per day across Research APIs, plus the separate Followers and Following allowance—are quotas for approved Research API access, not a general allowance to scrape TikTok.
7. Data minimization, deletion, and provenance
- Request only fields needed for the stated purpose.
- Hash or remove usernames when identity is not necessary.
- Keep source IDs, endpoint name, account or project identity, query, and collection timestamp.
- Define an expiration job for data no longer required.
- Process deletion signals and re-fetch status where the platform requires it.
- Restrict the database and logs; tokens must never appear in exception messages.
Reddit’s Data API terms grant a conditional, revocable license and require compliance with the developer documentation and applicable law. Commercial use, research beyond limits, or another use outside the permitted terms may require a separate agreement. TikTok Research Tools similarly distinguish approved non-profit research from commercial access.
8. cURL and Node.js equivalents
Use these only with an endpoint and authorization method allowed by the platform. They demonstrate the same request shape as the Python collector.
curl --fail-with-body --retry 3 \\
  -H "Authorization: Bearer $SOCIAL_ACCESS_TOKEN" \\
  -H "User-Agent: authorized-research-collector/1.0 contact@example.org" \\
  --get "$SOCIAL_API_URL" \\
  --data-urlencode "query=python" \\
  --data-urlencode "limit=100"
const url = new URL(process.env.SOCIAL_API_URL);
url.searchParams.set('query', 'python');
url.searchParams.set('limit', '100');
const response = await fetch(url, {
headers: {
Authorization: `Bearer ${process.env.SOCIAL_ACCESS_TOKEN}`,
'User-Agent': 'authorized-research-collector/1.0 contact@example.org',
Accept: 'application/json'
}
});
if (!response.ok) throw new Error(`${response.status}: ${await response.text()}`);
const payload = await response.json();
console.log(payload);9. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| 401 Unauthorized | Expired token, wrong audience, or missing bearer prefix. | Repeat the documented token flow and inspect the required Authorization header. |
| 403 Forbidden | App lacks a scope, project approval, or endpoint eligibility. | Request only documented scopes and confirm the project is approved. Do not try another identity to bypass the decision. |
| 429 Too Many Requests | Quota exhausted. | Honor Retry-After, slow workers, and persist cursors. Check whether your plan or agreement has a different limit. |
| Empty data | Wrong query syntax, unavailable field, indexing delay, or a page token bug. | Test the smallest documented query, log sanitized request parameters, and check freshness notes such as TikTok’s 48-hour indexing delay. |
| Repeated records | Cursor was not advanced or retries were not idempotent. | Deduplicate by platform source ID and persist the cursor only after a page is written successfully. |
| Timeouts | Large page size, slow endpoint, or network failure. | Lower the page size, use a 30–90 second client timeout, and retry only transient failures. |
| Deleted content remains | No deletion reconciliation. | Run the platform’s documented deletion process and remove records no longer required. |
10. Performance, reliability, and cost
Throughput is usually bounded by the platform quota, not Python. Use one shared HTTP session, moderate concurrency only where the documentation permits it, and backoff with jitter when many workers receive 429 responses. Batch database writes per page, but commit the cursor after the batch is durable.
Measure requests, successful records, empty pages, 4xx and 5xx responses, retry count, and lag between the platform timestamp and collection timestamp. Alert on a sudden rise in 403 responses or empty pages; it can indicate a permission change rather than a coding bug.
Budget for API access, storage, and reprocessing. A free quota can still create database and egress costs. Keep raw responses only as long as necessary, compress archival files, and schedule incremental collection instead of repeatedly downloading the same history.
11. Or skip the browser setup
If your task is to capture a social page visually for documentation, QA, or an audit, ScreenshotNeo provides a website screenshot API. It is separate from authorized social-data APIs: it captures the rendered page rather than granting access to platform records.
One request returns PNG, JPEG, WebP, or PDF. The API accepts full-page capture, CSS element selection, dark mode, device presets or custom viewports, retina scale, custom CSS and JavaScript, clicks, selector waits, delays, network-idle waits, blocked resources, headers, cookies, user agents, Authorization, timezone, geolocation, transparent backgrounds, resizing, caching, signed links, asynchronous jobs, webhooks, bulk capture, and usage reporting. See the ScreenshotNeo documentation for parameter names and response details.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://reddit.com/r/python -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://reddit.com/r/python"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://reddit.com/r/python' });
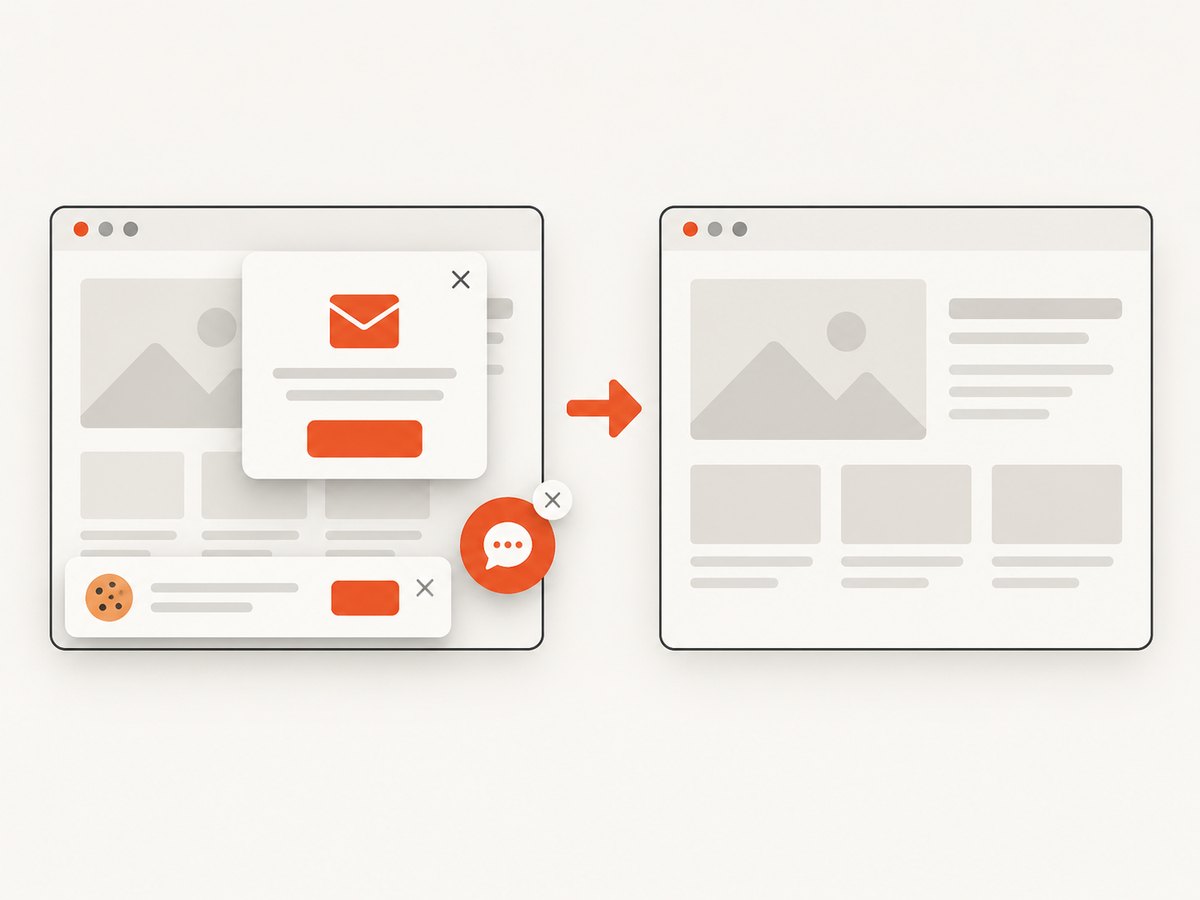
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing status. An MCP server lets Claude, Cursor, and other MCP clients call take_screenshot, get_page_info, and capture_pdf. The Free plan includes 1,000 screenshots each month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
12. Practical checklist
- Confirm the platform’s current terms and API documentation.
- Record the purpose, fields, eligibility, and retention period.
- Register the app or research project and use approved OAuth.
- Keep secrets in environment variables or a secret manager.
- Send a truthful User-Agent where required.
- Implement bounded retries, pagination, quota handling, and cursor persistence.
- Store source IDs, timestamps, query parameters, and provenance.
- Remove deleted or expired data according to the platform’s rules.
- Stop when access is denied; request the correct permission or change the scope.
13. FAQ
Can I scrape any public profile with Python?
No. Public visibility does not settle authorization. Check the platform terms, endpoint permissions, and your purpose first.
Is a third-party Python package enough?
No. A library can simplify HTTP calls, but it cannot expand the permissions granted to your app.
Should I rotate proxies when I hit a limit?
No. Treat the limit as a policy boundary. Slow down, request an approved quota, or reduce the collection scope.
How current is the data?
It depends on the API. TikTok Research documentation explicitly describes archived data and delays of up to 48 hours for new videos and up to 10 days for some counts.
Can ScreenshotNeo provide social-media API access?
No. ScreenshotNeo captures rendered webpages. Use the social platform’s approved API for records, and use ScreenshotNeo when you need a clean visual capture.


