How to Scrape Text From a Span With PuppeteerSharp
Select a span, wait for JavaScript content, extract innerText, handle nulls and frames, and automate reliable text scraping with PuppeteerSharp.
To scrape text from one <span> with PuppeteerSharp, navigate to the page, wait until the span exists if JavaScript renders it, select it with QuerySelectorAsync, read its innerText property, and convert the result to a C# string. The complete pattern is:
using PuppeteerSharp;

await new BrowserFetcher().DownloadAsync();
await using var browser = await Puppeteer.LaunchAsync(new LaunchOptions { Headless = true });
await using var page = await browser.NewPageAsync();
await page.GoToAsync("https://example.com");

var span = await page.QuerySelectorAsync("span.price");
if (span is null)
{
    throw new InvalidOperationException("The span selector did not match an element.");
}

var textHandle = await span.GetPropertyAsync("innerText");
var text = await textHandle.JsonValueAsync<string>();
Console.WriteLine(text);
This approach reads the text as a user sees it. QuerySelectorAsync returns an element handle for the first match, or null when no element matches. GetPropertyAsync("innerText") obtains the rendered text property, and JsonValueAsync<string>() converts it to a C# string.
1. Set up PuppeteerSharp
Create a console application and add the PuppeteerSharp package:
dotnet new console -n SpanScraper
cd SpanScraper
dotnet add package PuppeteerSharp
PuppeteerSharp controls a Chromium browser from .NET. The first run downloads a compatible browser through BrowserFetcher. In a production image, you can download the browser during the image build and point ExecutablePath at the installed binary instead.
Use await using for the browser and page. Browser processes consume memory and file descriptors; disposing them is essential when the scraper runs repeatedly.
2. Scrape a span from static HTML
For markup that is already present when navigation finishes, query the span immediately after GoToAsync:
using PuppeteerSharp;

await new BrowserFetcher().DownloadAsync();
await using var browser = await Puppeteer.LaunchAsync(new LaunchOptions
{
    Headless = true
});
await using var page = await browser.NewPageAsync();

await page.GoToAsync("https://example.com/product");

var span = await page.QuerySelectorAsync("span.price");
if (span is null)
{
    throw new InvalidOperationException(
        "No span.price element was found on https://example.com/product.");
}

var innerTextHandle = await span.GetPropertyAsync("innerText");
var priceText = await innerTextHandle.JsonValueAsync<string>();

Console.WriteLine(priceText);
Make the selector specific enough to identify the field you need. A class such as span.price or a data attribute such as span[data-testid='price'] is generally more stable than a positional selector like div:nth-child(3) span.
3. Wait for JavaScript-rendered spans
Single-page applications often load the page shell first and insert the actual span after an API request. In that case, navigation completion does not mean the target exists. Call WaitForSelectorAsync before querying:
await page.GoToAsync("https://example.com/product");
await page.WaitForSelectorAsync("span.price");

var span = await page.QuerySelectorAsync("span.price");
if (span is null)
{
    throw new InvalidOperationException("The price span was not rendered.");
}

var text = await (await span.GetPropertyAsync("innerText"))
    .JsonValueAsync<string>();

Console.WriteLine(text);
WaitForSelectorAsync waits for a selector to be added to the DOM. Add an explicit timeout when a missing element should fail quickly:
await page.WaitForSelectorAsync("span.price", new WaitForSelectorOptions
{
    Timeout = 10_000
});
A timeout usually means one of four things: the selector is wrong, the page returned an error or login screen, the content is inside an iframe, or the application never completed its request. Capture the URL, selector, and page title in your error logs so the failure can be diagnosed.
4. Choose between innerText, textContent, and innerHTML
innerText is the usual choice for scraping visible text. It respects CSS visibility and represents line breaks as rendered by the browser. textContent returns the text nodes in the DOM, including text that may be hidden with CSS. innerHTML returns markup and should only be used when you intentionally need child elements.
var innerText = await (await span.GetPropertyAsync("innerText"))
    .JsonValueAsync<string>();

var textContent = await (await span.GetPropertyAsync("textContent"))
    .JsonValueAsync<string>();

var html = await (await span.GetPropertyAsync("innerHTML"))
    .JsonValueAsync<string>();
Normalize whitespace only after deciding what it means for your data. For a price, trimming is usually enough. For a multi-line label, replacing all whitespace with a single space may destroy meaningful formatting.
var normalized = text.Trim();5. Scrape several spans
Use QuerySelectorAllAsync when a page contains a collection of matching spans:
var spans = await page.QuerySelectorAllAsync("span.result");
var values = new List<string>();

foreach (var item in spans)
{
    var value = await (await item.GetPropertyAsync("innerText"))
        .JsonValueAsync<string>();
    values.Add(value.Trim());
}

foreach (var value in values)
{
    Console.WriteLine(value);
}
An empty collection is not an exception. Decide whether zero results is valid for your job. If it is an error, check values.Count and report the URL and selector.
6. Use page-side evaluation for custom extraction
When extraction needs fallback logic, filtering, or traversal of nested elements, execute JavaScript in the page context with EvaluateFunctionAsync:
var text = await page.EvaluateFunctionAsync<string>(
    "selector => document.querySelector(selector)?.innerText ?? ''",
    "span.price");
This returns an empty string when there is no match. That is convenient for optional fields, but it can hide a selector regression. For required fields, return a structured result or throw in the page function:
var value = await page.EvaluateFunctionAsync<string>(@"
    selector => {
        const element = document.querySelector(selector);
        if (!element) {
            throw new Error(`Selector not found: ${selector}`);
        }
        return element.innerText.trim();
    }
", "span.price");
Evaluation is also useful for selecting the first non-empty span, joining child labels, or reading an attribute:
var data = await page.EvaluateFunctionAsync<string>(@"
    selector => {
        const element = document.querySelector(selector);
        return element?.getAttribute('data-value') ?? '';
    }
", "span.price");
7. Handle iframes
A selector run against the main page cannot see elements inside an iframe. Find the frame first, then perform the same selector operations against the frame:
await page.GoToAsync("https://example.com/embedded");
await page.WaitForSelectorAsync("iframe[data-widget]");

var frame = page.Frames.FirstOrDefault(f =>
    f.Url.Contains("widget", StringComparison.OrdinalIgnoreCase));

if (frame is null)
{
    throw new InvalidOperationException("The widget frame was not found.");
}

await frame.WaitForSelectorAsync("span.value");
var span = await frame.QuerySelectorAsync("span.value");
if (span is null)
{
    throw new InvalidOperationException("The span was not found in the frame.");
}

var value = await (await span.GetPropertyAsync("innerText"))
    .JsonValueAsync<string>();
Cross-origin frames are still automatable as frame contexts, but you must select the correct frame object. If the iframe is created after navigation, wait for the iframe element or poll page.Frames briefly.
8. Make navigation and extraction reliable
Use navigation and wait settings that match the site. Waiting for network idle can help with applications that fetch data immediately after load, while a selector wait is more precise for the field you actually need:
await page.GoToAsync("https://example.com/product", new NavigationOptions
{
    WaitUntil = new[] { WaitUntilNavigation.DOMContentLoaded },
    Timeout = 30_000
});

await page.WaitForSelectorAsync("span.price", new WaitForSelectorOptions
{
    Timeout = 15_000
});
Do not use arbitrary long delays as the only synchronization method. A fixed delay can be too short on a slow run and waste time on a fast run. Prefer a selector, a known response, or an application-specific readiness condition.
For repeated jobs, create one browser process and a fresh page per URL, or limit concurrency with a queue. Launching a browser for every span increases startup cost and memory use. Always close pages and browsers when a job finishes or fails.
9. Troubleshooting common errors
| Symptom | Likely cause | Fix |
|---|---|---|
QuerySelectorAsync returns null |
Selector mismatch or content not rendered yet | Verify the selector in DevTools and add WaitForSelectorAsync. |
| Wait times out | Wrong URL, failed request, consent wall, login page, or iframe | Log the final URL and title, save HTML, inspect frames, and check the selector on the returned page. |
| Text is empty | The span contains hidden text, only child elements, or text is inserted later | Try textContent, wait for a non-empty value, or evaluate custom JavaScript. |
| Only part of the page is visible | Target is in an iframe or shadow DOM | Use the correct frame; for shadow DOM, evaluate from the host element and traverse its shadow root. |
| Browser fails to launch | Chromium was not downloaded or executable dependencies are missing | Run BrowserFetcher().DownloadAsync(), verify the executable path, and install required system libraries in the host image. |
| Scraper leaks memory | Pages or browsers are not disposed | Use await using, cap concurrency, and recycle the browser periodically for very long jobs. |
When debugging, save a screenshot and the current HTML immediately before extraction. The screenshot shows whether a consent dialog or error page covers the content; the HTML confirms whether the span exists at all.
10. Parse and validate the extracted value
Keep extraction separate from parsing. First obtain the string, then convert it with the expected culture and validation rules:
using System.Globalization;

var raw = text.Trim();
if (!decimal.TryParse(raw, NumberStyles.Currency,
    CultureInfo.InvariantCulture, out var amount))
{
    throw new FormatException($"Unexpected price text: '{raw}'");
}
Web pages may include currency symbols, non-breaking spaces, localized decimal separators, or accessible text that differs from the visual label. Store the raw value alongside the parsed value when auditability matters.
11. When a screenshot or rendered capture is enough
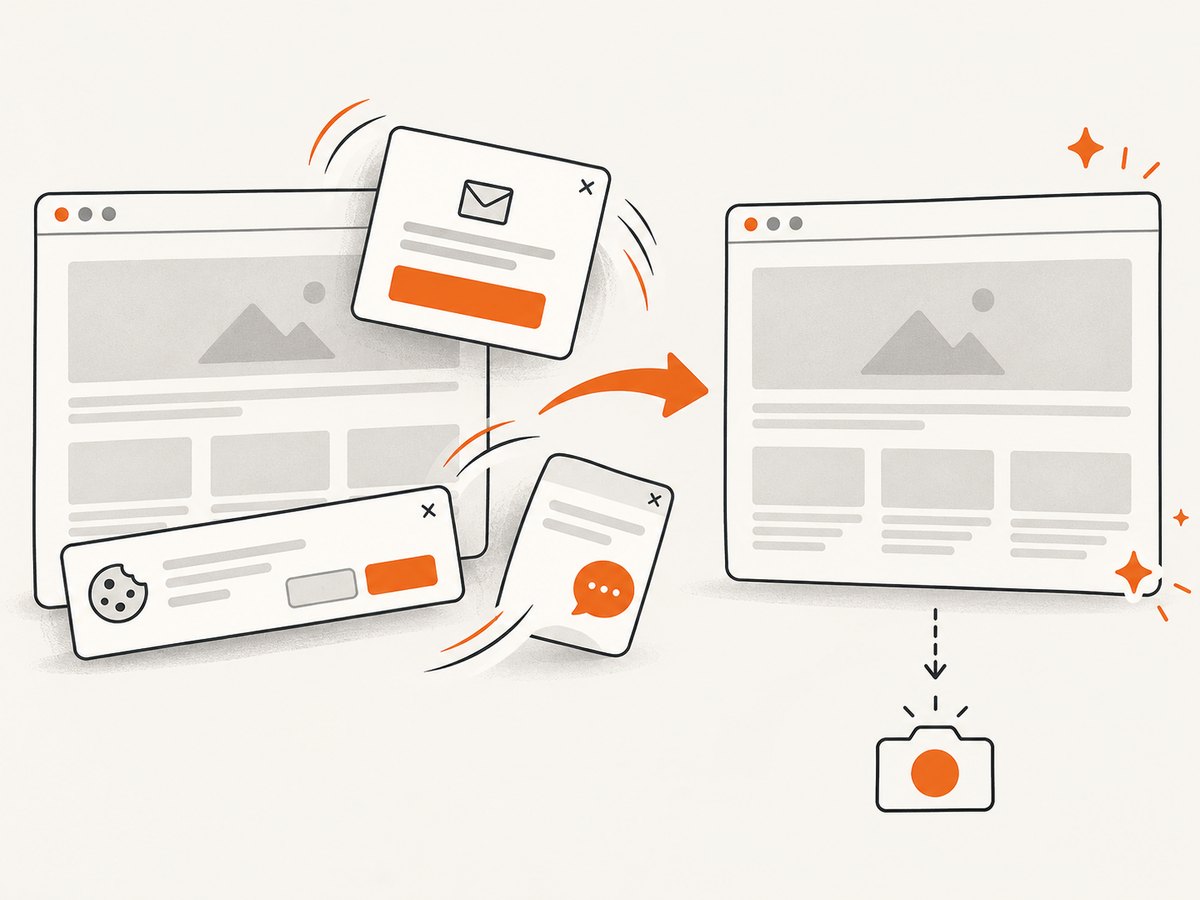
If the goal is visual verification, documentation, regression review, or an image of the rendered span rather than structured text, a screenshot API can avoid maintaining a browser runtime. ScreenshotNeo accepts one GET request and returns a PNG, JPEG, WebP, or PDF. It can wait for selectors, run custom JavaScript, capture one element by CSS selector, and remove known cookie banners, newsletter popups, and chat widgets before capture.
Or skip the browser setup
Use the ScreenshotNeo endpoint when you need a rendered result and do not want to manage Chromium. See the ScreenshotNeo API documentation for the full option list.
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
Cookie banners, popups, and chat widgets are removed before the shot. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing status. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000 shots.
Create a free ScreenshotNeo account to try the API with 1,000 screenshots each month and no card.
12. Performance, reliability, and cost considerations
- Reuse resources: Keep one browser process for a batch and create isolated pages. Limit parallel pages according to available memory.
- Wait precisely: A selector wait is usually cheaper and more reliable than a long fixed delay.
- Cache carefully: Cache only when stale text is acceptable. Include URL, selector, and relevant headers in your cache key.
- Retry selectively: Retry navigation timeouts and transient network failures, but do not endlessly retry a deterministic selector mismatch.
- Record evidence: Log URL, selector, final URL, duration, and whether the result was empty. Store HTML or screenshots for failed runs.
- Respect access rules: Follow the target site’s terms, robots guidance, authentication requirements, and rate limits.
FAQ
Does PuppeteerSharp scrape hidden span text?
innerText reflects rendered visibility. Use textContent when you intentionally need text nodes that are hidden by CSS.
What is the difference between QuerySelectorAsync and QuerySelectorAllAsync?
The first returns one matching element handle or null. The second returns all matching handles, including an empty collection when there are no matches.
Can I scrape a span without launching Chromium?
Only when the required text is present in the original HTML and you use an HTTP parser. JavaScript-rendered spans require a browser or a rendering service.
Why does the selector work in DevTools but fail in PuppeteerSharp?
DevTools may be inspecting a later application state, a different frame, or a page after authentication. Wait for the element, inspect the final URL, and check the frame context.
Should I use a CSS class or XPath?
Use the most stable identifier available, such as a data attribute. CSS selectors are usually sufficient; XPath is useful when the relationship between elements matters.


