How to Scrape Websites With Google Sheets
Use Google Sheets import formulas for supported web data, then move to Apps Script or the Sheets API when you need more control.
To scrape a website with Google Sheets, choose the import function that matches the data the page exposes: IMPORTHTML for an HTML table or list, IMPORTXML for structured HTML or XML selected with XPath, IMPORTDATA for a CSV or TSV URL, and IMPORTFEED for RSS or Atom. These formulas work when the data is available in a format Sheets can fetch; they do not make every website scrapeable.
Start with one source URL, test the result, and check that the returned fields match what you intended to collect. If the source requires login, interaction, or JavaScript rendering that the import function cannot access, or if you need custom processing and controlled automation, use Apps Script or the Sheets API. Google frames import functions as suitable for small amounts of dynamic data and points to those tools for more complex ingestion.
1. Choose the right Google Sheets import function
| Source format | Function | Use it when |
|---|---|---|
| HTML table or list | IMPORTHTML |
The desired content is in a table or list on a page. |
| Structured HTML or XML | IMPORTXML |
You can select the content with an XPath expression. |
| CSV or TSV file | IMPORTDATA |
The URL serves delimited text data directly. |
| RSS or Atom feed | IMPORTFEED |
The site publishes an RSS or Atom feed. |
The page’s visual appearance is not enough to determine which function will work. A page may show data in a table but build that table with client-side JavaScript, or require a login or user action before the data appears. The import functions are documented for supported data formats; a particular URL still needs to be checked in Sheets.
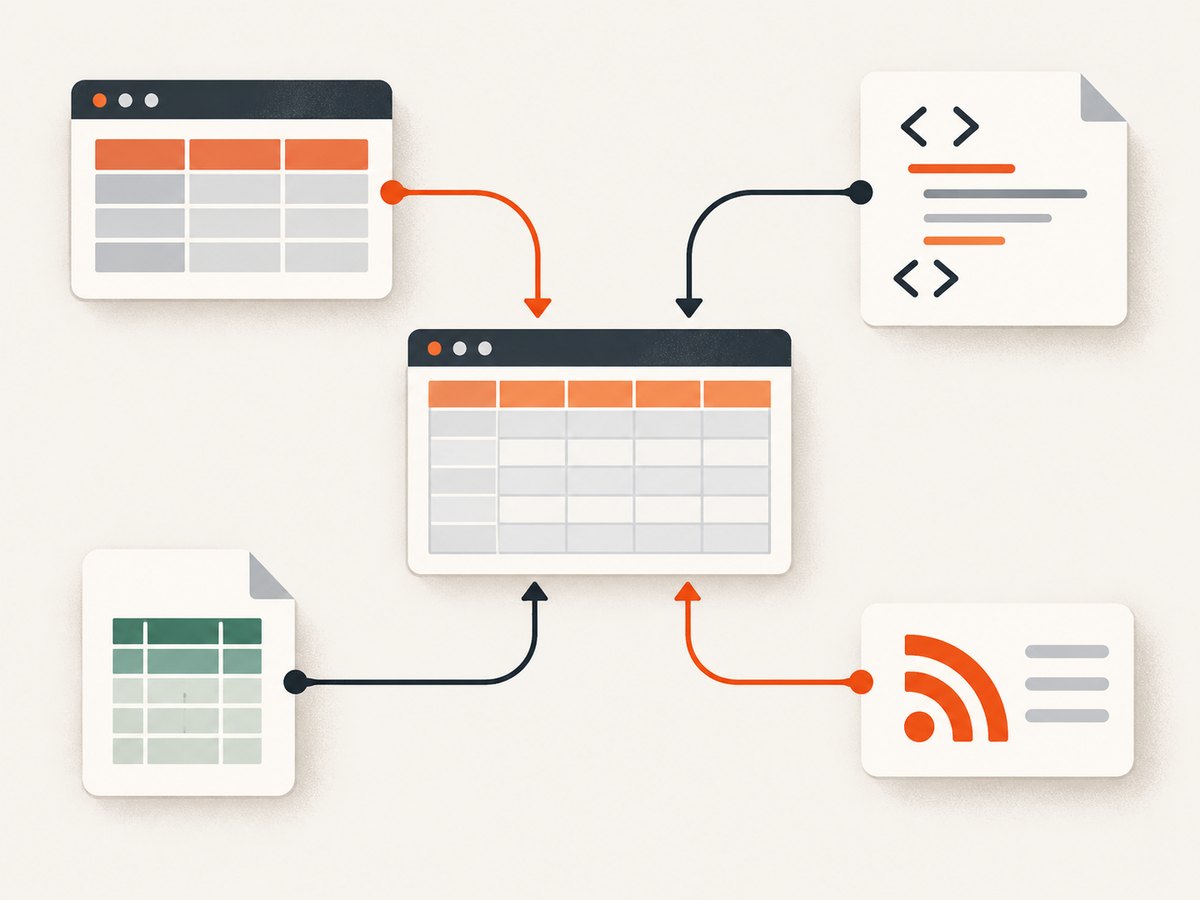
2. Import an HTML table or list with IMPORTHTML
IMPORTHTML(url, query, index) takes a page URL, a query of "table" or "list", and a one-based index. Begin with the table or list that visibly contains the target information, then inspect the output for headers, row count, and column order.
=IMPORTHTML("https://en.wikipedia.org/wiki/Demographics_of_India","table",4)This follows Google’s documented example. Replace the URL and index with the page and table you need. If the result is the wrong content, try the next plausible index and compare the output. The index counts tables or lists found on the page, not the position of a row within a table.
Keep the URL and index editable
Put the URL and index in cells so you can adjust the source without rebuilding the formula:
A1: https://example.com/catalog
B1: 1
C1: =IMPORTHTML(A1,"table",B1)
For a list instead of a table, change the second argument to "list". After the import loads, verify that the result has the expected number and meaning of columns. A successful formula can still return a different table than the one you intended.
3. Select structured content with IMPORTXML
Use IMPORTXML(url, xpath_query, locale) to select structured data from a page with XPath. Google documents imports of structured data including XML, HTML, CSV, TSV, RSS, and Atom XML. XPath describes where the content is in the document, so it must fit the source page’s markup.
=IMPORTXML("https://en.wikipedia.org/wiki/Moon_landing","//a/@href")This documented example returns link targets. For a real task, test a small, specific selection first. Store the page URL and XPath in cells if you expect to adjust them:
A1: https://example.com/articles
B1: //h2/a
C1: =IMPORTXML(A1,B1)
XPath is not a visual selector. Page redesigns can change the structure and cause an expression to return no values or the wrong values. Recheck the imported fields after a source change, and avoid assuming that a selector valid for one page template also fits every page on a site. The optional locale argument can be supplied where locale handling is relevant; it does not change what the XPath selects.
4. Import CSV, TSV, RSS, or Atom data
If the source provides a CSV or tab-separated values URL, import that directly instead of extracting cells from a rendered page:
=IMPORTDATA("https://example.com/data.csv")For a published RSS or Atom feed, use IMPORTFEED, the purpose-built Sheets import option for feeds. Check the function’s current in-product help for its arguments and available feed fields. A feed endpoint or CSV URL can be more stable for structured ingestion than a page layout, but the endpoint must still be accessible to Sheets.
5. Build and validate a small import workflow
- Identify the source shape. Determine whether the needed fields are served as a table/list, other structured markup, CSV/TSV, or a feed.
- Choose the matching function. Use
IMPORTHTML,IMPORTXML,IMPORTDATA, orIMPORTFEEDaccordingly. - Test one URL. Do not fill a workbook with repeated formulas before confirming that the source can be fetched and the output is useful.
- Check the values. Compare a few returned fields with the source page. Confirm headers, row alignment, duplicates, and missing values.
- Move adjustable inputs into cells. Keep URLs, table indices, and XPath expressions easy to change and review.
- Reduce repeated requests. Avoid unnecessary copies of the same import and frequent changes to its arguments.
- Reassess when the source changes. A page redesign or changed endpoint can invalidate a previously working table index or XPath.
For collection at scale, also review the target site’s access rules. Google describes robots.txt as a way for site owners to manage crawler access and traffic. It is not a security mechanism and does not ensure that a page cannot appear in search results. Do not treat a formula, script, or robots.txt entry as permission to ignore a site’s terms or access controls.
6. When to use Apps Script or the Sheets API
Built-in formulas are convenient for small, straightforward imports. Apps Script or the Sheets API may fit better when you need custom ingestion logic, a preferred programming language, or more control over how data is fetched and processed. Google’s ingestion guide describes these as options for more complex needs; switching tools does not guarantee access to a page that requires authentication or browser interaction.
Apps Script’s UrlFetchApp can make HTTP and HTTPS requests. A basic request-and-log example is:
function fetchPage() {
  const url = 'https://example.com/data.csv';
  const response = UrlFetchApp.fetch(url);
  Logger.log(response.getContentText());
}
If the script declares OAuth scopes explicitly, URL Fetch requires the external-request authorization scope. Apps Script also applies per-user quotas and execution limits. The current published quota page lists URL Fetch at 20,000 calls per day for consumer accounts and 100,000 for Google Workspace, and a six-minute runtime per execution. Google says quotas are per user, reset 24 hours after the first request, and can change or be eliminated without notice. Check the current official quota page before designing around a number. These are Apps Script limits, not a promise that a third-party site will accept the requests.
The Sheets API is another option when your workflow needs more complex logic or you prefer to perform ingestion in an application. It is not a website scraper by itself: your program still needs an allowed way to obtain the source data, then can write results into a spreadsheet.
7. Or skip the browser setup
If your goal is to capture a visual record of a page alongside your spreadsheet data, [ScreenshotNeo](https://screenshotneo.com) provides a screenshot API. It is separate from structured data extraction: a screenshot gives you an image or PDF of a page, not table cells to import.
One GET request captures a URL. See the [ScreenshotNeo API docs](https://screenshotneo.com/docs/) for configuration details.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://example.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com' });
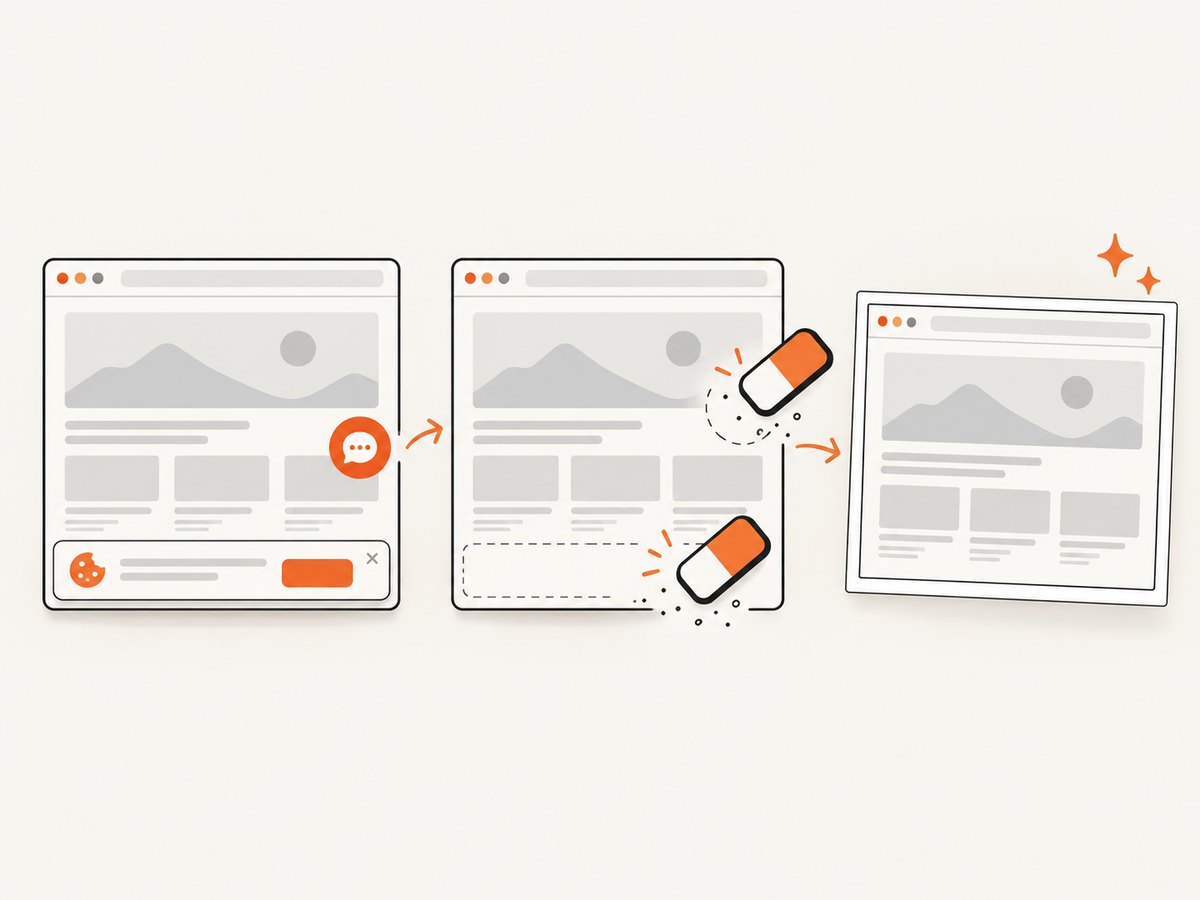
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo accepts cookie and consent banners like a visitor and removes more than 60 known consent platforms, newsletter popups, and chat widgets before capture; each step can be turned off. Bot checks and CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed, with response headers indicating the page verdict and billing status. Its MCP server offers take_screenshot, get_page_info, and capture_pdf for AI agents. The free plan includes 1,000 shots a month with no card; paid plans start at $5 for 3,000 shots.
Sign up free for 1,000 screenshots a month with no card.
8. Troubleshooting Google Sheets imports
| Symptom | Likely cause | What to try |
|---|---|---|
No useful result from IMPORTHTML |
Wrong query type or table/list index. | Try "table" versus "list", check another one-based index, and inspect the returned fields. |
IMPORTXML returns no values |
The XPath does not match the fetched document, or the desired content is not exposed in the retrieved markup. | Test a narrower XPath and verify the page structure and access requirements. |
| Import works, then breaks | The page markup, table order, endpoint, or feed changed. | Revalidate the URL, selector, and fields against the current source. |
| Data is incomplete | The page may need login, interaction, or client-side rendering, or the selected structure omits fields. | Check what is actually available to the importer; use an authorized source endpoint or a more suitable ingestion method. |
| “Loading data may take a while because of the large number of requests” | Import functions are creating too much traffic. | Reduce the number of import functions and avoid frequent changes to their arguments. Google does not give a universal fixed maximum number of formulas. |
| Apps Script authorization error | The script has not been granted the required external-request authorization, or declared scopes omit it. | Authorize the script as prompted and, when scopes are explicit, include the URL Fetch external-request scope. |
| Apps Script stops during a large run | The execution reached a quota or runtime limit. | Reduce work per execution, track calls, and check the current quotas for the account in use. |
9. Performance, reliability, and cost
Formula imports are quick to set up, but repeated calls and argument churn can create enough traffic to be throttled. Keep the number of import formulas under control and avoid duplicating fetches across a workbook when the same source can be reused. Google’s guidance is operational rather than a universal per-spreadsheet formula ceiling.
Apps Script gives you a place to add custom processing, but introduces authorization, execution runtime, and account-based quotas. Those quotas can change and do not control a target site’s own access rules or availability. The Sheets API can fit a larger application workflow, but it does not remove the need to obtain the source data appropriately.
For reliability, verify values at the point of use, make source URLs and selectors easy to update, and keep a fallback plan for a source layout or feed change. For cost planning, the built-in formulas do not require a separate screenshot product; Apps Script and API designs should be evaluated against their applicable Google quotas and the time required to maintain them. ScreenshotNeo’s separate visual-capture service has a free tier and paid tiers; use it only when a screenshot or PDF is useful, rather than as a replacement for structured extraction.
10. Frequently asked questions
Can Google Sheets scrape any website?
No. Import functions support particular data formats and structures, but a URL may require login, interaction, or client-side rendering unavailable to the function.
Should I use IMPORTHTML or IMPORTXML?
Use IMPORTHTML when the content is a table or list. Use IMPORTXML when the needed structured content can be selected with XPath.
Can I use a spreadsheet formula to bypass a site’s access controls?
No. Use only sources and access methods permitted by the site. Google’s description of robots.txt concerns crawler guidance and traffic management; it is not a security control or permission grant.
Can a screenshot API put page data into spreadsheet cells?
A screenshot API returns a visual capture, not structured table values. Use Sheets import functions, Apps Script, or an application using the Sheets API for cell data.


