How to Scrape Websites with Static Pagination
Learn a repeatable, reliable workflow for scraping every page of a statically paginated website with Python, cURL, Node.js, validation, and stopping rules.
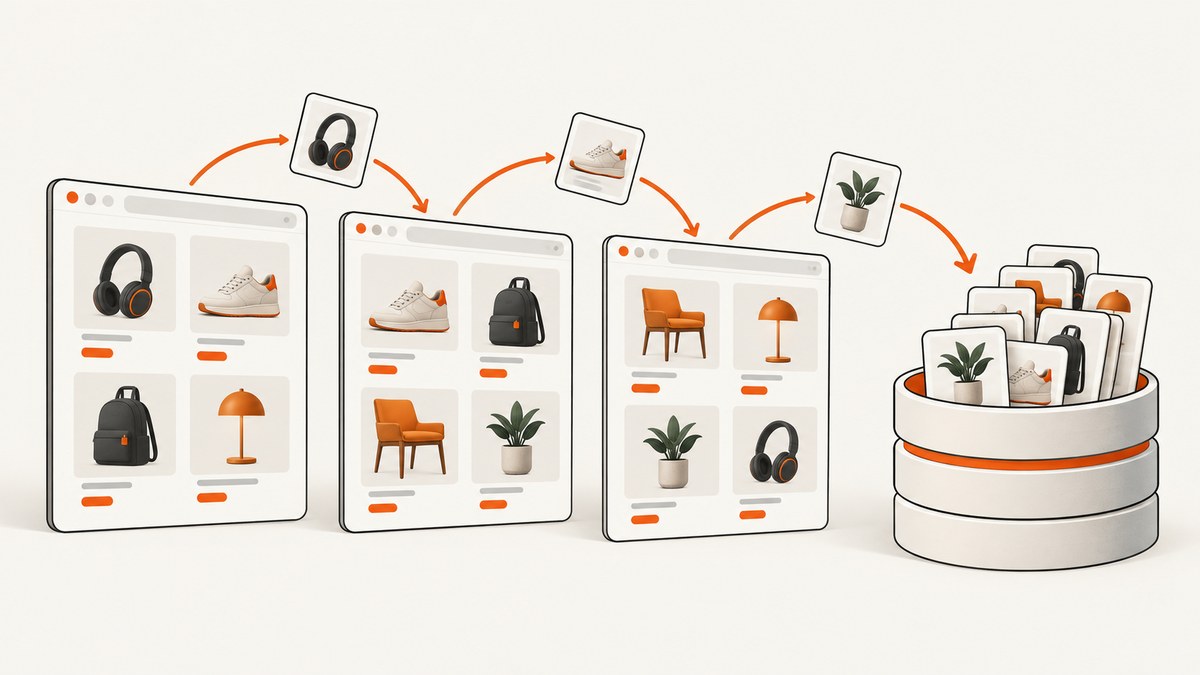
Direct answer: To scrape a website with static pagination, request the first listing page, extract records and the actual pagination links from its returned HTML, resolve each link against the response URL, fetch the next page, parse the same fields, and continue until there is no valid next link or a safety boundary is reached. Check every response status and body, track visited URLs, and deduplicate records so malformed links or repeated pages cannot create an endless crawl.
“Static” means the records and pagination controls are already present in ordinary HTML returned by the server. You do not need to click a browser control or execute JavaScript merely to discover page two. The exact selectors, URL shapes, and stopping conditions are site-specific, so inspect the target before writing assumptions into production code.
What static pagination looks like
Open a listing URL with an HTTP client and inspect its response body. Typical pagination is represented by one of these structures:
- A
rel="next"link such as<a rel="next" href="/products?page=2">. - A “Next” anchor with a normal
href. - Page-number links whose
hrefvalues contain a page number. - A stable path or query pattern, such as
/catalog/page/2/or?page=2.
Prefer the destination the page actually provides. Scrapy’s request and response model exposes the response URL, status, headers, and body, and its link-following APIs operate on URLs or extracted Link objects. An anchor without an href does not provide a destination to a link extractor. See the Scrapy requests and responses documentation.
A repeatable workflow
- Check permission and policy. Read the target’s terms, robots.txt, and published guidance. Legal requirements, request rates, and permitted uses depend on the site and jurisdiction; there is no universal rule in this tutorial.
- Fetch the first page. Record the final URL, status code, headers, and body. A completed request is not proof that the page is usable.
- Identify one record. Select a stable container and define the fields you need before handling pagination.
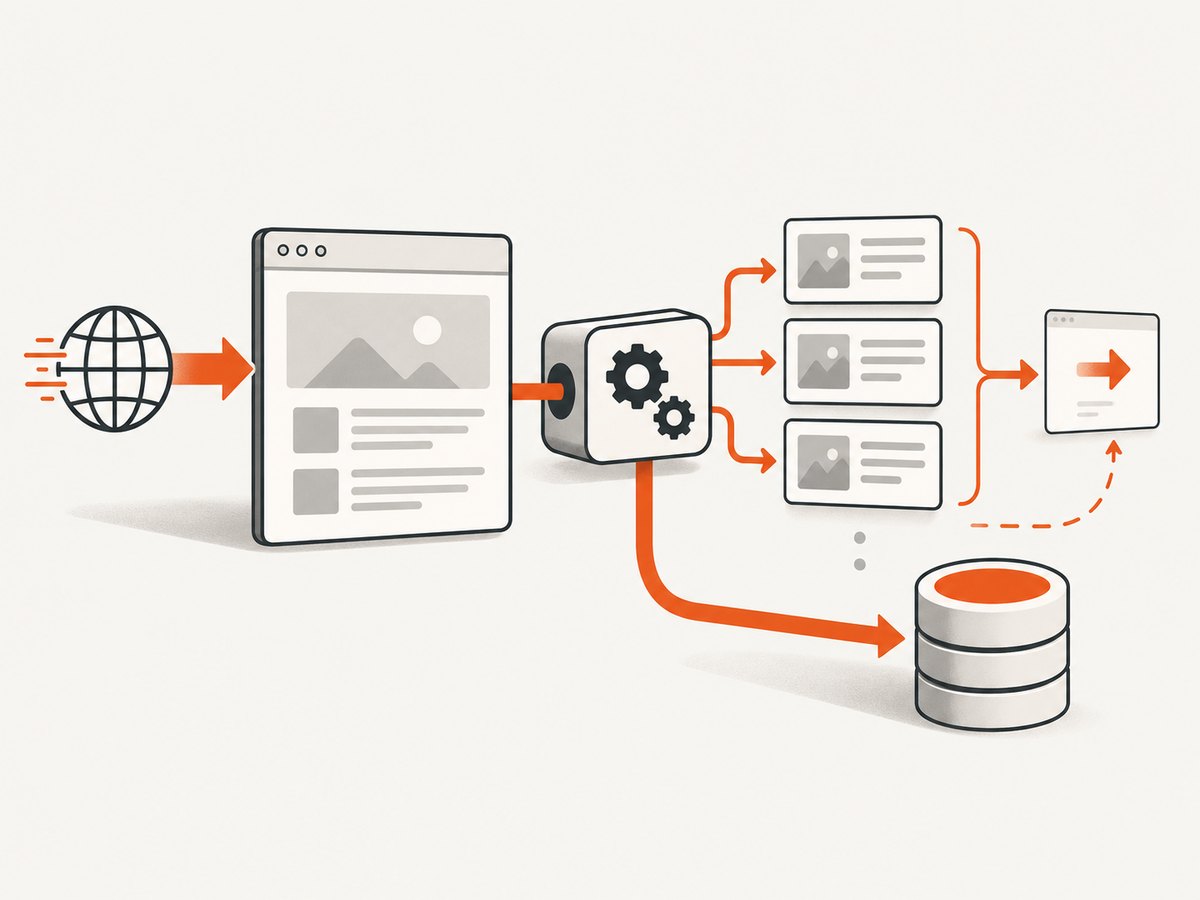
- Find the next destination. Use a rel-next link, a next-text link, or page-number links. Resolve relative values with the response URL.
- Fetch and parse repeatedly. Apply the same record parser to every page. Keep a visited-URL set and a record key for deduplication.
- Stop deliberately. Stop when the next link is absent, invalid, repeated, outside an expected boundary, or when a configured page limit is reached.
- Validate output. Check that records have required fields, that page counts are plausible for your job, and that error responses were not saved as data.
Complete Python scraper
The following script uses requests and BeautifulSoup. Replace the selectors with ones verified against the target HTML. It follows a real next link, resolves relative URLs, retries transient transport errors, rejects HTTP error statuses, detects repeated pages, and writes JSON Lines.
#!/usr/bin/env python3
import json
import time
from urllib.parse import urljoin

import requests
from bs4 import BeautifulSoup
from requests.adapters import HTTPAdapter
from urllib3.util.retry import Retry

START_URL = "https://example.com/catalog"
MAX_PAGES = 100
DELAY_SECONDS = 1.0

session = requests.Session()
retry = Retry(
    total=3,
    connect=3,
    read=3,
    backoff_factor=1,
    status_forcelist=(429, 500, 502, 503, 504),
    allowed_methods=frozenset(["GET"]),
    respect_retry_after_header=True,
)
session.mount("https://", HTTPAdapter(max_retries=retry))
session.mount("http://", HTTPAdapter(max_retries=retry))
session.headers.update({
    "User-Agent": "ExampleResearchBot/1.0 (+https://example.com/contact)"
})

def parse_page(html, page_url):
    soup = BeautifulSoup(html, "html.parser")
    rows = []
    for card in soup.select("article.product-card"):
        link = card.select_one("a.product-card__link[href]")
        name = card.select_one(".product-card__name")
        price = card.select_one(".product-card__price")
        if not link or not name:
            continue
        item_url = urljoin(page_url, link["href"])
        rows.append({
            "name": name.get_text(" ", strip=True),
            "price": price.get_text(" ", strip=True) if price else None,
            "url": item_url,
        })

    next_link = soup.select_one('a[rel="next"][href]')
    if next_link is None:
        for candidate in soup.select("a[href]"):
            label = candidate.get_text(" ", strip=True).casefold()
            if label in {"next", "next page", "›", "→"}:
                next_link = candidate
                break
    next_url = urljoin(page_url, next_link["href"]) if next_link else None
    return rows, next_url

def main():
    current_url = START_URL
    visited_urls = set()
    seen_records = set()
    page_number = 0

    with open("records.jsonl", "w", encoding="utf-8") as output:
        while current_url and page_number < MAX_PAGES:
            if current_url in visited_urls:
                print(f"Stopping: repeated URL {current_url}")
                break
            visited_urls.add(current_url)
            page_number += 1

            response = session.get(current_url, timeout=(10, 45))
            response.raise_for_status()
            if not response.text.strip():
                raise RuntimeError(f"Empty response body at {current_url}")

            rows, next_url = parse_page(response.text, response.url)
            for row in rows:
                key = row["url"] or row["name"]
                if key in seen_records:
                    continue
                seen_records.add(key)
                output.write(json.dumps(row, ensure_ascii=False) + "\n")

            print(f"page={page_number} records={len(rows)} url={response.url}")
            current_url = next_url
            if current_url:
                time.sleep(DELAY_SECONDS)

    print(f"Finished: pages={page_number}, unique_records={len(seen_records)}")

if __name__ == "__main__":
    main()
Install dependencies with python -m pip install requests beautifulsoup4. The retry policy is an example, not a target-site rate recommendation. Tune delays and concurrency only after checking the site’s policies.
Why each safeguard matters
- URL resolution:
urljointurns/catalog?page=2into an absolute URL using the actual response URL, including redirects and subpaths. - Visited URLs: protects against a broken “next” link that points back to an earlier page.
- Record keys: protects against duplicate products appearing on multiple pages or in overlapping result windows.
- Status checks: prevent an error page from being parsed as a valid listing.
- Maximum pages: gives every run a hard upper bound when the target’s markup changes.
Fetching pages with cURL
Use cURL to inspect the first response before coding selectors. -L follows redirects, -D saves headers, and -o saves the body.
curl -L --fail-with-body \
  -A 'ExampleResearchBot/1.0 (+https://example.com/contact)' \
  -D page-1.headers \
  'https://example.com/catalog?page=1' \
  -o page-1.html
Inspect page-1.html for the record container and next link. To test a discovered destination:
curl -L --fail-with-body \
  -A 'ExampleResearchBot/1.0 (+https://example.com/contact)' \
  'https://example.com/catalog?page=2' \
  -o page-2.html
Node.js example
Node 18 or newer includes fetch. This compact example uses Cheerio for HTML parsing and follows a rel-next link.
import * as cheerio from "cheerio";

const startUrl = "https://example.com/catalog";
const seenPages = new Set();
const seenItems = new Set();
let nextUrl = startUrl;
let pageCount = 0;

while (nextUrl && pageCount < 100) {
  if (seenPages.has(nextUrl)) break;
  seenPages.add(nextUrl);
  pageCount += 1;

  const response = await fetch(nextUrl, {
    headers: { "User-Agent": "ExampleResearchBot/1.0" },
    signal: AbortSignal.timeout(45_000)
  });
  if (!response.ok) throw new Error(`${response.status} at ${nextUrl}`);

  const html = await response.text();
  const $ = cheerio.load(html);
  $("article.product-card").each((_, element) => {
    const href = $(element).find("a.product-card__link").attr("href");
    const name = $(element).find(".product-card__name").text().trim();
    if (!href || !name) return;
    const url = new URL(href, response.url).href;
    if (seenItems.has(url)) return;
    seenItems.add(url);
    console.log(JSON.stringify({ name, url }));
  });

  const href = $('a[rel="next"][href]').attr("href");
  nextUrl = href ? new URL(href, response.url).href : null;
}
console.error(`pages=${pageCount} records=${seenItems.size}`);
Install Cheerio with npm install cheerio. Keep the parser independent from pagination so a selector change in one part does not silently disable the other.
Choosing selectors and stopping rules
Selectors
Choose selectors anchored to semantic structure, stable classes, or attributes intended for automation. Avoid selectors based on visual position such as “the third div.” Confirm that the selector matches one record on page one and the same kind of record on a later page. Extract text with whitespace normalization and preserve canonical URLs when available.
Next-link precedence
- Use
link[rel="next"]ora[rel="next"]when present. - Otherwise use a clearly labeled next anchor with an
href. - Use page-number links only when you can define ordering and a visited set.
- Guess a URL pattern only after verifying it against several real links.
Boundaries
Set a maximum page count, maximum record count, or an application-specific date boundary. A missing next link is a normal completion signal; an unchanged page with a new URL is a reason to stop and investigate. Do not infer that page numbers are contiguous unless the HTML demonstrates that behavior.
When the HTML does not contain the records
If a browser displays records that are absent from the ordinary response, static pagination is not the whole data path. Inspect browser network activity and identify the request that supplies the data. Scrapy’s dynamic-content guide recommends reproducing that request; method and URL may be sufficient, but headers, a request body, or form parameters can also matter. A headless browser is an alternative when reproducing the request is impractical.
Do not treat a successful browser request as a successful page. Playwright documents that HTTP error responses such as 404 or 503 can complete at the HTTP-request level; its requestfailed event is for transport failures such as network errors. See the Playwright Request documentation. Your scraper should check both the HTTP status and the response body.
Or skip the browser setup
If you need screenshots of paginated pages for review, archiving, or an AI workflow, ScreenshotNeo provides a single GET request for a clean PNG, JPEG, WebP, or PDF. It accepts the page URL and can handle full-page capture, lazy-loaded images, custom headers, cookies, waiting conditions, blocked resources, and other capture controls. See the ScreenshotNeo API documentation for the complete option list.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com/catalog?page=1 -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://example.com/catalog?page=1"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com/catalog?page=1' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);Cookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and billing result. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Create a free ScreenshotNeo account.
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Zero records | The selector matches browser-rendered content, or the response is an error page. | Print the status and a body sample; inspect raw HTML and network requests. |
| Only page one is collected | The next link uses a different selector, lacks an href, or is disabled. |
Inspect all pagination anchors and check for rel="next" and actual URLs. |
| Infinite loop | Next links repeat or normalize to the same URL. | Track visited absolute URLs and enforce a maximum page count. |
| Duplicate records | Pages overlap, URLs have tracking parameters, or the site repeats featured items. | Canonicalize URLs where appropriate and deduplicate on a stable record key. |
| 403 or 429 | Access policy, authentication, or request rate limits. | Read the site’s policy, slow down, use authorized credentials, and stop if access is not permitted. |
| 404 or 503 saved as data | Request completion was mistaken for a valid page. | Check response.status_code or response.ok before parsing. |
| Relative links fail | The scraper concatenated strings instead of resolving URLs. | Use urljoin in Python or new URL(href, response.url) in Node. |
Performance, reliability, and cost
- Performance: Start with one request at a time. Add bounded concurrency only when the target permits it and your parser is correct. Reuse a session so connections can be reused.
- Reliability: Set connect and read timeouts, retry only transient failures, honor
Retry-Afterwhere available, log final URLs and statuses, and checkpoint output so a stopped run can resume. - Correctness: Keep raw HTML or response metadata for a sample of pages. Compare record counts and required fields across pages to detect template changes.
- Cost: Ordinary HTTP fetching costs your infrastructure’s bandwidth and compute. Browser rendering generally adds operational complexity. ScreenshotNeo bills only clean shots; failed loads, blank pages, bot checks, timeouts, and cache hits are not billed.
Checklist before running at scale
- Have you confirmed the target’s terms, robots.txt, and permitted rate?
- Does the raw response contain both records and pagination links?
- Are relative and absolute URLs resolved against the final response URL?
- Do you check status, content type, and non-empty body?
- Do you have visited-page, duplicate-record, and maximum-page safeguards?
- Can you resume from a checkpoint after a network interruption?
- Have you tested selector behavior on more than one page template?
FAQ
Should I generate ?page=2 myself?
Only when the site’s actual links establish that pattern. An existing href is stronger evidence than a guessed URL format.
Is a headless browser required?
No. For records present in returned HTML, an HTTP client and parser are sufficient. Use browser network inspection or a headless browser when the required data is loaded dynamically.
How do I know I reached the last page?
Use the site’s next-link behavior, then stop when the link is absent or invalid. Also enforce a maximum page boundary and detect repeated URLs.
Can I scrape every website this way?
No. Pagination markup, access controls, policies, and legal requirements vary. Verify the intended site and jurisdiction before collecting data.
What should I store for debugging?
Store the requested URL, final URL, status, timestamp, parser version, and a small sample of raw HTML or headers. This makes selector and pagination changes explainable.


