How to Scrape Yandex Search Results with Python and Node.js
Use Yandex Search API with Python or Node.js, decode XML or HTML responses, handle pagination, authentication, limits, and errors.
Use the documented Yandex Search API when you need programmatic Yandex results. It supports REST, gRPC and the Yandex AI Studio SDK. Python and Node.js can call the REST interface with ordinary HTTP clients, then decode the synchronous response’s Base64 rawData field before parsing XML or HTML. Directly requesting the consumer Yandex results page is a different technique and should not be presented as an endorsed API integration.
This guide shows authentication, complete Python and Node.js examples, cURL, search parameters, XML and HTML handling, deferred operations, result limits, reliability practices and troubleshooting. It also explains where the old Yandex.XML service fits: its published license says it became void on November 1, 2024, so verify the current Search API terms, access requirements and pricing before production use.
1. Choose the supported interface
The current Yandex documentation describes three ways to submit text searches:
- REST: a JSON request over HTTPS. This is the simplest option for Python, Node.js and shell scripts.
- gRPC: useful when your service already uses generated protobuf clients and long-lived connections.
- Yandex AI Studio SDK: convenient when your application already uses the SDK’s authentication and resource abstractions.
The examples below use REST. The request fields use CamelCase; gRPC uses snake_case equivalents. Keep your client focused on the documented API instead of depending on the HTML structure of the public search page. The official documentation warns that response fields can be absent and that response content may change without prior notice. See the Yandex Search API documentation for the current endpoint and schema.
2. Prepare authentication and permissions
Every request must be authenticated. Yandex documents an IAM token in a Bearer authorization header for user or federated accounts. A service account can use an IAM token or an API key in the Authorization header. The identity needs the search-api.webSearch.user role.
User and federated-account requests must include a folder ID. A service-account request can use the service account’s own folder. Store tokens, API keys and folder IDs in environment variables or a secret manager; never commit them to source control.
export YANDEX_TOKEN='your-iam-token-or-api-key'
export YANDEX_FOLDER_ID='your-folder-id'
export YANDEX_SEARCH_URL='https://searchapi.api.cloud.yandex.net/v2/web/search'
Check the current authentication requirements in the Yandex authentication documentation. If the endpoint or credential type shown in your cloud console differs, use the current value from that documentation rather than copying an old blog post.
3. Make a search request with cURL
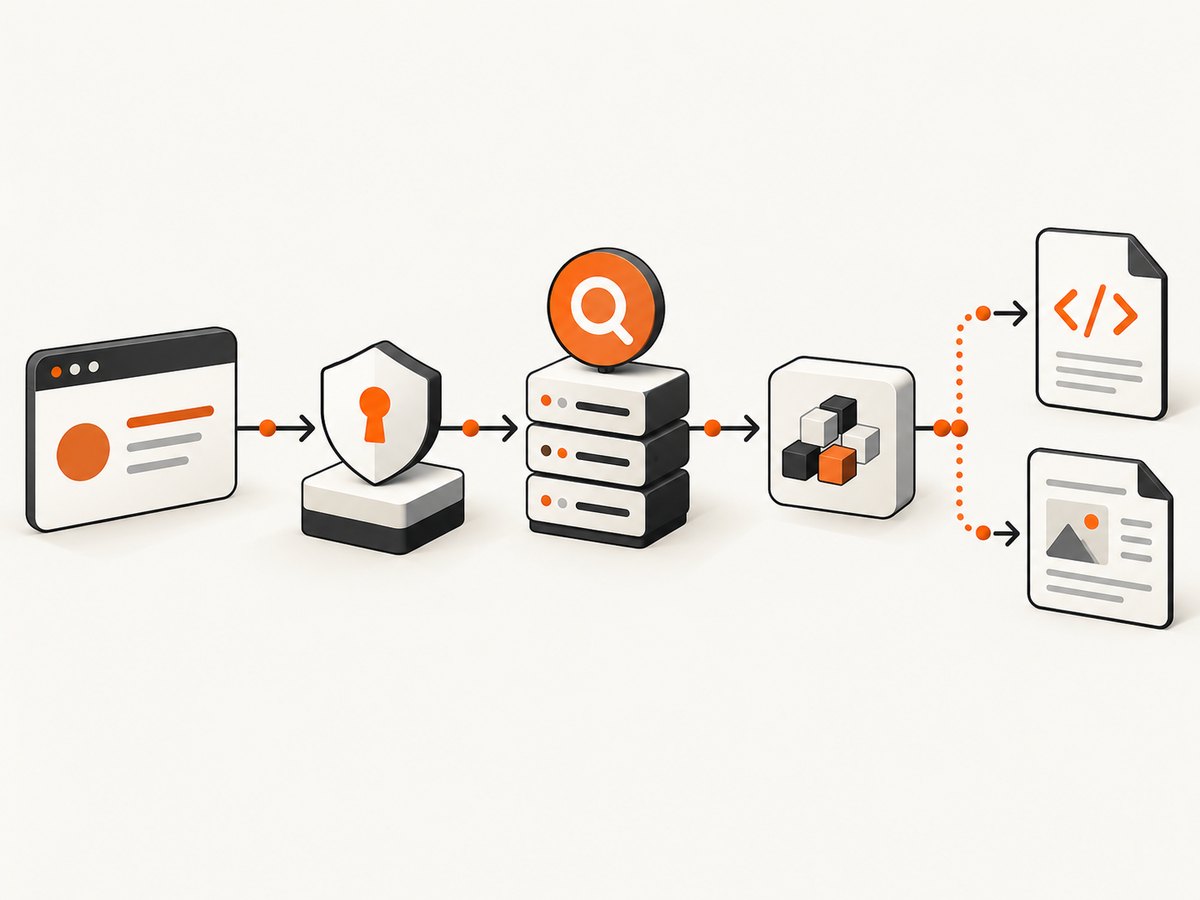
A REST request is a JSON POST. This example asks for Russian web results, enables family filtering, requests ten results per page and asks for XML.
curl -sS "$YANDEX_SEARCH_URL" \
  -H "Authorization: Bearer $YANDEX_TOKEN" \
  -H "Content-Type: application/json" \
  --data @- <<JSON
{
  "folderId": "$YANDEX_FOLDER_ID",
  "queryText": "site:example.com developer documentation",
  "searchType": "SEARCH_TYPE_RU",
  "familyMode": "FAMILY_MODE_MODERATE",
  "page": 0,
  "fixTypoMode": "FIX_TYPO_MODE_ON",
  "sortMode": "SORT_MODE_BY_RELEVANCE",
  "sortOrder": "SORT_ORDER_DESC",
  "groupMode": "GROUP_MODE_FLAT",
  "groupsOnPage": 10,
  "docsInGroup": 1,
  "region": "213",
  "l10n": "LOCALIZATION_RU",
  "responseFormat": "FORMAT_XML"
}
JSON
Names for enum values can vary with the API version. Treat the schema in the current documentation as authoritative. The important concepts are the same: query text, search type, family mode, ranking and sort, grouping, region, localization, response format and page.
4. Python implementation
The following script uses requests, checks the HTTP status, decodes Base64 rawData when present and writes the returned document to disk. Install the dependency with python -m pip install requests.
import base64
import json
import os
from pathlib import Path

import requests

endpoint = os.environ.get(
    "YANDEX_SEARCH_URL",
    "https://searchapi.api.cloud.yandex.net/v2/web/search",
)
token = os.environ["YANDEX_TOKEN"]
folder_id = os.environ["YANDEX_FOLDER_ID"]

payload = {
    "folderId": folder_id,
    "queryText": "site:example.com developer documentation",
    "searchType": "SEARCH_TYPE_RU",
    "familyMode": "FAMILY_MODE_MODERATE",
    "page": 0,
    "fixTypoMode": "FIX_TYPO_MODE_ON",
    "sortMode": "SORT_MODE_BY_RELEVANCE",
    "sortOrder": "SORT_ORDER_DESC",
    "groupMode": "GROUP_MODE_FLAT",
    "groupsOnPage": 10,
    "docsInGroup": 1,
    "region": "213",
    "l10n": "LOCALIZATION_RU",
    "responseFormat": "FORMAT_XML",
}

response = requests.post(
    endpoint,
    headers={
        "Authorization": f"Bearer {token}",
        "Content-Type": "application/json",
    },
    json=payload,
    timeout=60,
)
response.raise_for_status()
data = response.json()

raw_data = data.get("rawData")
if raw_data:
    document = base64.b64decode(raw_data)
    Path("yandex-results.xml").write_bytes(document)
    print("Wrote", len(document), "bytes to yandex-results.xml")
else:
    print(json.dumps(data, ensure_ascii=False, indent=2))
queryText is limited to 400 characters. Validate that limit before sending user input, and reject or shorten overlong queries with a useful message. Do not assume a successful HTTP response always contains every result field: inspect optional fields with dict.get(), and preserve the raw document for later parser updates.
5. Node.js implementation
Node.js 18 or newer includes fetch. This example uses the same REST payload, decodes rawData and saves the document. It does not require an external package.
import { writeFile } from 'node:fs/promises';

const endpoint = process.env.YANDEX_SEARCH_URL ??
  'https://searchapi.api.cloud.yandex.net/v2/web/search';
const token = process.env.YANDEX_TOKEN;
const folderId = process.env.YANDEX_FOLDER_ID;

if (!token || !folderId) {
  throw new Error('Set YANDEX_TOKEN and YANDEX_FOLDER_ID');
}

const payload = {
  folderId,
  queryText: 'site:example.com developer documentation',
  searchType: 'SEARCH_TYPE_RU',
  familyMode: 'FAMILY_MODE_MODERATE',
  page: 0,
  fixTypoMode: 'FIX_TYPO_MODE_ON',
  sortMode: 'SORT_MODE_BY_RELEVANCE',
  sortOrder: 'SORT_ORDER_DESC',
  groupMode: 'GROUP_MODE_FLAT',
  groupsOnPage: 10,
  docsInGroup: 1,
  region: '213',
  l10n: 'LOCALIZATION_RU',
  responseFormat: 'FORMAT_XML',
};

const response = await fetch(endpoint, {
  method: 'POST',
  headers: {
    Authorization: `Bearer ${token}`,
    'Content-Type': 'application/json',
  },
  body: JSON.stringify(payload),
});

if (!response.ok) {
  throw new Error(`Yandex returned ${response.status}: ${await response.text()}`);
}

const data = await response.json();
if (data.rawData) {
  const document = Buffer.from(data.rawData, 'base64');
  await writeFile('yandex-results.xml', document);
  console.log(`Wrote ${document.length} bytes`);
} else {
  console.log(JSON.stringify(data, null, 2));
}
6. Select XML or HTML deliberately
XML is UTF-8 by default and is usually the easier format for a stable parser. HTML can include ads, quick responses and other page elements. Choose HTML when your application specifically needs those elements; do not assume XML and HTML have identical structures or fields.
For synchronous requests, the service places the XML or HTML document in Base64-encoded rawData. Decode it as bytes, then parse it using an XML or HTML parser. Avoid regular expressions for nested markup. Treat titles, snippets, links and metadata as optional because the API documentation allows fields to be missing.
7. Configure search behavior
| Option | What it controls | Implementation note |
|---|---|---|
searchType |
Search geography and language, including Russian, Turkish, international, Kazakh, Belarusian and Uzbek types. | Choose this explicitly so results are reproducible. |
queryText |
The text query, up to 400 characters. | Validate length and normalize user input. |
familyMode |
Family-content filtering. | Pick the policy required by your application. |
page |
The result page. | Use bounded pagination; do not promise an unlimited stable snapshot. |
fixTypoMode |
Whether spelling corrections are applied. | Record the setting when comparing runs. |
sortMode and sortOrder |
Ranking and direction. | Relevance is generally preferable for user-facing search. |
groupMode, groupsOnPage, docsInGroup |
Grouping and the number of documents returned. | Valid ranges differ between XML and HTML. |
region |
Regional targeting. | Supported for Russian and Turkish search types. |
l10n |
Localization of the response. | Keep it aligned with the selected search type. |
responseFormat |
XML or HTML output. | Decode rawData before parsing. |
resultsWithin |
Time window for results where supported. | Confirm accepted values in the current schema. |
The documented maximum is 250 results per query. More pages do not guarantee an unlimited or immutable result set: rankings, indexing and response content can change between requests.
8. Synchronous and deferred searches
Synchronous mode is convenient for an interactive request that can wait for the response. Deferred mode returns an operation object instead. Save the operation ID, poll or track it, and read the response only after done becomes true. Use deferred processing for batch workloads, long-running jobs or a queue-based worker system.
For either mode, add an application request ID to your logs, record the query settings and keep the original response. This makes parser failures and ranking changes diagnosable without exposing credentials.
9. Reliability, performance and cost practices
- Reuse connections: use a persistent HTTP session in Python or an HTTP agent in Node.js for batches.
- Bound timeouts: set connect and read timeouts; retry only transient network failures and selected 5xx responses.
- Back off: use exponential backoff with jitter and a maximum retry count. Do not retry authentication or validation errors.
- Throttle concurrency: cap workers to the quota and rate limits attached to your cloud account.
- Cache carefully: cache identical queries only when stale results are acceptable, and include search settings in the cache key.
- Parse defensively: accept missing nodes, unknown enum values and additional fields.
- Measure payload size: HTML with ads and quick responses can be larger than XML. Stream or limit storage for high-volume jobs.
- Budget from current pricing: the supplied documentation establishes technical limits, not a universal price. Check your account’s current Search API pricing before estimating cost.
10. Common errors and fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| 401 or 403 | Expired token, wrong Authorization scheme or missing role. | Renew the IAM token or API key, send Authorization: Bearer ... where required, and assign search-api.webSearch.user. |
| Folder or resource error | Missing or incorrect folderId. |
Use the folder associated with the user or service account and include it in the request. |
| 400 validation error | Invalid enum, unsupported region/search-type combination or overlong query. | Compare every field with the current schema, keep queryText within 400 characters and use region only where supported. |
| Empty result fields | Optional fields are absent or the selected format has a different structure. | Use null-safe parsing and inspect the raw decoded document. |
| Parser sees unreadable characters | rawData was treated as plain text instead of Base64. |
Base64-decode first, then parse UTF-8 XML or HTML. |
| 429 or intermittent 5xx | Quota, throttling or a transient service/network failure. | Reduce concurrency, apply bounded exponential backoff and inspect quota metrics. |
| Results differ between runs | Ranking, indexing, region, localization or response content changed. | Log all search settings and avoid treating pagination as a permanent snapshot. |
11. Why direct SERP HTML scraping is a different method
People often use “scrape” to mean any automated extraction. An API client retrieves results through a documented service interface; a scraper downloads and interprets the public consumer SERP page. The old Yandex.XML license page describes automated requests by other means as prohibited without pre-approval, while also stating that the license became void on November 1, 2024. It is therefore historical caution, not a current contract. Check the current Search API terms before production automation. Yandex Webmaster’s robots.txt guidance concerns how site owners instruct crawlers about their own sites; it is not permission to automate requests to Yandex Search.
12. Or skip the browser setup
If your actual task is capturing a rendered Yandex results page or another URL for review, documentation or an AI workflow, ScreenshotNeo provides a one-call screenshot API and MCP server. It accepts cookie and consent banners as a visitor, removes more than 60 known consent platforms plus newsletter popups and chat widgets before capture, and lets you turn each step off. Bot checks, blank pages, timeouts, failed loads and cache hits cost nothing; response headers identify the page verdict and whether the shot was billed.
See the ScreenshotNeo API documentation for all options, including full-page lazy-image loading, CSS element capture, device presets, dark mode, custom CSS and JavaScript, waits, request blocking, headers, cookies, user agents, geolocation, PDFs, caching, signed links, async jobs, bulk capture and usage reporting.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://yandex.com -o shot.webpimport requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://yandex.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://yandex.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo also includes an MCP server with take_screenshot, get_page_info and capture_pdf tools for Claude, Cursor and other MCP clients. The free plan includes 1,000 screenshots each month with no card; paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
13. Checklist for production
- Confirm the current Search API endpoint, terms, quota and pricing.
- Create credentials and assign
search-api.webSearch.user. - Store secrets outside source code.
- Choose search type, region, localization and family mode intentionally.
- Validate the 400-character query limit.
- Decode Base64
rawDatabefore parsing. - Handle missing fields and changing response structure.
- Cap pagination at the 250-result documented maximum.
- Add timeouts, bounded retries, backoff and concurrency limits.
- Log settings and request IDs without logging credentials.
FAQ
Is this the same as scraping the Yandex consumer results page?
No. These examples call the documented Yandex Search API. Consumer-page HTML scraping is a separate method with different terms and maintenance risks.
Can I request more than 250 results?
The documented maximum is 250 results per query. Treat that as a hard application limit and design a separate query strategy when you need broader coverage.
Should I use XML or HTML?
Use XML for structured parsing. Use HTML when you specifically need ads, quick responses or other page elements, and write a parser for that format.
Why does my parser receive Base64?
Synchronous responses put the XML or HTML document in rawData. Decode it before interpreting the bytes as UTF-8 markup.
When should I use deferred mode?
Use it for batch or long-running work where a worker can poll an operation until done is true.


