Scraping Single-Page Applications with Playwright
Scrape SPA content reliably with Playwright: wait for the page state you need, extract from the rendered DOM, and handle dynamic lists and route changes.
To scrape a single-page application (SPA) with Playwright, navigate to the route, wait for a specific piece of content to appear or reach a known state, then read it from the rendered DOM. A document event such as load tells you about the document lifecycle; it does not guarantee that client-side requests and rendering have finished. Likewise, a fixed sleep can be too short on a slow run and waste time on a fast one.
The reliable pattern is: navigate → wait for evidence the data you need is ready → extract with locators. This guide uses Python and Playwright’s synchronous API, then shows JavaScript, dynamic lists, route changes, browser-side evaluation, troubleshooting, and a one-call screenshot alternative. Playwright’s API details are documented in its Page API, Locator API, and evaluation guide.
1. Install Playwright and prepare a browser
Install Playwright and its Chromium browser. The browser installation is a separate step because Playwright needs a browser binary to launch.
python -m pip install playwright
python -m playwright install chromium
Save the following as scrape_spa.py. Replace the example URL and selectors with those of a site you are allowed to access. The example waits for a product card to become visible, then extracts its text and link. It also writes the records as JSON.
import asyncio
import json
from playwright.async_api import async_playwright

URL = "https://example.com/catalog"
CARD = "article.product-card"

async def main():
    async with async_playwright() as p:
        browser = await p.chromium.launch(headless=True)
        page = await browser.new_page()
        response = await page.goto(URL, wait_until="domcontentloaded", timeout=30_000)

        if response and not response.ok:
            raise RuntimeError(f"Navigation returned HTTP {response.status}")

        cards = page.locator(CARD)
        await cards.first.wait_for(state="visible", timeout=15_000)

        # Read current DOM state after the meaningful readiness check.
        count = await cards.count()
        rows = []
        for i in range(count):
            card = cards.nth(i)
            title = (await card.locator(".product-title").inner_text()).strip()
            href = await card.locator("a").get_attribute("href")
            rows.append({"title": title, "url": href})

        with open("products.json", "w", encoding="utf-8") as f:
            json.dump(rows, f, ensure_ascii=False, indent=2)
        await browser.close()

asyncio.run(main())
Run it with python scrape_spa.py. The selector names are examples, not universal selectors. Inspect the target page’s rendered DOM and choose a stable, specific locator. If the target’s application displays a result count, loading status, or empty-state message, that state may provide a better readiness condition than the first card.
2. Wait for the content, not just navigation
page.goto() can wait for document lifecycle milestones. domcontentloaded means the initial document has been parsed; load waits for the document’s load event and dependent resources. An SPA may still be fetching data or rendering components after either event. Follow navigation with a check tied to what the scraper needs.
| Wait condition | What it tells you | Use it for |
|---|---|---|
domcontentloaded |
The initial document was parsed. | A quick navigation milestone, followed by a content check. |
load |
The document load event fired. | Pages where load-dependent resources matter; still verify SPA content. |
| Locator state | A relevant element reached a state such as visible. | Waiting for a known result, heading, or status. |
| Application condition | A particular count or text became correct. | Pages with a meaningful “loaded” state or known result target. |
networkidle |
No network connections for at least 500 ms. | Not a general readiness guarantee; Playwright discourages using it as one. |
For example, wait for a status to change from “Loading” to a result state:
status = page.locator("[role=status]")
await status.wait_for(state="visible")
await page.get_by_text("Loading", exact=True).wait_for(state="hidden", timeout=15_000)
await page.locator("article.product-card").first.wait_for(state="visible")
Use conditions the page actually exposes. A hidden loading label is only useful if the application removes or hides it when the relevant data is ready. If the page can legitimately return zero results, wait for either cards or the empty-state message rather than waiting forever for a card.
3. Extract rendered content with locators
Locators are designed to retry and auto-wait for actions and assertions. They resolve against the current page state, which helps when a component is replaced during a re-render. Prefer role, label, text, or a stable test attribute when available; use CSS selectors when they are the clearest option.
cards = page.locator("article.product-card")
await cards.first.wait_for(state="visible")

for i in range(await cards.count()):
    card = cards.nth(i)
    title = await card.locator(".product-title").inner_text()
    price = await card.locator("[data-price]").get_attribute("data-price")
    print(title.strip(), price)
Use inner_text() for user-visible text and text_content() when you need text content without the same visibility-oriented behavior. Use get_attribute() for attributes such as href and data-id. Normalize whitespace and validate values before storing them; a page can contain placeholders or partially populated cards during rendering.
Dynamic lists need a readiness condition
locator.all() returns elements present immediately; it does not wait for a changing list to finish populating. First wait for an application-specific condition. If the page reports a total, compare the rendered number against it. If it paginates, extract a page at a time and follow the application’s next-page control.
cards = page.locator("article.product-card")
await page.get_by_text("24 results", exact=True).wait_for(state="visible")
await cards.first.wait_for(state="visible")

# Snapshot the currently available matching locators only after readiness.
items = await cards.all()
rows = []
for item in items:
    rows.append({"title": (await item.locator(".product-title").inner_text()).strip()})
If the result total is variable, read the count from the page and wait until the rendered card count matches it, or wait for an explicit completion indicator. Avoid assuming that one visible card means every card has arrived.
4. Handle SPA route changes and browser-side extraction
Some navigation is client-side: clicking a link changes the URL without loading a new document. When the URL transition matters, synchronize with it using wait_for_url(), then wait for the target route’s content. The URL change alone does not prove that rendering is complete.
await page.get_by_role("link", name="Next category").click()
await page.wait_for_url("**/category/next")
await page.get_by_role("heading", name="Next category").wait_for(state="visible")
await page.locator("article.product-card").first.wait_for(state="visible")
For a DOM transformation that is easier to express in the page, use evaluate(). Its callback runs in the browser page context, separate from your Python process; browser globals such as document are available there. Return serializable values, and pass inputs explicitly instead of expecting Python variables to exist in the page.
records = await page.locator("article.product-card").evaluate_all("""cards => cards.map(card => ({
  title: card.querySelector('.product-title')?.textContent?.trim() ?? '',
  href: card.querySelector('a')?.href ?? null
}))""")
Use locator methods for straightforward extraction because they make the target and operation easy to inspect. Use page-side evaluation when processing a collection in one browser operation is materially simpler. Do not return DOM nodes or functions; return JSON-compatible values such as strings, numbers, arrays, and objects.
5. Practical edge cases
- Empty result: Wait for either the result list or the empty-state element, then record which occurred.
- Lazy-loaded content: Scroll the relevant container or page and wait for new items to appear. A full list may not exist in the DOM until it is brought into view.
- Infinite scrolling: Repeat scroll, wait, and count checks until the count stops increasing or the site signals completion. Set a maximum page or item limit to avoid an unbounded run.
- Re-render during extraction: Keep using locators resolved at the time of reading. If elements can disappear between fields, retry the card as a unit or wait for a stable state.
- Locale-dependent values: Preserve the raw text and parse it with an explicit locale rule; commas and decimal points vary.
- Frames: Content inside an iframe belongs to that frame. Locate the frame and query within it rather than searching the main page.
- Consent overlays: They may obscure controls or content. Follow the site’s consent behavior and access rules; do not assume an overlay’s presence means the underlying content is ready.
6. JavaScript version
The same wait-for-content pattern works with Playwright’s Node.js library. Install the package and Chromium, save as scrape.mjs, and run with Node.js. Replace the URL and selectors as in the Python example.
import { chromium } from 'playwright';
import { writeFile } from 'node:fs/promises';

const browser = await chromium.launch({ headless: true });
try {
  const page = await browser.newPage();
  const response = await page.goto('https://example.com/catalog', {
    waitUntil: 'domcontentloaded',
    timeout: 30_000,
  });
  if (response && !response.ok()) {
    throw new Error(`Navigation returned HTTP ${response.status()}`);
  }

  const cards = page.locator('article.product-card');
  await cards.first().waitFor({ state: 'visible', timeout: 15_000 });
  const rows = await cards.evaluateAll(nodes => nodes.map(card => ({
    title: card.querySelector('.product-title')?.textContent?.trim() ?? '',
    url: card.querySelector('a')?.href ?? null,
  })));
  await writeFile('products.json', JSON.stringify(rows, null, 2));
} finally {
  await browser.close();
}
7. Or skip the browser setup
If your goal is a visual snapshot of a page rather than structured extraction from its DOM, a screenshot API can return the rendered page without you managing a browser. ScreenshotNeo is a website screenshot API and MCP server. Its one-call API returns PNG, JPEG, WebP, or PDF; see the API documentation for options.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com/catalog -o shot.webpPython:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://example.com/catalog"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com/catalog' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
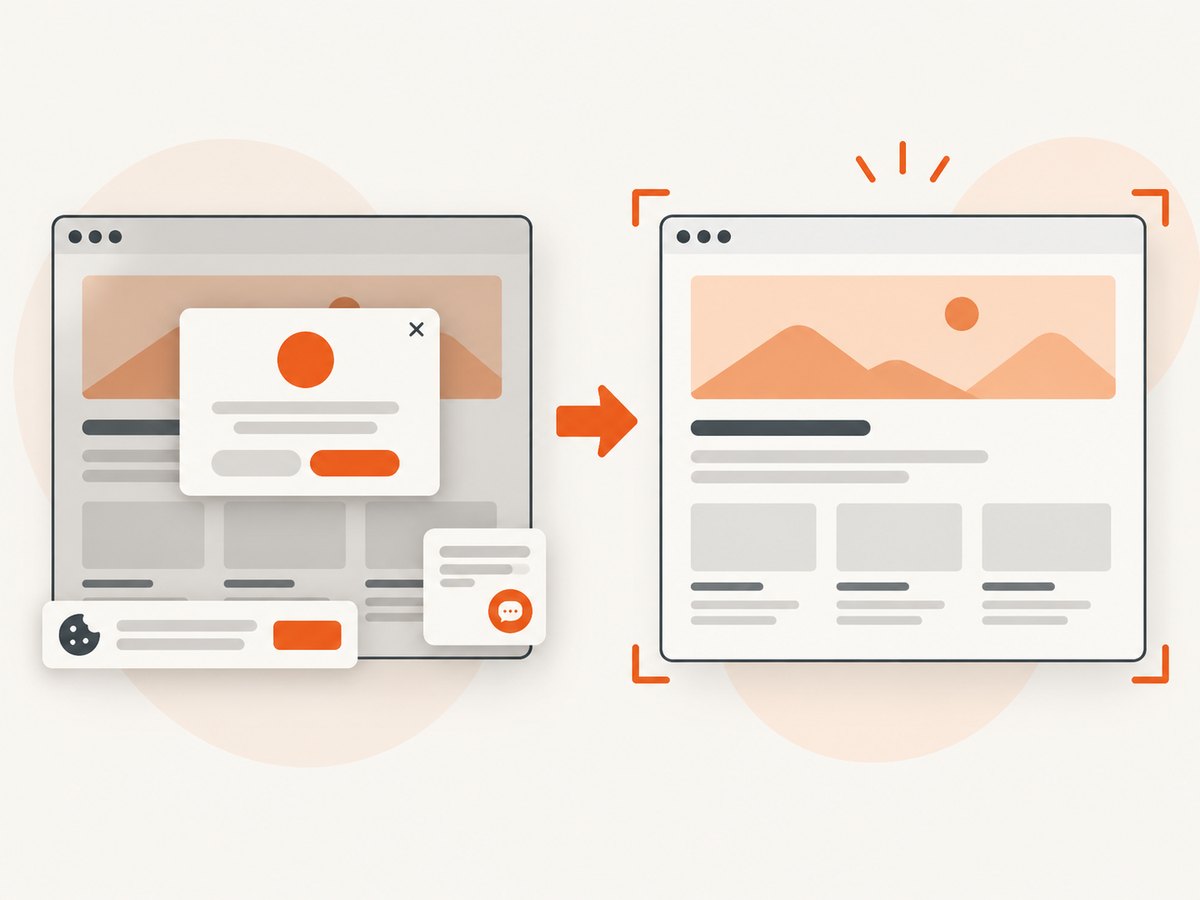
Cookie banners are accepted and removed before the shot, along with known newsletter popups and chat widgets. Bot checks, blank pages, and failed loads are never billed; response headers say whether a page was clean and billed. Its MCP server lets AI agents use take_screenshot, get_page_info, and capture_pdf. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000. Screenshots are visual output, not a substitute for querying page data with Playwright locators. Sign up for 1,000 free screenshots a month, no card required.
8. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Empty text or no cards | Extraction ran after document navigation but before client rendering. | Wait for a meaningful locator, result status, or count, then read the current DOM. |
| Timeout waiting for a selector | The selector is wrong, the state never occurs, or the page returned an error/empty result. | Inspect the rendered DOM and URL; wait for either results or the empty state; raise the timeout only when the site’s expected behavior justifies it. |
| Intermittent missing list items | The list is still loading or virtualized, or all() ran too early. |
Wait for a known total or completion signal. For virtualized lists, scroll and collect in batches as items render. |
| Wrong route or stale data | A client-side click changed state asynchronously. | Wait for the expected URL when applicable and then wait for the new route’s identifying content. |
Navigation response is null |
Some navigations, including client-side transitions, do not produce a new document response. | Do not treat a missing response as proof of failure; verify URL and page content. |
| Browser executable missing | The Playwright package is installed but its browser binary is not. | Run python -m playwright install chromium (or the matching install command for your runtime). |
| Different values between runs | Content depends on account, locale, geolocation, time, or changing inventory. | Set an intentional context locale/timezone where appropriate, record capture time, and make parsing tolerant of valid variants. |
| Blocked or challenged page | The site may reject automation or require authorization. | Check the site’s access rules and use authorized credentials or an approved data interface. Do not treat a challenge page as target content. |
9. Performance, reliability, and cost
Browser rendering costs more time and resources than reading a static response because it launches a browser and executes page code. Reuse a browser process across pages in a batch, while creating an appropriate context for each isolated session. Extract only the fields needed, avoid waiting for unrelated assets, and use a content condition so a fast page does not pay an unnecessary fixed delay.
Set explicit navigation and locator timeouts, handle failed navigation and empty states separately, and close the browser in a finally block. For repeated jobs, log the URL, time, observed status, item count, and failure reason; retries should be bounded and should not duplicate downstream writes. Avoid aggressive concurrency against the target. Respect its terms, robots guidance where applicable, authentication requirements, and rate limits.
Playwright itself is an open-source automation library; operational cost comes from the machine, browser time, network, and any infrastructure or proxy service you choose. This workflow makes no performance guarantee: page complexity and the target’s response vary. A screenshot API can be simpler for image or PDF output, but it does not provide the same DOM-level extraction workflow as locators.
10. FAQ
How do I wait for a page to finish rendering in Playwright?
There is no universal “finished” event for an SPA. Wait for a locator, status, result count, or other observable condition that represents the data you need.
Why does Playwright return empty content from a SPA?
The script may read the page before the client-side request and render complete, or it may query the wrong route, frame, or selector. Verify the current page state and wait for target content.
Should I use networkidle?
Not as a blanket readiness test. Playwright defines it as at least 500 ms without network connections and discourages it as a general signal; applications can be ready before or after that quiet period.
Can I use Playwright for any website?
Technical access does not establish permission. Check the target site’s terms, access rules, and rate limits before automating extraction.


