How to Take a Screenshot of a Specific DOM Element Using Ruby
Capture one DOM element in Ruby with Selenium, Ferrum, Cuprite, or Playwright, including selectors, waits, sizing, troubleshooting, and an API option.
To screenshot one DOM element in Ruby, use a browser API that understands elements instead of capturing the viewport and cropping pixels afterward. Selenium can find a node and call save_screenshot. Ferrum accepts a CSS selector directly. Cuprite exposes the underlying Ferrum browser when you use Capybara. Playwright Ruby provides locator.screenshot, with built-in waiting, scrolling, animation control, and timeout options.
The shortest Selenium example is:
require 'selenium-webdriver'

driver = Selenium::WebDriver.for :chrome
begin
  driver.get 'https://example.com/'
  element = driver.find_element(:css, 'h1')
  element.save_screenshot('./image.png')
ensure
  driver.quit
end
Replace h1 with an ID, class, attribute selector, XPath, or another locator supported by the Ruby binding. The WebDriver screenshot contract captures the element content or its visible portion, depending on the conformant browser driver.
Which Ruby library should you choose?
| Situation | Recommended approach | Why |
|---|---|---|
| An existing Selenium test suite | Selenium | Find the element and save its screenshot with minimal architectural change. |
| Direct Ruby control of Chrome | Ferrum | A selector can be passed directly to browser.screenshot, alongside format, scale, area, and background options. |
| Capybara already uses Cuprite | Cuprite plus Ferrum | Use the driver’s underlying Ferrum browser for selector screenshots. |
| Locator-rich automation or visual testing | Playwright Ruby | locator.screenshot waits for actionability, scrolls the element into view, and supports animation, style, scale, and timeout controls. |
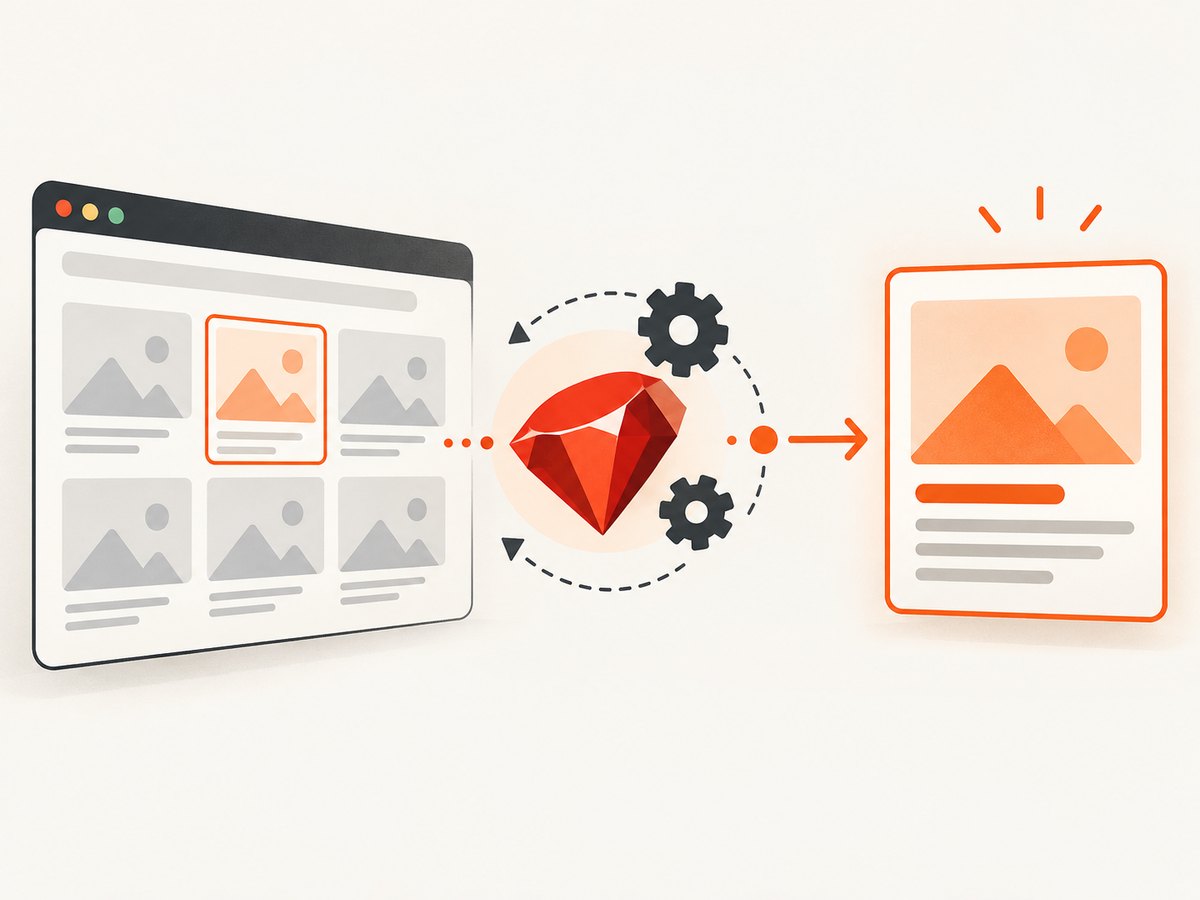
1. Capture an element with Selenium Ruby
Selenium’s Ruby API follows the WebDriver screenshot behavior documented by Selenium. The element must be found after navigation, and the output directory must already exist.
require 'selenium-webdriver'

FileUtils.mkdir_p('tmp/screenshots')
driver = Selenium::WebDriver.for :chrome
begin
  driver.get 'https://example.com/'
  heading = driver.find_element(:css, 'h1')
  heading.save_screenshot('tmp/screenshots/heading.png')
ensure
  driver.quit
end
Add require 'fileutils' if you use FileUtils.mkdir_p. For a product card, use '.product-card'. For a data attribute, use '[data-testid="price"]'. XPath is also available:
element = driver.find_element(:xpath, '//article[@data-testid="product"]')
element.save_screenshot('tmp/screenshots/product.png')
Selenium’s element capture may represent only the visible portion when the node extends beyond the viewport. If you need a complete long element, scroll it into view first or use a library with explicit full-page or area controls.
2. Capture by selector with Ferrum
Ferrum is a Ruby browser client built around Chrome DevTools Protocol. Its screenshot method accepts a CSS selector, so you do not need to retrieve a Selenium-style element object.
require 'ferrum'

browser = Ferrum::Browser.new
begin
  browser.go_to('https://example.com/')
  browser.screenshot(path: 'heading.png', selector: 'h1')
ensure
  browser.quit
end
Ferrum screenshot options include:
selector:— capture the node matching a CSS selector.format:—pngorjpeg.encoding:—binaryorbase64.full:— capture the full page when you are not restricting the shot to one element.area:— capture a specific rectangle.scale:— control output scaling.background_color:— set the background used for the capture.
browser.screenshot(
  path: 'tmp/card.jpg',
  selector: '.product-card',
  format: :jpeg,
  scale: 2,
  background_color: '#ffffff'
)
Use a selector that matches exactly one stable node. If a page contains several matching cards, refine the selector with a parent, ID, or data attribute.
3. Use Cuprite through Capybara
Cuprite is a pure Ruby Capybara driver backed by Ferrum. It is useful when your application tests already use Capybara’s page object. The Cuprite project documents the Ferrum-backed architecture; browser operations can be reached through the driver handle.
require 'capybara/dsl'
require 'capybara/cuprite'

Capybara.configure do |config|
  config.default_driver = :cuprite
end

Capybara.visit('https://example.com/')
page.driver.browser.screenshot(
  path: 'tmp/card.png',
  selector: '.product-card'
)
In a normal Capybara test, wait for the page condition before accessing the browser:
visit('/catalog')
assert_selector('.product-card')
page.driver.browser.screenshot(path: 'tmp/card.png', selector: '.product-card')
Keep the screenshot call close to the assertion. That makes a missing selector fail at the point where the page state is known, rather than producing a confusing browser error later.
4. Use Playwright Ruby locators
Playwright Ruby’s Locator#screenshot is designed for element screenshots. It waits for actionability, scrolls the element into view, and clips the output to the matched node. The API is documented in the Playwright Locator reference.
require 'playwright'

Playwright.create(playwright_cli_executable_path: 'npx playwright') do |playwright|
  playwright.chromium.launch(headless: true) do |browser|
    page = browser.new_page
    page.goto('https://example.com/')
    locator = page.locator('.product-card')
    locator.screenshot(path: 'tmp/card.png', type: 'png', animations: 'disabled')
  end
end
Useful options include:
path:— destination filename.type:—pngorjpeg.quality:— JPEG quality.scale:— device-pixel scaling.style:— extra CSS applied during capture.animations:— control or disable animations for repeatable output.timeout:— maximum wait for the locator and screenshot operation.
locator.screenshot(
  path: 'tmp/stable-card.png',
  type: 'png',
  scale: 'css',
  animations: 'disabled',
  style: '.carousel, .cursor { visibility: hidden !important; }',
  timeout: 15_000
)
A detached node causes the screenshot call to fail. Keep a locator rather than an old element handle and reacquire it after a framework replaces the DOM.
Selectors that survive page changes
The selector is the most common source of flaky element screenshots. Prefer a stable ID or test attribute over a generated class name.
| Selector | Example | Use when |
|---|---|---|
| ID | #invoice-total |
The page gives the element a unique semantic ID. |
| Data attribute | [data-testid="invoice"] |
You control the markup or test hooks. |
| Class | .product-card |
The class is stable and uniquely scoped. |
| Descendant | main article[data-id="42"] |
A short selector needs a stable parent. |
| XPath | //button[@aria-label="Download"] |
You need an attribute or text relationship unavailable in a simple CSS selector. |
When multiple nodes match, make the locator specific. A broad selector can capture the first matching element in one run and a different element after a content change.
Waiting, visibility, and layout control
- Wait for existence. Use Capybara’s
assert_selector, Playwright’s locator waiting, or an explicit Selenium wait before capturing. - Wait for the final state. A node can exist before its text, image, or chart has rendered. Wait for a child selector, a loading class to disappear, or a known application condition.
- Scroll before capture. Playwright does this as part of locator screenshots. With Selenium, call
driver.execute_script('arguments[0].scrollIntoView({block: "center"})', element)when needed. - Control animations. Disable CSS transitions or use Playwright’s
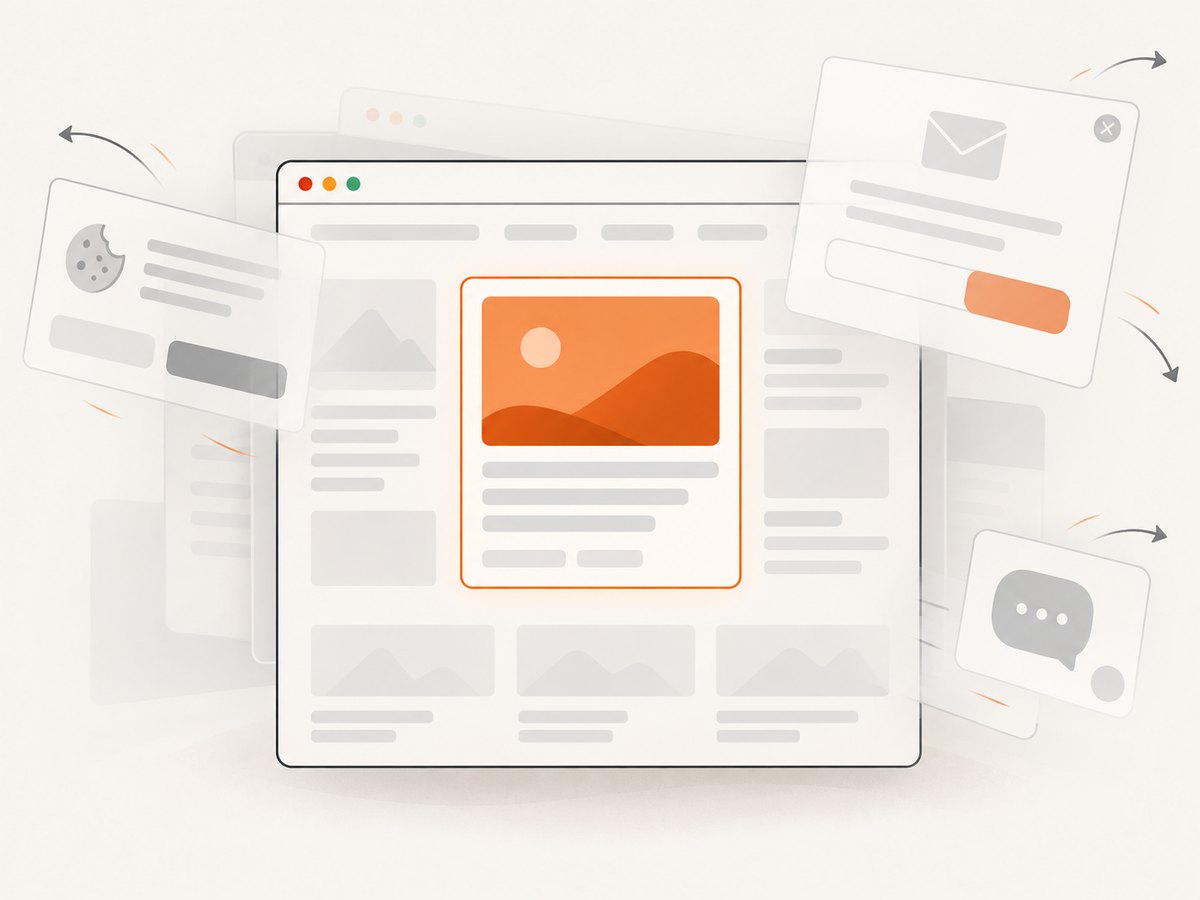
animations: 'disabled'for stable visual output. - Check overlays. A cookie banner, modal, sticky header, or chat widget can cover the target. The element may technically exist while the visible screenshot shows the overlay.
- Handle lazy content. Scroll the target into view and wait for its image or canvas to finish loading before capture.
wait = Selenium::WebDriver::Wait.new(timeout: 15)
element = wait.until do
  candidate = driver.find_element(:css, '[data-testid="chart"]')
  candidate if candidate.displayed? && candidate.size.width > 0
end
element.save_screenshot('tmp/chart.png')
Output size, format, and repeatability
PNG is lossless and usually best for UI comparisons, text, and transparent areas. JPEG is smaller for photographic content but introduces compression artifacts. Ferrum and Playwright expose scale controls; a higher scale produces sharper retina-sized output at a larger file size. Keep the same viewport, browser version, device scale, fonts, timezone, and data set when comparing screenshots.
For deterministic visual tests, freeze time-dependent content where possible, disable animations, wait for network-dependent components, and hide blinking cursors or rotating carousels. Save files with a stable naming convention such as page-name--selector--commit.png.
Troubleshooting common errors
| Symptom | Likely cause | Fix |
|---|---|---|
no such element or a timeout |
The selector is wrong, the page has not rendered, or the element is inside an iframe. | Inspect the selector, wait for a stable condition, and switch into the correct frame before locating it. |
| Screenshot is blank | The node has zero dimensions, is hidden, or the page is still loading. | Check visibility and width/height, scroll into view, and wait for content to finish. |
| Only part of a tall element appears | WebDriver captured the visible portion of an oversized node. | Use Ferrum’s capture controls, split the content, or capture the full page and crop only when element capture cannot represent the complete node. |
| Unexpected popup or banner | An overlay covers the element. | Dismiss it, hide the selector, or use a capture service that removes known consent and widget overlays. |
| Detached or stale element | A frontend framework replaced the DOM node. | Reacquire the element or locator immediately before the screenshot. |
| File cannot be written | The destination directory does not exist or is not writable. | Create the directory and verify process permissions before starting the browser. |
| Different pixels on every run | Animations, ads, timestamps, fonts, or responsive layout vary. | Disable animations, block or mock unstable resources, fix viewport and scale, and wait for fonts and images. |
| Chrome starts locally but fails in CI | Missing browser binary, sandbox restrictions, or incompatible driver. | Install the browser in the CI image, use the library’s supported launch settings, and pin compatible versions. |
Performance, reliability, and cost considerations
Launching a browser for every URL is expensive. Reuse one browser process and create separate pages or contexts when isolation permits. Keep selectors narrow, avoid unnecessary full-page captures, and wait for the specific resource your element needs instead of sleeping for a fixed long delay. Parallel pages can improve throughput, but cap concurrency so CPU, memory, and network saturation do not create slower or less reliable captures.
Element screenshots inherit the target site’s behavior. Bot checks, authentication, rate limits, third-party failures, and client-side errors can all prevent a useful image. Record the URL, selector, viewport, browser version, and failure message with each job so you can reproduce it.
Self-hosted browser automation costs your infrastructure time and resources. If you only need an image from a URL, an API removes browser installation, process management, and capture cleanup from your application.
Or skip the browser setup
ScreenshotNeo provides a website screenshot API and MCP server. The API accepts one GET request and can capture a specific element with a selector parameter:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://example.com/ \
  --data-urlencode selector=.product-card \
  -o card.webp
require 'net/http'
require 'uri'
uri = URI('https://api.screenshotneo.com/v1/shot')
uri.query = URI.encode_www_form(
access_key: 'YOUR_API_KEY',
url: 'https://example.com/',
selector: '.product-card'
)
response = Net::HTTP.get_response(uri)
raise "Screenshot failed: #{response.code}" unless response.is_a?(Net::HTTPSuccess)
File.binwrite('card.webp', response.body)Equivalent clients are useful when your Ruby service already delegates media work:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://example.com/", "selector": ".product-card"}, timeout=90)
r.raise_for_status()
open("card.webp", "wb").write(r.content)
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://example.com/', selector: '.product-card' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
require('fs').writeFileSync('card.webp', Buffer.from(await res.arrayBuffer()));See the ScreenshotNeo documentation for request parameters and response handling. Before capture, ScreenshotNeo accepts cookie and consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks and CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed, and the response identifies the result with X-Page-Verdict and X-Billed headers. The service also offers custom CSS and JavaScript, click and wait actions, blocked resources, headers, cookies, user agents, authorization, timezone and geolocation, caching, signed links, PDFs, async jobs, bulk capture, a usage API, and an MCP server with take_screenshot, get_page_info, and capture_pdf tools for AI clients.
One thousand screenshots per month are free with no card. Paid plans start at $5 for 3,000 shots. Create a free ScreenshotNeo account.
FAQ
Can Selenium capture an element selected by CSS?
Yes. Use driver.find_element(:css, 'selector'), then call save_screenshot on the returned element.
Which library handles waiting automatically?
Playwright’s locator screenshot performs actionability checks and scrolls the element into view. Selenium and Ferrum require you to add the waits your page needs.
Can I capture an element inside an iframe?
Switch to the iframe context first, then locate the element within that frame. A top-level selector cannot cross frame boundaries.
Should visual tests use PNG or JPEG?
Use PNG for pixel comparisons and text-heavy interfaces. Use JPEG when smaller files matter more than lossless pixels.
How do I avoid consent banners in automated shots?
Dismiss or hide the banner in your browser script, or use ScreenshotNeo, which removes known consent platforms and common newsletter and chat overlays before capture.


