How to Select Elements by ID in XPath
Learn the portable XPath syntax for selecting HTML elements by ID, when to use id(), Selenium locators, and how to fix common lookup failures.
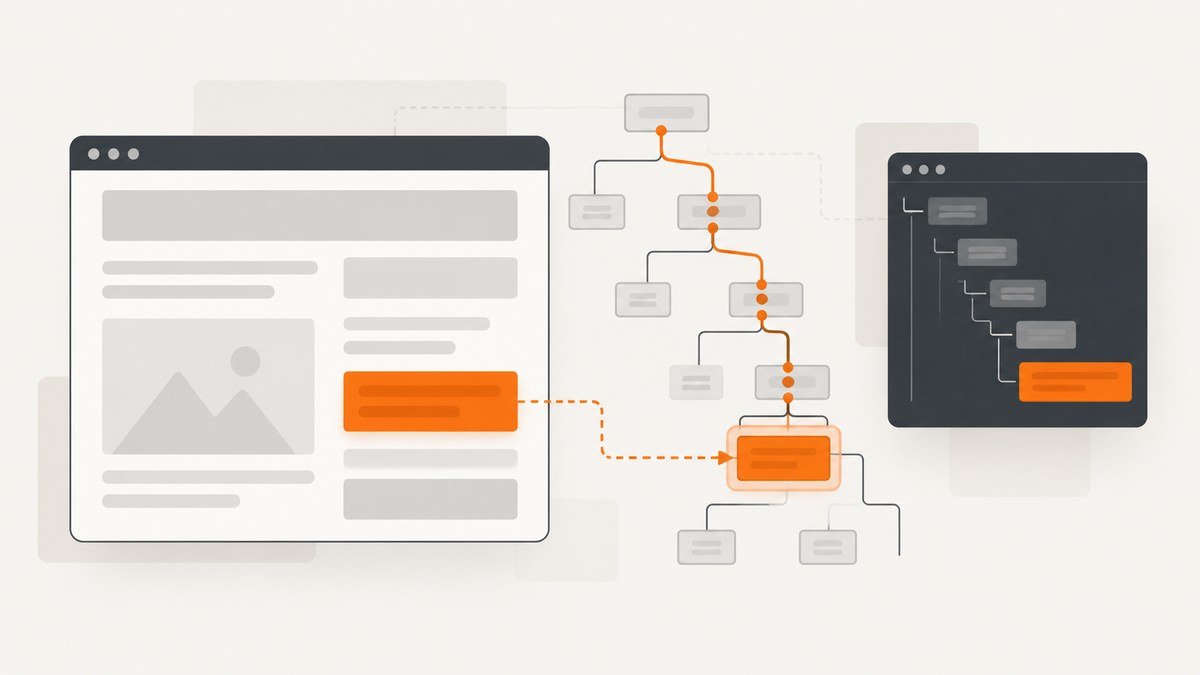
Direct answer: For HTML, the most portable XPath for an element with a known ID is //*[@id='element-id']. If your XPath processor knows that the document’s ID attribute is typed as an ID, XPath 1.0 also supports id('element-id'). In Selenium, use By.ID for a simple ID lookup and By.XPATH with an attribute predicate when you need XPath logic around that ID.
This distinction matters because the XPath id() function is not merely shorthand for checking an attribute named id. It depends on ID typing metadata supplied by the document and processor. An explicit predicate such as //*[@id='login'] checks the literal attribute and is usually the clearest choice for HTML automation and scraping.
1. The basic XPath for an element ID
Given this markup:
<button id="login" type="submit">Sign in</button>Select it with:
//*[@id='login']The expression has three parts:
//searches descendants anywhere in the document.*matches any element name.[@id='login']keeps elements whoseidattribute equals the literal valuelogin.
If you know the tag name, make the expression more specific:
//button[@id='login']
//input[@id='email']
//form[@id='checkout-form']
An element-qualified expression can make intent clearer and can prevent an accidental match if malformed markup contains the same ID on another element.
2. id('value') versus //*[@id='value']
| Approach | How it matches | Best use | Main limitation |
|---|---|---|---|
id('login') |
Uses the processor’s notion of typed IDs | XML or environments with reliable ID typing | May return nothing when HTML ID typing is unavailable |
//*[@id='login'] |
Tests the literal id attribute |
HTML, browser automation, and portable XPath | Can match multiple nodes when IDs are duplicated |
//input[@id='login'] |
Tests id and element name |
Known control type | Does not match if the tag changes |
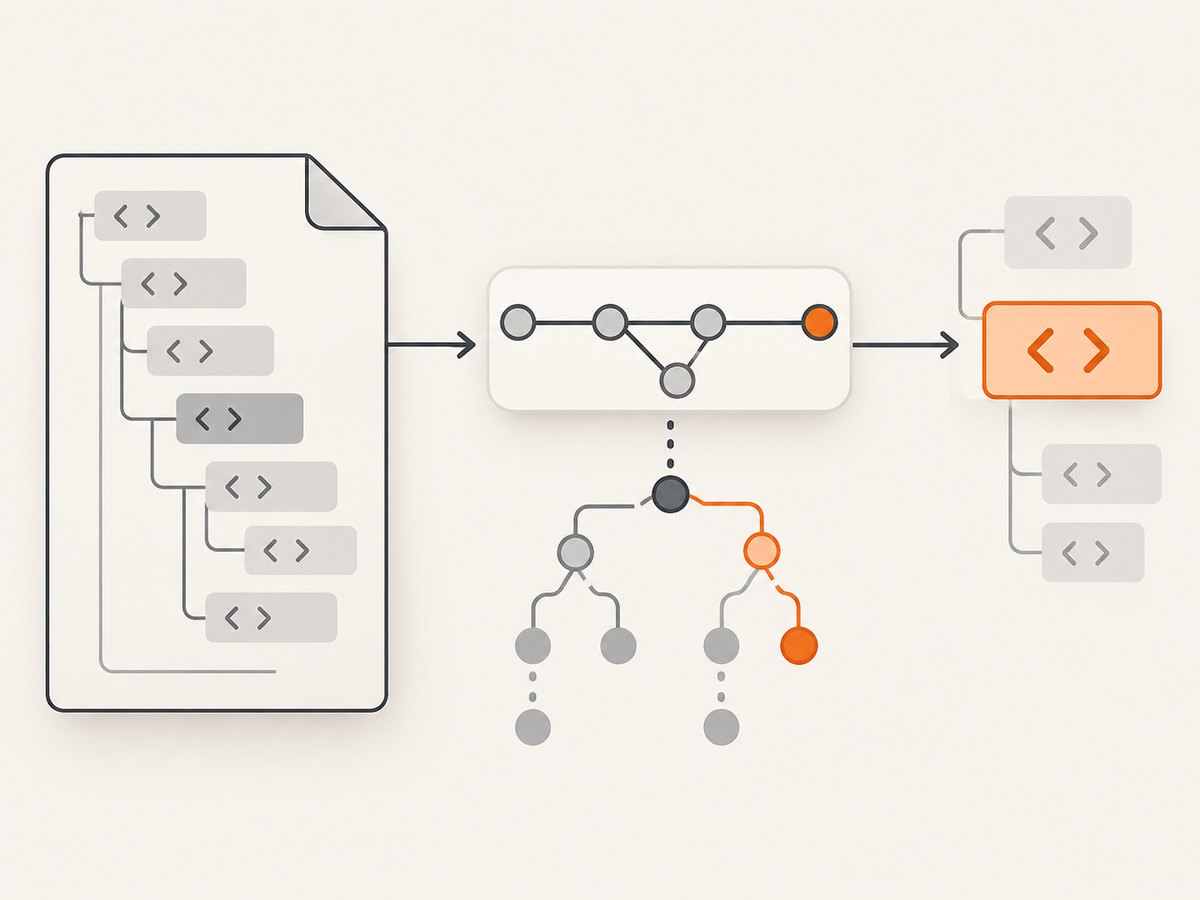
MDN describes the id function as finding nodes matching supplied IDs and returning the identified nodes. In XPath 1.0, however, the document’s DTD determines which attribute is of type ID. XML vocabularies can define an ID attribute with a different name, while an implementation without that typing information may not resolve id() as you expect.
For an HTML page, start with //*[@id='value'] or an element-qualified equivalent. Use id() when you know the document model and XPath implementation provide the required ID typing.
3. IDs are case-sensitive and should be unique
HTML ID values are case-sensitive. login, Login, and LOGIN are different values:
//*[@id='login']
//*[@id='Login']
Conformant documents should use a unique ID for each element. Real pages sometimes contain duplicates, especially when a component is rendered twice or a hidden template remains in the DOM. In that case:
//*[@id='login']may return more than one node. A DOM convenience method such as getElementById() returns the first match, which can hide the markup problem. If duplicates are unavoidable, add context:
//main//*[@id='login']
//form[@id='account-form']//*[@id='email']
(//*[@id='login'])[1]
(//*[@id='login'])[last()]
Use positional expressions only when the ordering is part of the page contract. A stable ancestor, role, or form relationship is generally more maintainable.
4. Selecting an ID with additional XPath conditions
The main reason to choose XPath over a direct ID locator is that XPath can express relationships and predicates. Examples:
//section[@id='billing']//input[@name='cardNumber']
//*[@id='results']//a[contains(normalize-space(.), 'Details')]
//*[@id='profile' and @aria-hidden='false']
//*[@id='cart']//button[normalize-space(.)='Remove']
//label[@for='email']/following-sibling::input[1]
//*[@id='dialog']//ancestor::main[1]
Useful XPath tools include:
contains()for a substring in an attribute or text node.normalize-space()to collapse surrounding and repeated whitespace.ancestor,parent,following-sibling, anddescendantaxes for relationships.andandorfor multiple conditions.- Predicates such as
[1]or[last()]when position is intentional.
Avoid absolute paths such as /html/body/div[2]/form/input. They depend on every wrapper and sibling position, so a layout change can invalidate them. Anchor the expression to a stable ID or semantic structure instead.
5. Selenium: locating an element by ID
Selenium exposes ID and XPath as separate locator strategies. Use the simplest locator that expresses the requirement.
Python
from selenium import webdriver
from selenium.webdriver.common.by import By

 driver = webdriver.Chrome()
 driver.get("https://example.com/login")

login = driver.find_element(By.ID, "login")
login.click()

# Equivalent XPath when XPath logic is needed:
login = driver.find_element(By.XPATH, "//*[@id='login']")
For dynamic pages, wait for the element instead of querying immediately:
from selenium.webdriver.support.ui import WebDriverWait
from selenium.webdriver.support import expected_conditions as EC

login = WebDriverWait(driver, 15).until(
    EC.element_to_be_clickable((By.ID, "login"))
)
login.click()
Selenium’s JavaScript By.id implementation uses a CSS selector equivalent to *[id="$ID"], while By.xpath evaluates an XPath expression. That means By.ID is direct and readable, whereas By.XPATH is appropriate when you need predicates or axes.
JavaScript
import { Builder, By, until } from "selenium-webdriver";

const driver = await new Builder().forBrowser("chrome").build();
try {
  await driver.get("https://example.com/login");
  const login = await driver.wait(
    until.elementLocated(By.id("login")),
    15000
  );
  await login.click();

  const sameElement = await driver.findElement(By.xpath("//*[@id='login']"));
} finally {
  await driver.quit();
}
Java
WebDriver driver = new ChromeDriver();
driver.get("https://example.com/login");

WebElement login = driver.findElement(By.id("login"));
WebElement sameElement = driver.findElement(By.xpath("//*[@id='login']"));
6. Dynamic XPath values and quoting
When the ID comes from a variable, construct the XPath using your host language’s escaping rules. Do not concatenate untrusted text into an expression without handling quotes. In Python, a simple ID can be passed to Selenium’s dedicated strategy:
element_id = "login"
element = driver.find_element(By.ID, element_id)
If XPath is required, IDs containing apostrophes need an XPath string literal that uses double quotes, and values containing both quote types require concat(). A helper can choose the safe form:
def xpath_literal(value: str) -> str:
    if "'" not in value:
        return f"'{value}'"
    if '"' not in value:
        return f'"{value}"'
    parts = value.split("'")
    return "concat(" + ", \"'\", ".join(f"'{part}'" for part in parts) + ")"

expr = f"//*[@id={xpath_literal(element_id)}]"
element = driver.find_element(By.XPATH, expr)
Keep IDs under your control when possible. A generated selector should still be checked for uniqueness and case.
7. HTML versus XML
HTML parsers know the conventional id attribute, but XPath itself is used across XML documents where the ID declaration can come from a DTD or schema. An XML document might use an attribute such as xml:id or a vocabulary-specific name. In those documents, id('value') can be the correct abstraction only if the processor has the typing information.
When portability matters and the attribute is literally named id, use:
//*[@id='value']When the document defines a different ID attribute, use that attribute explicitly or follow the processor’s documented ID behavior. Namespace-aware XML queries may also require a namespace prefix registered with the XPath engine.
8. Selecting elements by ID in browser scripts
Browser JavaScript does not evaluate XPath with CSS syntax. For a direct lookup, the DOM API is usually simplest:
const element = document.getElementById("login");To evaluate XPath in the browser:
const result = document.evaluate(
  "//*[@id='login']",
  document,
  null,
  XPathResult.FIRST_ORDERED_NODE_TYPE,
  null
);
const element = result.singleNodeValue;
Use XPathResult.ORDERED_NODE_SNAPSHOT_TYPE when duplicate IDs must be inspected:
const result = document.evaluate(
  "//*[@id='login']",
  document,
  null,
  XPathResult.ORDERED_NODE_SNAPSHOT_TYPE,
  null
);
for (let i = 0; i < result.snapshotLength; i++) {
  console.log(result.snapshotItem(i));
}
9. Troubleshooting XPath ID lookups
| Symptom | Likely cause | Fix |
|---|---|---|
id('login') returns no node |
The processor does not know the attribute is typed as an ID | Use //*[@id='login'], or configure XML ID typing |
| Lookup returns no element | Wrong case, spelling, frame, shadow root, or page state | Inspect the live DOM, match case exactly, switch to the frame, or wait for rendering |
| Several elements match | Duplicate IDs | Fix the markup; otherwise anchor to a stable ancestor and verify the selected node |
| Works locally, fails in CI | Timing, redirects, consent overlays, or different responsive markup | Wait on a meaningful condition, log the current URL and DOM, and use a viewport appropriate to the test |
| XPath syntax error | Unescaped quote or malformed predicate | Escape dynamic values and test the expression in browser developer tools |
| Element is found but cannot be clicked | Overlay, disabled state, off-screen position, or stale reference | Wait for clickability, dismiss the overlay, scroll into view, or reacquire the element |
| Absolute XPath breaks after redesign | Wrapper or sibling indexes changed | Use a relative ID anchor and semantic relationships |
Frames and shadow DOM
An element inside an iframe is not in the top-level document’s XPath context. In Selenium, switch first:
frame = driver.find_element(By.ID, "payment-frame")
driver.switch_to.frame(frame)
card = driver.find_element(By.XPATH, "//*[@id='card-number']")
driver.switch_to.default_content()
Shadow DOM boundaries also require entering the shadow root before locating descendants. A document-level XPath expression cannot cross that boundary.
10. Performance, reliability, and maintainability
- Prefer direct IDs:
By.IDorgetElementById()communicates intent and avoids unnecessary XPath evaluation. - Use XPath for logic: Choose XPath when you need hierarchy, text, or multiple predicates; do not use a long XPath just because it works.
- Wait on state: Presence, visibility, and clickability are different conditions. Choose the one your action requires.
- Keep IDs stable: Test and automation IDs should not change with visual redesigns. If the application supports it, use dedicated attributes such as
data-testidfor test contracts. - Validate uniqueness: Add a DOM assertion that the ID occurs once. This catches ambiguous selectors early.
- Record diagnostics: On failure, capture the URL, frame context, viewport, and a short DOM excerpt. This distinguishes a bad selector from a page that never reached the expected state.
XPath performance is rarely the primary bottleneck for a single ID lookup. Network waits, JavaScript rendering, and synchronization usually dominate. A stable locator and correct wait strategy improve reliability more than micro-optimizing equivalent XPath spellings.
11. Verify the page visually with ScreenshotNeo
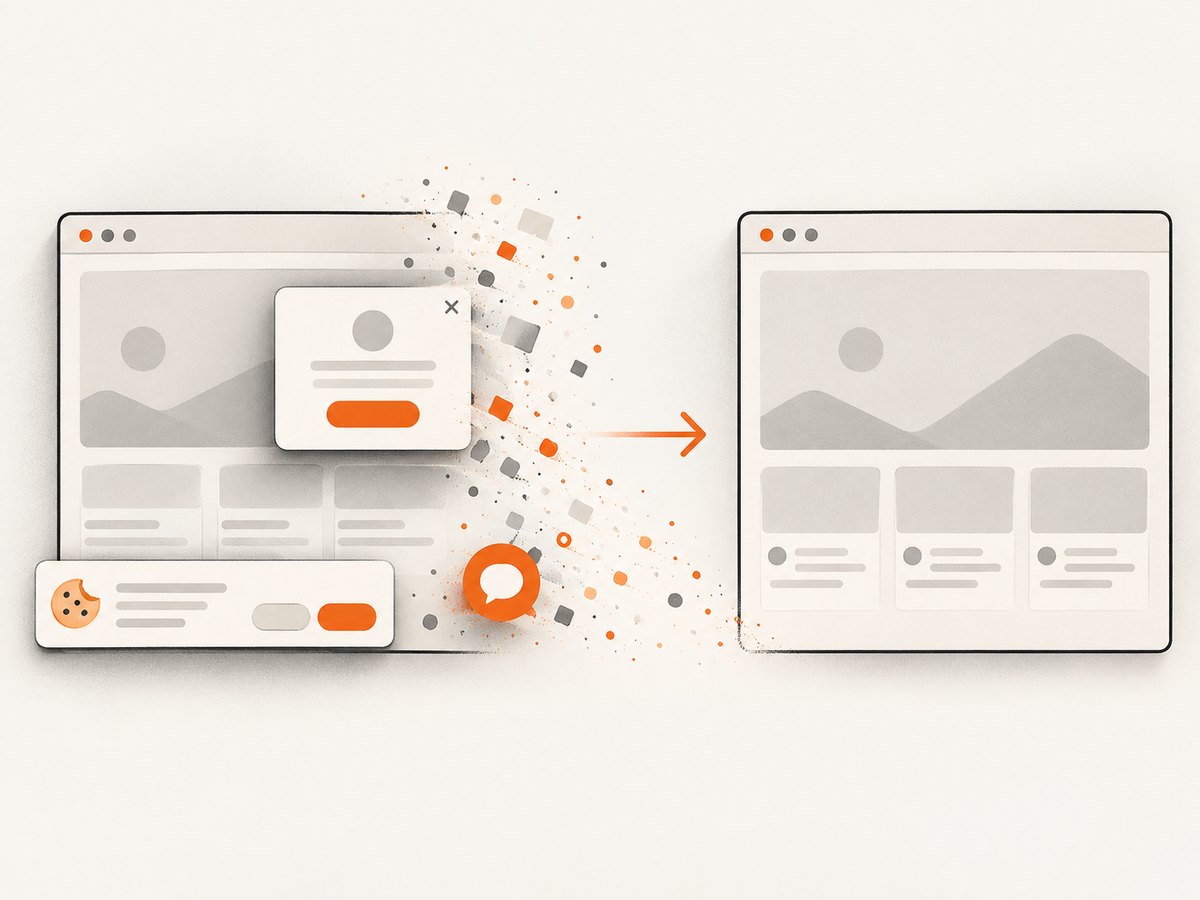
When an automation failure may be caused by a consent banner, popup, chat widget, bot check, or blank render, a screenshot gives you evidence of the page state. ScreenshotNeo is a website screenshot API and MCP server. It can capture a full page or one element by CSS selector, wait for a selector or network idle, run custom JavaScript, set cookies and headers, and return PNG, JPEG, WebP, or PDF. Its clean-shot mode accepts cookie and consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets before capture.
Here is a direct request you can save while debugging a locator:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpSee the ScreenshotNeo API documentation for request options and response headers. The same request in Python:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' }); const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo reports X-Page-Verdict and X-Billed headers. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits cost nothing; only clean shots are billed. An MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients.
12. Or skip the browser setup
If your goal is a reliable visual capture rather than maintaining Selenium infrastructure, call ScreenshotNeo directly. Cookie banners, popups, and chat widgets are removed before the shot; bot checks, blank pages, and failed loads are never billed; an MCP server lets AI agents take screenshots; 1,000 screenshots a month are free with no card and paid plans start at $5 for 3,000.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpCreate a free ScreenshotNeo account with 1,000 screenshots each month and no card required.
13. FAQ
What is the XPath for an element with a specific ID?
Use //*[@id='value']. Add the tag name when useful, for example //button[@id='save'].
Is id('x') faster or better?
It can be appropriate when the processor knows the document’s ID typing. For ordinary HTML automation, the explicit attribute predicate is more predictable.
Should Selenium use By.ID or By.XPATH?
Use By.ID for a direct, stable ID. Use By.XPATH when you need relationships, text conditions, or additional predicates.
Why does capitalization matter?
ID values are case-sensitive. The selector must use exactly the same characters as the DOM attribute.
Can XPath cross an iframe?
No. Switch into the iframe first, then evaluate XPath in that document context.
What if the page has duplicate IDs?
Fix the markup when possible. Otherwise constrain the XPath with a stable ancestor and verify how many nodes matched.


