How to Select Values Between Two HTML Nodes with PHP
Parse HTML with DOMXPath, find boundary nodes, and extract text or markup safely between them with predictable stopping rules.
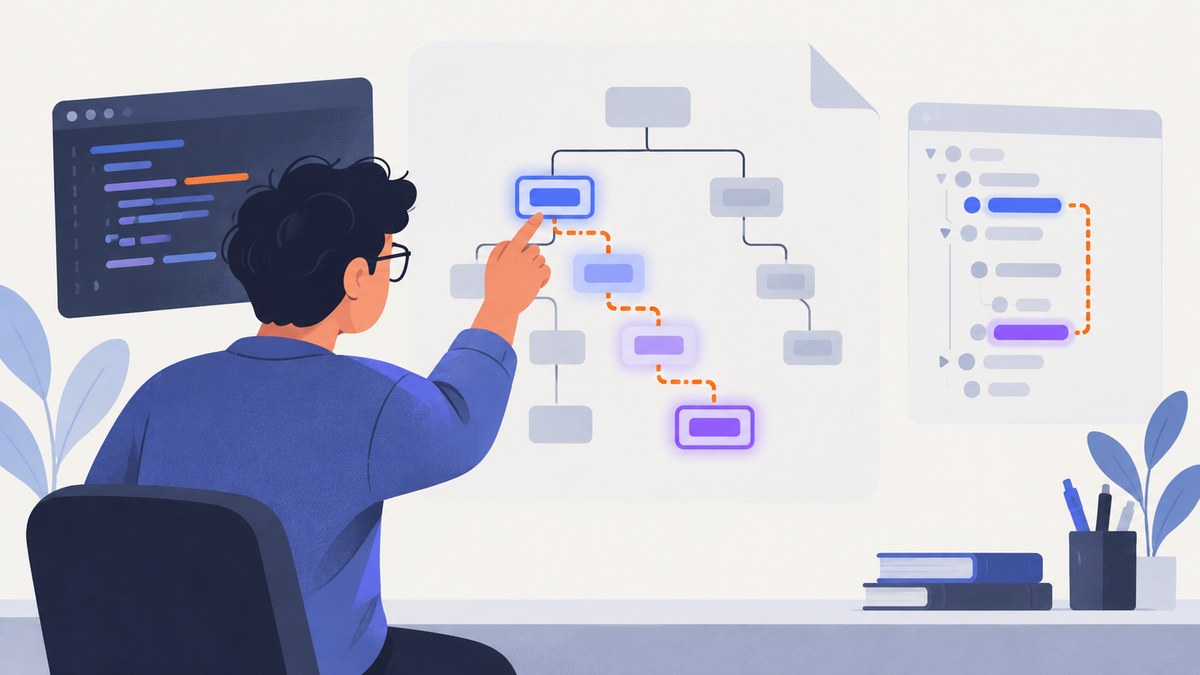
To select everything between two HTML nodes in PHP, parse the HTML into a DOM, locate the start and end markers with DOMXPath, then walk nextSibling until the end node. This explicit loop is the safest default because it stops at the first matching end marker, handles whitespace and comments predictably, and works when sections repeat.
Use textContent when you need readable values. Use DOMDocument::saveHTML() when you must preserve links, emphasis, images, or other markup. For modern HTML, be aware that DOMDocument::loadHTML() uses an HTML 4 parser; PHP 8.4 adds Dom\\HTMLDocument for HTML5-conforming parsing.
1. The reliable DOM sibling-loop solution
This complete example finds the headings with IDs start and end, then collects every non-empty text-bearing node between them.

<?php
declare(strict_types=1);

$html = <<<'HTML'
<div class="content">
  <h2 id="start">Start</h2>
  <p>First value</p>
  <p>Second <strong>value</strong></p>
  <!-- This comment is between the markers -->
  <h2 id="end">End</h2>
  <p>Outside the range</p>
</div>
HTML;

$doc = new DOMDocument();
libxml_use_internal_errors(true);
$loaded = $doc->loadHTML($html, LIBXML_NOERROR | LIBXML_NOWARNING);
libxml_clear_errors();

if (!$loaded) {
    throw new RuntimeException('Invalid HTML');
}

$xpath = new DOMXPath($doc);
$startResult = $xpath->query("//h2[@id='start']");
$endResult   = $xpath->query("//h2[@id='end']");

if ($startResult === false || $endResult === false) {
    throw new RuntimeException('Invalid XPath expression');
}

$start = $startResult->item(0);
$end   = $endResult->item(0);

$values = [];
if ($start instanceof DOMNode && $end instanceof DOMNode) {
    for ($node = $start->nextSibling; $node !== null; $node = $node->nextSibling) {
        if ($node->isSameNode($end)) {
            break;
        }

        if ($node->nodeType === XML_ELEMENT_NODE || $node->nodeType === XML_TEXT_NODE) {
            $text = trim($node->textContent ?? '');
            if ($text !== '') {
                $values[] = $text;
            }
        }
    }
}

print_r($values);
The output is:
Array
(
    [0] => First value
    [1] => Second value
)
DOMXPath::query() returns a DOMNodeList, or false for a malformed expression or invalid context. Check both results before calling item(0). The node API exposes nextSibling, previousSibling, childNodes, nodeValue, and textContent, so the stopping condition remains visible in ordinary PHP code. See the DOMXPath documentation and DOMNode documentation.
2. How the algorithm works
- Create a DOM document and parse the HTML.
- Create a
DOMXPathobject for that document. - Find the first start and end nodes.
- Begin at
$start->nextSibling, so the start marker itself is excluded. - Compare each node with the end marker using
isSameNode(). - Stop immediately when the end marker is reached.
- Read
textContent, or serialize the node when markup must be retained.
Whitespace between tags is represented as text nodes. Comments are separate comment nodes. The example ignores comments and empty text, but you can include them when your application needs the exact document structure.
3. Preserve HTML instead of extracting plain text
For a fragment that retains nested tags, links, and emphasis, serialize each element with saveHTML():
$fragments = [];

if ($start instanceof DOMNode && $end instanceof DOMNode) {
    for ($node = $start->nextSibling; $node !== null; $node = $node->nextSibling) {
        if ($node->isSameNode($end)) {
            break;
        }

        if ($node->nodeType === XML_ELEMENT_NODE) {
            $fragments[] = $doc->saveHTML($node);
        }
    }
}

$fragmentHtml = implode("\n", $fragments);
echo $fragmentHtml;
This returns markup such as <p>Second <strong>value</strong></p>. Do not treat the result as sanitized HTML if the source is untrusted. Escape it for the output context or sanitize it with a dedicated, security-reviewed sanitizer.
4. XPath-only selection with following-sibling
When both markers are unique siblings in one parent, XPath can select the range without a procedural loop:
$nodes = $xpath->query(
    "//h2[@id='start']/following-sibling::node()[following-sibling::h2[@id='end']]"
);

if ($nodes === false) {
    throw new RuntimeException('Invalid XPath expression');
}

$values = [];
foreach ($nodes as $node) {
    $text = trim($node->textContent ?? $node->nodeValue ?? '');
    if ($text !== '') {
        $values[] = $text;
    }
}
The predicate keeps nodes that have an end heading somewhere later among their siblings. It is concise, but it can over-select when there are repeated end markers or nested sections. Use the explicit loop when “the first matching end marker” is part of the requirement.
5. Scope XPath to a container
If a page contains several independent articles, first identify the container and run a relative query. A leading dot is important because it keeps the query below the context node:
$containerResult = $xpath->query("//article[@data-section='pricing']");
if ($containerResult === false || !$containerResult->item(0)) {
    throw new RuntimeException('Container not found');
}

$container = $containerResult->item(0);
$startResult = $xpath->query(".//h2[@id='start']", $container);
$endResult   = $xpath->query(".//h2[@id='end']", $container);

if ($startResult === false || $endResult === false) {
    throw new RuntimeException('Invalid relative XPath');
}

$start = $startResult->item(0);
$end = $endResult->item(0);
Without a container scope, //h2 searches the whole document and may select a marker from a different section.
6. Handling repeated markers and nested content
Repeated sections
For repeated start/end pairs, iterate over containers or select a start node and find the first end node that follows it in the same parent. A sibling loop naturally terminates at the first end node it encounters. Validate that both markers share the expected parent before extracting.
Nested elements
nextSibling moves among children of the same parent. It does not descend into a child element. If your start marker is inside a wrapper and the values are nested below it, select the wrapper first, then inspect its childNodes or use a relative XPath query.
Including the boundary nodes
To include the start heading, process $start before entering the loop. To include the end heading, process it after the loop breaks. Most extraction tasks exclude both markers, which is why the example begins at nextSibling and stops before processing $end.
7. Modern HTML and parser caveats
DOMDocument::loadHTML() accepts imperfect HTML, but PHP documents warn that it uses an HTML 4 parser and can produce a tree different from a browser’s HTML5 parser. PHP 8.4 introduces Dom\\HTMLDocument::createFromString() and createFromFile() for HTML5-conforming parsing. Parsing behavior can also vary with the installed libxml version. Read the loadHTML manual before relying on browser-specific markup behavior.
For older PHP versions, suppress expected libxml warnings only around the parse, always clear the error buffer, and record malformed-input failures in your application logs. Do not use loadHTML() as an HTML sanitizer; parsing differences can have security consequences for untrusted input.
8. XPath expressions you can adapt
| Goal | XPath |
|---|---|
| Heading by ID | //h2[@id='start'] |
| Heading by exact text | //h2[normalize-space()='Start'] |
| Any element with a class token | //*[contains(concat(' ', normalize-space(@class), ' '), ' marker ')] |
| Following element siblings | following-sibling::* |
| All sibling node types | following-sibling::node() |
| Relative search in a container | .//section[@data-part='body'] |
Prefer stable IDs or data attributes. Matching visible text is more fragile because punctuation, whitespace, localization, and nested inline tags can change.
9. Common errors and fixes
| Error or symptom | Cause | Fix |
|---|---|---|
Call to a member function item() on bool |
query() returned false. |
Check the query result before calling item(); validate XPath syntax. |
item(0) is null |
No matching boundary exists. | Check the selector, casing, namespace, and source HTML; handle the missing-marker case. |
| Values include content after the end marker | The query selected all following siblings or the end marker differs from the one tested. | Use the procedural loop and compare with isSameNode(). |
| Nothing is returned between headings | The markers are not siblings; content is nested in a wrapper. | Scope to the common parent or traverse that container’s descendants. |
| Text appears duplicated | You collected a parent element and its child elements. | Choose either element nodes or text nodes, not both, and define whether you want block-level values. |
| Unexpected structure around modern markup | HTML 4 parsing differs from browser HTML5 parsing. | Use Dom\\HTMLDocument on PHP 8.4+ or a parser designed for your HTML version. |
| Security issue from imported HTML | Parsed HTML was assumed to be sanitized. | Parse and sanitize as separate operations; escape output for its context. |
10. Performance, reliability, and limits
Parsing is usually the dominant cost, not the sibling walk. A single XPath lookup and linear traversal are appropriate for ordinary documents. Avoid reparsing the same string for every section: build one DOM, reuse one DOMXPath, and pass a container context for each extraction.
For very large documents, discard unrelated input before parsing when possible, or process one document per job. Avoid deeply nested recursive code when a sibling loop expresses the range. Put limits on input size and extraction time for user-supplied HTML. If the source is fetched over the network, separate download timeouts from parsing and validate the HTTP status before loading the body.
Cache selectors only when the source template is stable. Log missing markers, parser warnings, and the selected section identifier so a template change can be diagnosed without storing sensitive HTML.
11. Testing checklist
- Start and end markers both exist.
- Markers are in the same intended container.
- There are no repeated IDs.
- Whitespace-only nodes and comments behave as expected.
- The first end marker stops extraction.
- Nested inline markup is preserved or flattened intentionally.
- Missing markers produce a controlled result.
- Malformed and untrusted HTML follow your parser and sanitization policy.
- PHP and libxml versions used in production match the parser behavior you tested.
12. Or skip the browser setup
If the HTML lives on a public URL and your real goal is a visual capture, ScreenshotNeo can return a clean PNG, JPEG, WebP, or PDF with one request. It accepts cookie and consent banners, then removes more than 60 known consent platforms, newsletter popups, and chat widgets before capture. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing result.

See the ScreenshotNeo API documentation for all options. The basic call is:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython:
import requests

r = requests.get(
    "https://api.screenshotneo.com/v1/shot",
    params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
    timeout=90,
)
r.raise_for_status()
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
if (!res.ok) throw new Error(`Screenshot failed: ${res.status}`);
const buffer = Buffer.from(await res.arrayBuffer());
require('fs').writeFileSync('shot.webp', buffer);
For PHP, the same endpoint works with cURL:
<?php
$url = 'https://api.screenshotneo.com/v1/shot?' . http_build_query([
    'access_key' => 'YOUR_API_KEY',
    'url' => 'https://stripe.com',
]);

$ch = curl_init($url);
curl_setopt_array($ch, [
    CURLOPT_RETURNTRANSFER => true,
    CURLOPT_TIMEOUT => 90,
]);
$body = curl_exec($ch);
if ($body === false) {
    throw new RuntimeException(curl_error($ch));
}
$status = curl_getinfo($ch, CURLINFO_RESPONSE_CODE);
curl_close($ch);
if ($status < 200 || $status >= 300) {
    throw new RuntimeException("Screenshot failed: $status");
}
file_put_contents('shot.webp', $body);
Options cover full-page capture with lazy images, CSS selector capture, dark mode, device presets, custom viewports, retina scale, PDF paper and page ranges, custom CSS and JavaScript, clicks, waits, blocked resources, headers, cookies, user agents, authorization, timezone, geolocation, transparent backgrounds, resizing, chosen cache TTLs, signed image links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs, and a usage API. An MCP server provides take_screenshot, get_page_info, and capture_pdf for Claude, Cursor, and other MCP clients.
There are 1,000 free screenshots each month with no card. Paid plans start at $5 for 3,000 shots; yearly billing gives two months free. Create a free ScreenshotNeo account to try it.
13. FAQ
Should I use XPath or CSS selectors?
Use XPath with DOMXPath when you need document relationships such as following siblings, ancestor checks, or text predicates. CSS selectors require a different selector engine and do not replace XPath’s relationship axes directly.
How do I return one combined string?
Append each extracted value to an array and call implode("\n", $values). This lets you filter empty nodes before joining.
Can I select nodes between two arbitrary elements?
Yes, provided you define their relationship. A sibling loop handles nodes with the same parent. For different branches, identify the common ancestor and define an order-aware traversal.
Does textContent decode HTML entities?
It returns the DOM’s text representation. If you serialize markup instead, use the resulting HTML according to your output context and escaping rules.
What happens if the end marker is missing?
Decide on a policy: return an empty result, extract to the end of the container, or raise an exception. Do not silently assume the template is unchanged.