How to Follow URL Redirects and Screenshot the Final Page with SlimerJS
Follow redirects in SlimerJS, verify the final URL, handle frames and HTTP errors, and capture the settled page with a reproducible viewport.
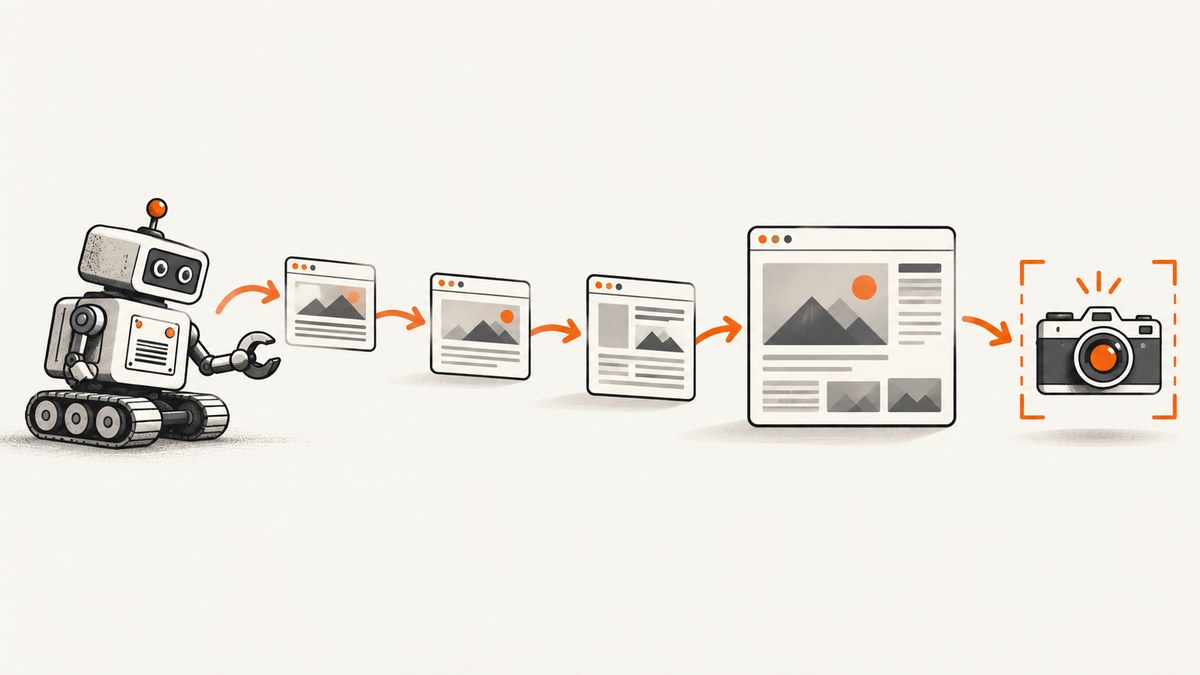
Direct answer: SlimerJS follows ordinary HTTP redirects during page.open(). Wait for its asynchronous callback (or promise) to finish, read page.url for the browser’s resulting URL, optionally record response.redirectURL from resource events for redirect diagnostics, set viewportSize, wait for the asynchronous reflow, and then call page.render(). Do not inspect the URL or render immediately after calling page.open(); that code runs before navigation has completed.
This is a legacy-tool walkthrough. The official SlimerJS project site says development ceased in 2018 and that SlimerJS works with Firefox 59 only. Versions above Firefox 59 are unsupported. Treat the recipe as an archival maintenance technique and verify the exact SlimerJS/Firefox environment before relying on it.
What happens during a redirect
A normal browser navigation handles 301, 302, 303, 307, and 308 responses internally. Your script generally does not need to implement redirect logic itself. When the main document has loaded, page.url is the URL currently displayed by the page object, which is the value you usually want to store with the screenshot.

Redirect response metadata answers a different question: which network request pointed to which target? In onResourceReceived, a response may contain redirectURL. Record it when present, but do not assume every redirect or navigation exposes a value. The two signals work together:
| Signal | Use it for | Limitation |
|---|---|---|
page.url |
The final URL visible to the browser after navigation | It does not provide a complete HTTP redirect history |
response.redirectURL |
Diagnosing individual redirected resource responses | Optional response metadata; it may be absent |
onLoadFinished(status, url, isFrame) |
Knowing that a document load event occurred | It also fires for frames, and success can include HTTP 404 responses |
Prerequisites and the Firefox 59 constraint
Install the SlimerJS 1.0.0 release alongside the Firefox version it supports. The project homepage explicitly warns that higher Firefox versions will not be supported because development stopped in 2018. Do not silently substitute a current Firefox binary: an apparently similar setup can fail before your script reaches page.open().
- Provision SlimerJS 1.0.0 and Firefox 59 in an isolated legacy environment.
- Confirm the executable starts and reports the expected versions.
- Save screenshots and logs outside the temporary browser profile so they survive each run.
- Use HTTPS URLs where the target site supports them, and make your capture policy explicit for authentication, cookies, and private pages.
The examples below use the documented SlimerJS webpage module. They are documentation-derived patterns, not claims of current runtime testing.
Callback implementation: follow, verify, and capture
Callback style is closest to older PhantomJS-style code and is the safest shape when maintaining an existing script. The important ordering is navigation, callback, URL inspection, viewport assignment, reflow wait, render, and cleanup.
var page = require('webpage').create();
var startUrl = 'https://example.com/short-link';
var redirectTargets = [];

page.onResourceReceived = function (response) {
    if (response.redirectURL) {
        redirectTargets.push({
            from: response.url,
            to: response.redirectURL,
            status: response.status
        });
    }
};

page.open(startUrl, function (status) {
    if (status !== 'success') {
        console.log('Navigation failed: ' + status);
        page.close();
        slimer.exit();
        return;
    }

    // This is the browser's current URL after navigation.
    console.log('Current page URL: ' + page.url);
    console.log('Redirect response metadata: ' +
        JSON.stringify(redirectTargets));

    // Choose the viewport before rendering.
    page.viewportSize = { width: 1280, height: 900 };

    // viewportSize causes an asynchronous reflow. Give it time to apply.
    window.setTimeout(function () {
        page.render('final-page.png', { onlyViewport: true });
        page.close();
        slimer.exit();
    }, 500);
});
Run a script with the SlimerJS executable, for example:
slimerjs capture-final.jsThe fixed 500 millisecond delay is a simple API-compatible illustration. It is not a universal guarantee that client-side rendering, fonts, images, or late requests have settled. For a dynamic page, replace the blind delay with a page-specific readiness check where possible (for example, wait until a known element exists and contains the expected state), then keep a bounded timeout so a broken page cannot hold the process forever.
Promise style and main-frame filtering
SlimerJS also documents a promise-returning form of page.open(). Promise chaining can make sequential actions easier to read, but the quick-start documentation notes that this style is not compatible with PhantomJS. Choose it when the rest of your code already uses SlimerJS promises.
var page = require('webpage').create();
var startUrl = 'https://example.com/short-link';

page.open(startUrl)
    .then(function (status) {
        if (status !== 'success') {
            throw new Error('Navigation failed: ' + status);
        }

        console.log('Final browser URL: ' + page.url);
        page.viewportSize = { width: 1440, height: 1000 };

        // Keep the render after the asynchronous viewport reflow.
        return new Promise(function (resolve) {
            window.setTimeout(resolve, 500);
        });
    })
    .then(function () {
        page.render('final-page.png', { onlyViewport: true });
        page.close();
        slimer.exit();
    })
    .catch(function (error) {
        console.log(error.message);
        page.close();
        slimer.exit();
    });
An event-based alternative is useful when you need to observe every load:
page.onLoadFinished = function (status, url, isFrame) {
    if (isFrame) {
        return; // Ignore iframe and subframe completions.
    }
    console.log('Main document load: ' + status + ' at ' + url);
    console.log('Page object's current URL: ' + page.url);
};
onLoadFinished can fire for frames as well as the top-level document. Filter with isFrame === false (or return when it is true) before triggering a top-page capture. Otherwise an iframe completing after the main document can cause an unintended second screenshot.
Render scope, formats, and viewport choices
page.render(filename, options) captures the browser rendering. SlimerJS documents PNG, JPEG/JPG, PDF, BMP, and ICO output; GIF is unavailable in Gecko. The filename extension normally communicates the format, while options control the capture region.
| Setting | What it does | When to choose it |
|---|---|---|
onlyViewport: true |
Captures only the visible viewport | Visual regression checks, above-the-fold previews, fixed-size thumbnails |
| Default content capture | Can include the document beyond the viewport | Archival pages or long-form content where the whole document matters |
clipRect |
Restricts output to a rectangle | Capture a known region while keeping a stable viewport |
Set the viewport before the render and record its width, height, and device scale assumptions with the output. A viewport change triggers asynchronous reflow. The API documentation also describes slimer.wait(500) for allowing asynchronous viewport or zoom changes; that helper is SlimerJS-specific and is not compatible with PhantomJS.
page.viewportSize = { width: 1280, height: 900 };
slimer.wait(500);
page.render('viewport.jpg', { onlyViewport: true });

// A clipped region (coordinates are in page pixels).
page.render('header.png', {
    onlyViewport: true,
    clipRect: { top: 0, left: 0, width: 1280, height: 240 }
});
HTTP status, redirects, and error policy
Do not treat status === 'success' as proof of a 2xx response. The SlimerJS 1.0.0 webpage API documentation explains that a valid HTTP response can produce success even for a 404. Decide whether your job should capture error pages for debugging or reject them for a success-only report.
To apply that policy, collect response status codes:
var mainResponseStatus = null;

page.onResourceReceived = function (response) {
    if (response.url === page.url || response.redirectURL) {
        mainResponseStatus = response.status;
    }
};

page.open(startUrl, function (status) {
    if (status !== 'success') {
        console.log('Transport/navigation failure: ' + status);
        return;
    }

    console.log('Final URL: ' + page.url);
    console.log('Observed response status: ' + mainResponseStatus);

    // Example success-only policy; change it if error-page captures are useful.
    if (mainResponseStatus !== null &&
        (mainResponseStatus < 200 || mainResponseStatus >= 300)) {
        console.log('Rejecting non-2xx final response');
        page.close();
        slimer.exit();
        return;
    }

    page.viewportSize = { width: 1280, height: 900 };
    window.setTimeout(function () {
        page.render('final-page.png', { onlyViewport: true });
        page.close();
        slimer.exit();
    }, 500);
});
Status collection can be complicated by subresources and multiple responses. If exact auditing matters, log each response’s URL, status, and redirect target, then identify the main document using the navigation URL and your site’s known behavior. Keep the screenshot policy separate from the logging policy.
Waiting for dynamic content after the redirect
Load completion means the document received a valid response; it does not prove that a single-page application has finished rendering. After the redirect, late JavaScript may replace the DOM, lazy-load images, or display an interstitial. Prefer a readiness condition tied to the page:
page.open(startUrl, function (status) {
    if (status !== 'success') {
        page.close();
        slimer.exit();
        return;
    }

    var deadline = Date.now() + 10000;
    function captureWhenReady() {
        var ready = page.evaluate(function () {
            var marker = document.querySelector('[data-render-ready]');
            return marker && marker.getAttribute('data-render-ready') === 'true';
        });

        if (ready || Date.now() >= deadline) {
            page.viewportSize = { width: 1280, height: 900 };
            window.setTimeout(function () {
                page.render('final-page.png', { onlyViewport: true });
                page.close();
                slimer.exit();
            }, 500);
            return;
        }
        window.setTimeout(captureWhenReady, 200);
    }
    captureWhenReady();
});
Use a marker your application actually controls. If you cannot add one, wait for a stable selector, a known text condition, or a bounded delay and document the limitation.
Troubleshooting checklist
| Symptom | Likely cause | Fix |
|---|---|---|
| Screenshot shows the original short URL | Render ran before page.open() completed |
Move URL inspection and rendering into the callback or promise continuation. |
| Final URL is correct but layout is old | Viewport assignment had not reflowed yet | Wait after setting viewportSize; use a readiness check or slimer.wait(). |
| Capture fires several times | onLoadFinished responded to frames |
Ignore events where isFrame is true. |
| Script reports success for an error page | SlimerJS treats a valid 404 response as success |
Record response status and enforce your own 2xx or error-page policy. |
| No redirect chain appears in logs | redirectURL is optional response metadata |
Use page.url for the resulting URL and treat redirect metadata as diagnostic only. |
| Blank or partially rendered image | Client-side rendering or resources were still loading | Wait for a page-specific marker, increase a bounded timeout, and inspect resource events. |
| Executable fails before navigation | Unsupported Firefox version or mismatched legacy binaries | Use the documented Firefox 59 pairing in an isolated environment. |
| PDF or image cannot be opened | Extension, format, or Gecko limitation | Use documented PNG/JPEG/PDF formats and remember GIF is unavailable in Gecko. |
Performance, reliability, and cost considerations
Redirects add network round trips, while JavaScript-heavy final pages add rendering time. Keep one page object per job, close it on every success and failure path, and impose a navigation and readiness deadline. Log the starting URL, final page.url, statuses, redirect metadata, viewport, output format, and elapsed time so a wrong screenshot can be reproduced.

For repeatable output, pin the legacy runtime, viewport dimensions, user agent, timezone, and input cookies. Avoid assuming that a fixed delay is reliable across all sites. A page can change after the screenshot if it has animations, rotating ads, or time-dependent content; disable or mask those elements in the page when you control it.
SlimerJS itself is free and open source, but maintaining Firefox 59, patched dependencies, isolated profiles, and a compatibility test set is an operational cost. The research materials provide no benchmark or uptime figures, so choose timeouts and capacity from measurements in your own environment.
Or skip the browser setup
ScreenshotNeo provides a hosted website screenshot API and MCP server. Its one-call endpoint follows the target navigation and returns a PNG, JPEG, WebP, or PDF, so you do not have to maintain SlimerJS and Firefox 59.
See the ScreenshotNeo API documentation for parameters and response details. A minimal request:
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
import requests
r = requests.get(
"https://api.screenshotneo.com/v1/shot",
params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"},
timeout=90,
)
open("shot.webp", "wb").write(r.content)const q = new URLSearchParams({
access_key: 'YOUR_API_KEY',
url: 'https://stripe.com'
});
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);ScreenshotNeo removes cookie and consent banners, newsletter popups, and chat widgets before capture. Bot checks, blank pages, failed loads, timeouts, and cache hits are not billed, and response headers identify the page verdict and whether the shot was billed. It also offers an MCP server with take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 screenshots per month without a card; paid plans start at $5 for 3,000 shots.
Create a free ScreenshotNeo account to try the 1,000 monthly screenshots.
FAQ
How do I get the final URL after a redirect in SlimerJS?
Read page.url inside the page.open() callback or promise continuation. Reading it immediately after starting navigation is too early.
Does SlimerJS expose every redirect?
No. Use page.url for the resulting browser URL. onResourceReceived may provide redirectURL for individual responses, but that field is optional.
Why does a 404 still produce a screenshot?
SlimerJS reports success when it receives a valid HTTP response, including a 404. Inspect response status codes and decide whether to capture or reject error pages.
Should I use callbacks or promises?
Callbacks fit older PhantomJS-style code. Promises read naturally for sequential steps, but the documented promise form is not PhantomJS-compatible.
Can I use current Firefox with SlimerJS?
The official project site says higher Firefox versions are unsupported and development ceased in 2018. Use the documented Firefox 59 pairing only when you have an appropriate legacy environment.