TypeScript vs. JavaScript for Web Scraping
Choose JavaScript for a small scraper and TypeScript for a growing pipeline. Both use the same browser automation tools; types help catch data-shape errors before runtime.
For a small, one-off web scraper, JavaScript usually gets you to a working script with the least setup. For a scraper that will grow, run in production, or be maintained by a team, TypeScript usually pays off by catching many data-shape and interface mistakes before the code runs.
Both languages run on Node.js and work with the same Playwright and Puppeteer browser automation libraries. TypeScript does not make browser automation faster or give it extra browser capabilities. The main difference is when and how you catch mistakes: TypeScript checks your code before execution; plain JavaScript generally discovers them at runtime unless you add JSDoc-based checking.
1. What TypeScript changes in a scraper
TypeScript is a static type checker for JavaScript programs. Its syntax is a superset of JavaScript, and its compiler removes type annotations while emitting JavaScript. That means a TypeScript scraper ultimately runs with JavaScript runtime behavior; the types help you reason about the program before it runs.
Consider a scraper that extracts product data. A page may omit a price, return an unexpected string, or change its markup. TypeScript can help catch mistakes in your own code, such as treating a possibly missing price as a definite number. It cannot prove that a live website will return a valid price. Scraped HTML and remote JSON are untrusted runtime inputs, so validate them when they enter your program.
| Question | TypeScript | JavaScript |
|---|---|---|
| Fastest way to start? | Requires a TypeScript runner or compile step, depending on setup | Runs directly in Node.js |
| Catch mismatched fields before execution? | Yes, when code is type-checked | Not by default; JSDoc and // @ts-check add checking |
| Browser features? | Same features from the chosen library | Same features from the chosen library |
| Best fit? | Long-lived, multi-module, team-owned pipelines | Small scripts, experiments, or JavaScript codebases |
2. Choose the language for the project
Use JavaScript when
- You need a one-off extraction or a small single-file job.
- The scraper is an experiment and may be discarded.
- Your existing service is JavaScript and adding type tooling would add more friction than value.
- The output shape is simple and runtime validation is already clear.
Use TypeScript when
- The scraper has multiple parsers, target sites, contributors, or modules.
- Records pass through retries, pagination, queues, and storage.
- Malformed data is costly downstream.
- You expect to change schemas or refactor the pipeline over time.
For a team project, define types around boundaries: fetched records, parser outputs, pagination state, retry results, and storage payloads. Keep runtime validation at external boundaries. A TypeScript declaration such as type Product = { price: number } does not check a web page at runtime.
3. Build a minimal Playwright scraper in TypeScript
Playwright for Node.js supports both JavaScript and TypeScript. Its browser automation capabilities are shared across supported languages. The example below visits a page, extracts links, checks the resulting values, and closes the browser even if navigation or parsing fails.
- Install Node.js, then create a project and install Playwright.
- Install a browser binary with Playwright’s browser installation command.
- Save the code below as
scrape.ts. - Run it using a TypeScript execution setup supported by your Node.js version, or compile it to JavaScript and run the output with Node.js. See the Playwright Node.js guide for current setup details.
import { chromium } from 'playwright';

type LinkRecord = {
  text: string;
  href: string;
};

function isLinkRecord(value: unknown): value is LinkRecord {
  if (typeof value !== 'object' || value === null) return false;
  const record = value as Record<string, unknown>;
  return typeof record.text === 'string' && typeof record.href === 'string';
}

async function main(): Promise<void> {
  const target = process.argv[2] ?? 'https://example.com';
  const browser = await chromium.launch({ headless: true });

  try {
    const page = await browser.newPage();
    const response = await page.goto(target, { waitUntil: 'domcontentloaded', timeout: 30_000 });
    if (!response) throw new Error('Navigation did not produce a main resource response');
    if (!response.ok()) throw new Error(`Page returned HTTP ${response.status()}`);

    const raw: unknown = await page.locator('a').evaluateAll(anchors =>
      anchors.map(anchor => ({
        text: anchor.textContent?.trim() ?? '',
        href: (anchor as HTMLAnchorElement).href,
      }))
    );
    if (!Array.isArray(raw) || !raw.every(isLinkRecord)) {
      throw new Error('Unexpected extracted link shape');
    }
    console.log(JSON.stringify(raw, null, 2));
  } finally {
    await browser.close();
  }
}

main().catch(error => {
  console.error(error);
  process.exitCode = 1;
});
The runtime guard is deliberate. The unknown type forces the program to establish the shape before treating extracted values as records. For richer data, use a runtime schema validator or explicit checks for required fields and allowed values.
4. The same scraper in JavaScript
Install the same Playwright package and browser. Save this as scrape.mjs and run it with Node.js. It performs the same navigation and extraction; the library behavior is not reduced because the file is JavaScript.
import { chromium } from 'playwright';

async function main() {
  const target = process.argv[2] ?? 'https://example.com';
  const browser = await chromium.launch({ headless: true });

  try {
    const page = await browser.newPage();
    const response = await page.goto(target, { waitUntil: 'domcontentloaded', timeout: 30_000 });
    if (!response) throw new Error('Navigation did not produce a main resource response');
    if (!response.ok()) throw new Error(`Page returned HTTP ${response.status()}`);

    const links = await page.locator('a').evaluateAll(anchors =>
      anchors.map(anchor => ({
        text: anchor.textContent?.trim() ?? '',
        href: anchor.href,
      }))
    );
    if (!Array.isArray(links) || links.some(link =>
      typeof link.text !== 'string' || typeof link.href !== 'string'
    )) throw new Error('Unexpected extracted link shape');

    console.log(JSON.stringify(links, null, 2));
  } finally {
    await browser.close();
  }
}

main().catch(error => {
  console.error(error);
  process.exitCode = 1;
});
5. Use Playwright effectively in either language
- Wait for meaningful state. Prefer a locator or a known page condition over arbitrary sleeps. Playwright’s locators and auto-waiting can handle many timing cases, but your scraper still needs to identify the content it depends on.
- Choose navigation waits deliberately.
domcontentloadedis often a reasonable starting point. Pages that render data after navigation may need a locator wait or another explicit state check. - Isolate jobs. Use separate browser contexts for independent sessions, cookies, or parallel tasks. Avoid sharing mutable page state between jobs.
- Bound resource use. Set navigation and operation timeouts, cap concurrency, and close pages, contexts, and browsers in cleanup paths.
- Respect the target. Check the site’s terms and applicable rules, limit request rates, and avoid collecting data you do not need.
Playwright supports Chromium, WebKit, and Firefox. Puppeteer is another Node.js browser automation option, documented around controlling Chrome or Firefox. Choose a framework based on browser coverage, existing code, and project needs; the framework choice is separate from TypeScript versus JavaScript.
6. Add checking to JavaScript before migrating
A full conversion is not required to get useful editor feedback. The TypeScript team documents gradual adoption using JSDoc, // @ts-check, checkJs, and a jsconfig.json configuration.
For a small file, enable checking and annotate the parser contract:
// @ts-check

/** @typedef {{ title: string, href: string }} ArticleLink */

/** @param {import('playwright').Page} page
 *  @returns {Promise<ArticleLink[]>}
 */
async function extractLinks(page) {
  return page.locator('a').evaluateAll(anchors =>
    anchors.map(anchor => ({
      title: anchor.textContent?.trim() ?? '',
      href: anchor.href,
    }))
  );
}
Turn on project-level JavaScript checking with checkJs in jsconfig.json, then fix the most useful errors first. This keeps the runtime and file extension unchanged while making contracts more visible.
7. Migrate a JavaScript scraper to TypeScript
- Stabilize boundaries. Identify the input URL, extracted record format, pagination state, and storage interface.
- Add JSDoc and checks. Give functions explicit parameter and return contracts; resolve real mismatches rather than silencing every warning.
- Convert a low-risk module. Rename one parser or utility to
.ts, add types, and keep runtime validation for data from pages and APIs. - Type asynchronous outcomes. Represent success and failure explicitly, for example with a result union, rather than assuming every navigation yields usable content.
- Make compiler settings a team decision. Start with strict checking where practical, but tighten incrementally if the existing project has many implicit assumptions.
- Remove duplicate declarations. Once the types express the contract clearly, avoid maintaining parallel JSDoc and TypeScript definitions for the same module.
TypeScript types disappear from emitted JavaScript. They do not sanitize HTML, validate JSON, or protect storage from a malformed record. Keep the runtime checks that protect important boundaries.
8. Performance, reliability, and cost
Does TypeScript make scraping faster?
There is no basis here for claiming that TypeScript increases scraping throughput. TypeScript compiles to JavaScript, and both examples use the same browser library. End-to-end duration is more likely to depend on network latency, browser startup, page behavior, selectors, concurrency, parsing, storage, rate limits, retries, and bot defenses. Measure the actual workload before tuning.
Reliability comes from the pipeline
Types reduce a class of mistakes in your code, especially around records moving between modules. Reliability also requires explicit timeouts, bounded retries with backoff, idempotent storage, validation, and useful logs. Do not retry every failure forever: distinguish a transient network error from a permanent 404 or a page that requires an unsupported interaction.
Account for operating cost
Both languages have the same underlying browser and network costs when run with the same setup. For self-hosted automation, plan for browser process memory, CPU, bandwidth, and maintenance. Limit parallel pages to what the worker can handle. If the task is simply producing screenshots rather than extracting structured page data, a screenshot service can remove the need to run and maintain a browser for that step.
9. Troubleshooting common scraper failures
| Symptom | Likely cause | Fix |
|---|---|---|
| TypeScript syntax error in Node | Node is executing a TypeScript file without an enabled TypeScript workflow | Use the current Playwright TypeScript setup, a compatible TypeScript runner, or compile to JavaScript before running. |
Cannot find package playwright |
Dependencies were not installed in this project or command runs from another directory | Install the package in the project and run from its root; install the browser binary as documented by Playwright. |
| Browser executable missing | Package is installed but its browser binary is not | Run Playwright’s browser installation command for the browser you use. |
| Navigation timeout | Slow server, long-running page, blocked request, or an overly strict timeout | Use a realistic timeout, wait for the needed selector instead of full network quiet, and capture diagnostics. Do not simply remove bounds. |
| Selector returns no records | Markup changed, content is client-rendered, or selector runs too early | Inspect the page structure, wait for a stable locator, and handle empty results as a valid or explicit failure case. |
| Type says field exists but it is undefined | A type annotation was trusted without runtime validation | Validate page/API data at the boundary and represent optional fields accurately. |
| Many duplicate or partial records | Pagination state, retries, or concurrent writes are not coordinated | Use stable record keys, persist page/cursor progress, and make writes idempotent. |
| Works locally, fails in production | Different browser dependencies, environment variables, permissions, proxy, or resource limits | Pin the runtime and browser setup, log the failing URL and stage, and test inside the production container. |
10. Or skip the browser setup
If your task is to capture a page as an image or PDF rather than extract records, ScreenshotNeo offers a one-call screenshot API. It can also be used for HTML/CSS to image. See the API documentation for request options.
curl -G "https://api.screenshotneo.com/v1/shot" \
  -d access_key=YOUR_API_KEY \
  --data-urlencode url=https://stripe.com \
  -o shot.webp
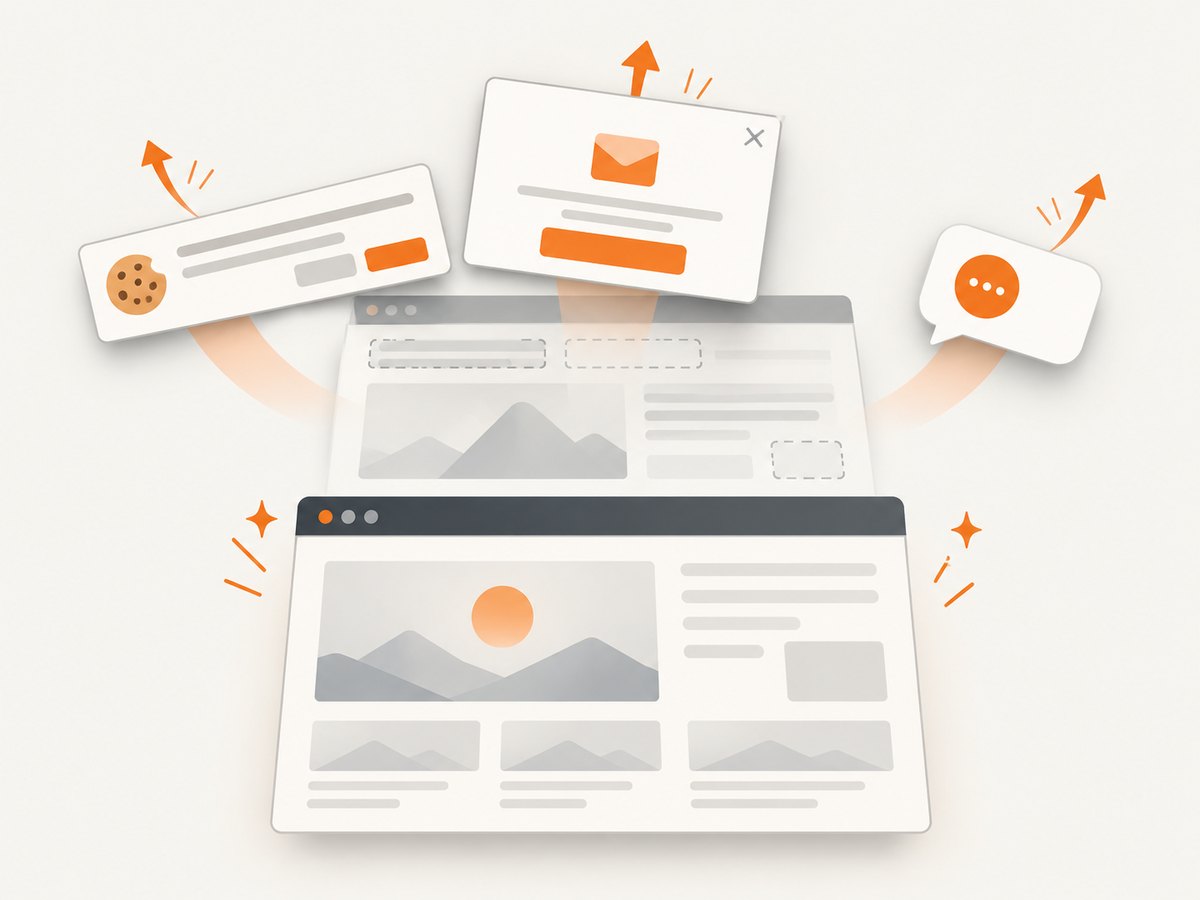
Cookie banners are accepted and removed before the shot, along with known newsletter popups and chat widgets. Bot checks, blank pages, timeouts, failed loads, and cache hits cost nothing; response headers say the page verdict and whether it was billed. An MCP server lets AI agents use take_screenshot, get_page_info, and capture_pdf. The free plan includes 1,000 screenshots a month with no card; paid plans start at $5 for 3,000 screenshots. Sign up for 1,000 free screenshots a month, with no card required.
11. FAQ
Can I scrape websites with TypeScript?
Yes. TypeScript is compiled to JavaScript and works with Node.js browser libraries such as Playwright and Puppeteer.
Is TypeScript better than JavaScript for Puppeteer or Playwright?
It can make a growing scraper easier to maintain through checked contracts. It does not change the library’s browser capabilities. For a tiny script, JavaScript may be simpler.
Should I rewrite an existing JavaScript scraper?
Not automatically. Add JSDoc and // @ts-check first, then convert modules where the extra contracts solve a real maintenance problem.
Do types replace tests or validation?
No. Types check your program before runtime; tests exercise behavior, and runtime validation checks external data as it arrives.


