URL to Markdown with Metadata as YAML Frontmatter
Convert a webpage URL into clean Markdown with YAML frontmatter. Compare hosted APIs with local tools, handle missing metadata, and build a reliable pipeline.
To convert a URL to Markdown with metadata in YAML frontmatter, fetch the page, extract its main content, normalize metadata from its HTML and structured data, then serialize both into one Markdown file. Frontmatter is a YAML block between --- delimiters at the top of the file. It keeps fields such as title, author, publication date, canonical URL, and description alongside the content they describe.
For a production pipeline, use a hosted extraction API when you need managed fetching or JavaScript rendering, or a local tool when you need direct control over the network and processing. Keep metadata optional: pages do not reliably publish every field. If the destination is a database rather than a file-based workflow, returning metadata separately as JSON can be simpler.
1. Understand the output format
A Markdown file with frontmatter might look like this:
---
title: "Example article"
author: "Jordan Lee"
date: "2025-04-12"
publisher: "Example Publisher"
language: "en"
description: "A short summary of the page."
canonical_url: "https://example.com/articles/example"
word_count: 842
reading_time: 4
---

# Example article

The readable page content starts here...
The frontmatter is structured metadata; everything after its closing delimiter is the Markdown body. This makes the file self-describing and convenient for static-site generators, notes apps, document stores, and LLM ingestion systems. The C2PA specification also recognizes YAML front matter as a structured-text location for a manifest block, though ordinary article frontmatter is not itself a provenance manifest.
Use stable, predictable field names. Store dates in an unambiguous format such as ISO 8601, preserve the canonical URL separately from the URL submitted for conversion, and represent unknown values as omitted or null according to your downstream schema. Do not turn a missing author into a guessed value.
2. Choose hosted extraction or local conversion
| Approach | Good fit | Tradeoffs to check |
|---|---|---|
| Hosted API | Managed fetching, JavaScript rendering, and a repeatable service interface | Request limits, caching behavior, geographic controls, field selection, and how the service handles blocked or malformed pages |
| Local CLI or library | Jobs running in your own infrastructure, offline processing of saved HTML, or tighter control of network access | You own browser setup, retries, rendering, updates, and operational monitoring |
| Separate metadata JSON | Database writes, queue messages, or typed application code | Metadata and body can drift if they are fetched or transformed in separate steps |
| Embedded YAML | Files that should travel as a single portable document | Consumers must parse frontmatter and tolerate absent or type-varying fields |
Microlink documents returning Markdown and page metadata from a request, including a pattern using data.markdown.attr=markdown, meta=true, and embed=markdown. Its SDK can also return metadata and Markdown for custom frontmatter construction. Tabstack documents embedded frontmatter by default, as well as a metadata: true mode that returns clean Markdown and structured metadata separately. Compare their current documentation for exact request syntax and available fields before adopting either API.
For local conversion, r11y and get-md are examples of CLI or local approaches. Decide based on whether you need browser rendering, what cleanup they perform, and how well they preserve tables, code blocks, links, and images. The tool names alone do not guarantee equivalent extraction quality.
3. Build the conversion pipeline
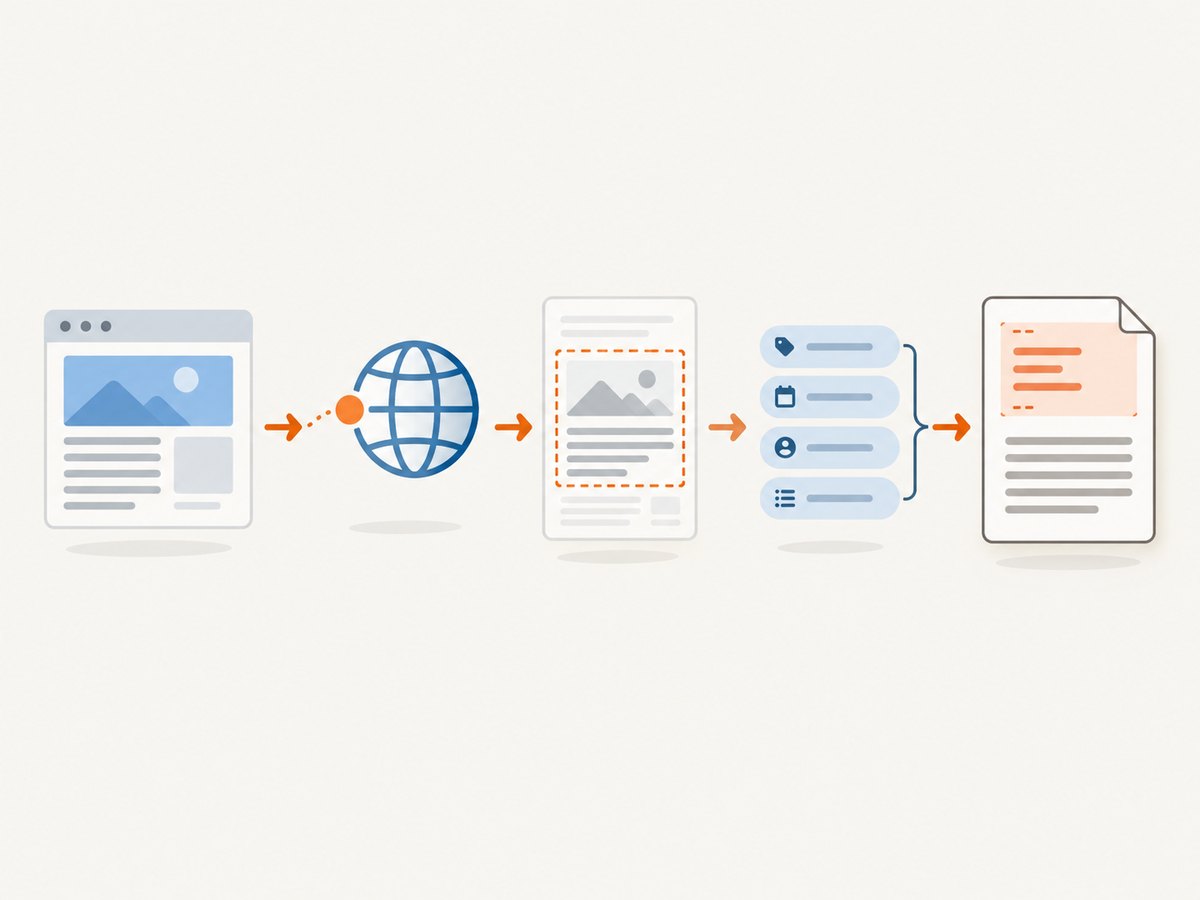
- Fetch one page version. Request the URL and retain the final response URL after redirects. Render JavaScript when the meaningful text or metadata is created in the browser.
- Extract the main content. Remove navigation and repeated page chrome while preserving meaningful headings, lists, tables, links, and code.
- Collect metadata. Read ordinary HTML metadata, Open Graph tags, Twitter Card tags, and JSON-LD where available.
- Resolve conflicts consistently. Define a source preference for each field. For example, use a valid canonical link for
canonical_url, and prefer a non-empty page title over a generic social card title. Record provenance separately if field origin matters. - Serialize safely. Quote strings when needed, escape values using a YAML library, and place the Markdown body after the closing delimiter.
- Validate the artifact. Parse the frontmatter back, check required internal fields, and confirm the body is not empty before storing or indexing it.
A single request that returns both content and metadata can reduce joins and version mismatches: title and body are derived from the same fetched page. If the API returns two separate objects from one response, construct the file from those objects in one processing step.
Metadata field checklist
title: human-readable page title; fall back to the document title only if your policy allows it.author: include only when extracted with reasonable confidence. Some pages list multiple contributors.date: distinguish publication date from modified date if both are present; do not silently substitute one for the other.publisher,language,description: useful for discovery and filtering, but frequently absent.canonical_url: useful for deduplication. Validate that it is a URL and retain the requested URL if provenance requires it.word_countandreading_time: derived values, not source metadata. Document how your pipeline calculates them.
4. Example hosted request patterns
Exact parameters differ by provider. The following is the documented Microlink request pattern described in its documentation; check its current API docs for authentication, encoding, and response envelope details.
curl -G 'https://api.microlink.io' \
  --data-urlencode 'url=https://example.com/article' \
  --data-urlencode 'data.markdown.attr=markdown' \
  --data-urlencode 'meta=true' \
  --data-urlencode 'embed=markdown'
In an application, treat the response as untrusted input. Confirm that the request succeeded, locate the Markdown and metadata fields in the documented response shape, then serialize with a YAML implementation rather than concatenating arbitrary page values between delimiter lines.
Python: construct frontmatter from returned data
This example shows the serialization step when you already have a Markdown string and a metadata mapping. Install PyYAML with python -m pip install PyYAML. Fetching and extraction are intentionally delegated to the API or local parser you choose; map its documented response fields to markdown and metadata.
from pathlib import Path
import yaml

markdown = "# Example article\n\nReadable content goes here.\n"
metadata = {
    "title": "Example article",
    "author": None,
    "canonical_url": "https://example.com/articles/example",
}

# Remove absent values if your schema represents missing fields by omission.
metadata = {key: value for key, value in metadata.items() if value is not None}
frontmatter = yaml.safe_dump(
    metadata,
    allow_unicode=True,
    sort_keys=False,
    default_flow_style=False,
).rstrip()

Path("article.md").write_text(
    f"---\n{frontmatter}\n---\n\n{markdown}",
    encoding="utf-8",
)
Node.js: construct frontmatter from returned data
Use a YAML package so strings containing colons, quotes, or newlines are encoded correctly. For example, install the yaml package with npm install yaml.
import { writeFile } from 'node:fs/promises';
import YAML from 'yaml';

const markdown = '# Example article\n\nReadable content goes here.\n';
const metadata = {
  title: 'Example article',
  canonical_url: 'https://example.com/articles/example',
};

const frontmatter = YAML.stringify(metadata).trimEnd();
await writeFile(
  'article.md',
  `---\n${frontmatter}\n---\n\n${markdown}`,
  'utf8',
);
5. Handle rendering, cleanup, and field conflicts
Static HTML is enough when the server response already contains the article and metadata. Use a JavaScript-capable renderer when the initial HTML is only a shell, client-side routing supplies the page, or metadata is inserted after load. Rendering adds latency and resource use, so enable it for the cases that need it rather than assuming every URL requires a browser.
Extraction quality affects the usefulness of the Markdown as much as conversion syntax. Inspect whether your chosen approach:
- removes navigation, advertisements, and repeated sidebars without deleting article content;
- preserves heading hierarchy, ordered lists, tables, code blocks, and link destinations;
- handles images as source links or references, and whether remote image URLs remain accessible;
- avoids selecting a short teaser or a comment thread as the main article;
- keeps text in the page’s original language and does not silently translate it.
Metadata often conflicts. The browser title may differ from og:title; JSON-LD may contain an author while visible page text lists an editor; a page can expose several dates. Set a deterministic precedence per field, keep the original source values when auditability matters, and avoid using one global priority rule for every field. Validate URLs and dates instead of assuming tags are correct.
6. Or skip the browser setup
ScreenshotNeo is a website screenshot API and MCP server from Yorker Media. It captures screenshots or PDFs; it does not convert a webpage into Markdown or produce YAML metadata. Use it when your pipeline also needs a page image, visual review, or an AI agent screenshot tool. It is a separate step from content extraction. See ScreenshotNeo and the API documentation.
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpCookie banners, newsletter popups, and chat widgets are removed before the shot. Bot checks, blank pages, and failed loads are never billed. Its MCP server lets AI agents take screenshots, and 1,000 screenshots a month are free with no card; paid plans start at $5 for 3,000. Sign up for 1,000 free screenshots a month.
7. Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Markdown is blank or only contains a loading message | Content is rendered client-side, or the request was blocked | Try JavaScript rendering, inspect the final response and status, and distinguish a genuine empty page from a fetch failure. |
| Frontmatter will not parse | Unescaped punctuation, newlines, or delimiter text in a value | Use a YAML serializer; do not interpolate raw strings. Parse the generated block as part of validation. |
| Author or date is missing | The page does not publish that field, or the extractor did not recognize its source | Allow absent values, inspect HTML and JSON-LD, and avoid inventing metadata. |
| Wrong title or canonical URL | Conflicting HTML, social, or structured metadata | Define field-specific precedence and retain the requested URL separately when needed. |
| Navigation appears in the body | Main-content detection selected a broad container | Adjust extraction rules or use a parser with page cleanup controls; compare output on representative page types. |
| Tables or code are damaged | Conversion flattened structure or treated preformatted content as prose | Test the extractor against pages with those elements; preserve HTML structures until the Markdown conversion stage where possible. |
| Duplicates enter the index | Tracking parameters or aliases create multiple request URLs | Normalize URLs carefully, use a valid canonical URL for deduplication, and retain the original request URL for traceability. |
| Requests intermittently time out | Slow origin, scripts, or third-party resources delay rendering | Set sensible timeouts, limit unnecessary rendering and resources, retry transient failures with backoff, and record failures separately from empty content. |
8. Performance, reliability, and cost
Hosted services shift browser management and extraction infrastructure to the provider, while local conversion shifts that work to your team. A static fetch is typically a lighter path than full rendering; a rendered browser must load scripts and potentially third-party assets. Use bounded concurrency and timeouts so a slow site cannot stall an entire batch.
For reliability, make jobs idempotent using a normalized URL and an extraction version. Record fetch time, final URL, response status, renderer mode, and parser version alongside the artifact or in a job record. Retry only transient network and service errors; repeating a request will not fix a page that consistently blocks access or publishes no metadata. Cache when freshness requirements allow it, and define how cache invalidation works when source pages change.
Cost depends on the provider’s current plan and what counts as a request; rendering and retries can affect resource consumption. Check pricing, limits, caching semantics, and geographic targeting in the provider documentation before estimating a large run. Local processing avoids a per-request hosted extraction fee only if you account for compute, browser maintenance, and engineering time. For a database pipeline, separate JSON may reduce parsing work; for portable archives, embedding YAML avoids maintaining a second metadata file.
9. Frequently asked questions
Can I guarantee every page has title, author, and date?
No. Those fields depend on what the source page exposes and what the extractor can identify. Design consumers to accept partial metadata.
Should metadata be YAML or JSON?
Use YAML frontmatter when metadata should travel inside a Markdown file. Use JSON as a separate object when your next step writes typed records or queries individual fields.
Does frontmatter change the article content?
It adds a machine-readable block before the body. A Markdown consumer that understands frontmatter can parse it; a plain Markdown viewer may display the delimiters as text.
Can this workflow capture a visual screenshot too?
Yes, as a separate output step. ScreenshotNeo can return a screenshot or PDF from a URL, while a content extraction service or local parser handles Markdown and metadata.
References
- Microlink API data parameters — Markdown extraction and metadata request patterns.
- Tabstack documentation — Markdown with embedded or separately returned metadata.
- r11y repository and get-md repository — local conversion approaches.
- C2PA Specification 2.4 — structured-text placement context.


